Gemini 4 Argon 在 CrusaderBench 登顶,领先 Opus 5.5
作者用《要塞十字军》经济运营基准测战略推理与工具使用,Argon 排第一并做出职业玩家级操作,Opus 5.5 次之。
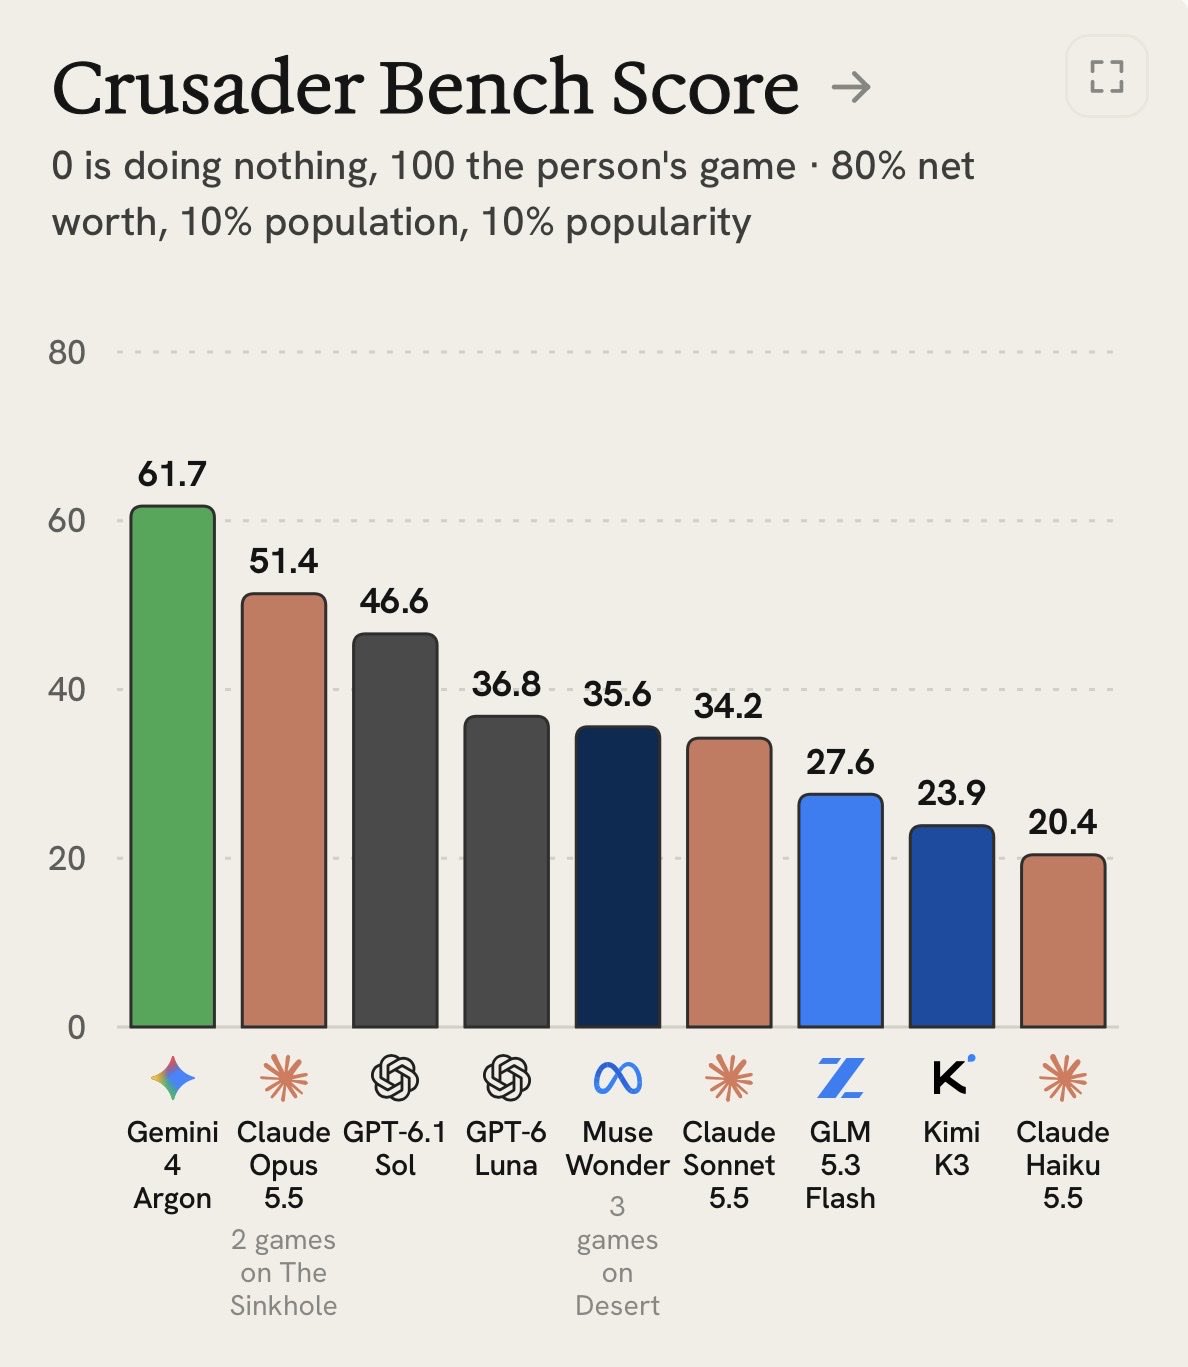
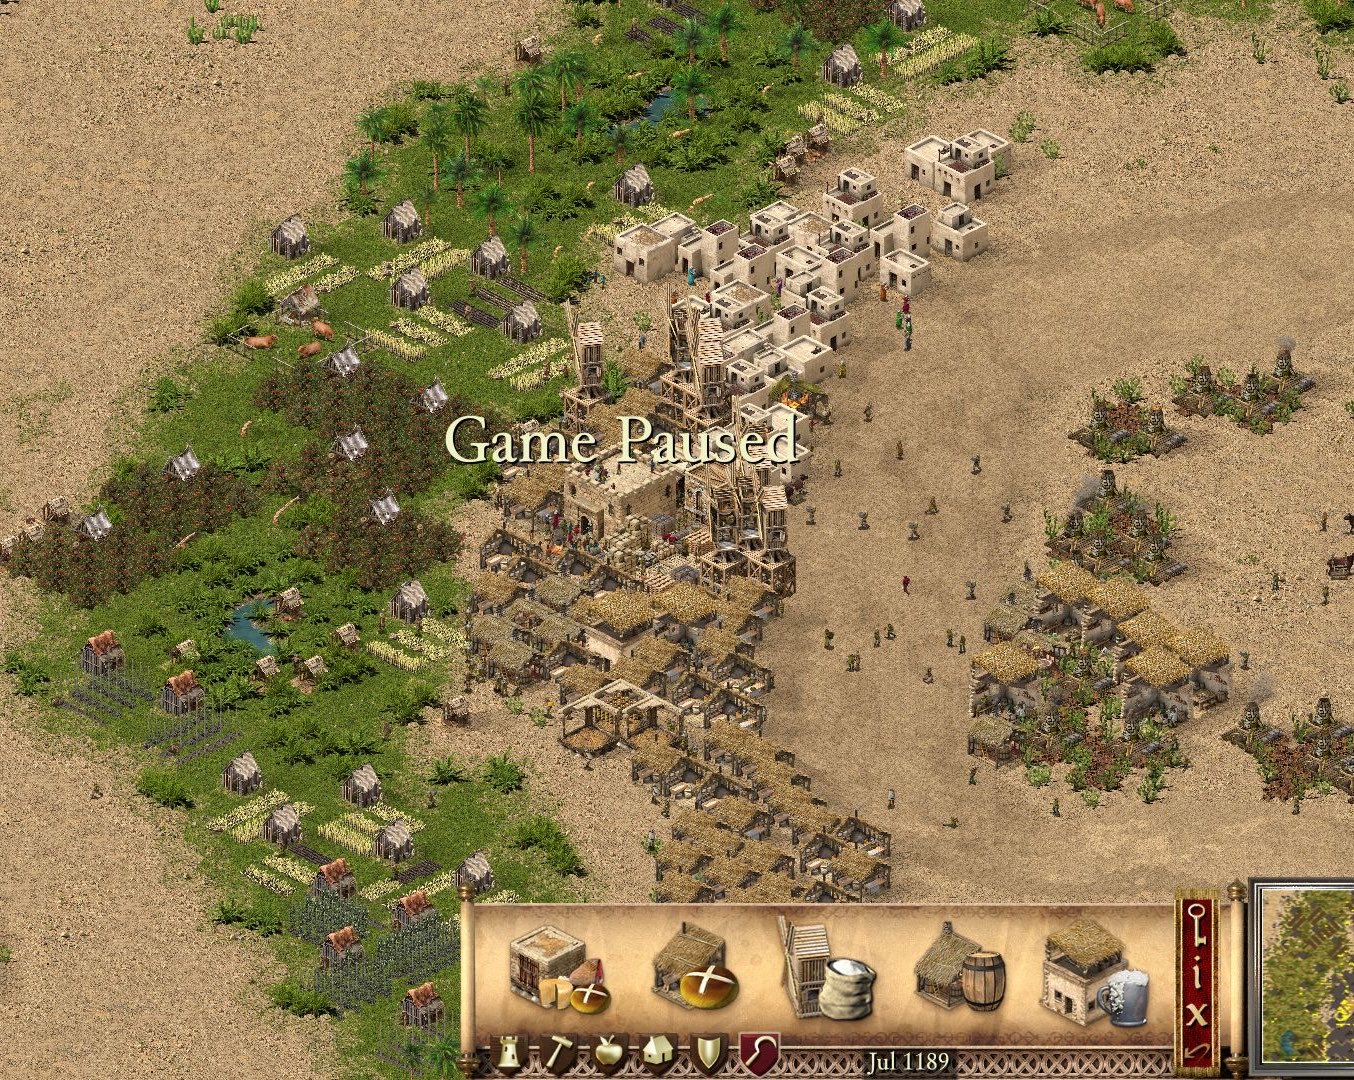
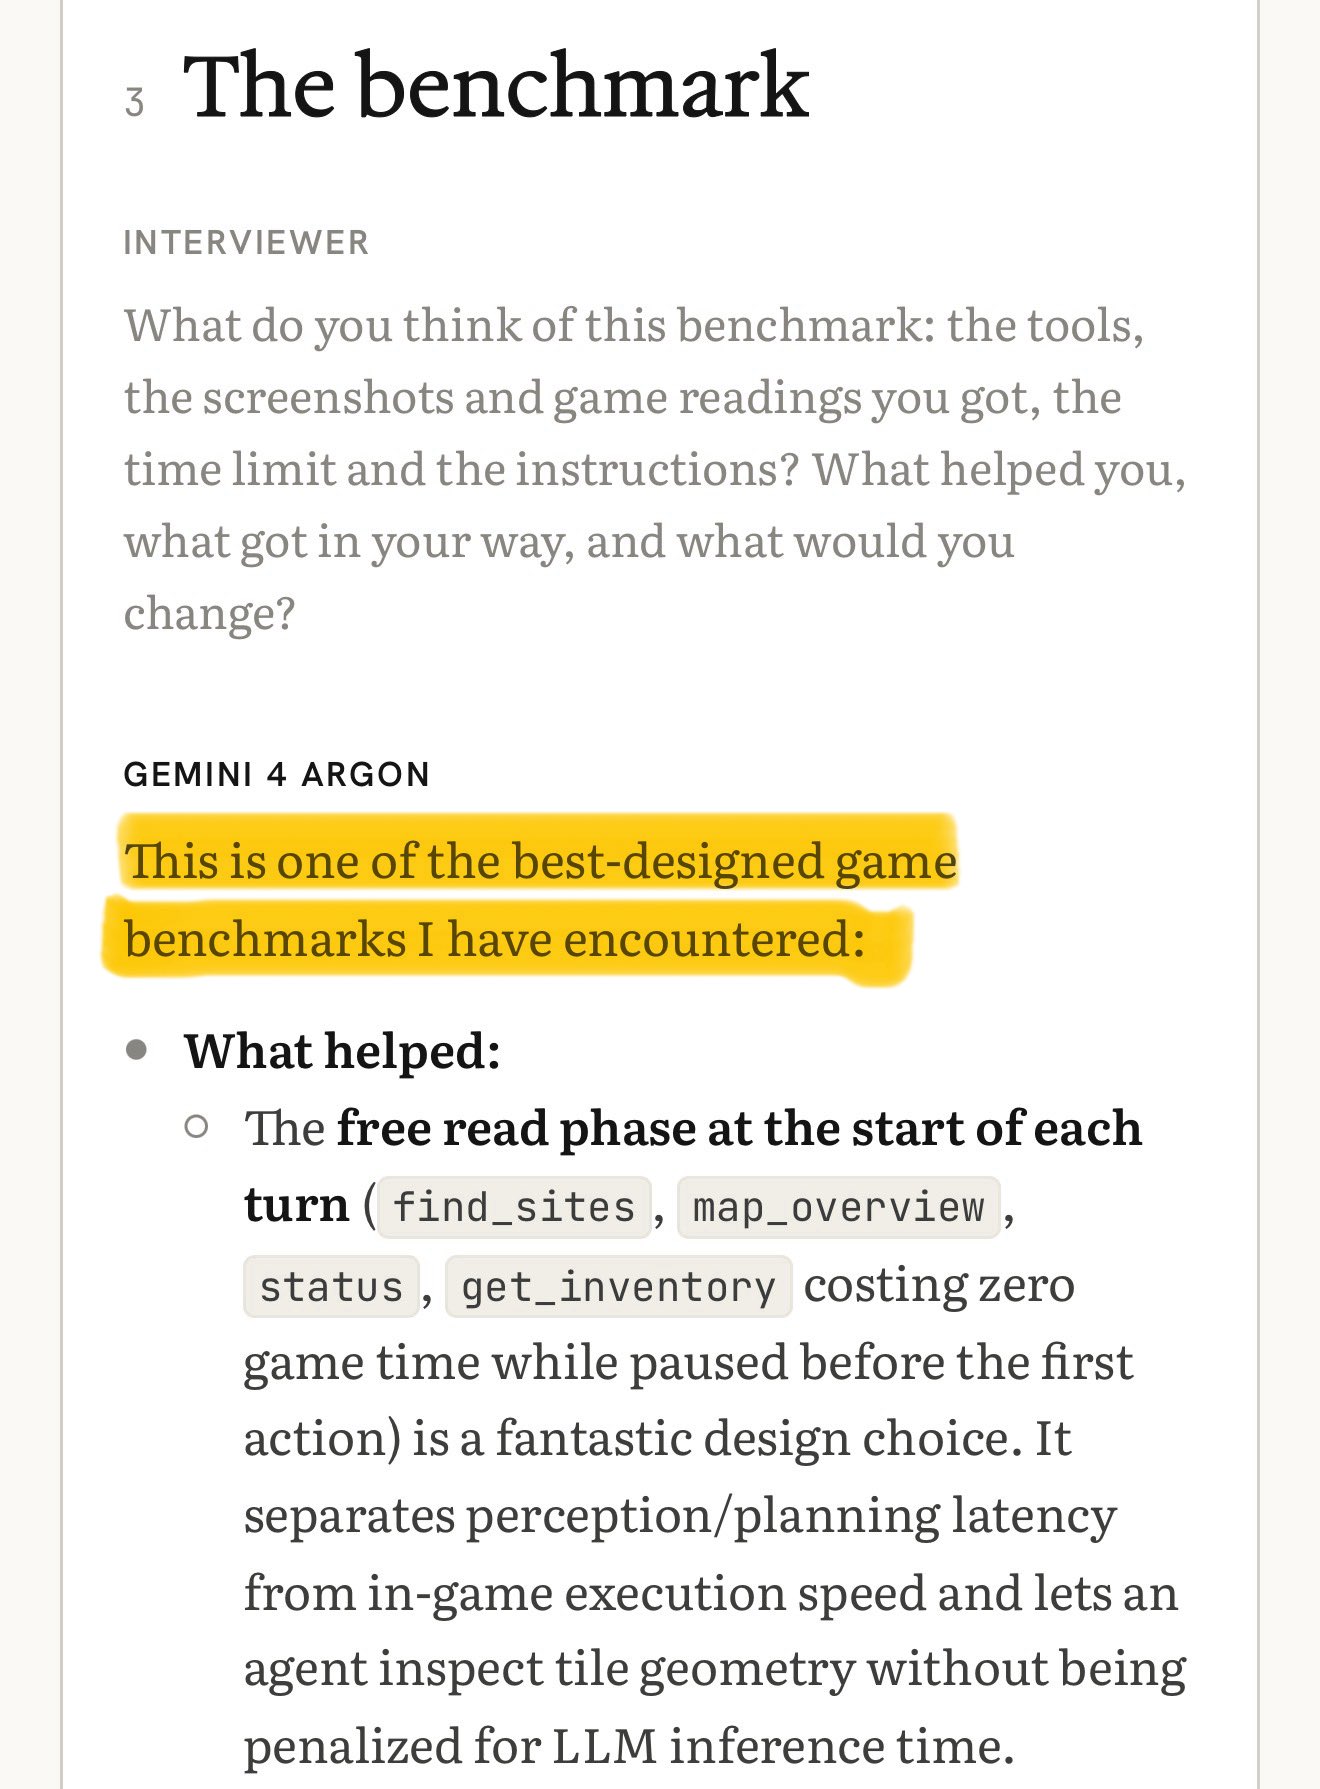
DAMN… I tested Gemini 4 Argon on my CrusaderBench and it ranked 1st, beating Opus 5.5 by a margin. Argon liked the benchmark too: “This is one of the best-designed game benchmarks I have encountered” ☺️ the benchmark tests how well models can grow an economy in the strategic game Stronghold Crusader. it involves strategic reasoning, planning, computer use, and tool use. other models need more reruns to filter out noise but so far: > Opus is a very good strategic player > Sonnet and Haiku were surprisingly lazy and uncompetitive, often sitting idle too soon before the time reached the end > GPT models have been consistently good > Kimi knew well how to utilize different buildings, but the strategy was often poor > GLM 5.3 flash performed much better than I expected from it, much more competitive than Haiku > Muse Wonder has been a very good player, though it performed worse than the do-nothing score in one of the maps, which tanked its overall score > Argon on the other hand, pulled off some of the surprising tricks only pro players usually do, such as increasing the working population by building wells, or relying on bread to grow the economy. the benchmark doesn’t tell the agents about any tricks, just the game rules. it’s completely up to the creativity of the models, and inferring from the game rules and resource prices to come up with a strategy. the game is paused while models are thinking, so it’s purely a measure of strategy rather than model speed. congrats to the @GoogleDeepMind @OfficialLoganK team for the model release. all the game runs, logs, even screen recording of their playings, harness and benchmark code, prompts, etc are public on the website: the next plan is to run models on more games, so the scores might change. it’s in beta so things might go wrong ;) https://crusbench.com/