STAIR:用文档目录结构替代向量检索的新 RAG 方法
新论文用文档真实层级做寻址,不用向量库和重排器,Recall@1 达 82.6%,幻觉率降到 0.05% 以下。

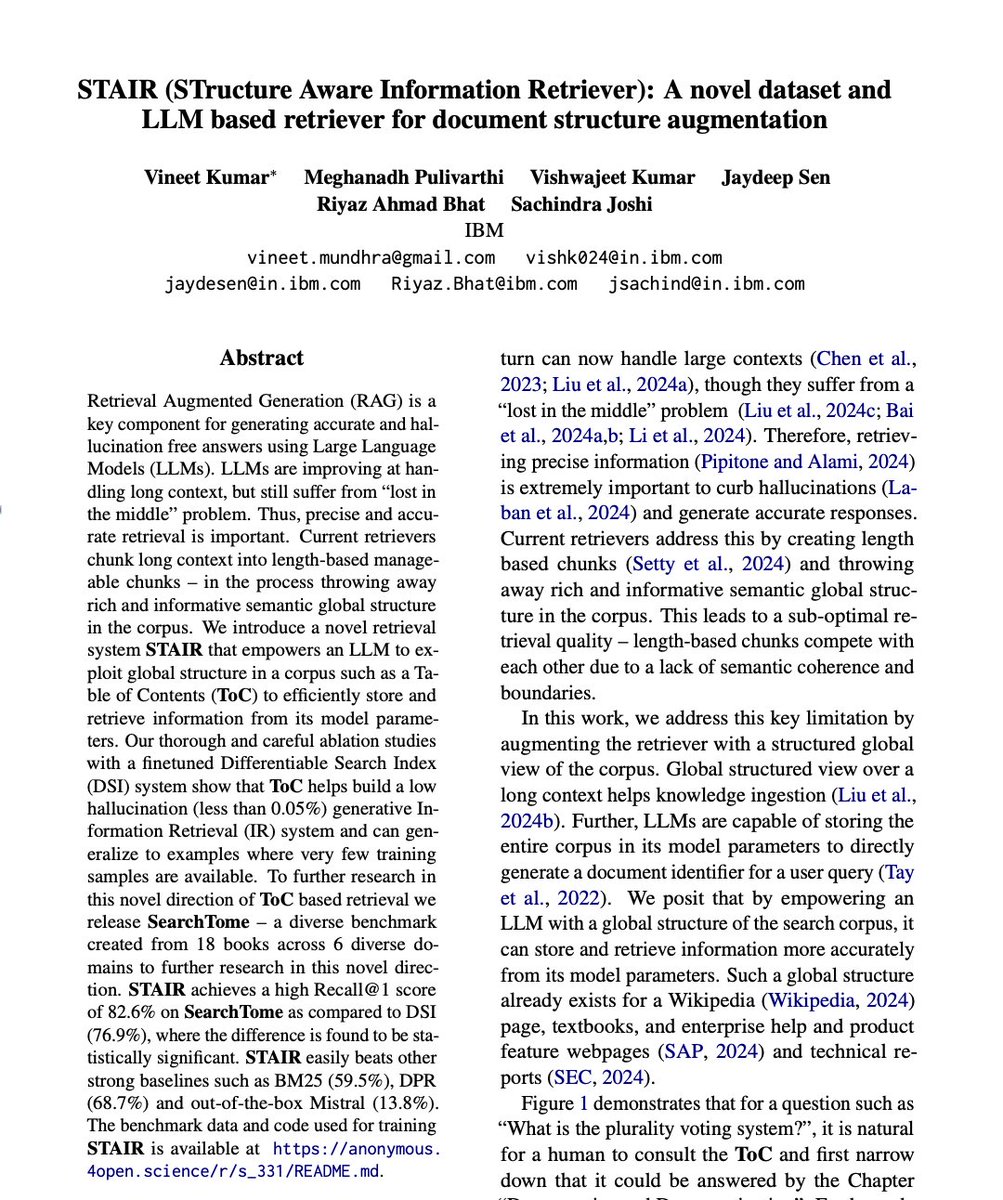
IBM built a retriever that hallucinates 65x less than fine-tuned RAG systems. no vector database. no embeddings. no re-ranker. Right now, if you want an AI to read a massive document, you use Retrieval-Augmented Generation (RAG). But standard RAG does something brutal. It takes a beautifully structured 500-page manual and throws it into a blender. It chops the text into arbitrary, fixed-size chunks. It strips away the chapters, the sections, the hierarchy. It throws away the map and asks the AI to find the treasure. A new paper just introduced STAIR, a method that fixes this massive blind spot. Instead of shredding documents into random chunks, STAIR uses the document's actual structure, its Table of Contents, as an addressing scheme. The generative retriever pulls information against the real hierarchy of the text. It remembers where things actually live. The benchmark results are staggering. STAIR hit an 82.6% Recall@1, completely destroying traditional methods like BM25 and standard Dense Passage Retrieval (DPR). But here is the most important metric for any business running AI in production: Hallucinations plummeted to under 0.05%. Almost zero. By giving the AI back the structural context, the system stopped guessing and started retrieving with lethal precision.