Jev 对比 6 个 LLM 做客服意图路由实测
30 条退款/支持分流消息上,Jev 准确率 30/30、中位 0.32 秒、每 10 万次决策 1.41 美元,并靠置信度触发追问。
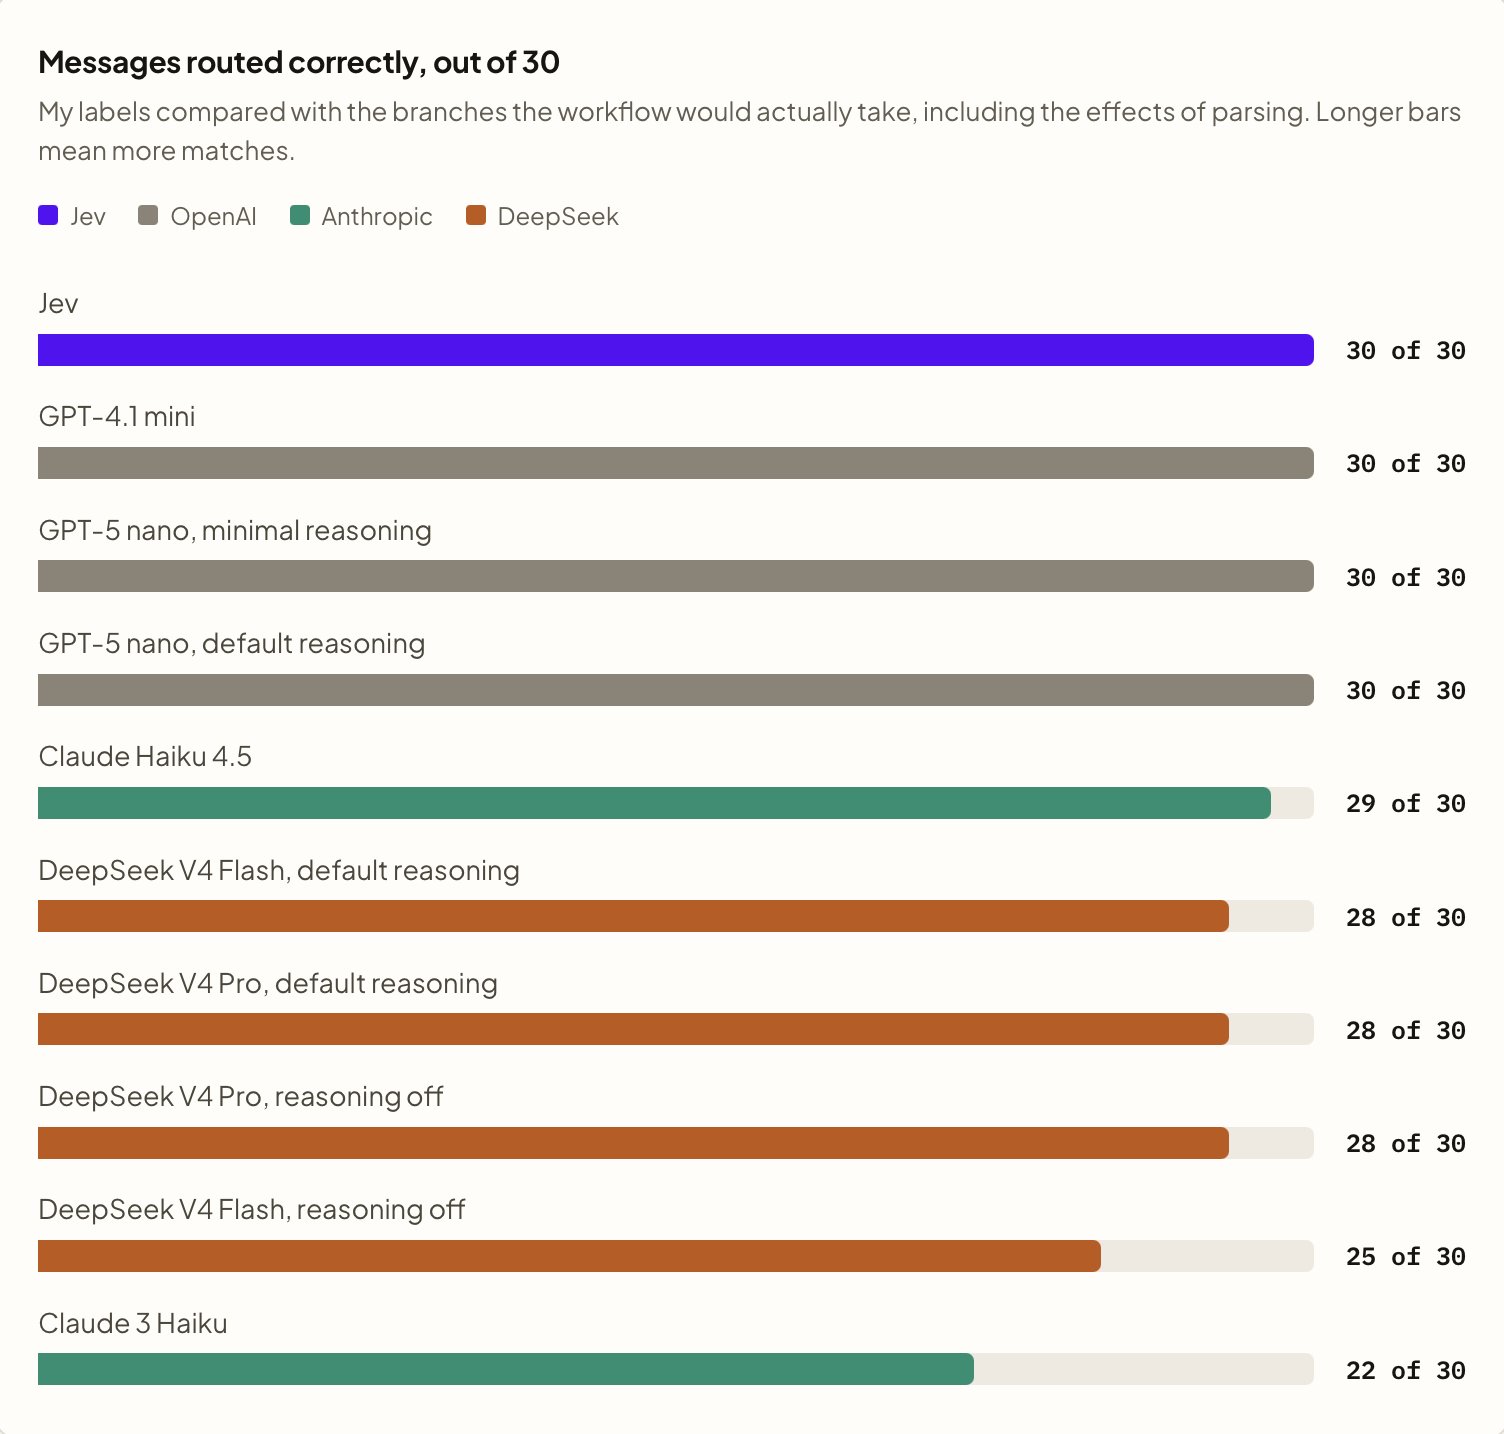
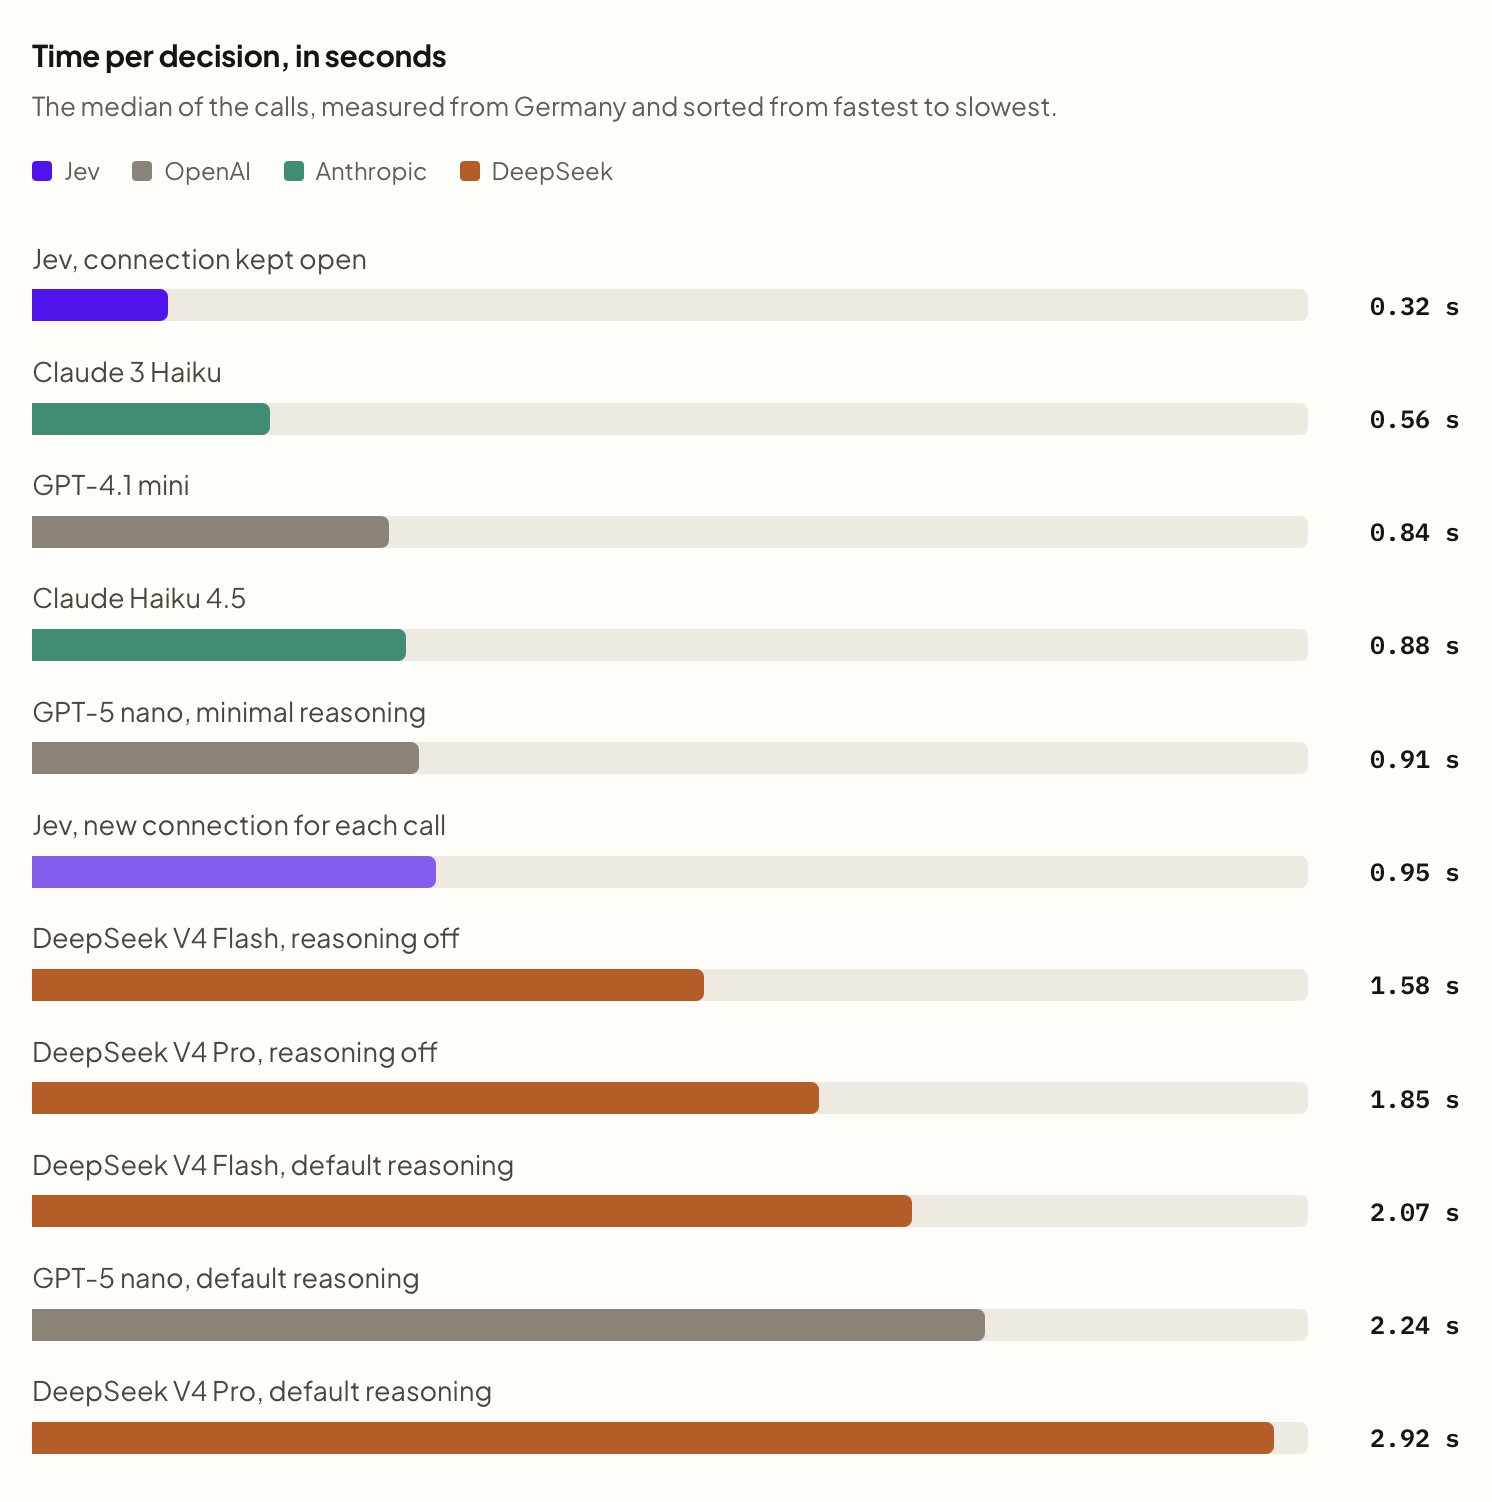
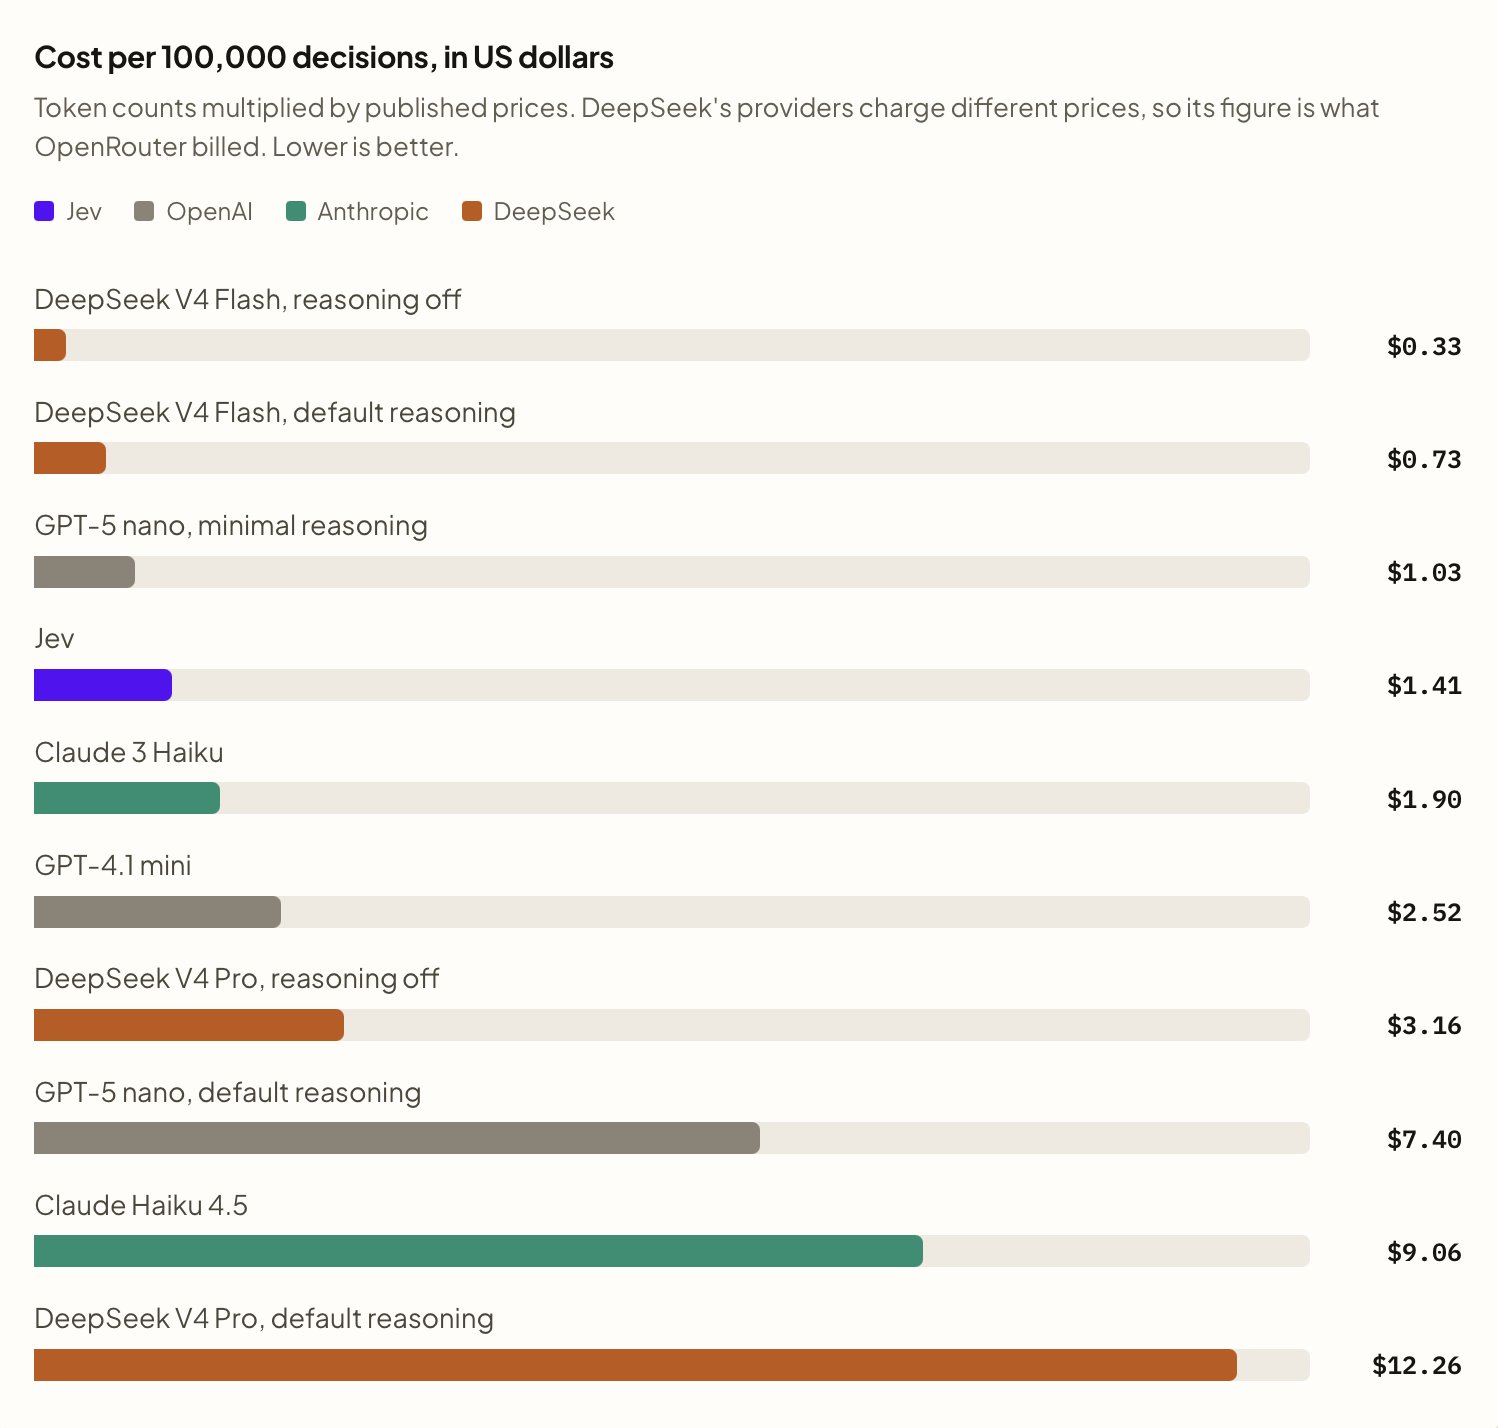
Jev has recently been released and is getting a lot of attention. It’s a decision model that returns a choice, probabilities and a confidence score, which makes it a natural fit for tasks like chatbot intent routing. So I tested it using ChatFrom’s production routing logic to see how it compares with LLMs on accuracy, speed and cost. The task was to decide whether a visitor wants a refund or needs support. I ran 30 test messages through Jev and six LLMs from OpenAI, Anthropic and DeepSeek, including ambiguous requests like “I want to cancel”. On accuracy, Jev matched GPT-5 nano and GPT-4.1 mini at 30/30. The Claude and DeepSeek models scored between 22/30 and 29/30, depending on the model and settings. On speed, Jev’s median response time was 0.32 seconds with the connection kept open, compared with 0.84–0.91 seconds for the two OpenAI models using their faster tested settings. Opening a new connection each time brought Jev to 0.95 seconds, so connection reuse mattered. On price, Jev cost $1.41 per 100,000 decisions. That put it between GPT-5 nano with minimal reasoning at $1.03 and GPT-4.1 mini at $2.52. DeepSeek V4 Flash was cheaper, but less accurate in this test. What interested me most was Jev’s confidence score. With a threshold of 0.8, two ambiguous messages would have triggered a follow-up question, giving the visitor a chance to clarify before the workflow continued. This was a small test with synthetic messages, but it gave me practical ideas for improving routing in ChatFrom. I wrote up the full comparison and how I’m planning to use confidence in the workflow. Article link in the first post.