Jev 式决策模型正在取代 agent 里的 JSON 路由
长文梳理 /v1/systemone 生态:Ollama、Perplexity、AWS 等接入,choice/noul/score 三种原语,并指出对抗注入可翻转六成输出。
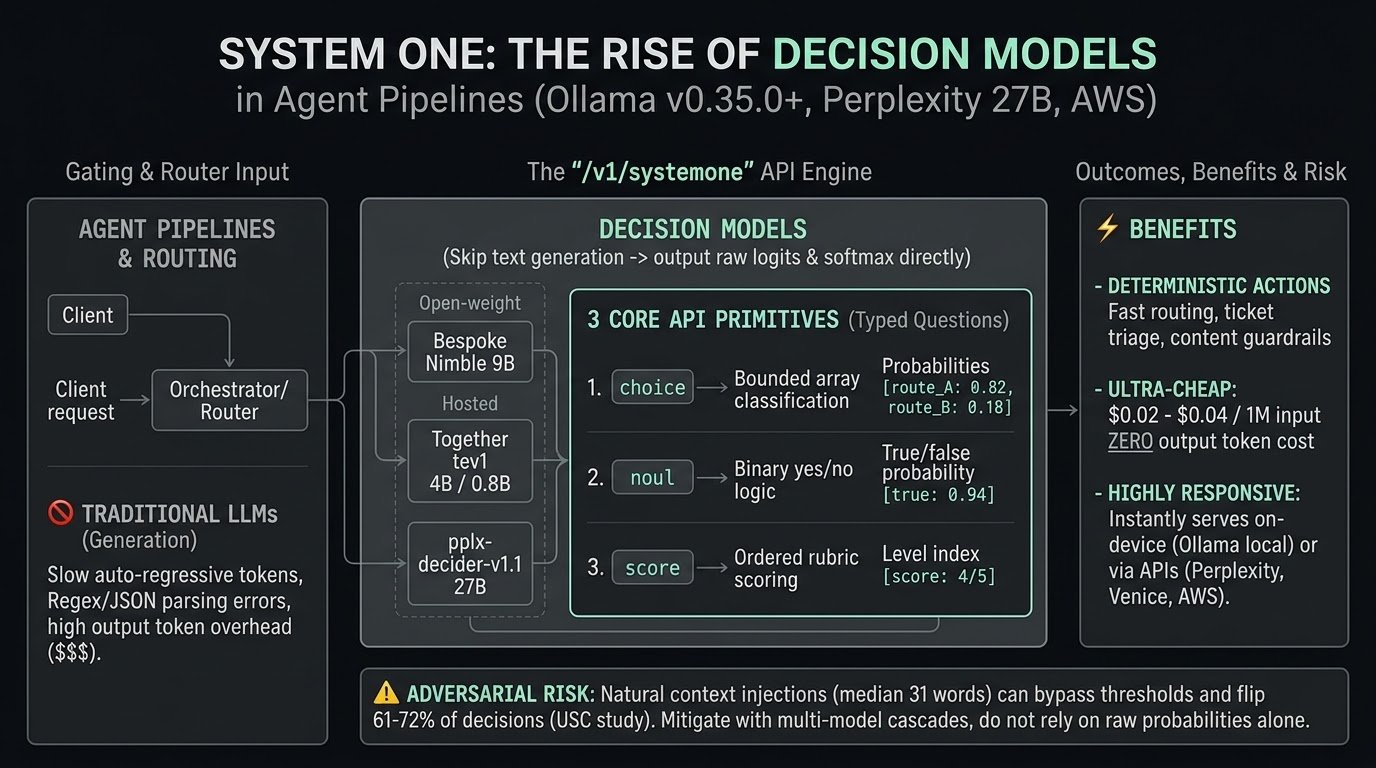
The most interesting architectural shift in AI agent design is happening quietly at the gating and routing layer. We are moving away from open-ended text generation toward "Decision Models." Historically, routing, triage, and gating in agent pipelines relied on standard LLMs prompted to return structured JSON. It’s slow, expensive, and fails whenever the model violates the schema or hallucinates formatting. A new tier of lightweight, specialized models is standardizing around the `/v1/systemone` protocol (originating from TypeSafe's Jev). These don't write text; they directly output raw logits and softmax probabilities for bounded questions. Since there is zero auto-regressive generation, inference is extremely fast, highly deterministic, and exceptionally cheap—costing between $0.02 and $0.04 per 1M input tokens with $0.00 output overhead. The API is dropping into runtimes everywhere: • Locally: Ollama v0.35.0+ introduced `/v1/systemone` support (using SystemOneModel) with Together AI’s `tev1` (4B/0.8B) and Bespoke Labs’ `nimble` (9B). • Hosted/Open: Perplexity’s `pplx-decider-v1.1-27b` (Apache 2.0) and its Decisions API, alongside AWS Strands Decider (2B), Upstage's Solar Decide, Venice, and OpenRouter. The schema reduces all routing to three primitive queries: 1. `choice` -> Array-based classification with exact probabilities (e.g., `[route_A: 0.82, route_B: 0.18]`). 2. `noul` -> Yes/no binary logic. 3. `score` -> Ordered rubric scoring (e.g., triage tier `4/5`). The Architectural Catch: A USC study found these category-wide models are highly vulnerable to adversarial injection. Inserting natural-looking context (median 31 words) flipped up to 61.4% of Jev and 72.6% of Qwen-based decision-model outputs. Takeaway: High raw probability does not guarantee robustness. If you’re routing sensitive agent execution paths, validate inputs first or deploy a multi-model consensus cascade. Never rely on confidence thresholds alone. How is your team handling prompt-level triage? Are you still wasting tokens on JSON generation, or are you migrating to dedicated deciders?