别再加 LLM 调用:用 Jev 做分类、打分和路由
以客服工单为例,说明 Jev 并行给预设选项打分、返回带概率的类型化答案,适合路由和意图判断,但需自测准确率与校准。
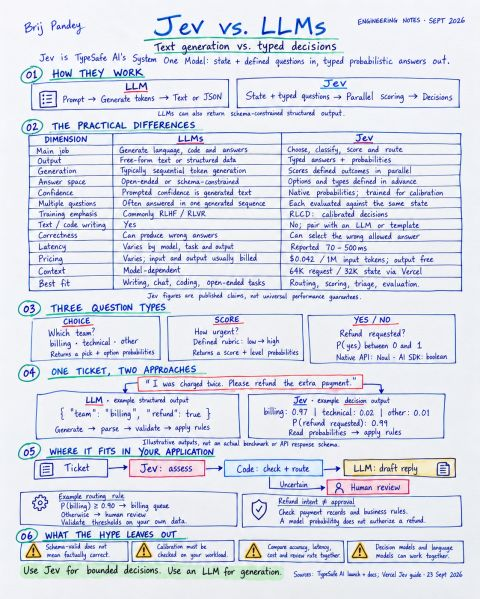
Before you add another LLM call, look at what your application actually needs back. A lot of the time it needs a category, a score, or a yes or no. I've been looking at Jev, the System One model from TypeSafe AI, for exactly that kind of work. You pass it context and a set of defined questions. It returns typed answers with probabilities attached, and your code can route, classify, or score on them directly. LLMs can already return JSON constrained to a schema. Jev gets there differently: An autoregressive LLM writes the answer out token by token. Jev scores the defined outcomes in parallel and never writes prose. If your workflow makes dozens of small decisions per request, that difference is worth measuring. 𝗔 𝗿𝗲𝗮𝗹 𝗲𝘅𝗮𝗺𝗽𝗹𝗲 A support ticket comes in: "I was charged twice. Please refund the extra payment." That one message holds four separate jobs: Route it to the right team Detect whether the customer is asking for a refund Check payment records against refund rules Write the reply I'd test Jev on 1 and 2. Step 3 stays in application code. Step 4 goes to an LLM. Anything below your confidence threshold goes to a person. I keep those jobs apart on purpose. A high probability that the customer asked for a refund tells you nothing about whether the refund should be approved. Your rules make that call. 𝗪𝗵𝗮𝘁 𝘆𝗼𝘂 𝘀𝘁𝗶𝗹𝗹 𝗵𝗮𝘃𝗲 𝘁𝗼 𝗱𝗼 A cleanly typed answer can still be wrong. Before you trust it: Measure accuracy on your own ticket history Check calibration, so 0.9 means right about 90% of the time on your data Set thresholds based on what a mistake costs you 𝗛𝗼𝘄 𝗜'𝗱 𝘀𝗽𝗹𝗶𝘁 𝘁𝗵𝗲 𝘄𝗼𝗿𝗸 Explicit rules go in code. Judgment calls inside a fixed set of options are where a decision model is worth evaluating. Anything that needs language goes to a generative model. Then judge the whole workflow on accuracy, latency, cost, and how much human review it creates. Benchmarking one component on its own won't tell you much. Which step in your agent workflow only needs a label, a score, or a yes or no back?