SGLang 为 Jev 类决策模型加打分接口
LMSys 博客介绍用 SGLang 服务 Open-Jev 这类打分模型:/v1/score 直接返回指定标签分数,多候选共享上下文只算一次,16 候选 p95 从 54ms 降到 20.6ms。
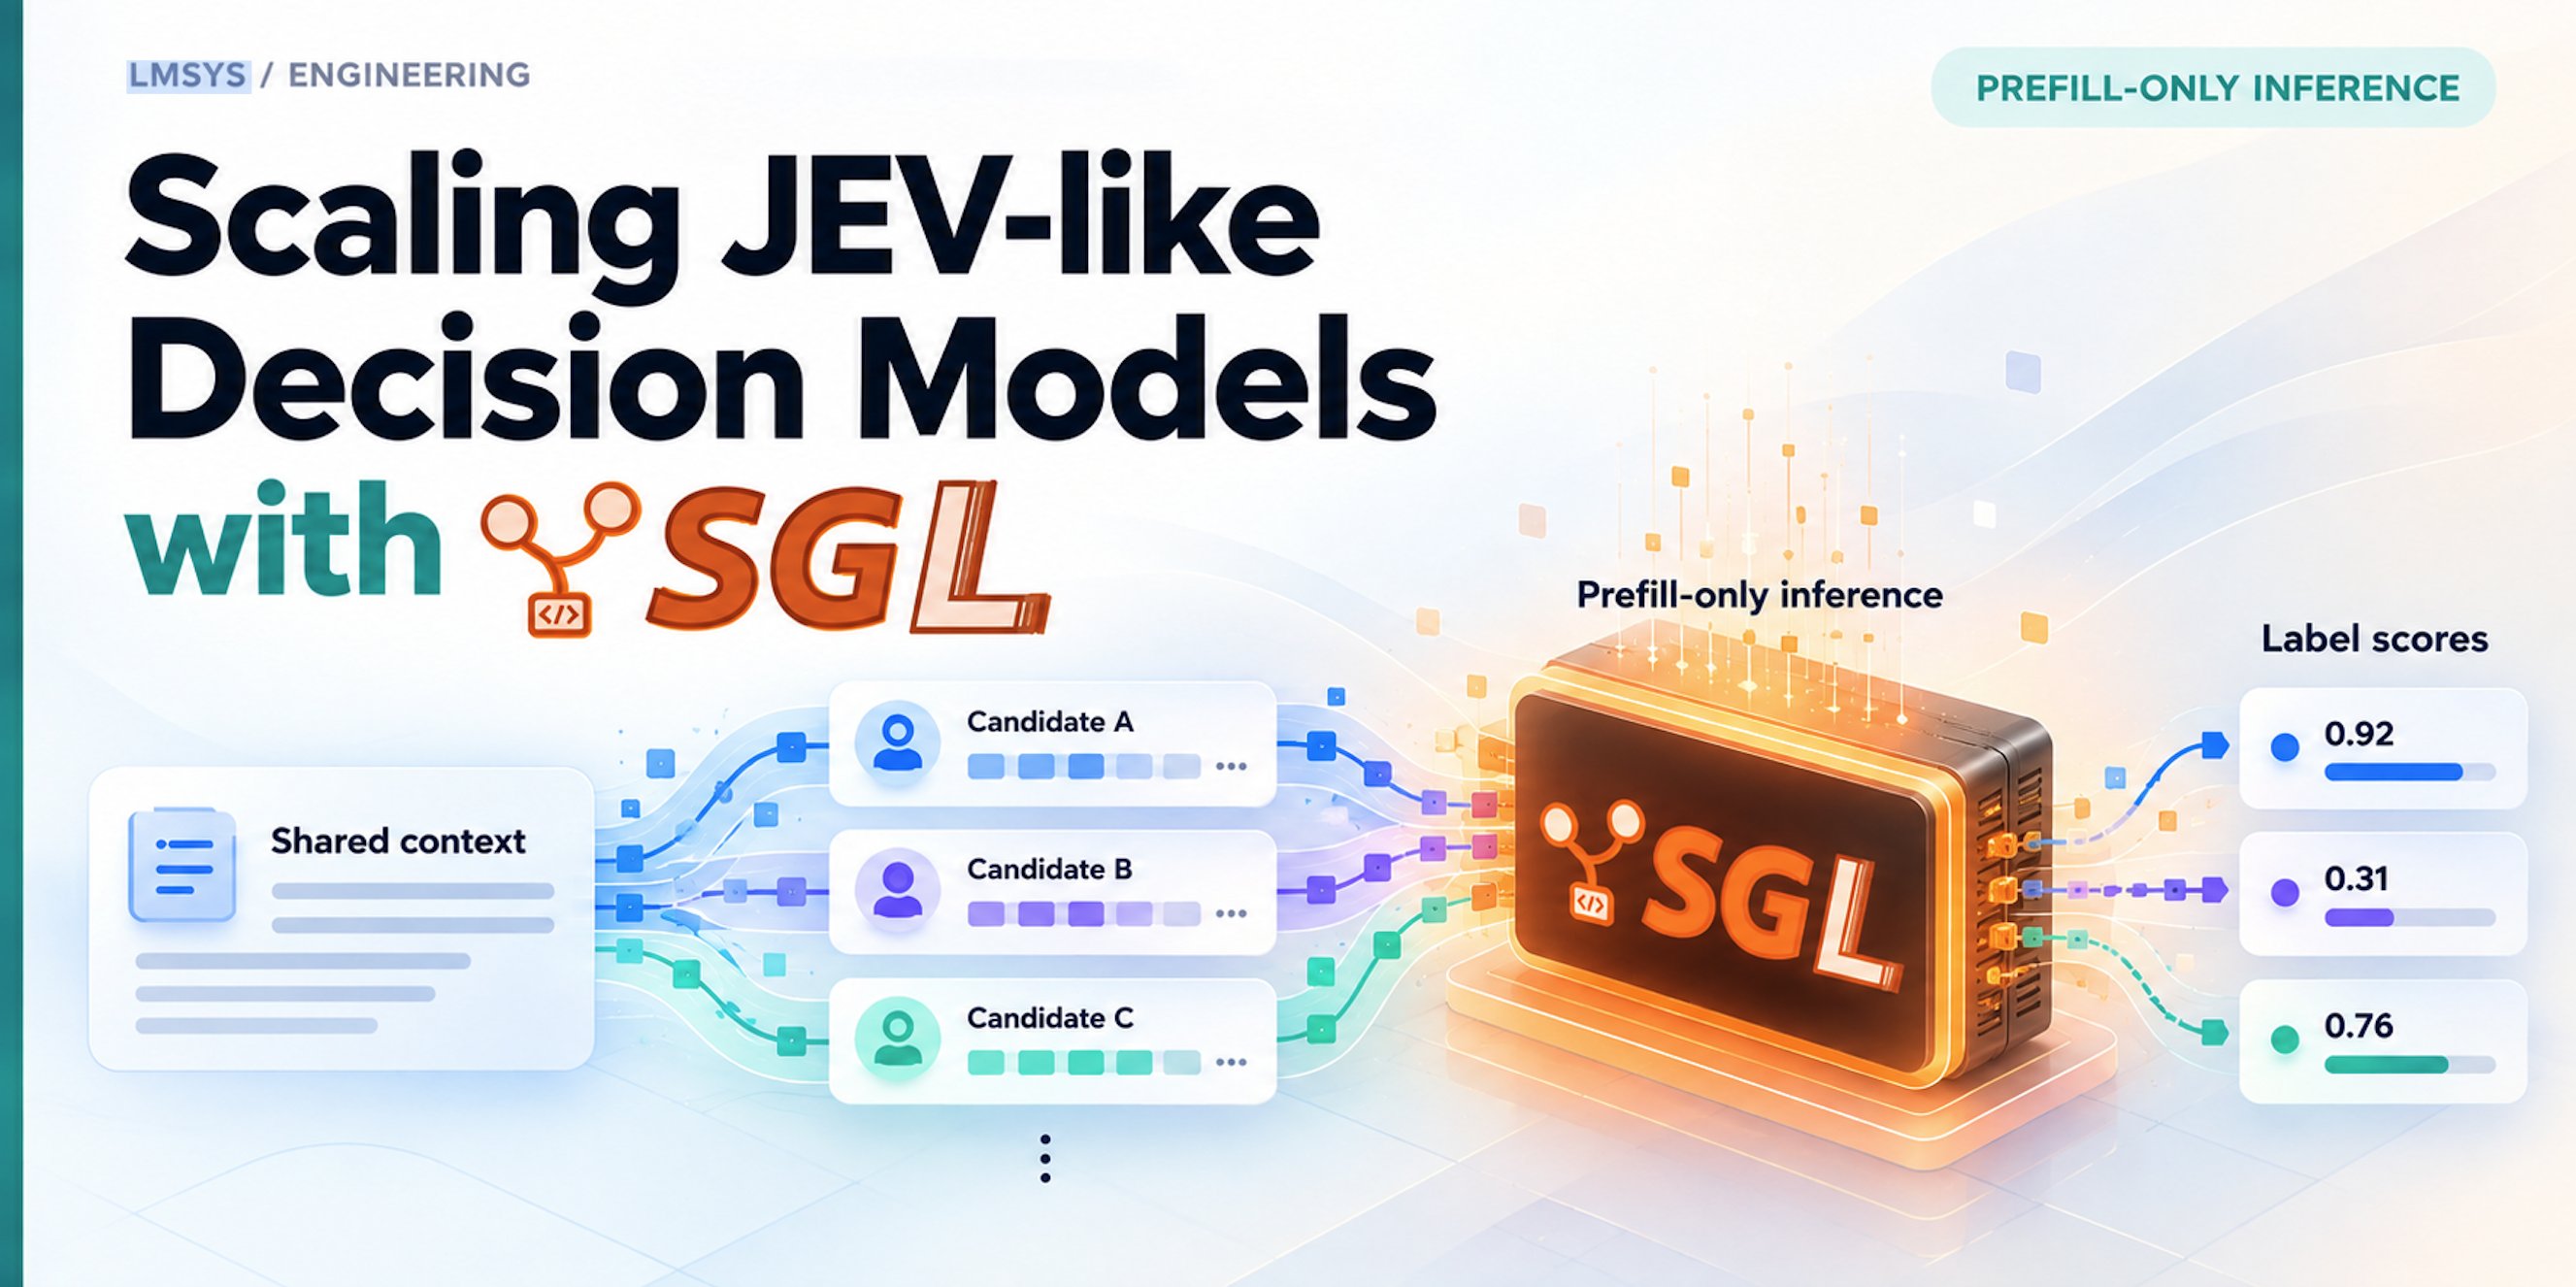
🚀 New blog: Scaling JEV-like decision models with SGLang Decision models need a score, not prose. Classification, ranking, and agent action selection all ask the same thing: which option wins? Open-Jev, for example, scores each candidate separately with a Yes/No prompt. Serving this well raises two issues: Generate + top-k logprobs can drop the label you need, and the shared context can be recomputed for every candidate. SGLang addresses both: - /v1/score returns scores for the exact labels you request (Yes/No, A/B/C) - Multi-item scoring (MIS) computes the shared context once and keeps each candidate isolated - MIS latency stays nearly flat from 2 to 16 candidates, with 16-candidate p95 on Qwen3-8B dropping from 54.1 ms (Generate) to 20.6 ms (MIS) - MIS p95 stays under ~100 ms as load rises on Qwen3-0.6B, vs. seconds for Generate and SIS Huge thanks to the @LinkedIn team for contributing! Benchmarks and launch commands in the blog 👇