xAI 内部 Grok Bot 的十个设计要点
从给模型配持久电脑、按部门拆分专职 Bot,到用 Chief of Staff 协调、把提示词变成基础设施,梳理 xAI 自用 Grok Bot 的架构。
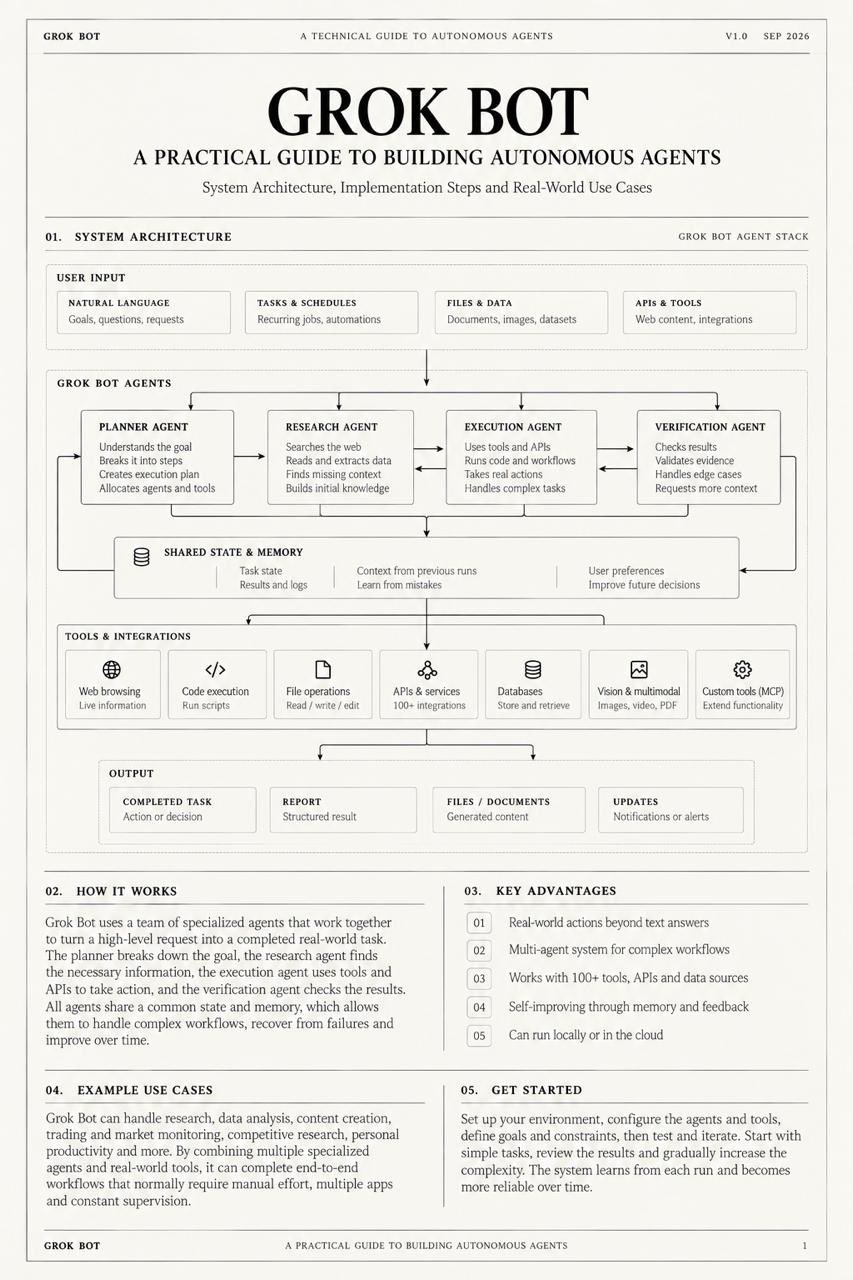
xAI built Grok Bot internally because even Grok 4.7 wasn't enough to automate real work it hits 71% on DeepSWE, yet xAI gave it a persistent computer after terminal performance jumped from 20.3% to 37.6% in one generation step 1 → stop treating the model as the product Grok Bot wraps Grok 4.7 inside a browser, filesystem and terminal so the agent can operate software instead of explaining what you should click step 2 → give that model a machine that doesn't disappear long-running jobs can continue in the cloud after you close your laptop instead of dying with the chat session step 3 → don't build one super-agent xAI split its own Bots across sales, marketing, finance, product, operations and engineering, then let the specialists communicate with each other step 4 → put a manager above the agents xAI employees are already using a “Chief of Staff” Bot to coordinate specialist Bots instead of manually routing every task step 5 → separate thinking from coding Grok Bot can pull context from Slack + Notion + GitHub, package the task, then hand it to Cursor's cloud agent to actually write the code step 6 → turn prompts into infrastructure one Bot can hold up to 50 routines, turning dozens of recurring jobs into repeatable workflows instead of dozens of separate chats step 7 → remove the prompt completely schedules, Slack messages, GitHub events and other Bots can trigger the next run automatically step 8 → reuse the ecosystem instead of rebuilding it Grok Bot supports MCP servers, plugins and skills, putting Gmail, Calendar, Drive and internal tools inside the same workflow step 9 → put another AI between the agent and the real world sensitive actions can pass through a separate reviewer that approves, blocks or escalates them before execution step 10 → now look at the benchmark that actually matters Grok 4.6 scored 20.3% on Terminal-Bench Grok 4.7 reached 37.6% that's an ~85% relative jump on a benchmark built around agents operating through a terminal and suddenly the architecture makes sense 71% DeepSWE gives it serious coding ability 37.6% Terminal-Bench pushes it further into real computer work 50 routines per Bot turns that capability into repeatable automation persistent computers keep the work alive specialist Bots parallelize it reviewers put boundaries around it xAI didn't build another chatbot they're building the operating system around the model
这条是引用着另一条写的:x.com/lummox_eth/status/2091129113972994356