Astra 与 Fable 5.1 数数能力对比
低推理档下数文本字符:1280 字符时 Astra 准确率 93%,Fable 5.1 仅 53%,且后者曲线非单调。
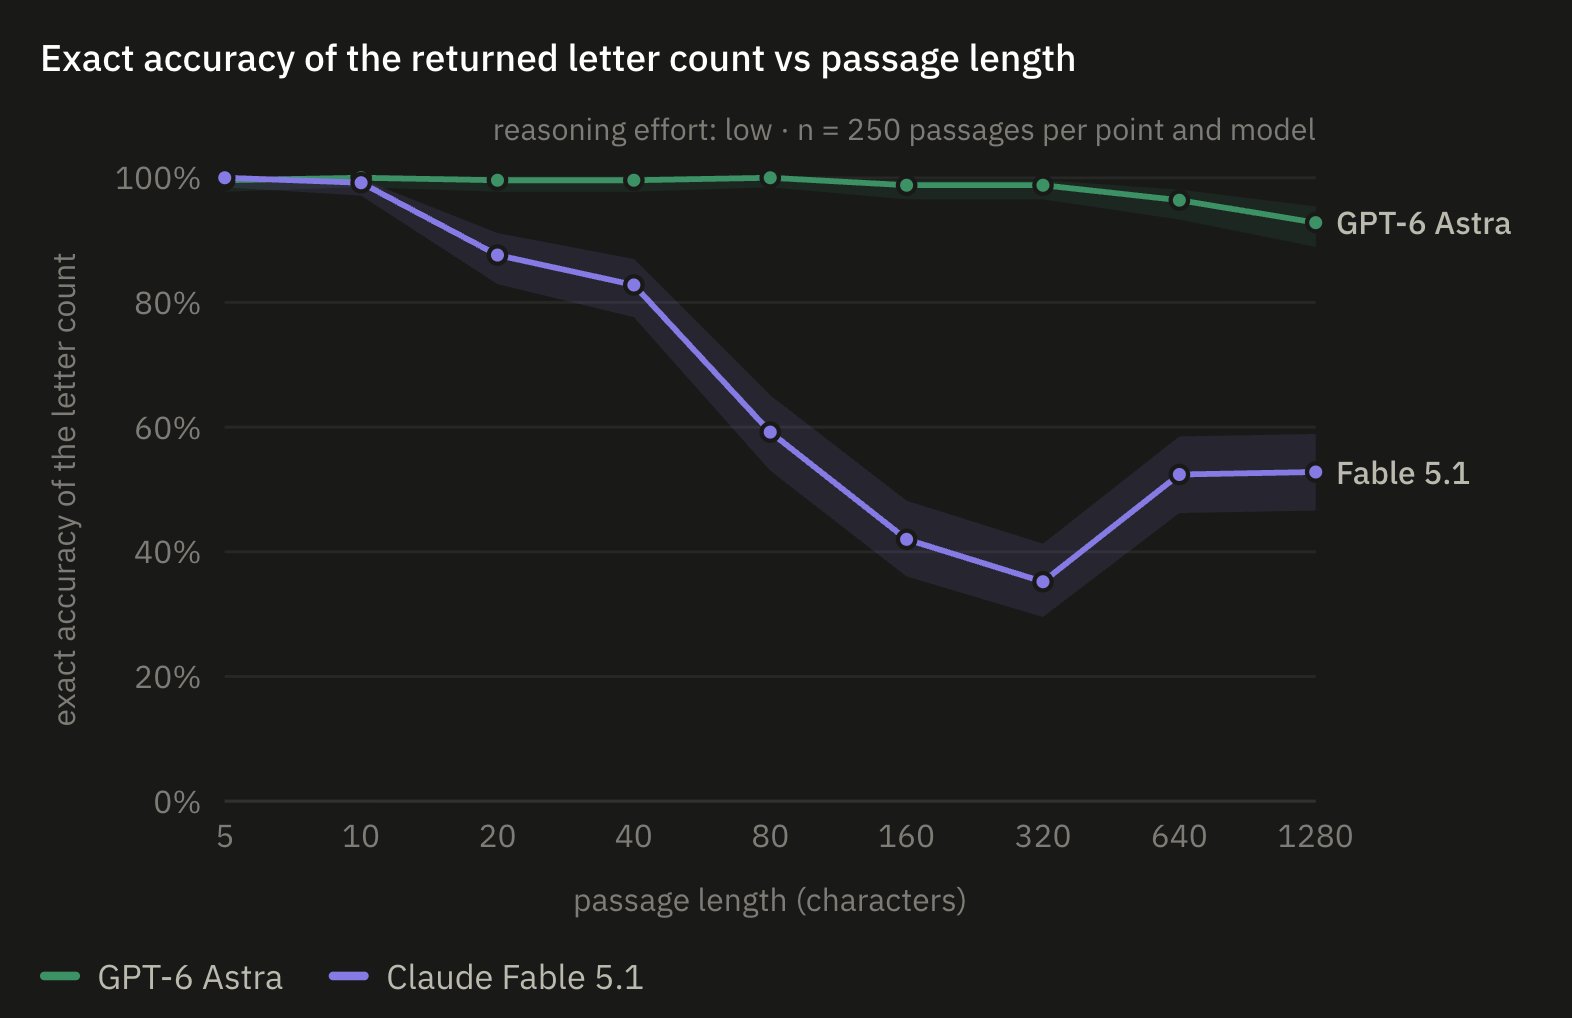
Can frontier LLMs count letters in text passages? This task is very simple but is out-of-distribution for frontier LLMs that are benchmaxxed on SWE-Bench and TerminalBench-like tasks, but not on simple counting! It turns out there is a large gap between the behavior of GPT-6-Astra and Fable 5.1 at low reasoning effort: Astra maintains very high accuracy (93% at 1280 characters), while Fable fails much more often (53% at 1280 characters). Interestingly, the Fable curve is not monotonic. This is again a failure of Fable's adaptive thinking: roughly until 320 character the model decides to not use any thinking tokens at all, while that would've increased the counting accuracy. The motivation for this experiment comes from understanding the no/low-CoT performance and whether avoiding using CoT would be sufficient for these models to implement complex solutions (e.g., scheming) without verbalizing this in the CoT. 1/5