APEX-Agents 1.1 榜单:Astra 排第五
Mercor 更新智能体基准,不再奖励含糊回答;Claude Fable 5.1 居首,GPT-6 Astra 以 64.7% 排第五。
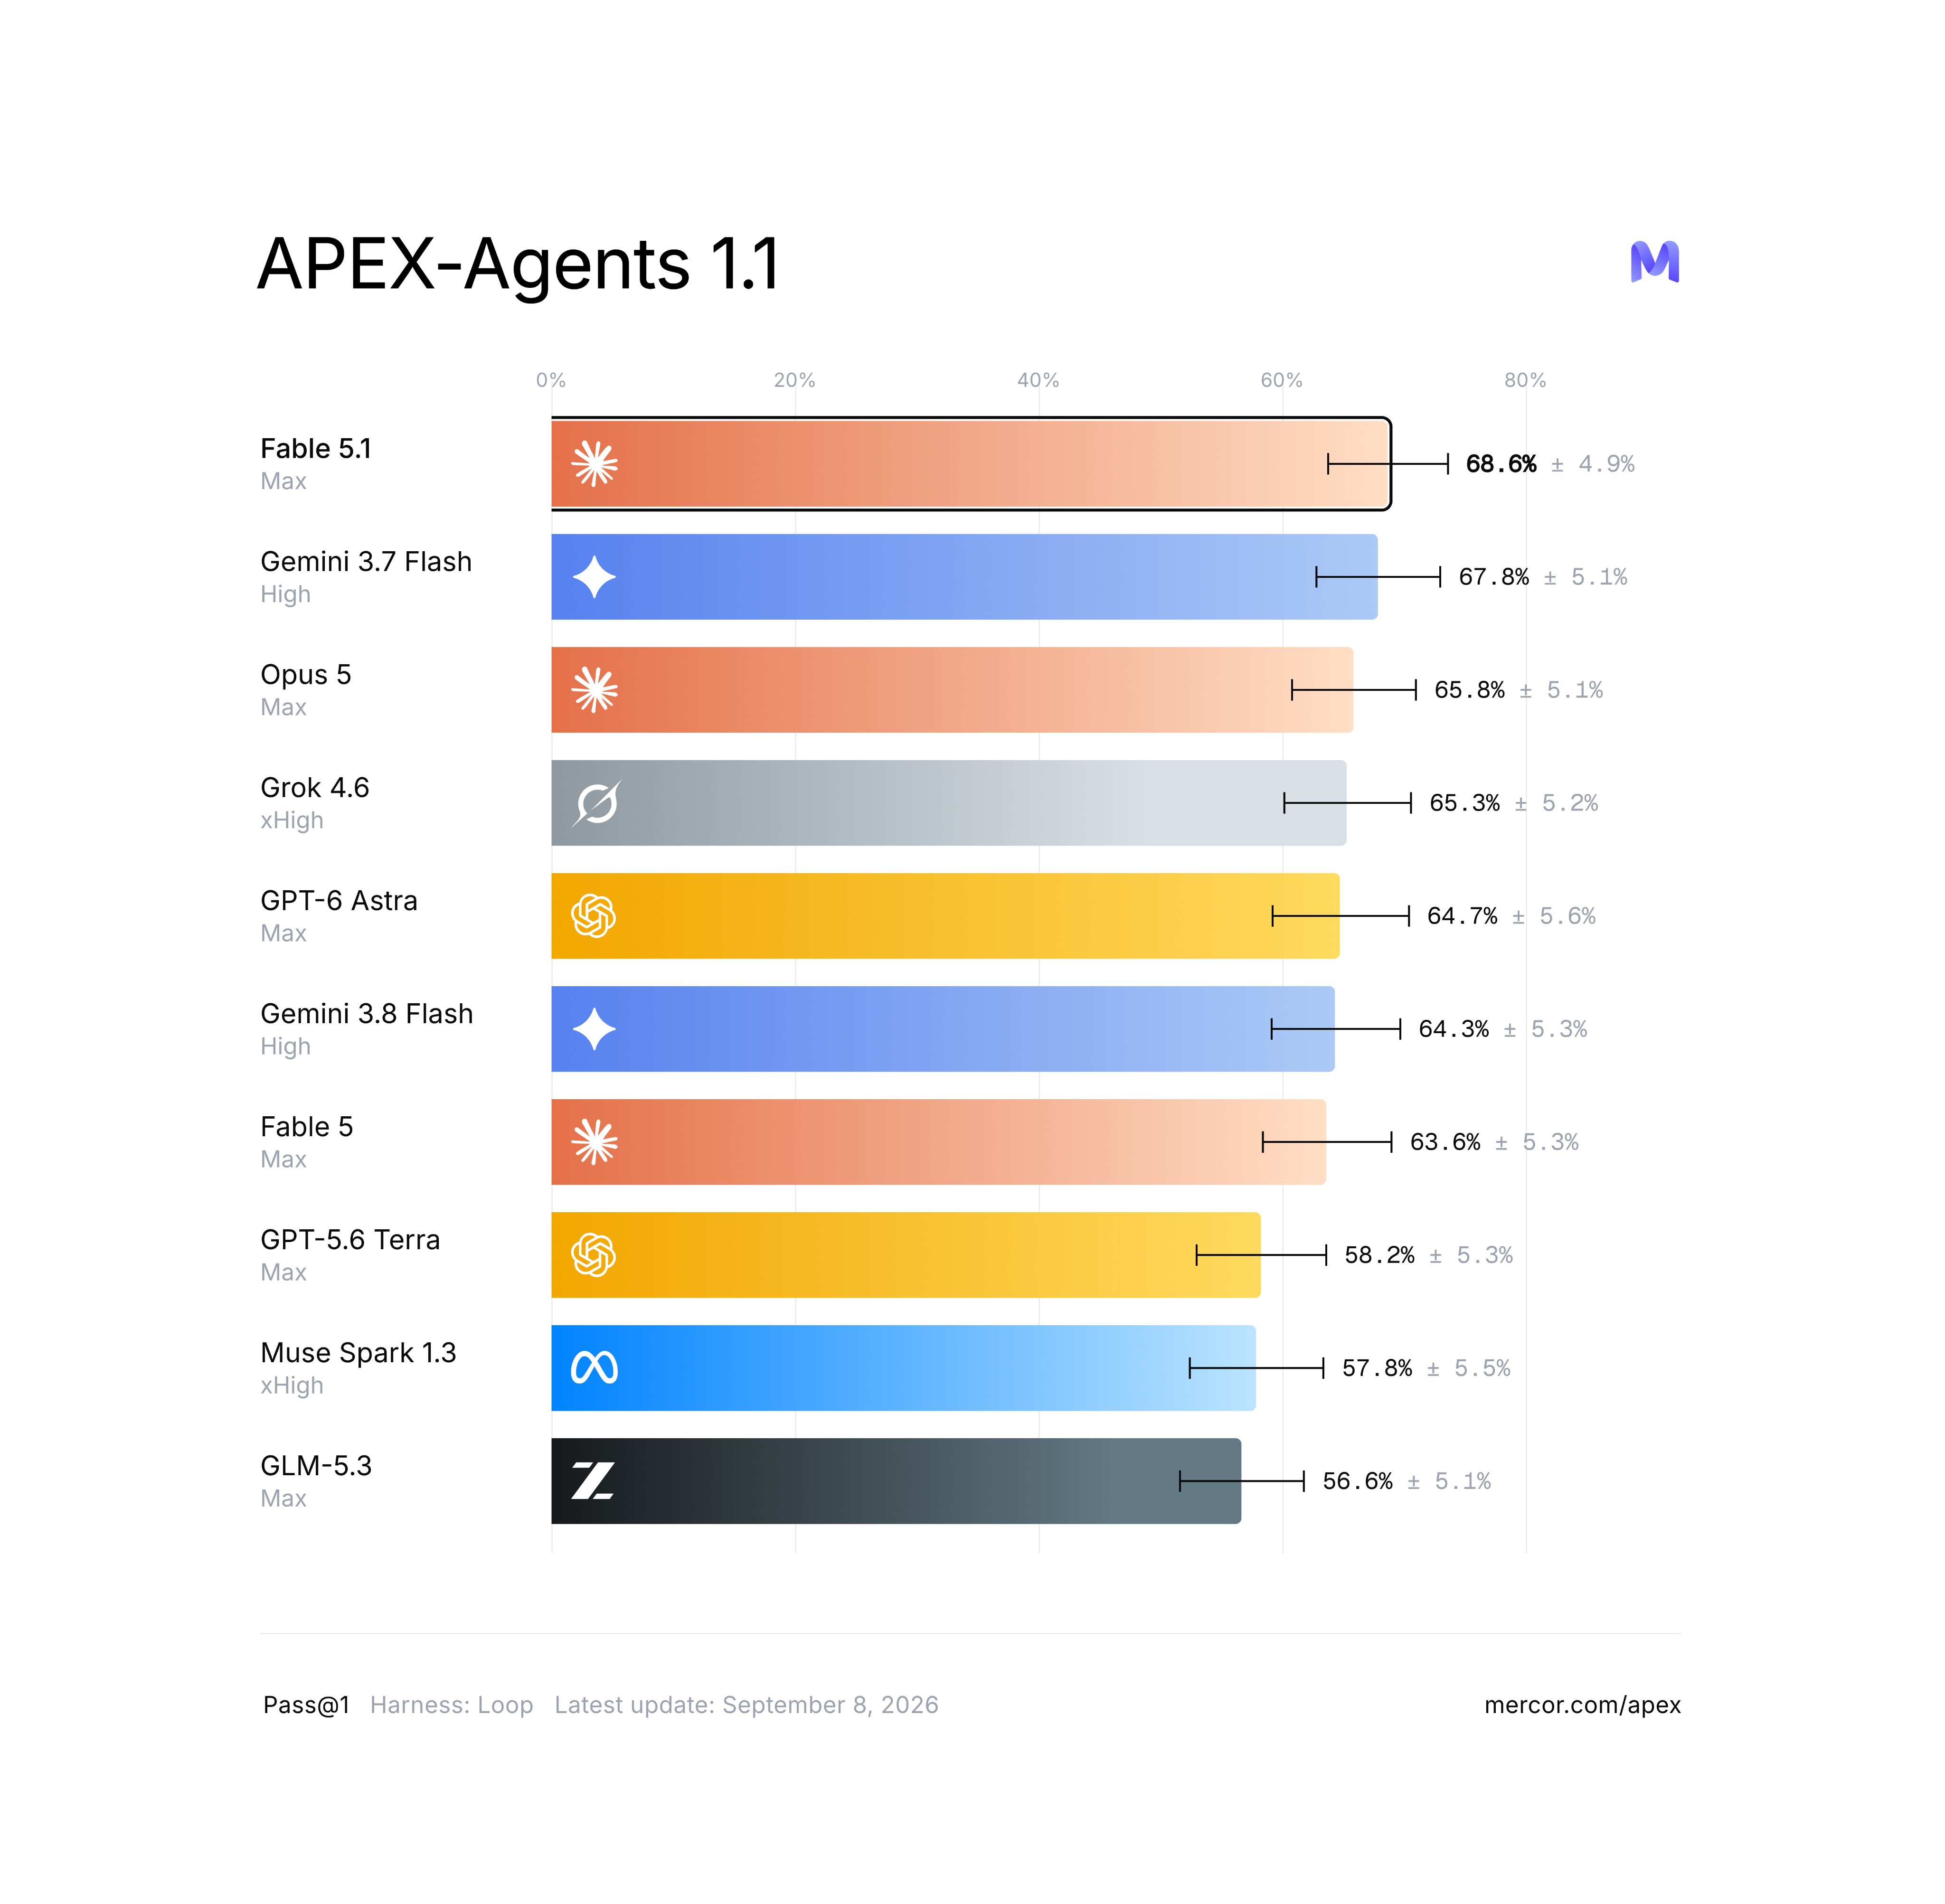
Today we're introducing APEX-Agents 1.1. As AI models advance, so do their methods to solve APEX-Agents tasks. We’re updating our benchmark with task specifications, tooling, and environments to maintain leaderboard accuracy. Most notably, APEX-Agents 1.1 no longer rewards noncommittal answers. This ensures that our tasks and grading align with how professionals operate. Claude Fable 5.1 remains on top of the leaderboard with 68.6% on Pass@1, though rankings have shifted throughout the rest of the board. Updated rankings for Pass@1: Claude Fable 5.1: 68.6% Gemini 3.7 Flash: 67.8% Claude Opus 5: 65.8% Grok 4.6: 65.3% GPT-6 Astra: 64.7% Read the announcement blog: https://www.mercor.com/blog/introducing-apex-agents-1-1/