GPT-6.1 Sol 在 APEX 基准逼近 Astra
Mercor 实测 GPT-6.1 Sol 在 APEX-Agents 得 60.0% Pass@1,距 Astra 仅 4.7 分,投行场景反超 Astra,价格却只有其五分之一。
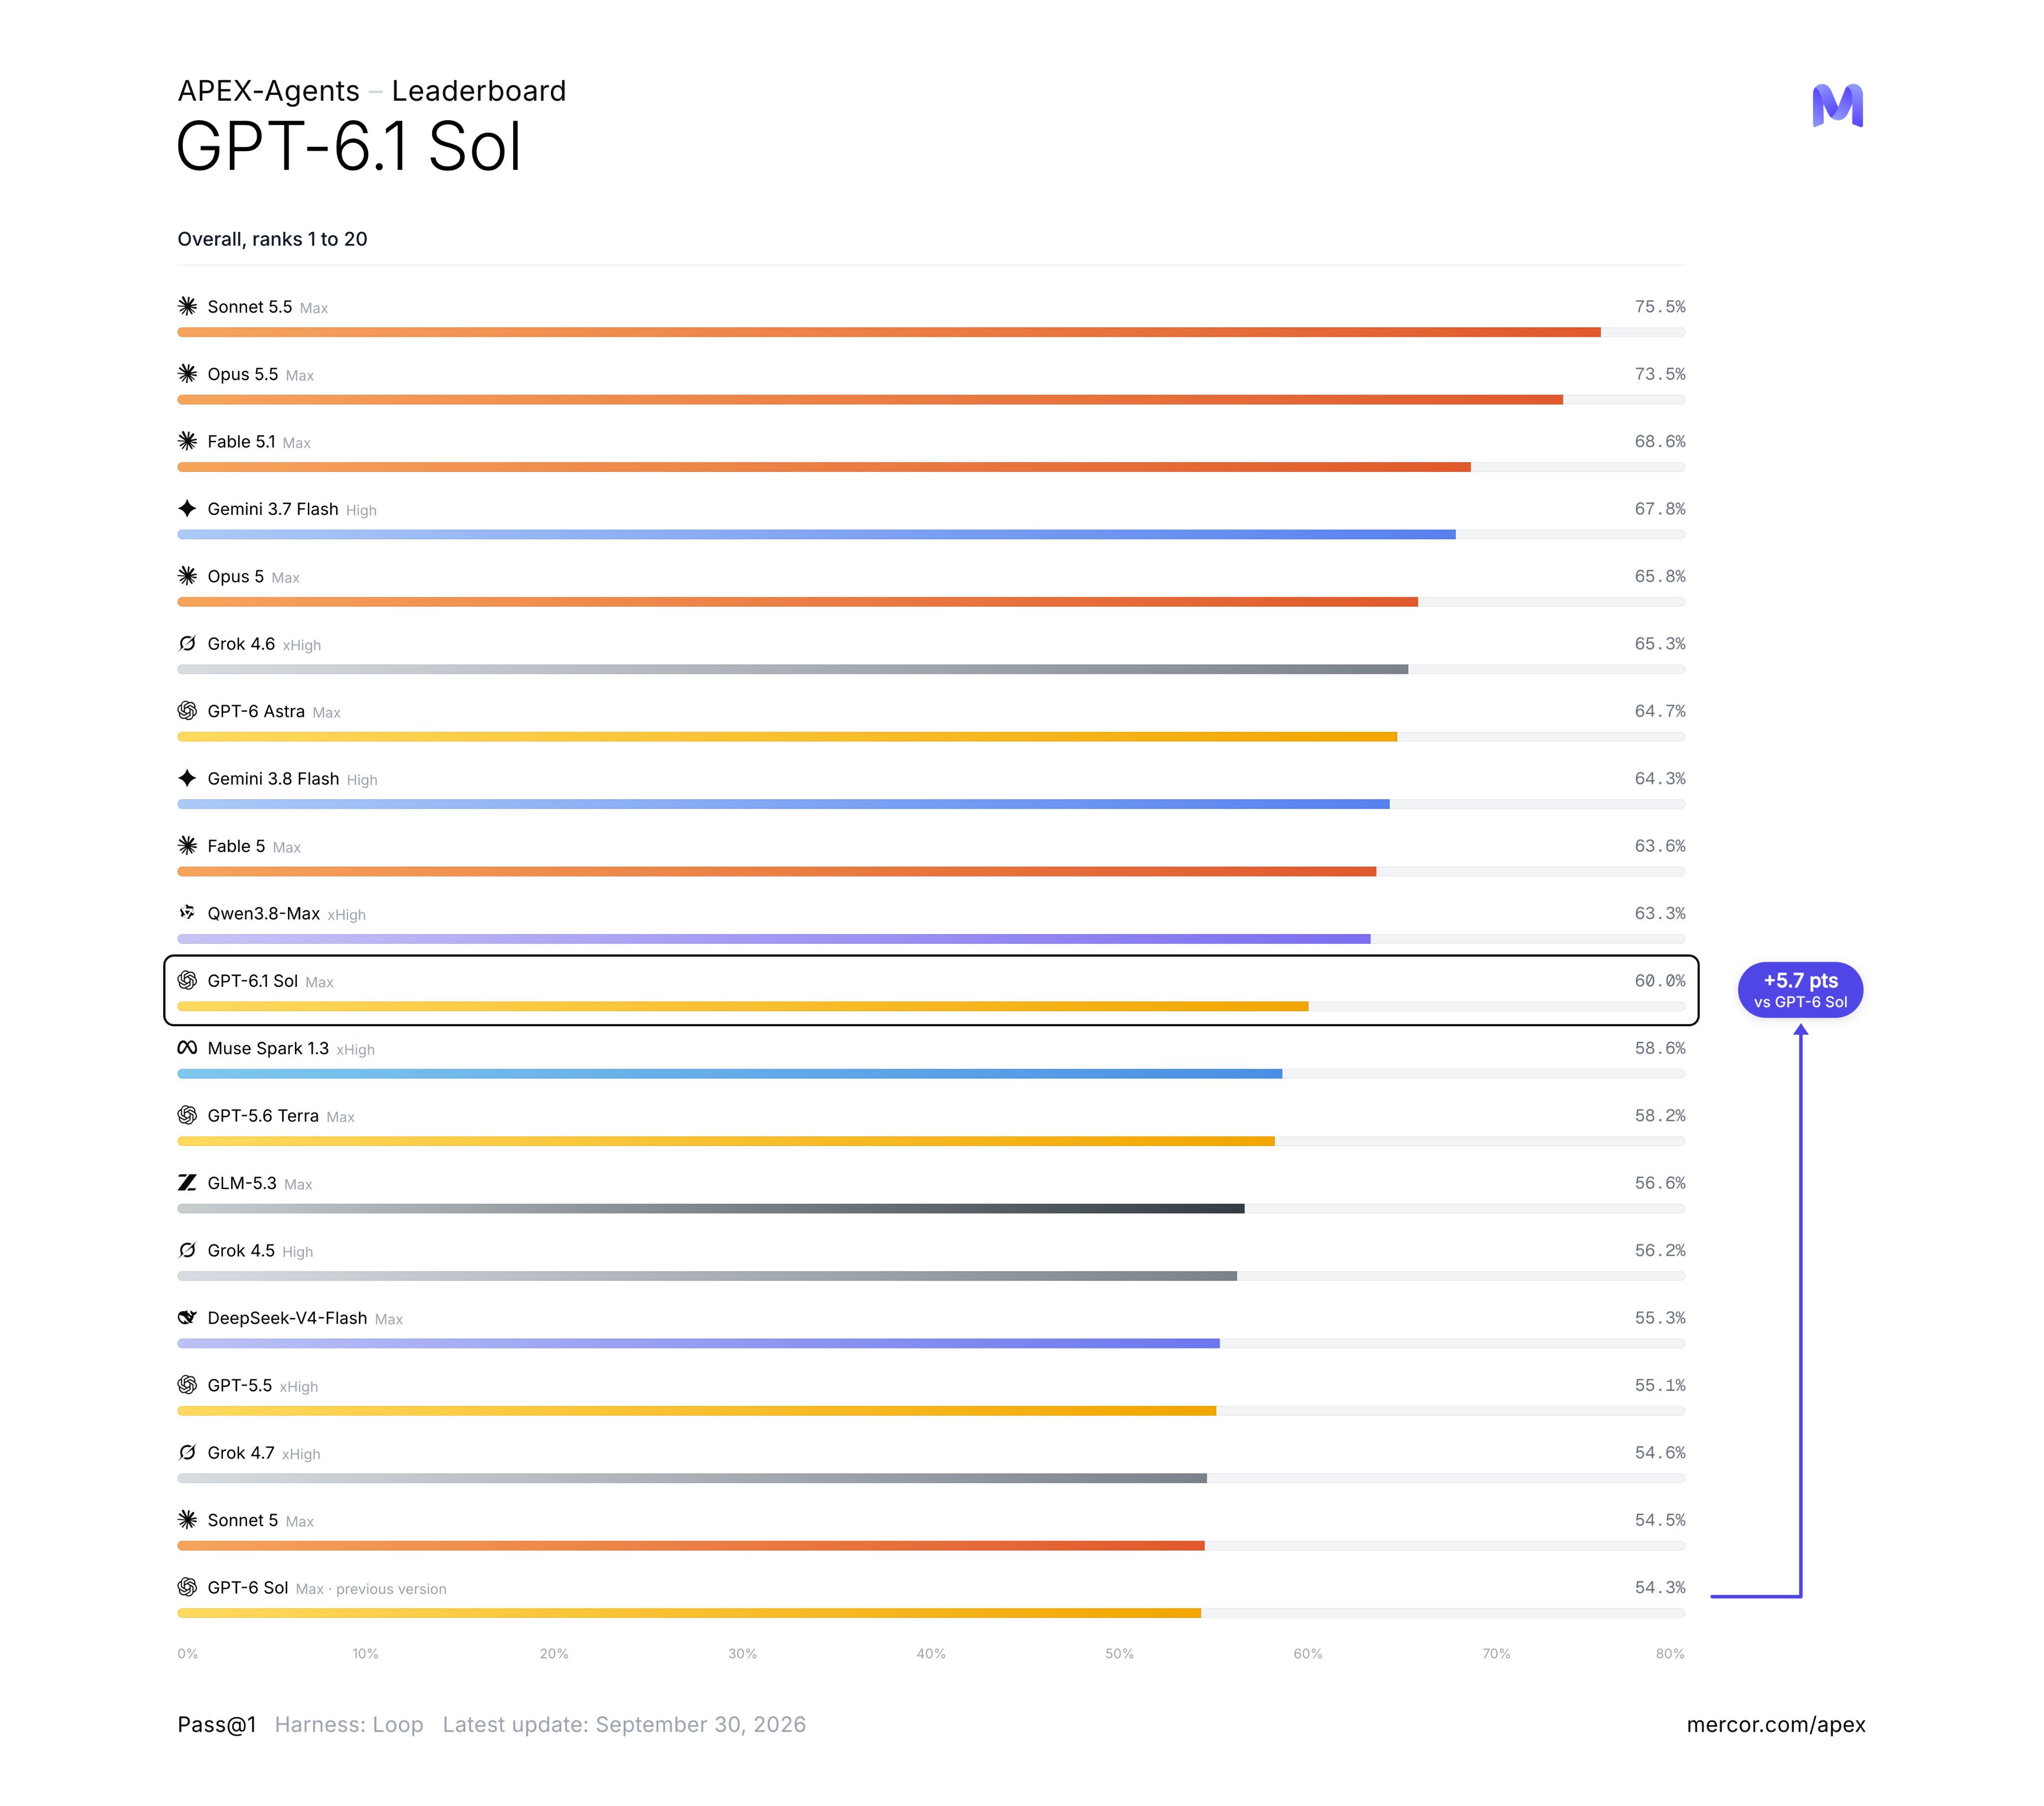
GPT-6.1 Sol scores 60.0% Pass@1 and 73.2% mean on APEX-Agents (#11), and 46.9% on APEX-SWE (#18). @OpenAI says it nearly matches GPT-6 Astra on professional work "at one-fifth of Astra's standard input and output token prices." That is consistent with what we’re seeing on APEX, within 4.7 points of Astra on Agents and 3.1 points on SWE. 𝗔𝗣𝗘𝗫-𝗔𝗴𝗲𝗻𝘁𝘀 GPT-6.1 Sol improves Pass@1 across all APEX-Agents domains compared with GPT-6 Sol. Corporate law: 63.4% (#11), up 7.2 Management consulting: 58.4% (#12), up 6.8 Investment banking: 58.1% (#10), up 2.9 That makes GPT-6.1 Sol OpenAI's #2 model on APEX-Agents, behind Astra and ahead of GPT-5.6 Terra (58.2%). It improves 5.7 points over GPT-6 Sol overall. On investment banking, GPT-6.1 Sol beats Astra (55.9%). It is now OpenAI's top model there. For corporate law, GPT-6.1 Sol trails Astra by 10 points on Pass@1, but its mean score is 85.3%. Only 4% of law runs score zero. It does most of the work and misses a rubric item or two. 𝗧𝗼𝗸𝗲𝗻𝘀 𝗮𝗻𝗱 𝗰𝗼𝗻𝘀𝗶𝘀𝘁𝗲𝗻𝗰𝘆 0.50M tokens per attempt on APEX-Agents. 1.29M per attempt on APEX-SWE. On law, failing runs use 2.4x the tokens of passing runs. GPT-6.1 Sol passed 49% of APEX-Agents tasks on all 4 runs. On APEX-SWE, 39%. 70 Agents tasks were never solved in any run. 𝗔𝗣𝗘𝗫-𝗦𝗪𝗘 GPT-6.1 Sol improves slightly over the prior generation with 46.9% (#18), up 1.9 from GPT-6 Sol. The gain is all in Observability where it scored 32.3% (#19), increasing by 4.5. Integration was mostly flat at 61.5%, scoring slightly below GPT-6 Sol (62.3%) and GPT-6 Astra (62.0%). Congrats @OpenAI on the launch. See full leaderboards: https://www.mercor.com/apex/