Jev 批量读 GDPR 长文:13 问一次调用省 12 倍
TypeSafe 实测把 13 个 Noul/Choice/Score 问题合并成一次 Jev 调用,成本降 12.2 倍、耗时降 10 倍,答案基本一致。
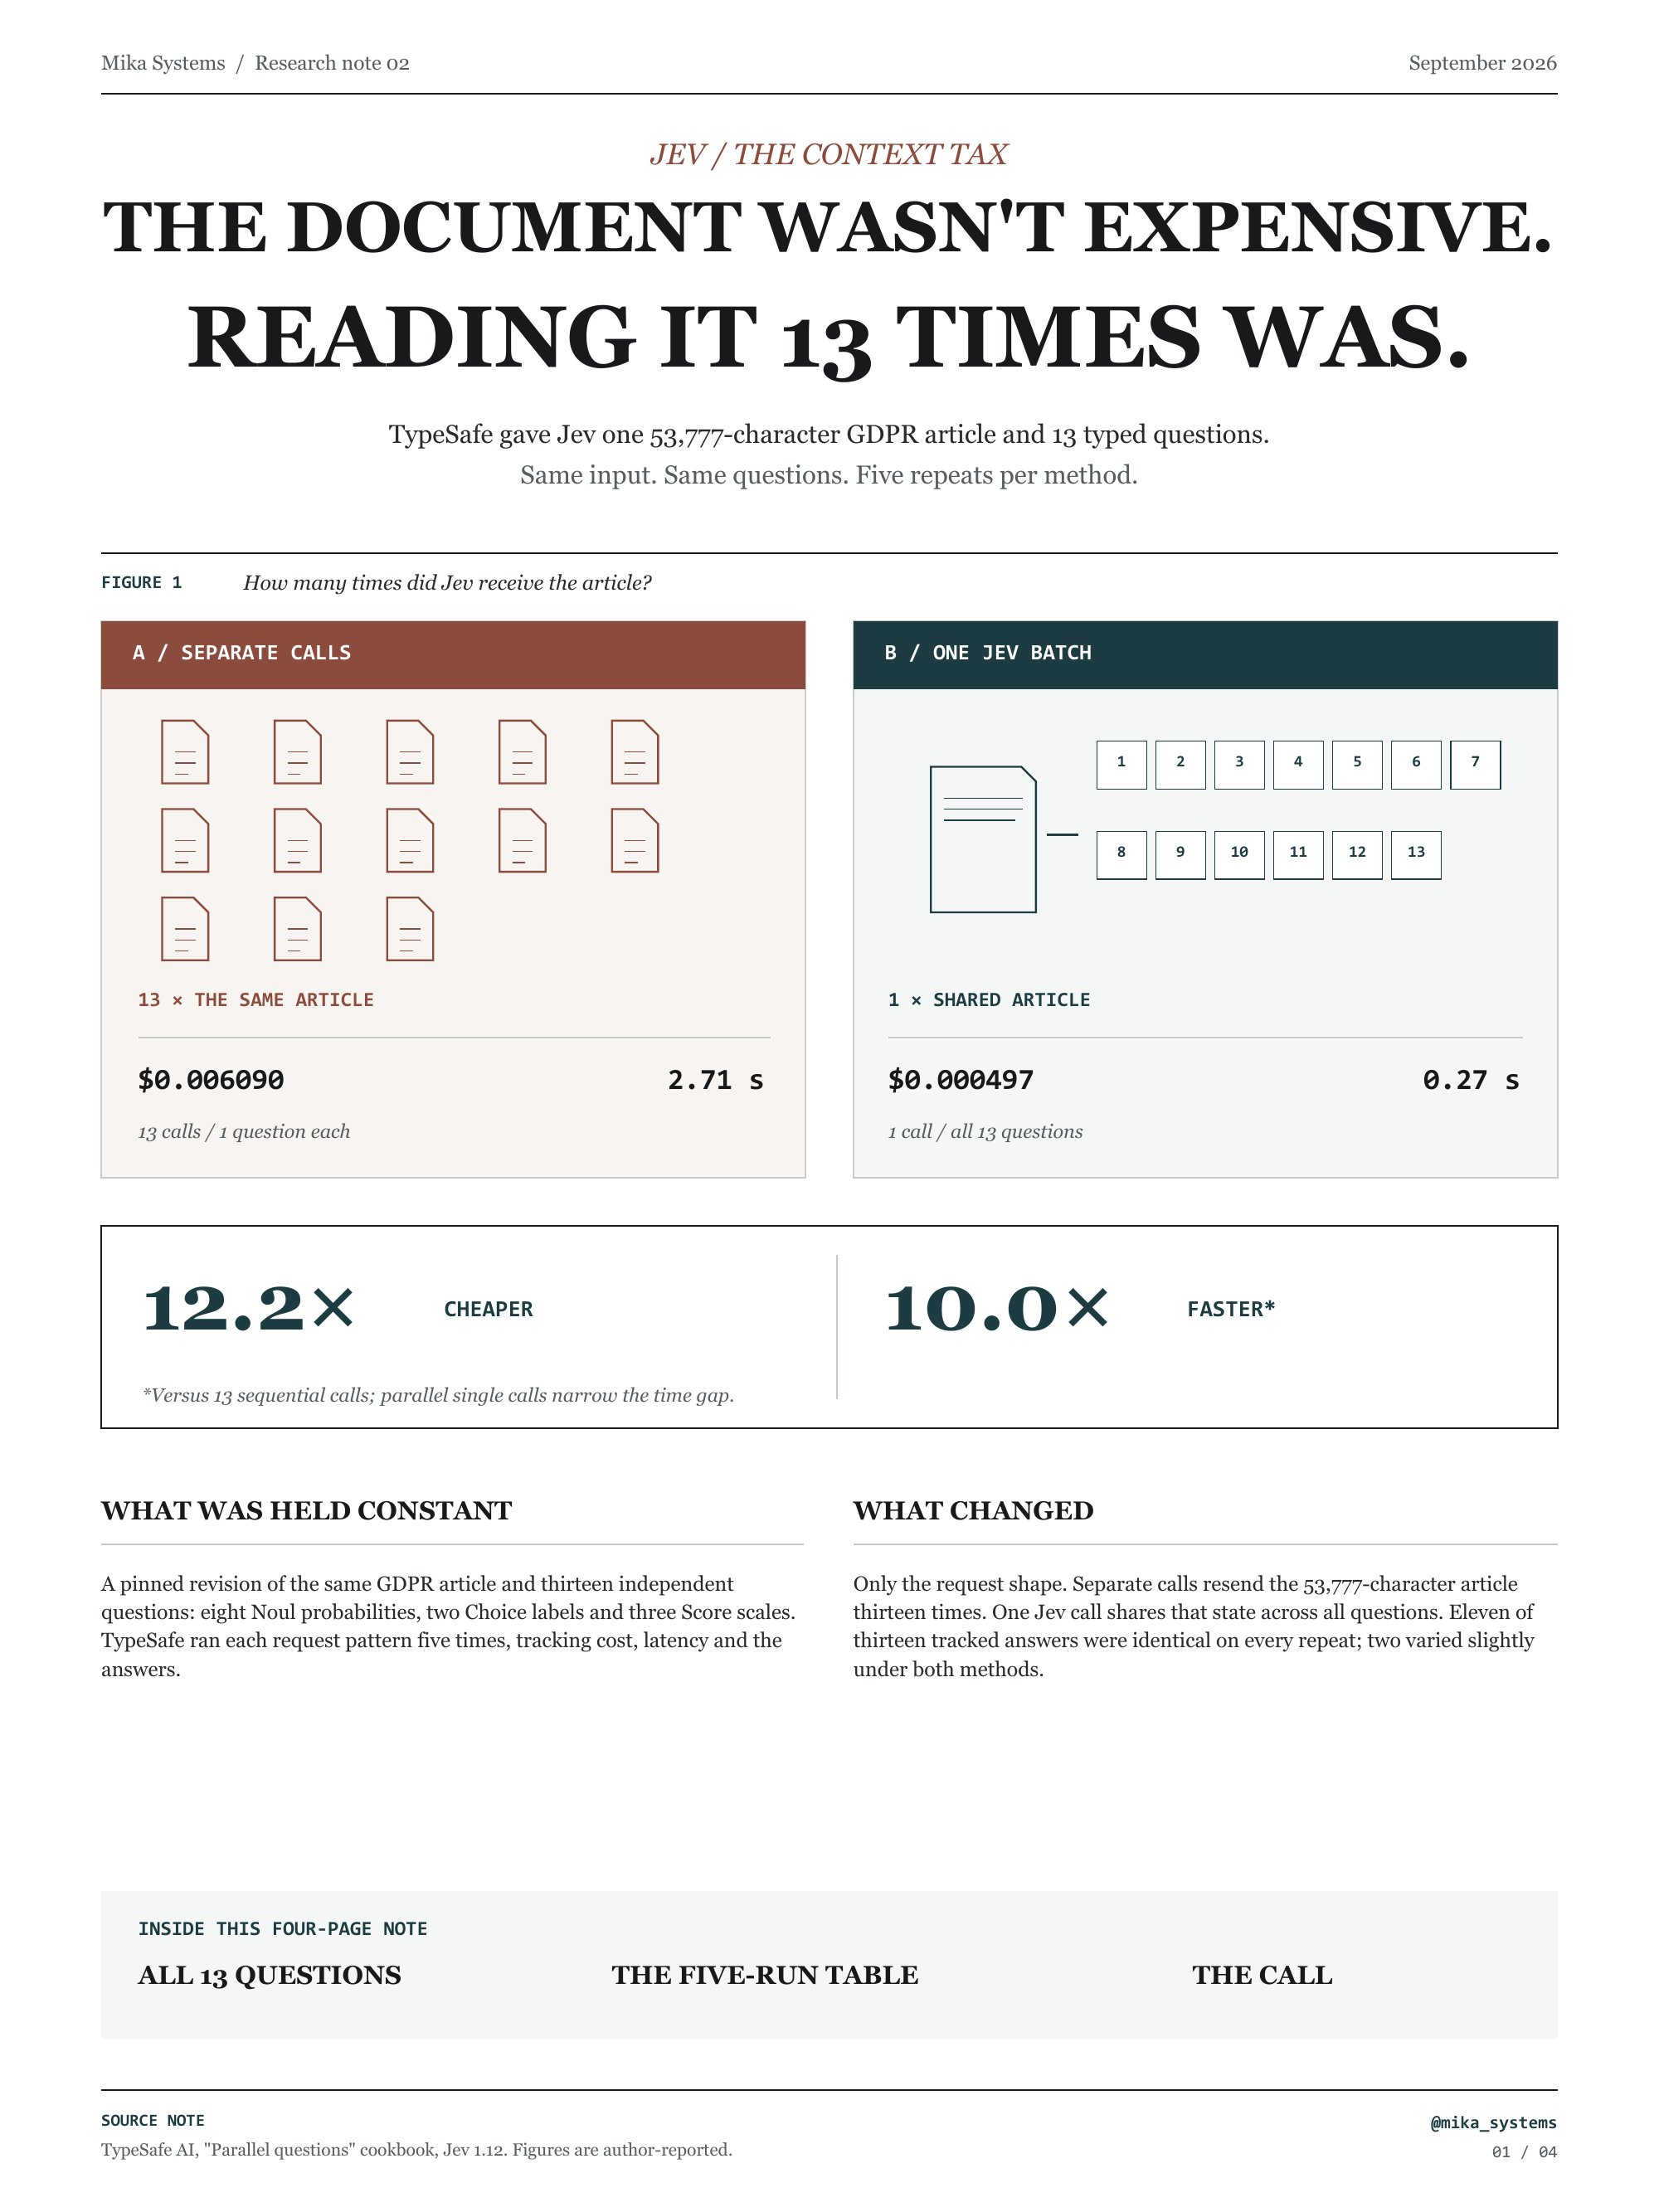
we've been paying AI to read the same document 13 times TypeSafe gave Jev a 53,777-character GDPR article and 13 questions: 8 Noul, 2 Choice and 3 Score. they tested two methods, five times each: > 13 separate calls, one question each > 1 Jev call containing all 13 questions batching didn't measurably change the answers. it changed the bill. 13 calls → $0.006090 → 2.71s 1 batch → $0.000497 → 0.27s 12.2× cheaper. 10.0× faster than sequential calls. the reason is almost stupidly simple: each separate call resends the entire article. Jev can read it once and score all 13 questions against the same state. if you're building this into an agent: > put the shared context into one state > define independent decisions up front > batch Choice, Score and Noul questions > execute high-confidence decisions in code > send uncertain cases to a human 11 of 13 tracked answers were identical across all five runs. the other two varied slightly under both methods. if your agent asks several questions about the same document, let Jev read it once. save the complete 4-page Jev field note - then read the full 9-step roadmap and four agent patterns in the article below ↓
这条是引用着另一条写的:x.com/mika_systems/status/2101686148338798610