模型发布IMAGE
Mirendil 发布首个模型 Fern:最高 1000 万 token 上下文
Mirendil 从零预训练的首个模型 Fern 支持最高 1000 万 token 上下文,面向审计训练数据、调试训练日志等 agentic AI 研发场景,更大版本在训练中。
Mirendil
@mirendil1 天前收录原推发布于 2026.10.27
Mirendil @mirendil原推发布于 2026.10.27
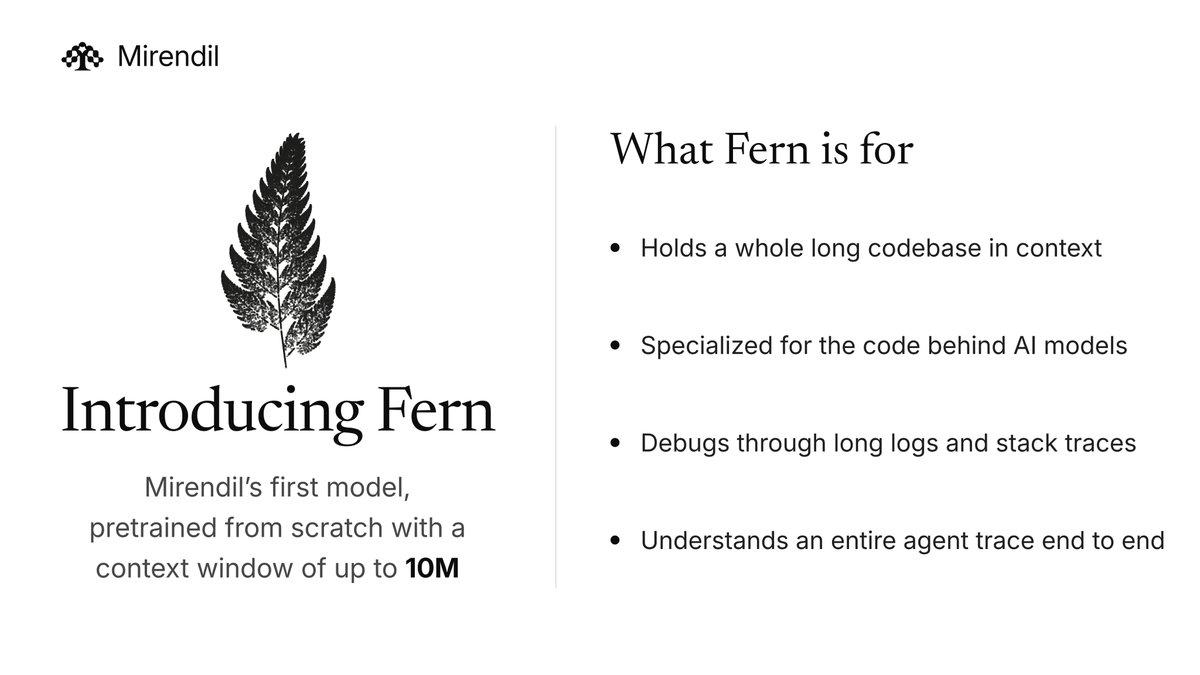
Introducing Fern, Mirendil’s first model: pretrained from scratch, with up to 10 million tokens of context. That’s ~0.5M lines of code or days of an agent’s work - all in context at once. Built for high-volume agentic work in AI R&D: auditing training data, debugging training runs from logs, and reading agent traces end to end. Fern’s next-token prediction keeps improving as context grows to 10M tokens. Fern 0.1 is Mirendil-Base after a short round of post-training. It’s the first and smallest of three models, with two larger ones now being pretrained. We’ll ship frequent updates and make the model available soon.
x.com/mirendil/status/2114750800526446987采集于 2026.10.27 10:29