jevIMAGE
MLflow 用 Jev 做 LLM 裁判并与 GPT/Claude 对比
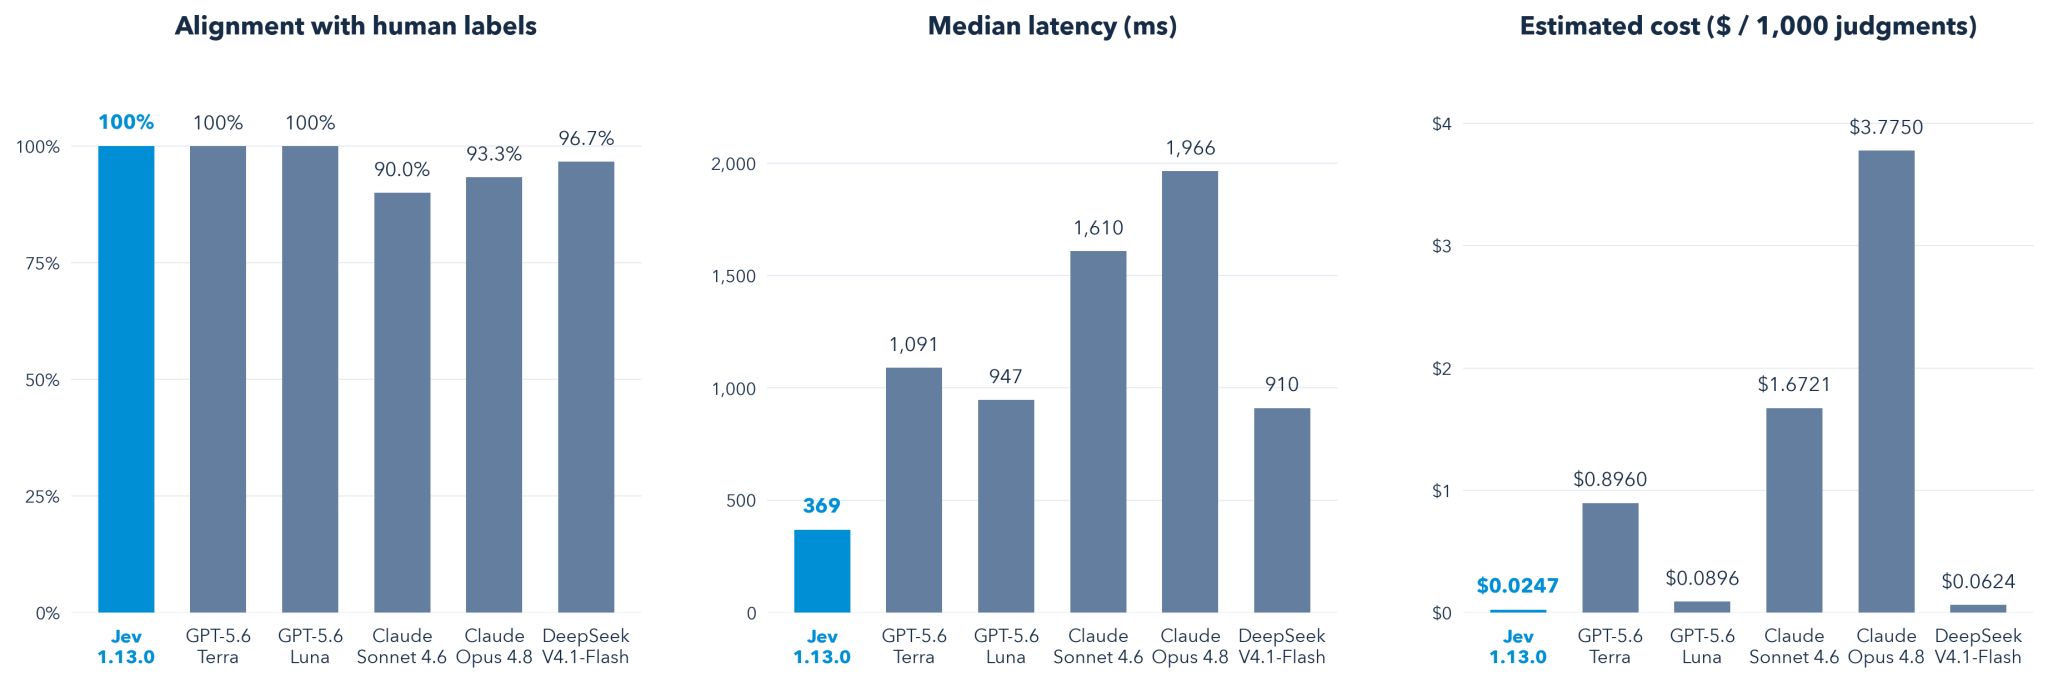
在 30 条人工标注 QA 上,Jev 与人类标注 30/30 一致,中位延迟 369ms,每千次判断约 0.0247 美元。
MLflow
@MLflow2026.09.26收录原推发布于 2026.09.25
MLflow @MLflow原推发布于 2026.09.25
We compared Jev, TypeSafe’s model for structured decisions, with GPT, Claude, and DeepSeek using MLflow. On 30 human-labeled QA examples, Jev matched the best agreement at lower cost and latency: ✅ 30/30 agreement with human labels ⚡ 369 ms median latency 💰 $0.0247 estimated cost per 1,000 judgments Our new blog walks through building a Jev scorer in MLflow, measuring quality, cost, and latency, and deciding when to use another judge. Try the same comparison on your own dataset. 📖 Full blog: https://mlflow.org/blog/jev-llm-judge/ #MLflow #OpenSource
x.com/mlflow/status/2103402881487389012采集于 2026.09.26 10:13