jevIMAGE
MLflow 3.17 支持 Jev 当 LLM 评测裁判
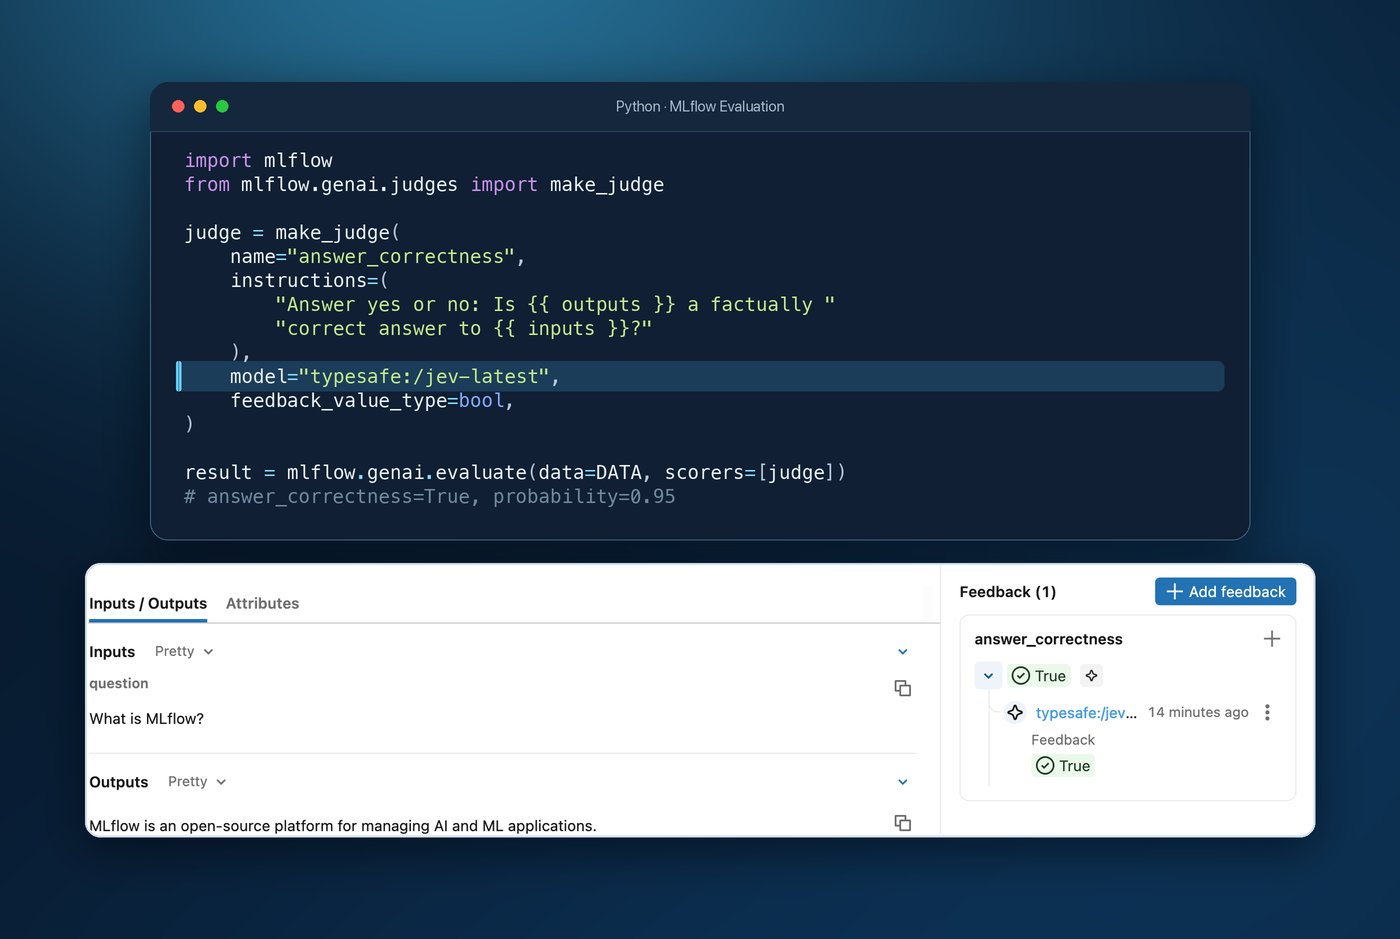
在 make_judge() 里设 model="typesafe:/jev-latest",Jev 返回结构化判定,MLflow 存为 assessment 并把概率写进 metadata,是非题评测不必每行都跑通用大模型。
MLflow
@MLflow18 天前收录原推发布于 2026.10.12
MLflow @MLflow原推发布于 2026.10.12
Yes/no evals don’t need a general-purpose LLM on every row. That gets slow and expensive at volume. In MLflow 3.17, TypeSafe’s Jev models work as judges. Keep your existing mlflow.genai.evaluate() flow and set model="typesafe:/jev-latest" on make_judge(). Jev returns a structured decision; MLflow stores it as an assessment and puts the probability in metadata, so close calls show up when you review. A versioned model ID keeps comparisons consistent across runs. 🔗 Learn more: https://mlflow.org/docs/latest/genai/eval-monitor/scorers/llm-judge/custom-judges/typesafe/ #MLflow #GenAI #LLMOps
x.com/mlflow/status/2109665792778277372采集于 2026.10.13 10:08