Jev 与 GPT-5.5、Opus 4.8 做 15 轮内容审核一致性测试
同一篇边界帖跑 8 问 15 次,看各模型是否翻队列,并对比每次调用价格 0.000046 美元 vs 0.041 美元。
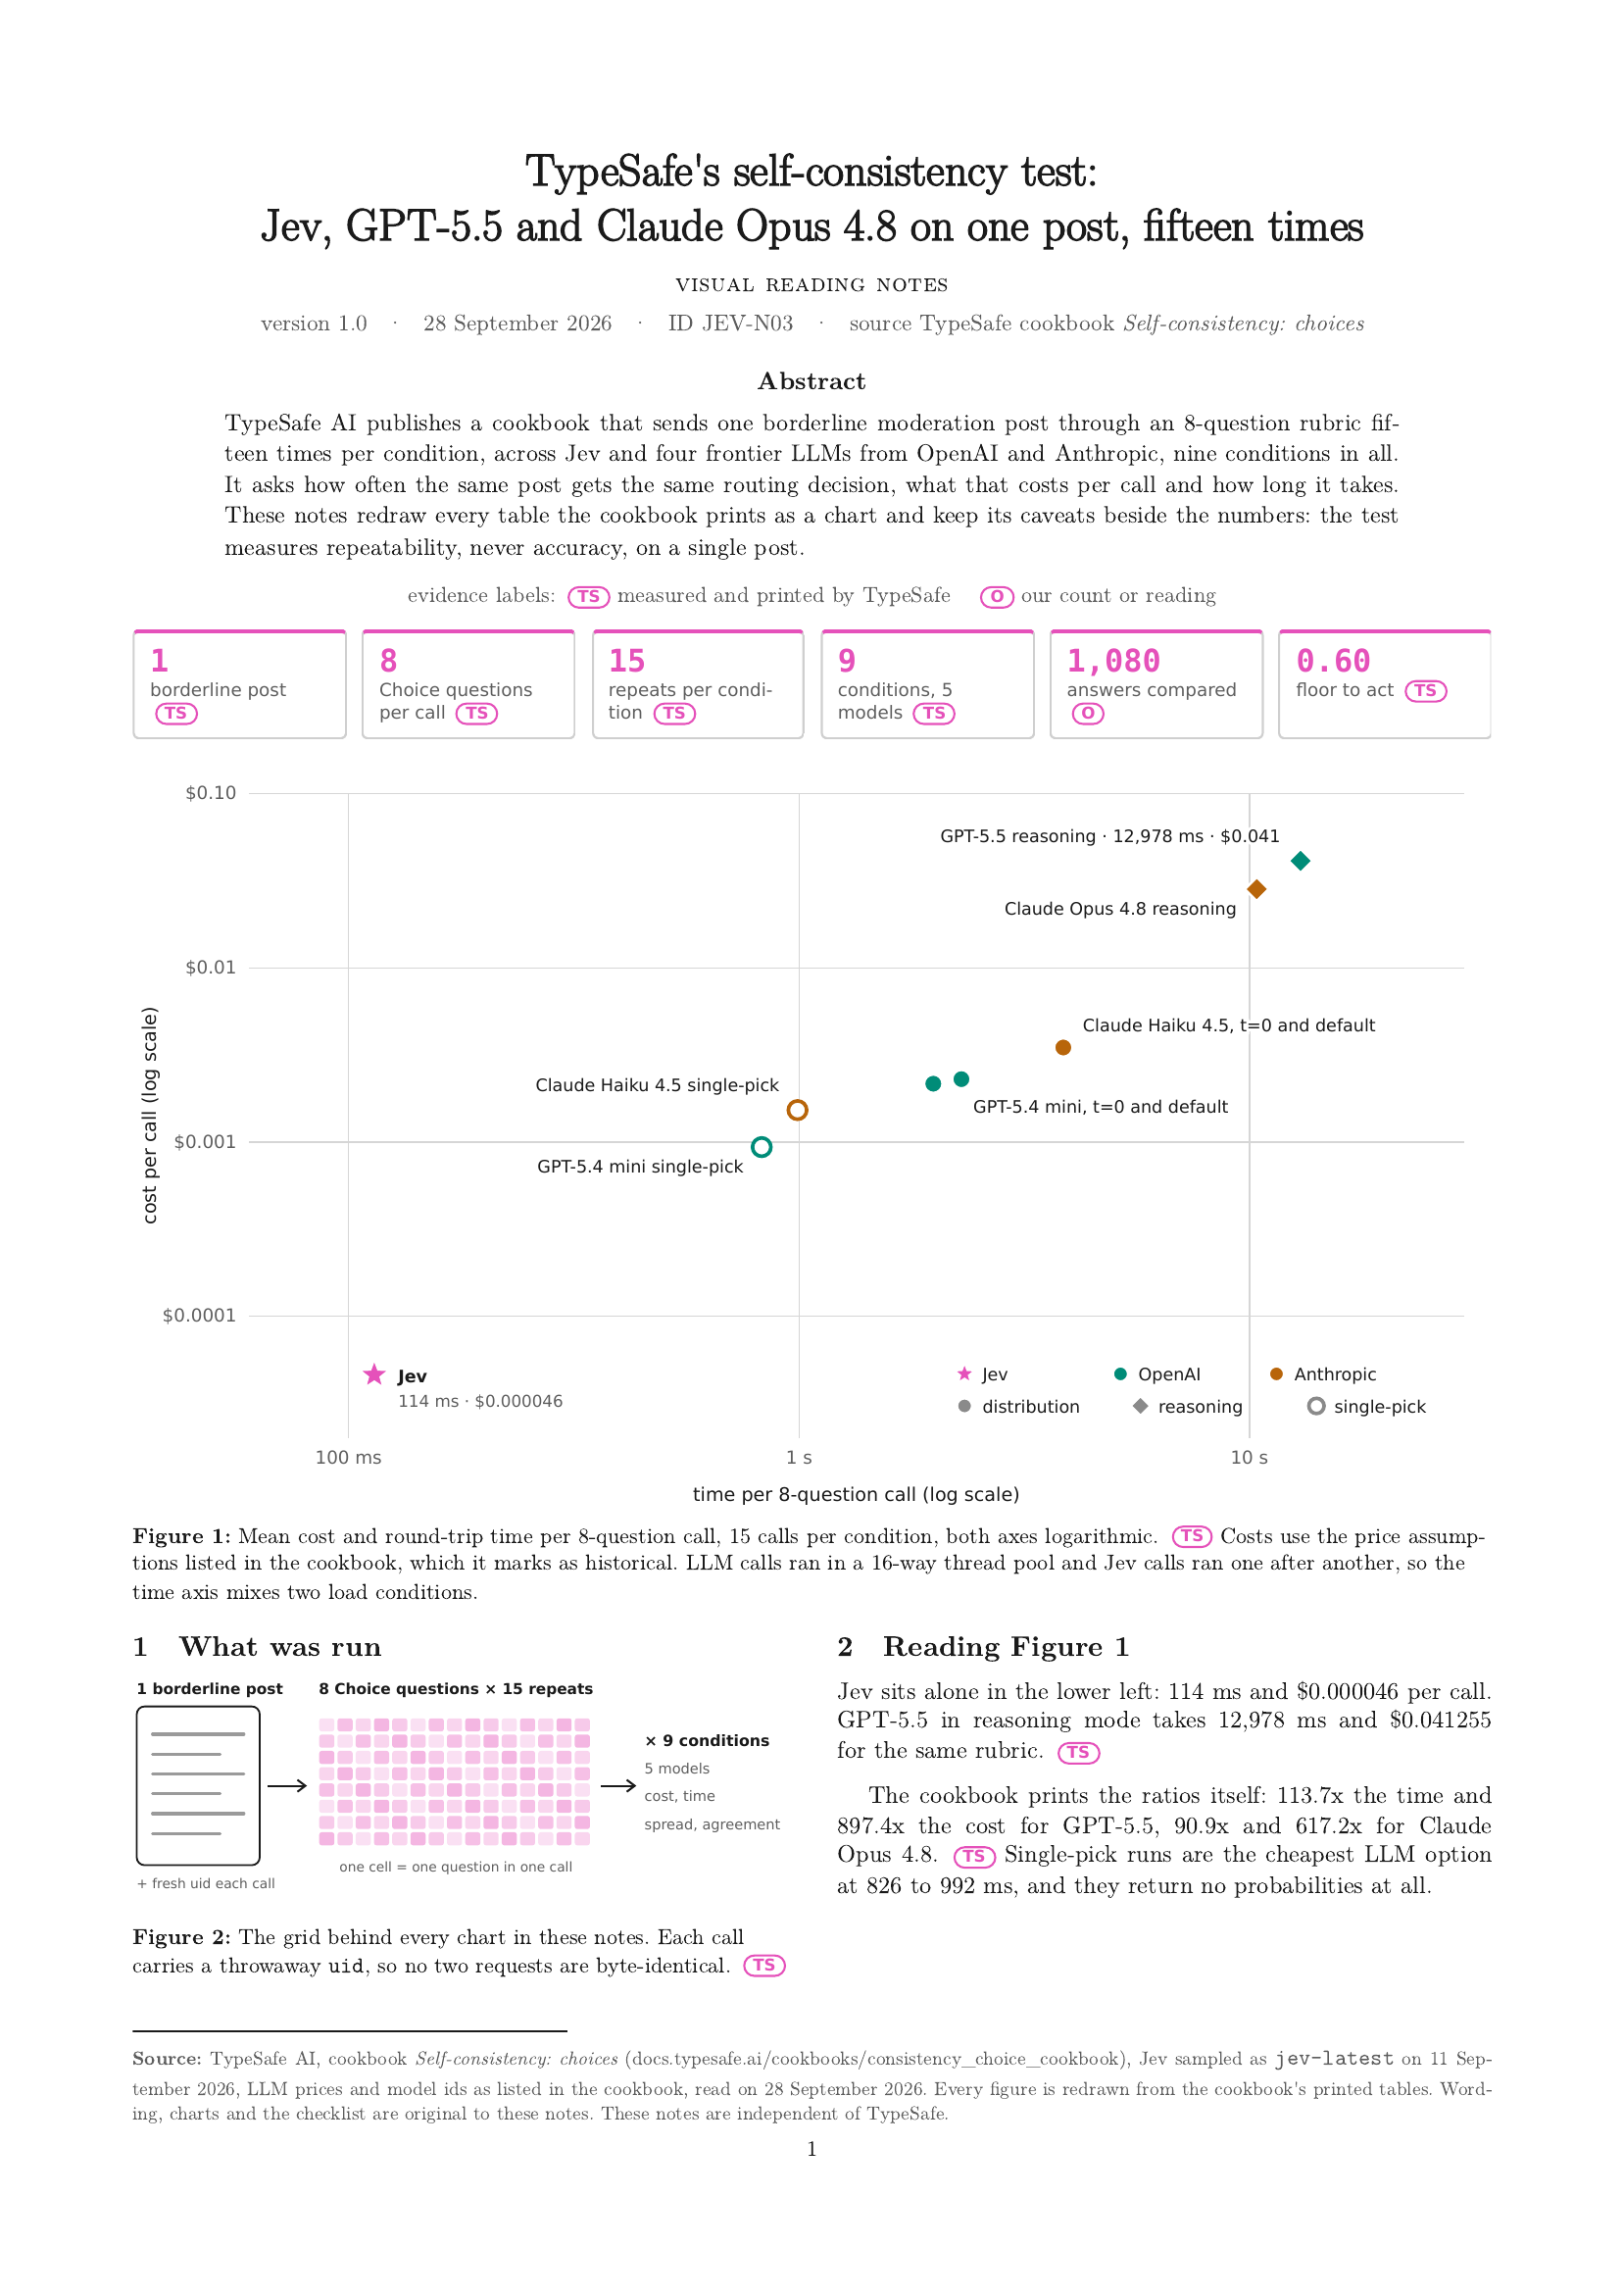
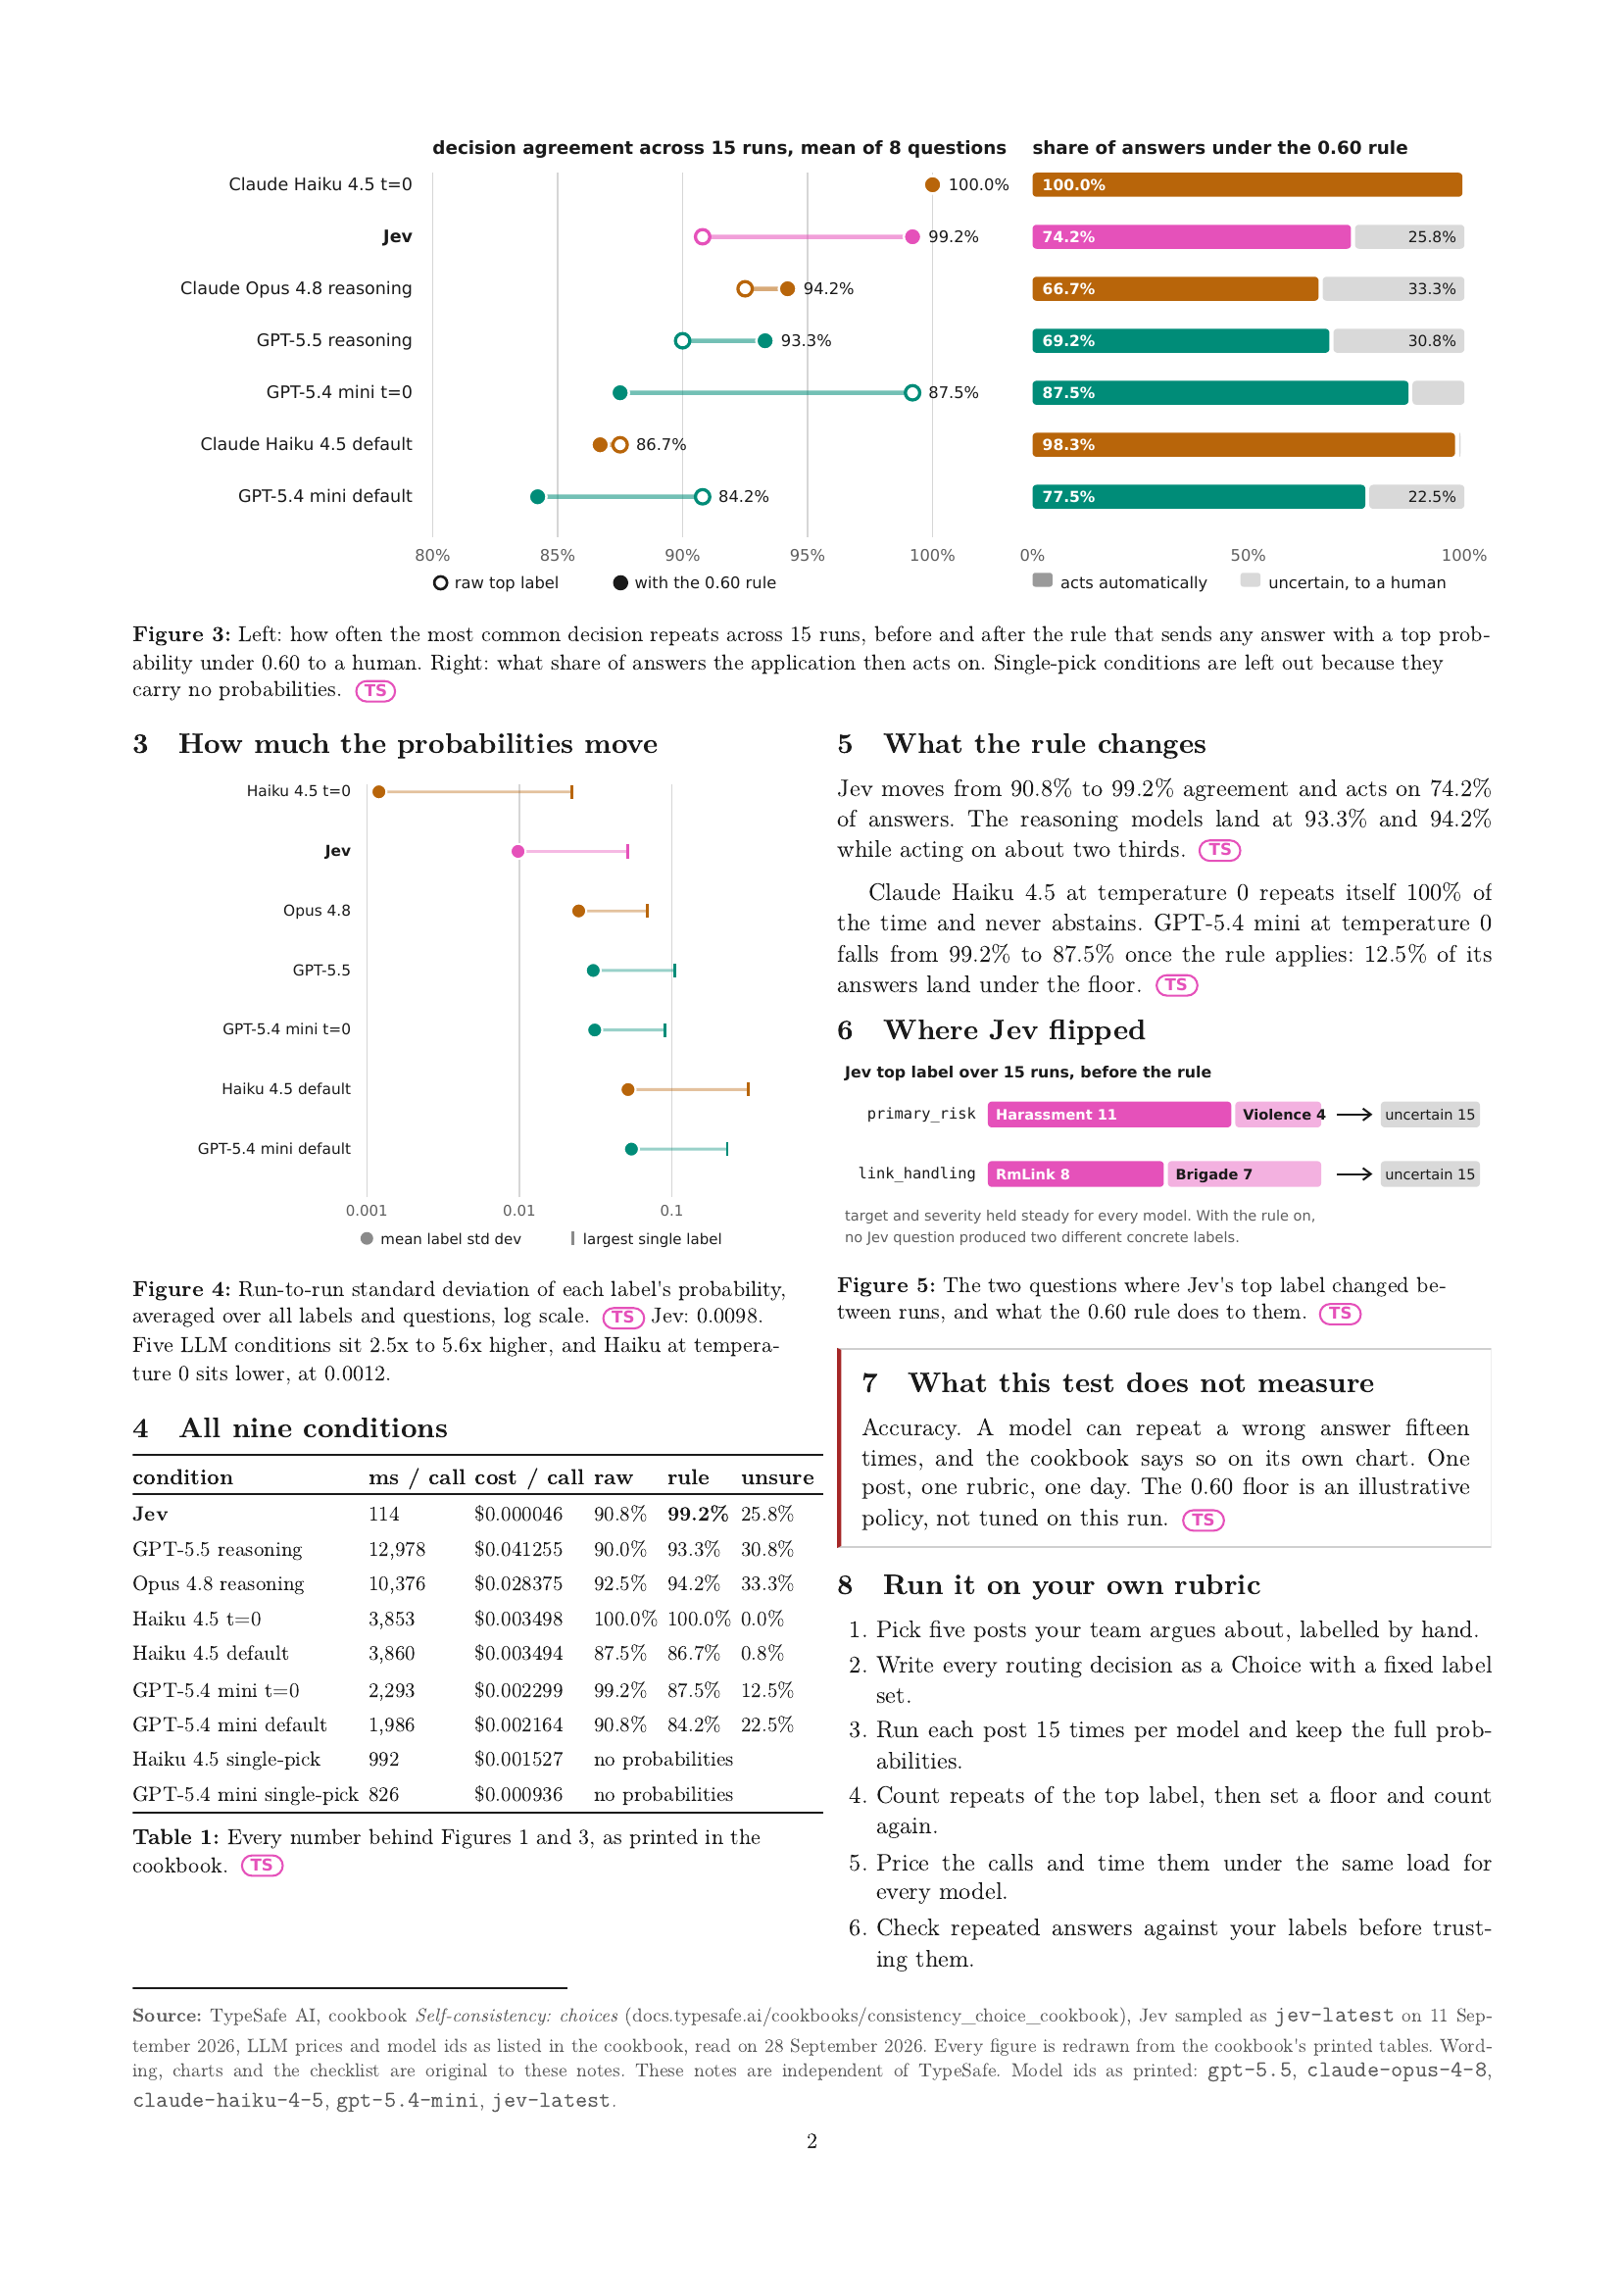
it's f*cking the best i found this weekend TypeSafe just made GPT-5.5, Claude Opus 4.8 and Jev moderate one post 15 times a borderline post can land in a different queue on the very next run. the test counts how often each answer holds: 1 post -> 8 questions -> 15 runs -> under 0.60 goes to a human all nine setups, drawn on two pages: > see which models flip the same post between queues > watch what a 0.60 floor does to every model's agreement > compare price and speed per call on one log chart $0.000046 vs $0.041 per 8-question call, Jev against GPT-5.5, at the cookbook's listed prices. the rare test that prints its own caveats on the chart
这条是引用着另一条写的:「TypeSafe 官方 skill 教 Claude Code 用 Jev」