实测 Jev 在记忆管线各环节的取舍
Dhravya Shah 测了 Jev 在重排、分块、抽取前过滤、何时召回上的表现:能砍掉 58% 抽取 token,但丢掉一句上下文就会把记忆判错。
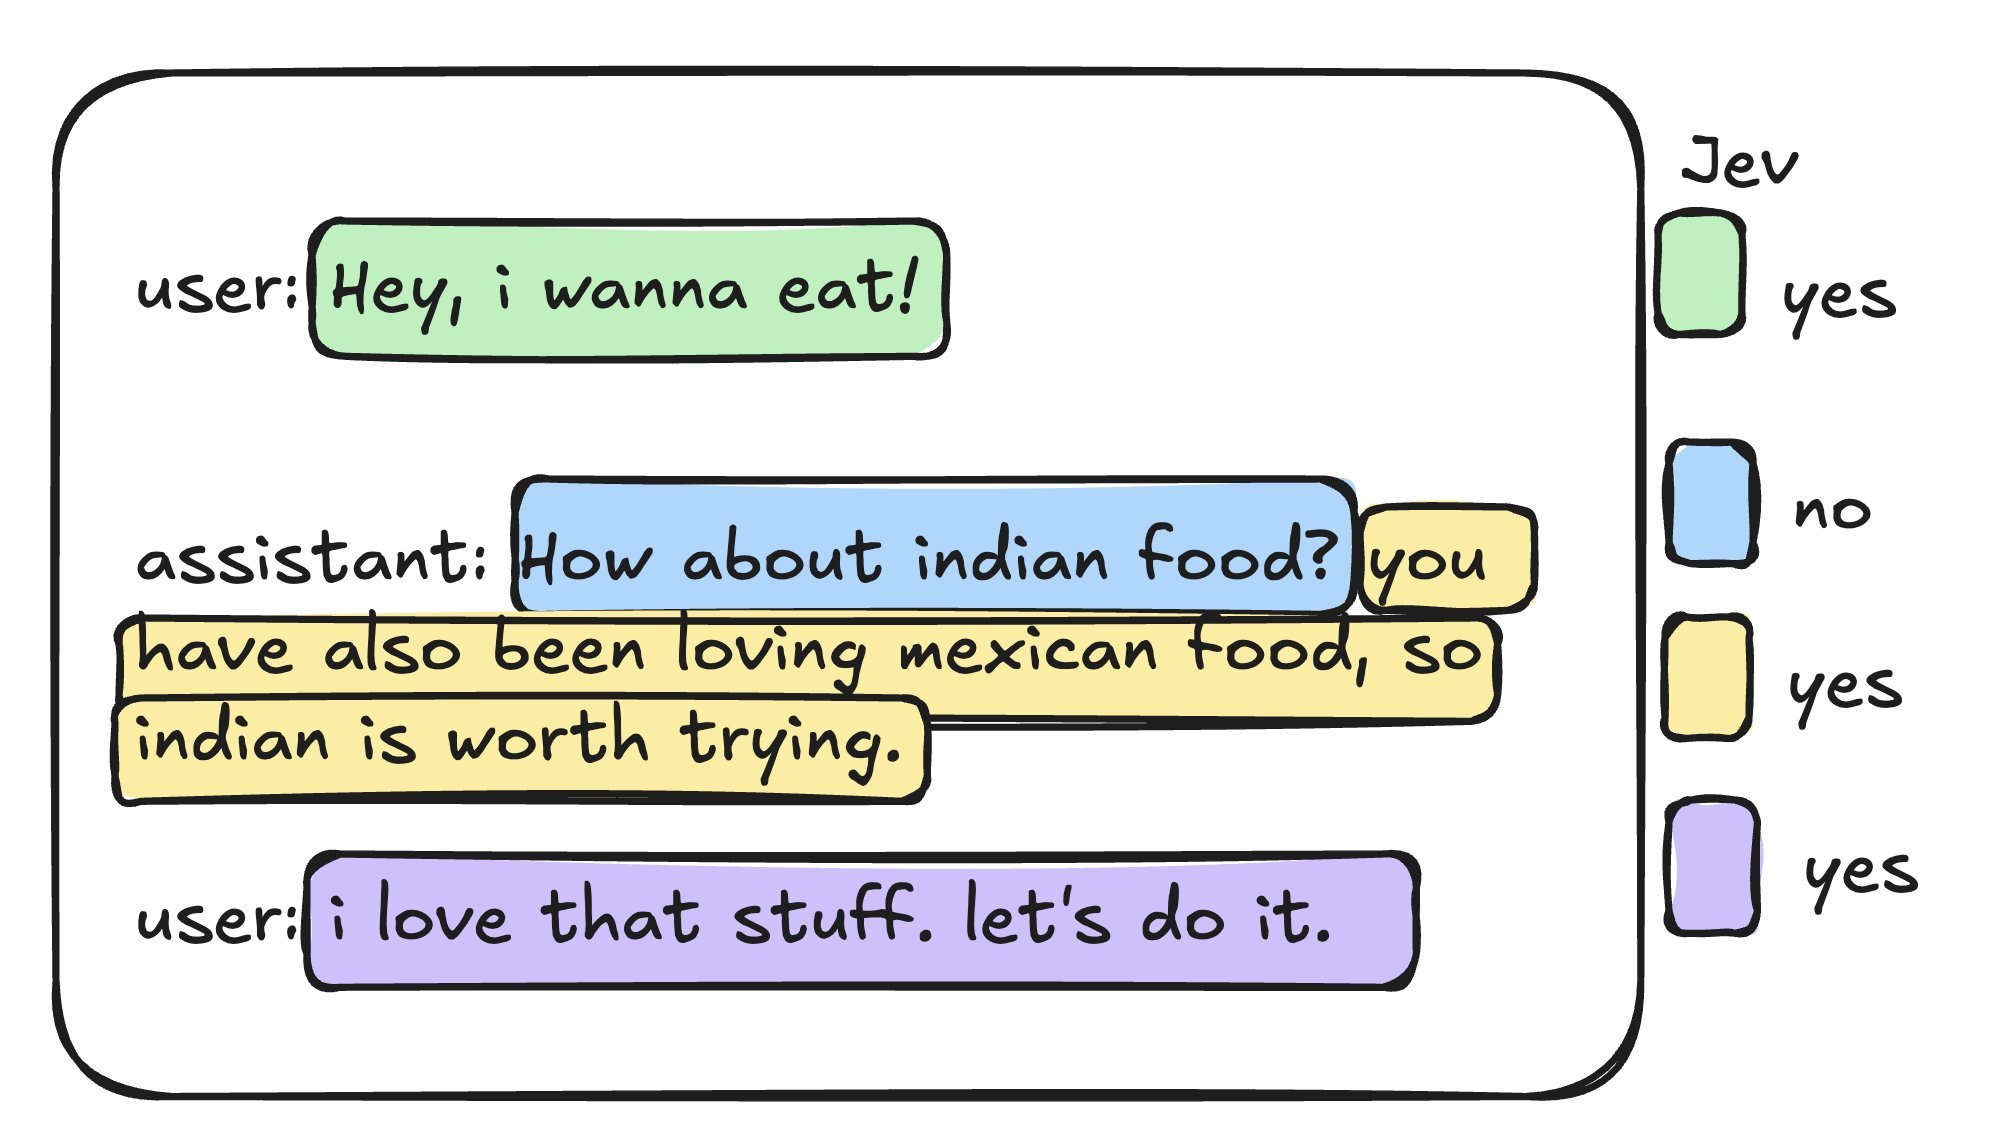
banger research just dropped!! @DhravyaShah tested jev, @typesafeai's new decision model, across the whole memory pipeline: reranking, chunking, filtering context before extraction, and deciding when an agent should recall at all. did you know jev can cut 58% of the tokens going into memory extraction, but dropping one line like "how about indian food?" can turn "i love that stuff" into a memory about mexican food? decision models are insanely fast at yes/no calls and still need the full context to judge meaning. that's why @supermemory leans on learner-1, a small specialized model that makes observation cheap enough to skip the risky cut entirely :)
这条是引用着另一条写的:x.com/dhravyashah/status/2103314339239428201