AutomationBench 上 Opus 5.5 与 GPT-6 Astra 的差距
Opus 5.5 把自动化基准从 26.9% 提到 40%,GPT-6 Astra 41.4%,多应用任务仍会先动手后观察。
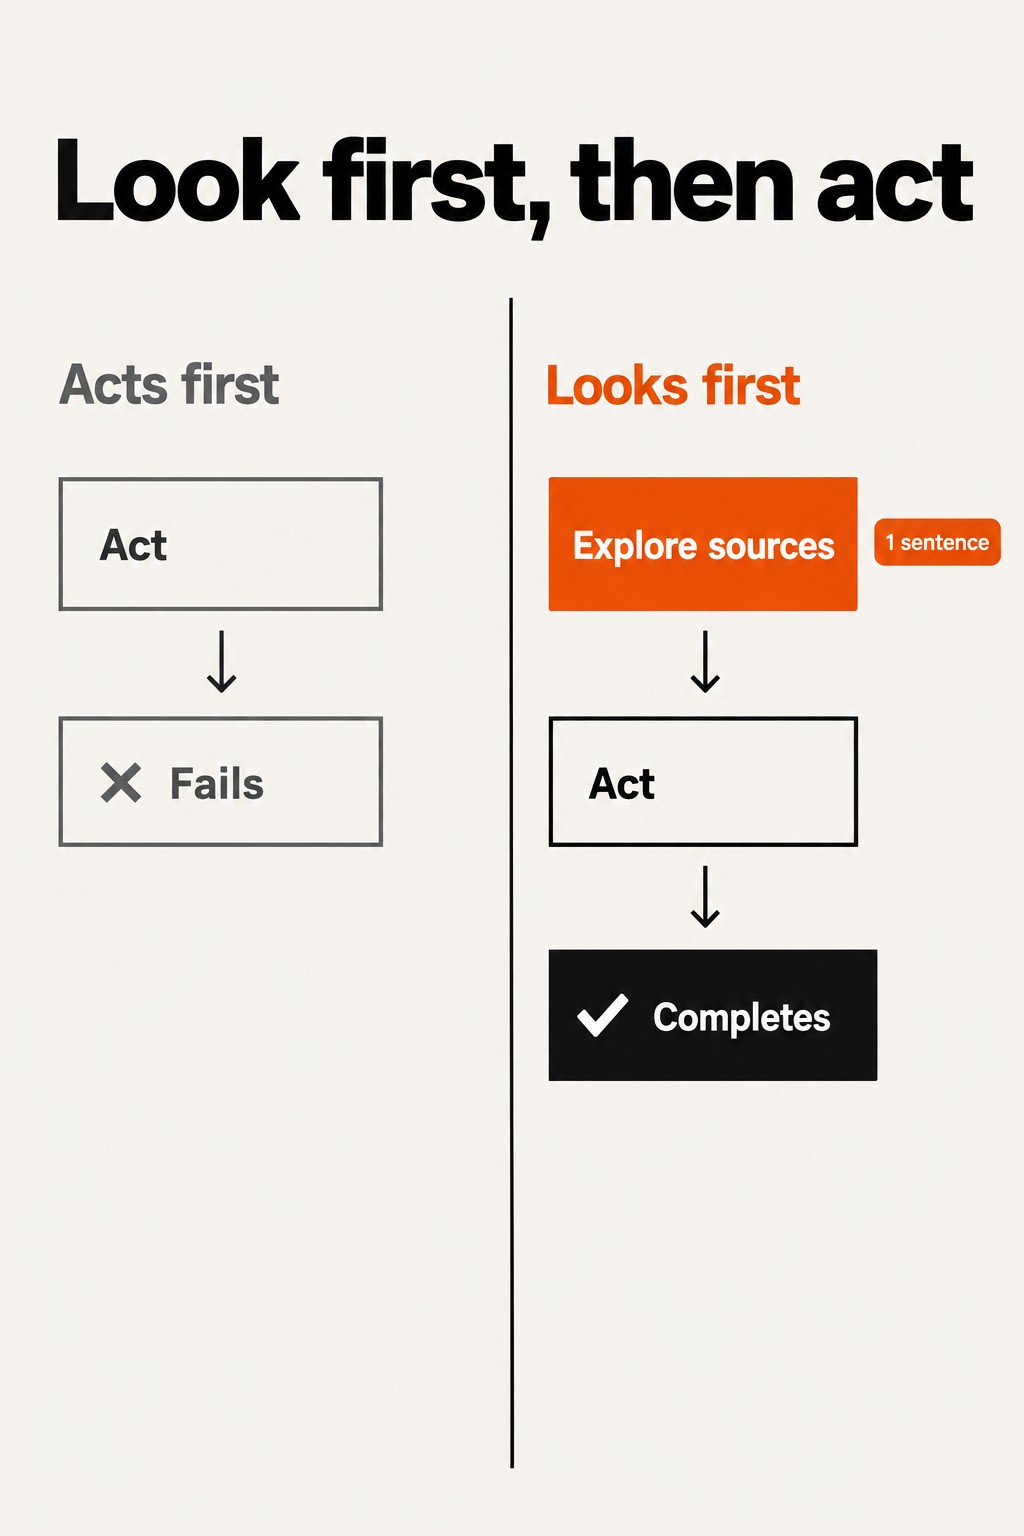
AutomationBench rose from 26.9% on Opus 5 to 40.0% on Opus 5.5! GPT-6 Astra scores 41.4%, so this is not a clean win. multi-app work still fails the same way. across email, documents, spreadsheets and a CRM, the model acts before it looks around. Anthropic's guide has a fix that needs no new model: one sentence in the prompt telling it to explore the relevant sources before it acts. Anthropic says that made it complete noticeably more multi-app tasks correctly. and the sentence cuts both ways. a model told to act on what it finds will act on an injected instruction too, so it only goes at sources you trust. Which of your sources would you not point it at?
这条是引用着另一条写的:x.com/neil_xbt/status/2105292880797483484