4 台 DGX Spark 跑 M3.1 Flash:单流 59 tok/s,100 万上下文
作者用 4 台 DGX Spark(GB10)加 SGLang TP=4 端到端跑通 M3.1 Flash,实测单流解码 59 tok/s、6 路并发合计 122.9 tok/s,266k 请求的 needle 测试命中,并列出显存、KV 池与踩坑细节。
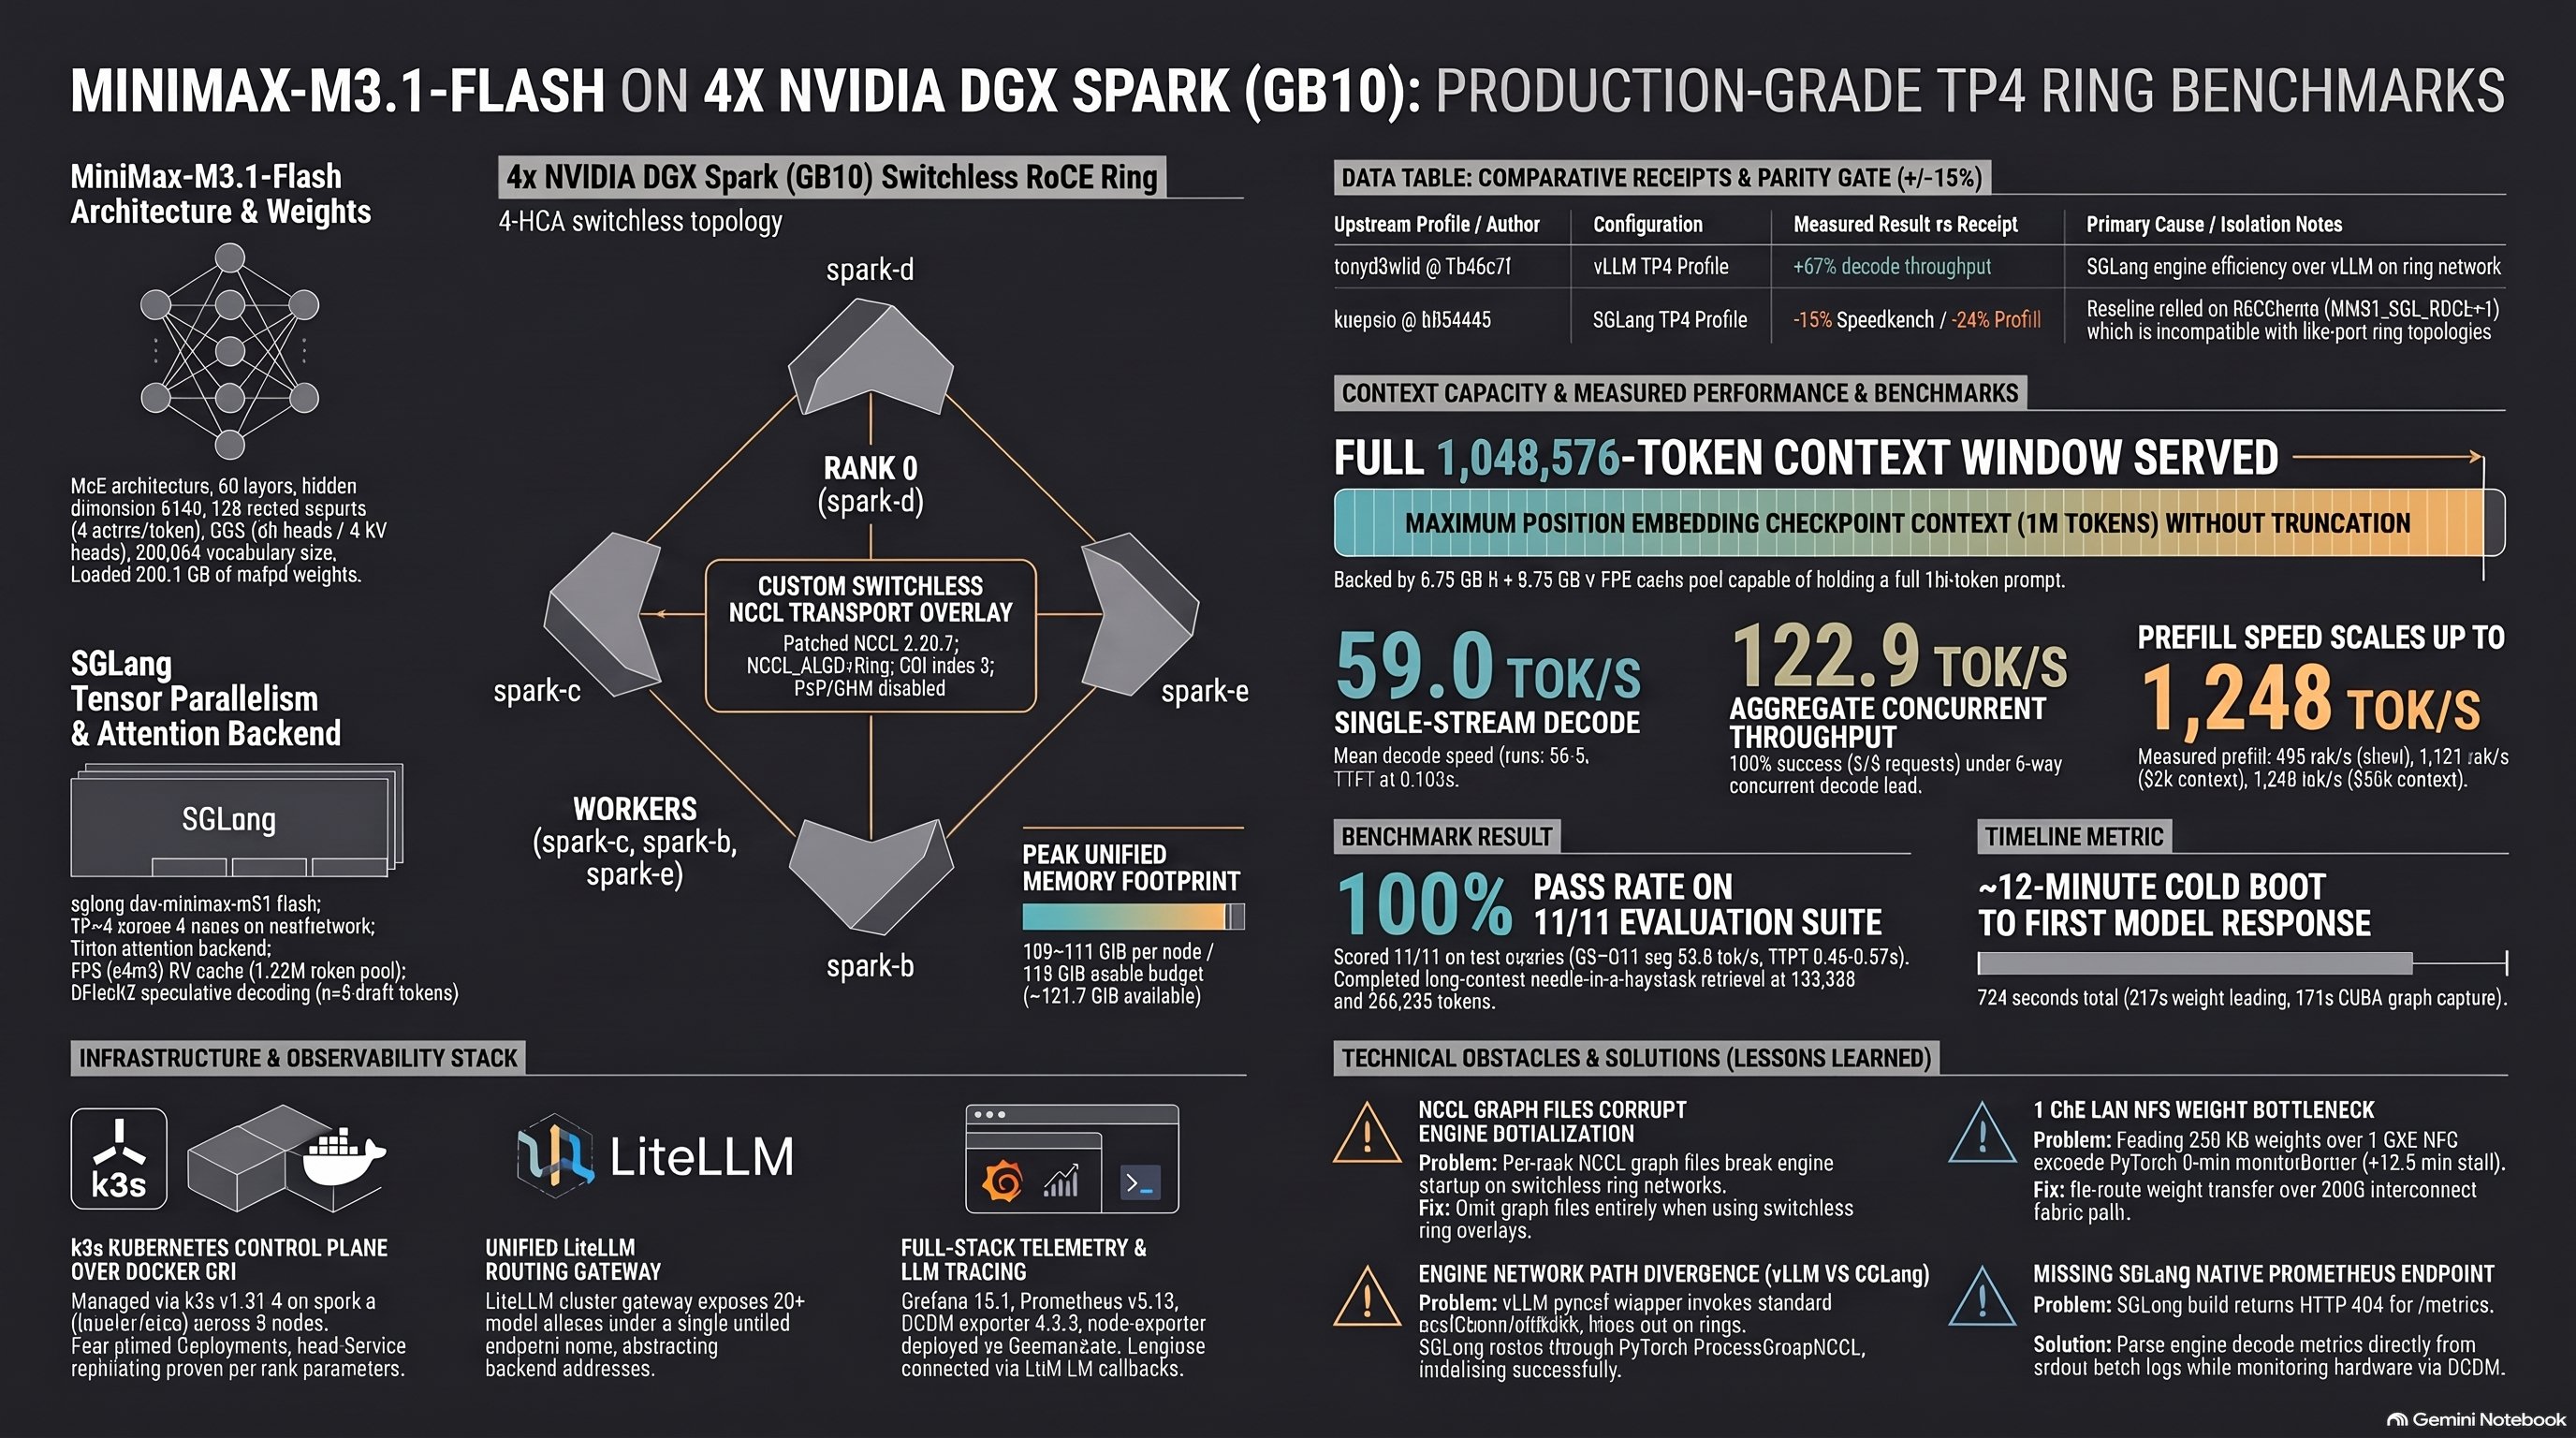
1/ I ran MiniMax-M3.1-Flash on 4x NVIDIA DGX Spark (GB10) and it works end-to-end. Engine: SGLang, TP=4 / nnodes=4, hostNetwork. Transport: patched NCCL 2.30.7, ALGO=Ring, switchless overlay over 4 RoCE HCAs/node. Context: 1,048,576 (checkpoint max, not a truncated serve). KV: fp8_e4m3, 1,220,096-token pool. Spec decode: DFLASH, draft @radixark, k=5. Weights: 250.1 GB, mxfp8. ~118 GiB VRAM/node, 110 GiB peak UMA. 2/ Measured, not claimed: - Single-stream decode: 59.0 tok/s (TTFT 0.183 s) - 6-way concurrent aggregate: 122.9 tok/s - Prefill: 1,121 tok/s @32k; 1,248 tok/s @266k - Eval: 11/11 (Q1-Q11 scored, Q12a-d recorded) - 266,235-token request: 200 + needle found - Boot to first 200: ~12 min - Author parity: +67% vs one upstream recipe, -19%/-24% vs another (isolated to their RoCEnante path being unusable on a ring) Graded against the upstream authors' own published receipts, +/-15% gate. 3/ Infra: - k3s v1.31.4 control plane on spark-a (etcd + master), 5 nodes, Docker CRI - This was the FIRST TP4-ring serve we put under Kubernetes - LiteLLM gateway on the cluster, 20+ model aliases, one name for agent tooling - Grafana 13.1 + Prometheus v3.13 + DCGM exporter + node-exporter + Alertmanager - Langfuse for LLM trace-level observability Build the plane first, then the model. 4/ Credits: - @majewskizby / knapcio — SGLang profile, the one we shipped - @Tech2Wild / tonyd2wild — vLLM profile - @MiaAI_lab / MiaAI-Lab — switchless NCCL ring overlay we reused - @radixark — DFlash2 draft model - @rhysjones — SGLang RoCEnante overlay pattern - @sgl_project, @vllm_project — the engines - @MiniMax_AI — MiniMax-M3.1-Flash Their recipes and published receipts; our ring launcher, k8s manifest and measurements. 5/ What cost me time: - Per-rank NCCL graph files pass a small all-reduce test and still break the engine. Switchless ring mode, no graph file. - vLLM's pynccl path can't init on a like-port ring. SGLang's torch ProcessGroupNCCL path can. - Feeding 250 GB of weights over 1 GbE LAN NFS can't clear torch's 8-min monitoredBarrier. Feed over the 200G fabric path. - The SGLang build ships no /metrics endpoint. Engine throughput came from server logs; cluster+GPU metrics from Prometheus/DCGM. MiniMax-M3.1-Flash on 4x DGX Spark: SGLang TP4, RoCE ring, 1M ctx, DFlash2 spec decode. 59 tok/s single / 123 aggregate, eval 11/11. k3s control plane + Grafana/DCGM. (This thread was written by MiniMax-M3.1-Flash running on those same 4 Sparks.)