Jev 工作原理的可视化图解
用图解讲清 Jev 如何用单次 Transformer 解码加 KV 缓存直接输出合法 JSON,取代逐 token 自回归生成。
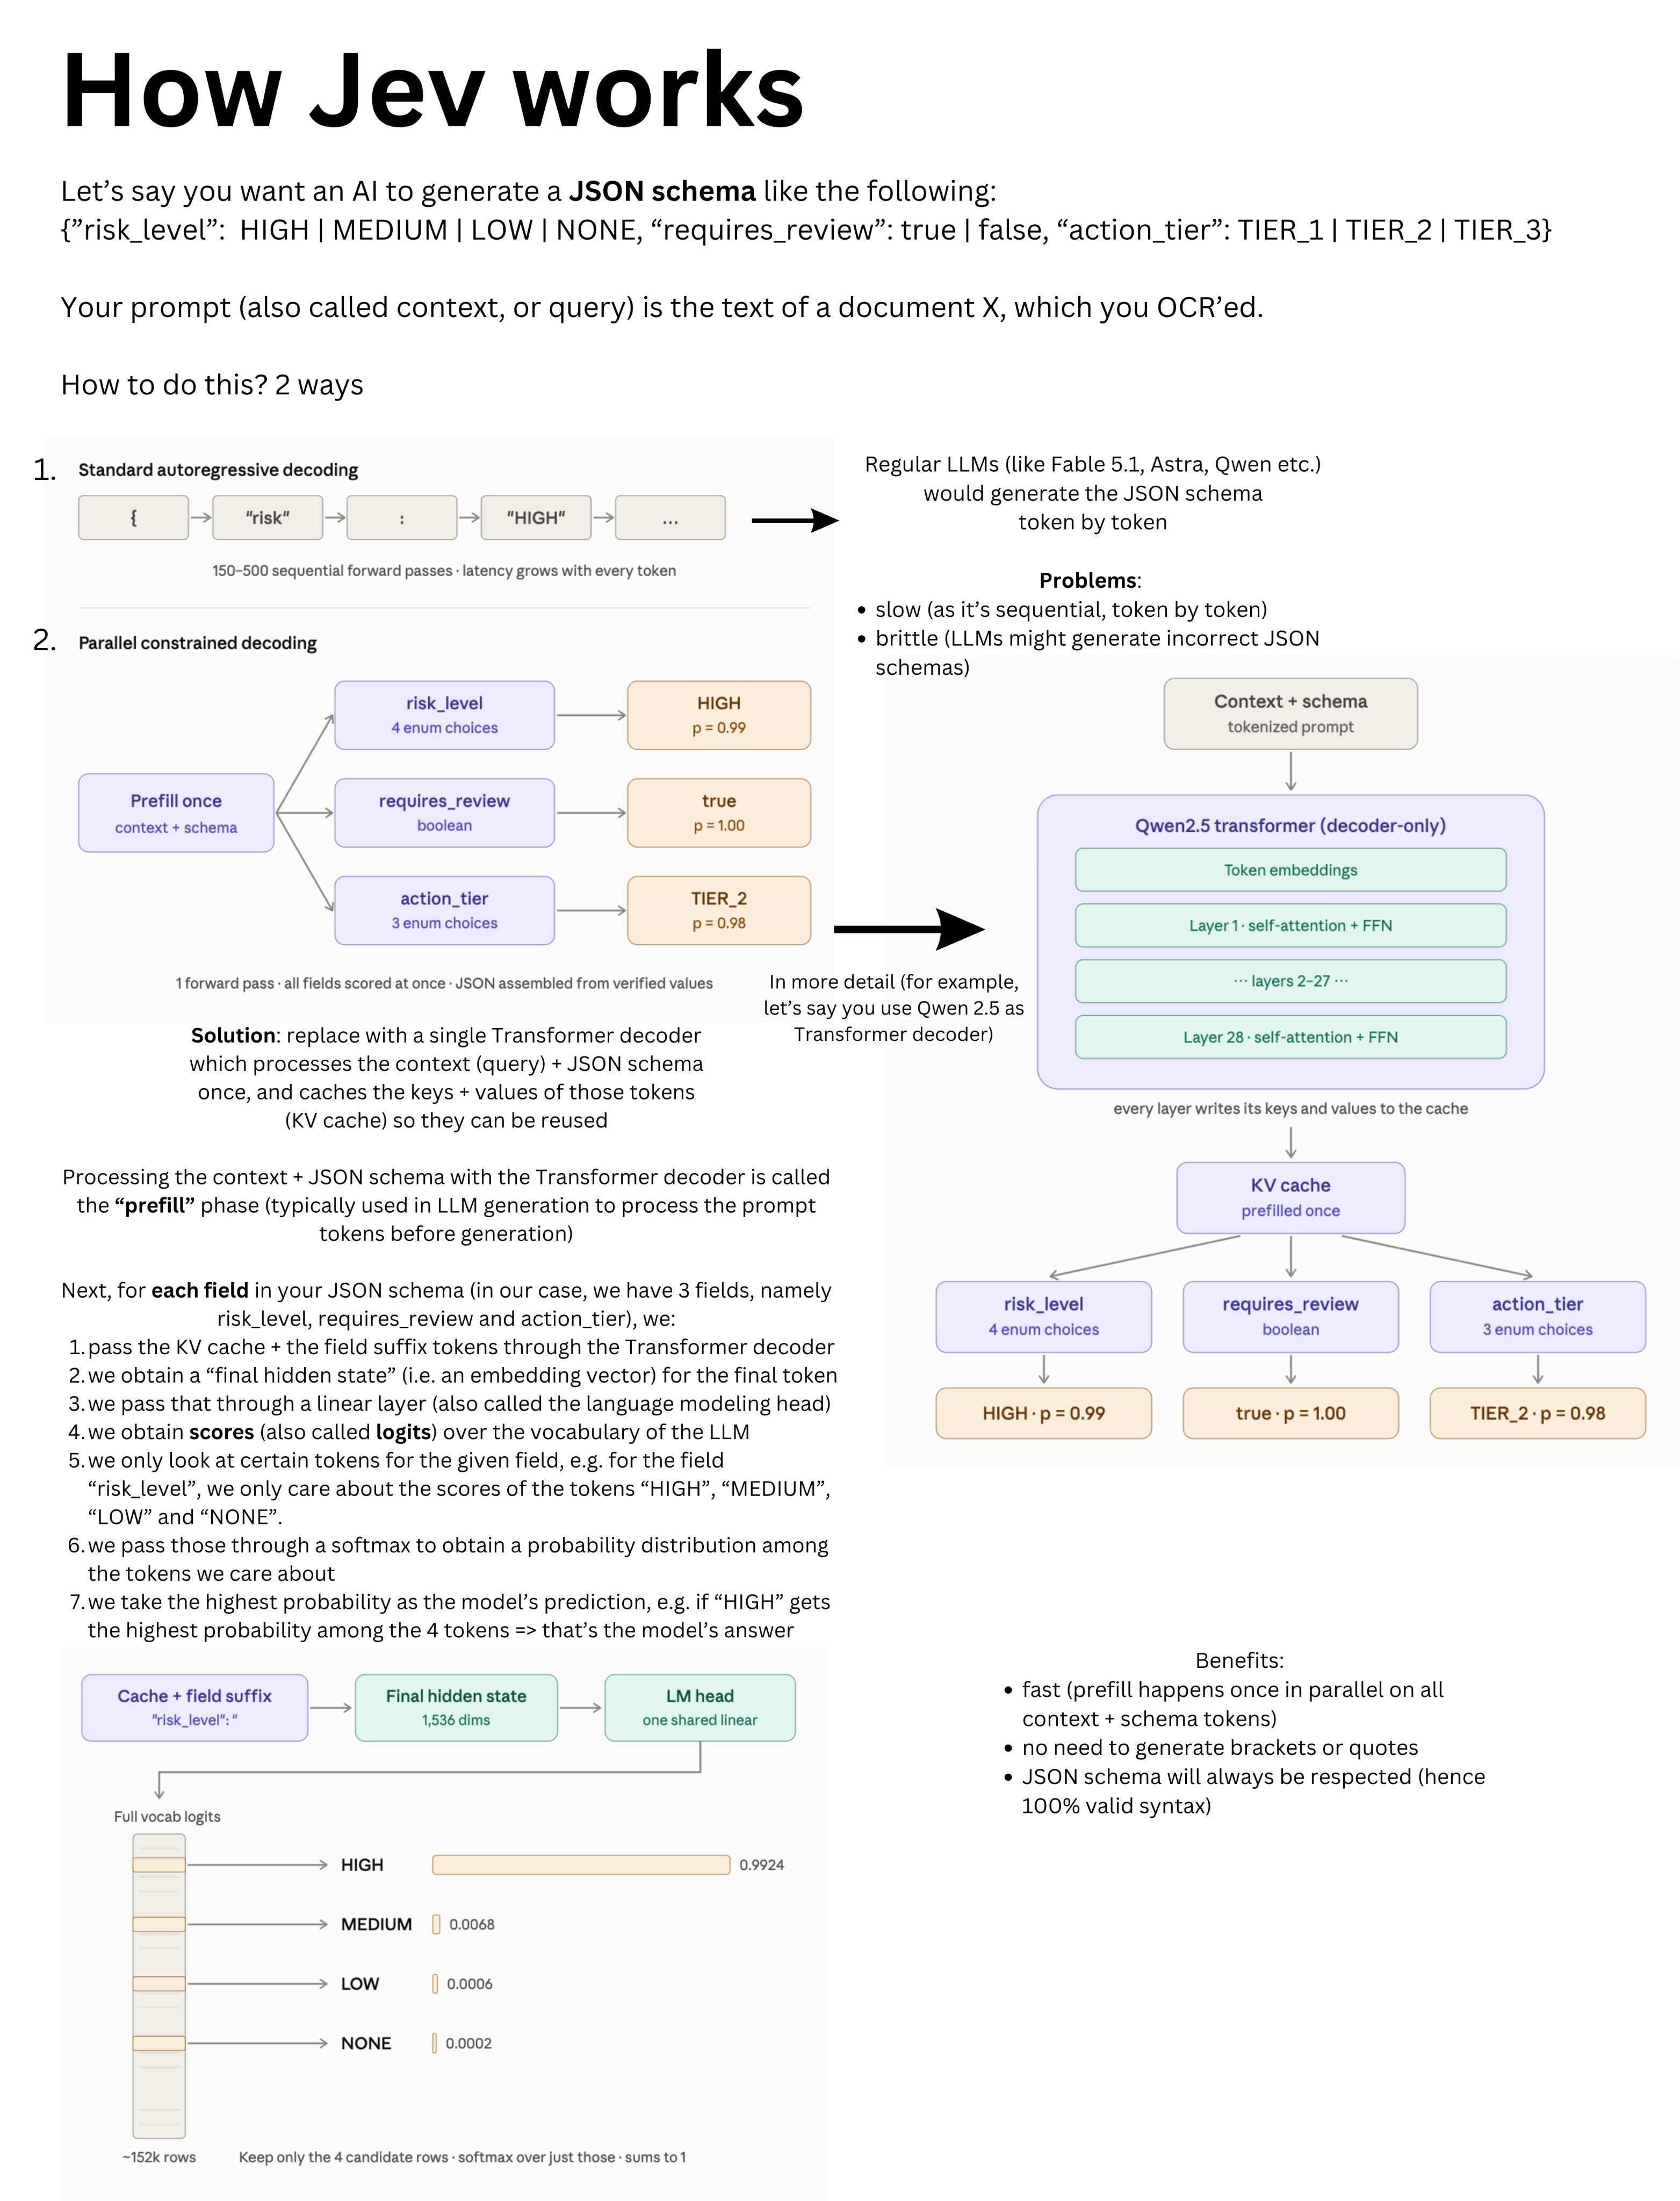
For anyone curious how Jev works, I made a visual explanation using @claudeai :) This is based on the Qwen2.5-RLCD model which @harshagundal released on @huggingface The idea is to replace autoregressive LLM generation by a single Transformer decoder (of a pre-trained LLM), which processes the context + JSON schema only once. The keys and values of those tokens are cached. Next, for each field of the JSON schema, we: 1. pass its field suffix tokens through the Transformer decoder again (reusing the KV-cache) 2. obtain a final hidden state, which we pass through the language modeling head 3. we obtain scores, also called logits, for all tokens in the vocab of the LLM 4. we only look at the scores of the tokens we care about for the given field, and pass those through a softmax to obtain probabilities which sum to 1 5. we take the token with the highest probability. The benefits of this are that: 1. it's fast (we don't need to generate the JSON schema token by token) 2. it's 100% valid JSON (we don't need to rely on the model to generate a valid schema)
这条是引用着另一条写的:x.com/nielsrogge/status/2100114968460820986