Harness-Zero 提出把 Agent 脚手架蒸馏进模型
Google 等机构的新方法只在训练时使用优化后的 harness,让模型在部署时无需专用脚手架,宏任务成功率从 23.3% 提升到 44.3%。

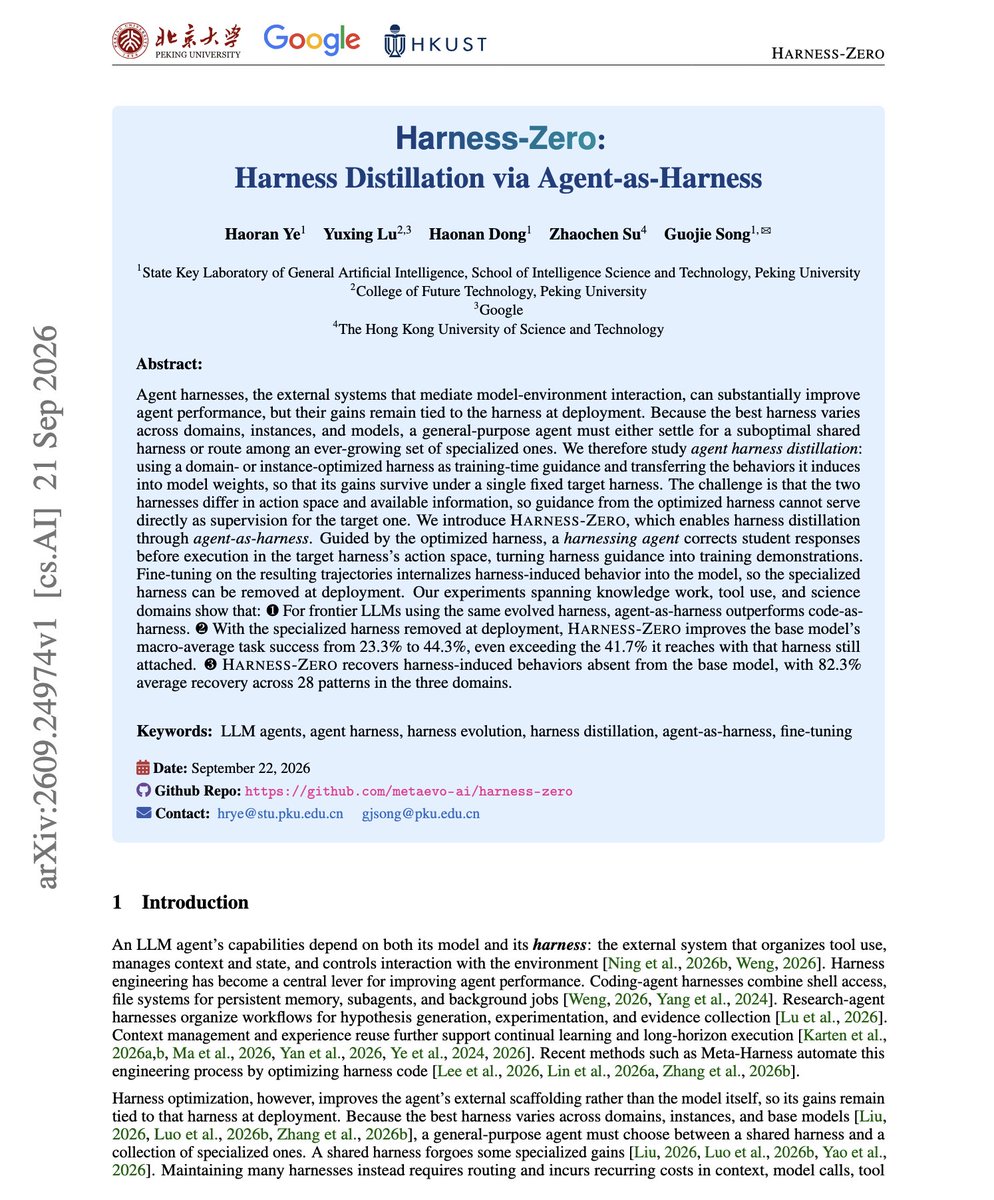
Super interesting paper from Google and colleagues. It studies where it's possible to distill an agent harness. With the specialized harness removed, macro task success goes from 23.3% to 44.3%. That is higher than the 41.7% the base model reaches with the harness attached. Harness-Zero uses the optimized harness only during training. The optimized harness and the deployment harness have different action spaces, so a harnessing agent guided by the optimized harness corrects the student's responses in the deployment action space before they run. Those corrected runs become the training demonstrations. Across 28 harness-induced behaviors in knowledge work, tool use and science, 82.3% are recovered on average. For frontier models using the same evolved harness, the agent-as-harness form also beats the code-as-harness form. It remains to be seen how robust the approach is, but it's very interesting to see potential in harness distillation. Paper: https://t.co/AiBm1p17Lp Chat with Paper: https://t.co/Nda4XsZgrh