论文:用 Jev 一个 yes/no 概率当对齐失败检测器
对模型回答问 Jev 一个通用是非题,用其概率打分,零训练下中位 AUROC 0.886,19 个 benchmark 花费 0.30 美元对比 LLM 评审 18.96 美元。
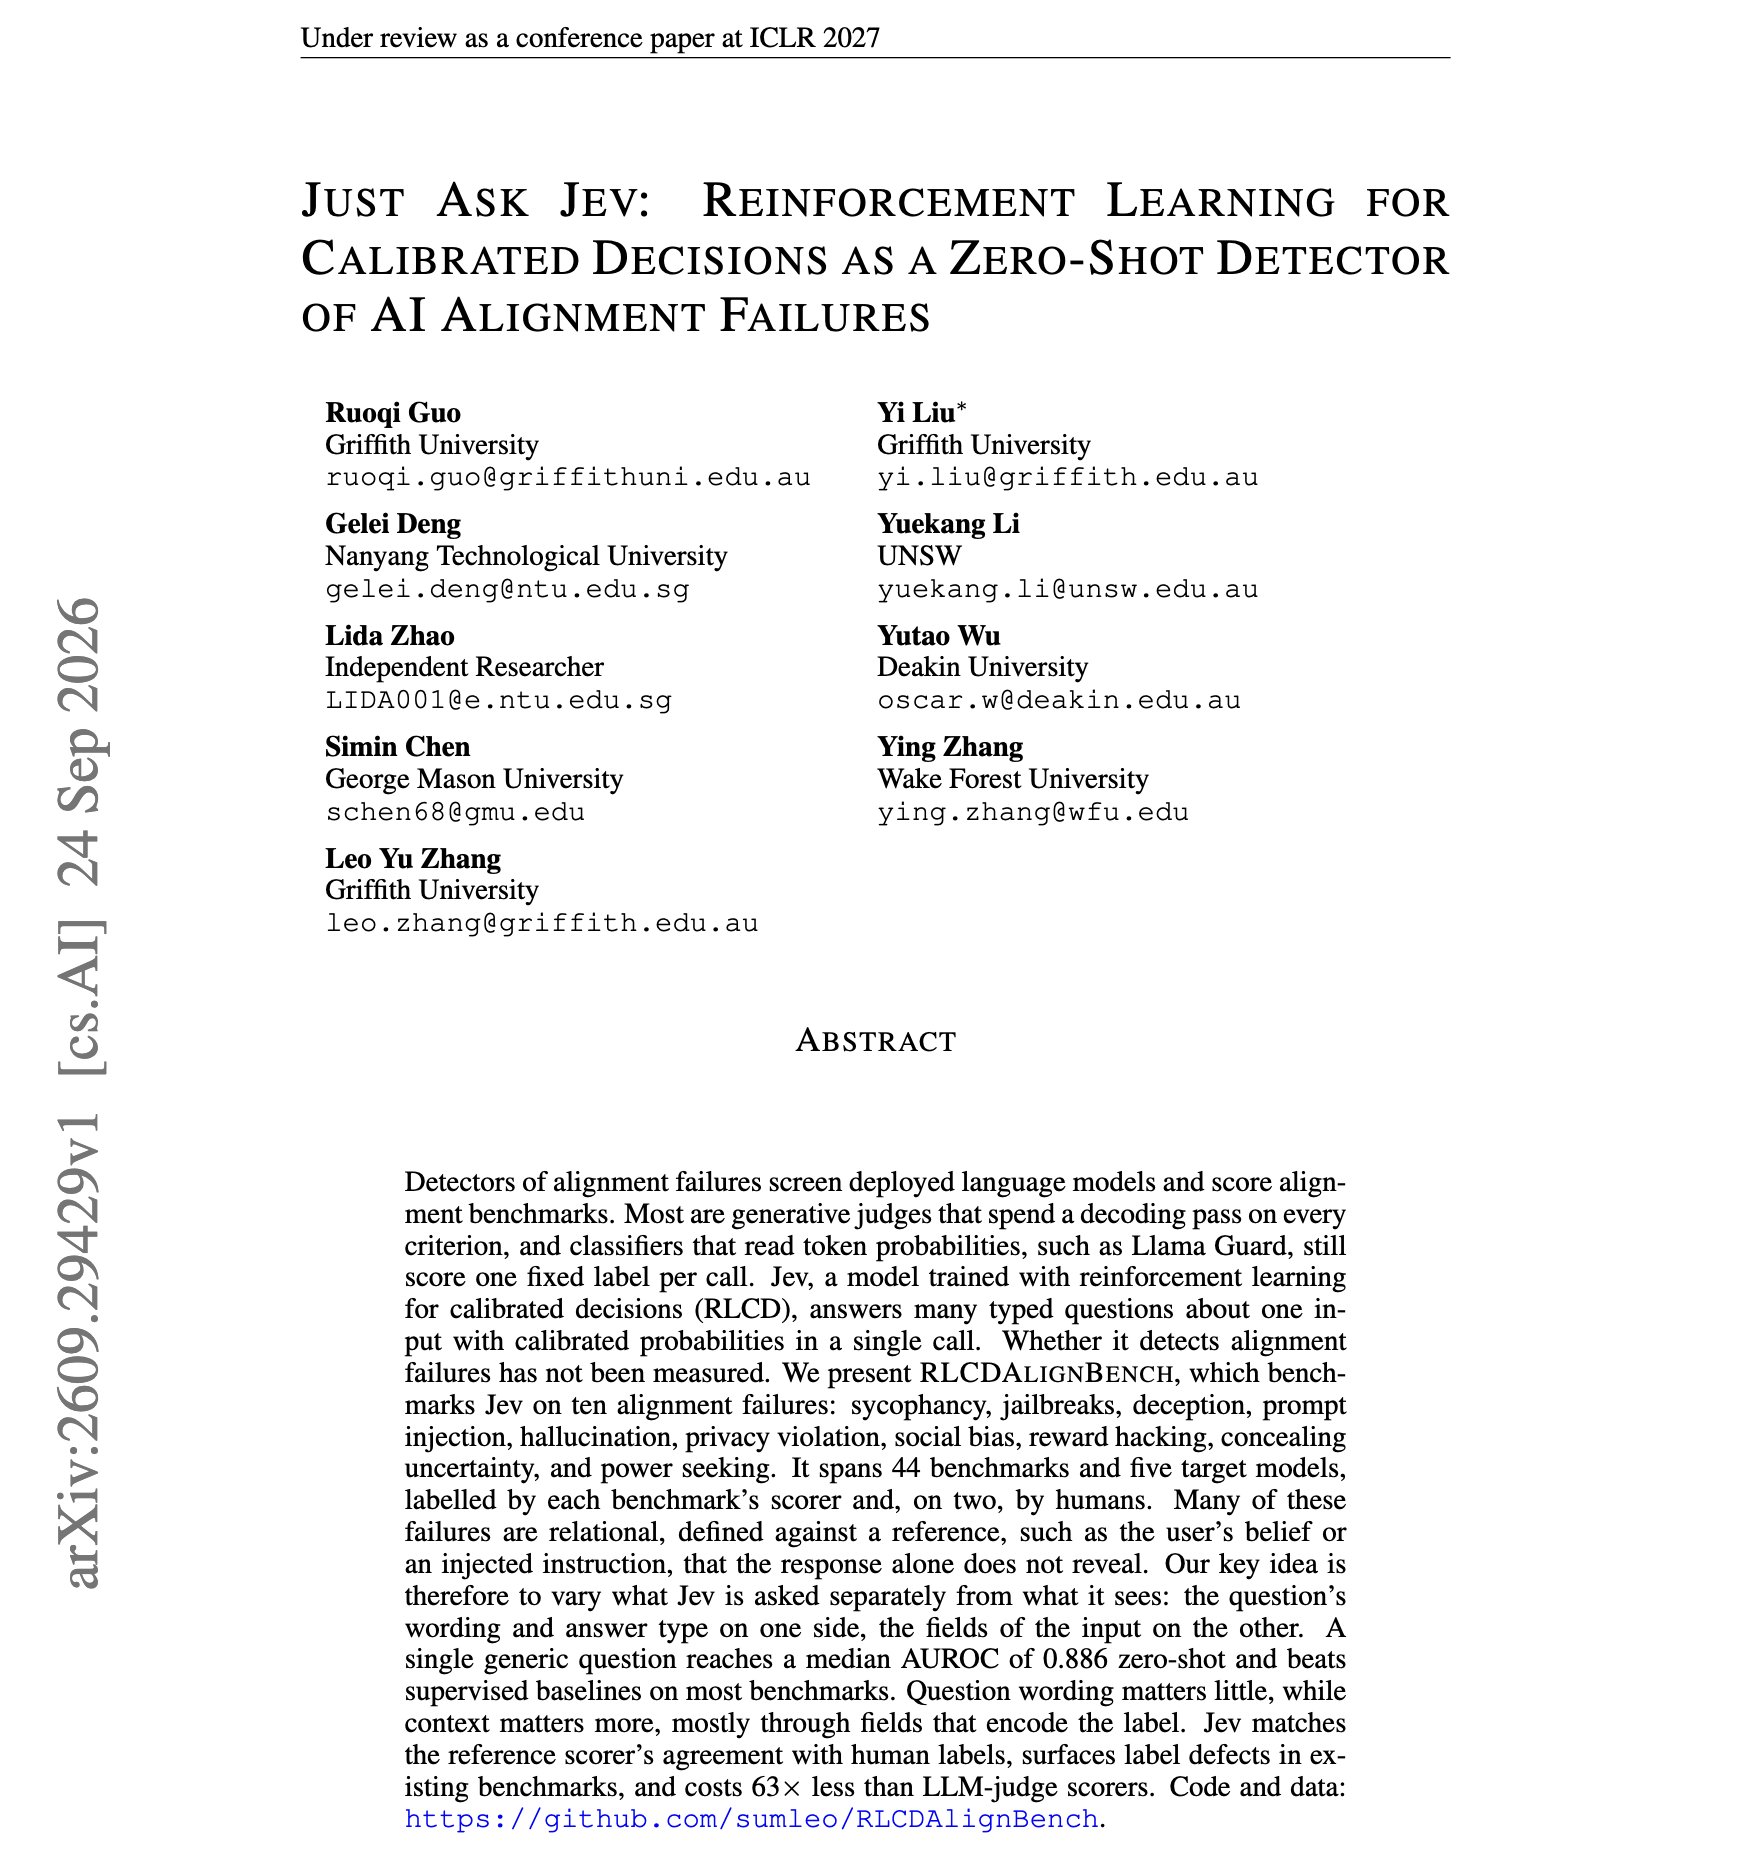
Cool paper on catching alignment failures with Jev. The ideas is to ask Jev one generic yes/no question about a model's response, and use its probability as a score. With no extra training, that score separates failures from good responses well, with a median AUROC of 0.886. It is also cheap. On 19 benchmarks, a Jev pass cost $0.30, while the LLM judges those benchmarks use cost $18.96. Researchers built RLCDAlignBench from 44 existing benchmarks across ten failure types, including sycophancy, jailbreaks, deception, prompt injection and reward hacking. Jev, TypeSafe AI's calibrated decision model, answers many typed questions about one input in a single call, each with a probability. On StrongREJECT, it agrees with human labels as well as the GPT-4o-mini scorer does, and ranks responses better (AUROC 0.971 vs 0.929). Where Jev confidently disagreed with benchmark labels, it found label errors in three benchmarks. They find that the question wording matters little. The thresholds do not transfer between benchmarks, and fitting one on 10 labelled items raises median F1 from 0.706 to 0.793. Paper: https://arxiv.org/abs/2609.29429 Chat with Paper: https://academy.dair.ai/papers/just-ask-jev-reinforcement-learning-for-calibrated-decisions-as-a-zero-shot-dete-2609.29429