何时用 Jev、何时用前沿 LLM 的选型判断
作者主张按「有界决策还是开放式回答」分流:Jev 做分类、打分、路由,前沿模型处理需解释的边界情况,并用置信度阈值交接。
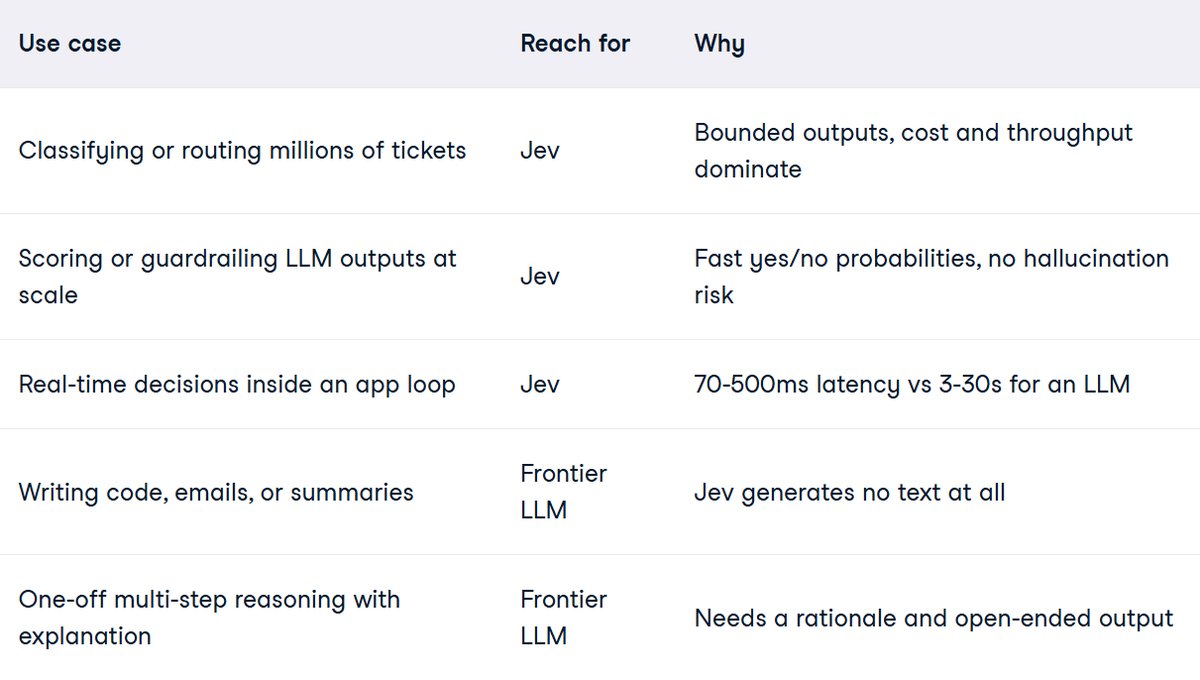
the real question isn't whether Jev beats GPT-5.6. it's whether you're asking the right model the right question. one design choice splits everything: does your task need a bounded decision or an open-ended answer? use Jev when: > classifying or routing millions of tickets - bounded outputs, cost and throughput dominate > scoring or guardrailing LLM outputs at scale - fast yes/no probabilities, zero hallucination risk > real-time decisions inside an app loop - 70-500ms vs 3-30s for any frontier LLM use a frontier LLM when: > writing code, emails, or summaries - Jev generates no text at all > one-off multi-step reasoning with explanation - needs rationale and open-ended output the part nobody mentions: the two models compose. Jev handles the high-volume decision layer. classification, scoring, routing. frontier LLM handles the hard edge cases that need an explanation. Jev's calibrated confidence is what makes the handoff clean. set a threshold. everything above it gets auto-acted. everything below it goes to GPT or Opus. you're not choosing between them. you're stacking them.
这条是引用着另一条写的:x.com/p0lybender/status/2101765571096506841