RTX3080 上三款小模型跑个人助理实测
在 RTX3080 上开推理对比 Qwen 3.5 4B、LFM3-1.7B、MiniCPM5 2B 做个人助理,给出 PA Core 总分与各自强项。
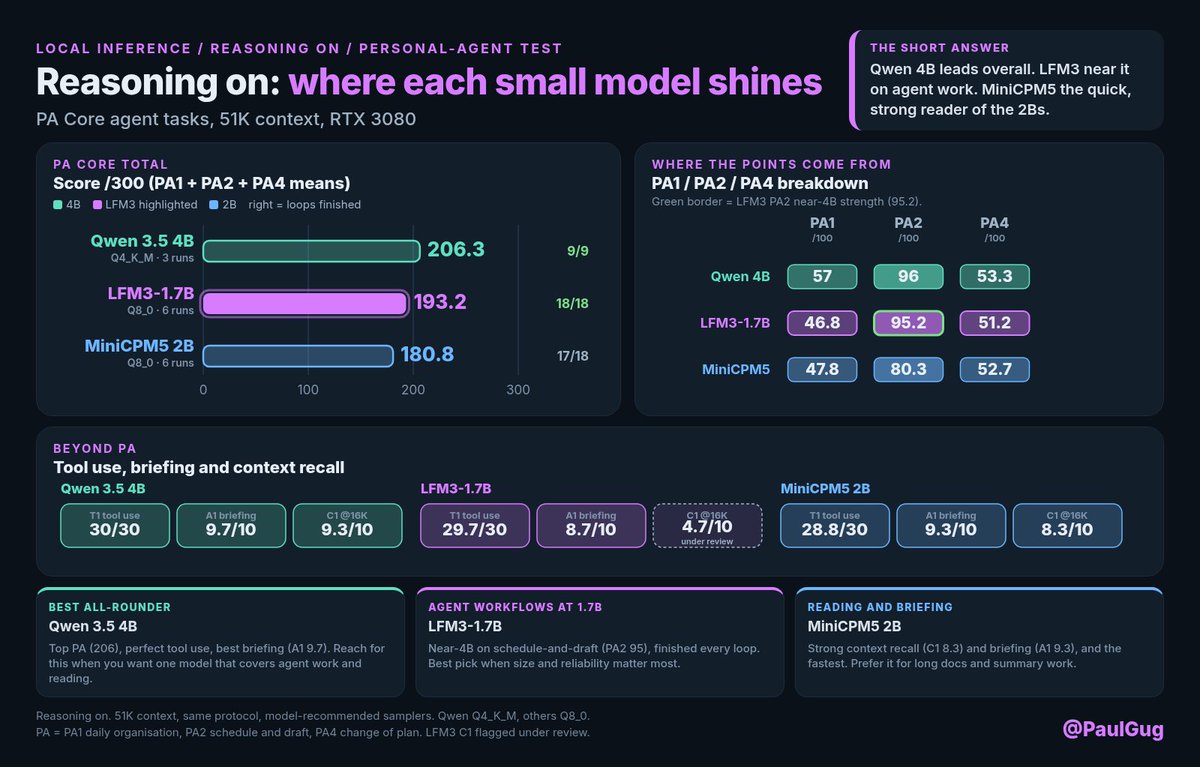
Round two on small models for personal agents on the RTX3080, this time with reasoning on. Same protocol for all three: 51K context, my PA Core agent tests, each model on its recommended sampler. PA Core total /300: - Qwen 3.5 4B: 206 - LFM3-1.7B: 193 - MiniCPM5 2B: 181 The numbers don't tell the whole story. Where each one is stronger: - Qwen 3.5 4B is the all-rounder. Best on multi-step agent tasks, perfect tool calling, best briefings. If you have the VRAM for a 4B, it's the pick for an assistant that plans and acts. - LFM3-1.7B is the agent-workflow surprise. It nearly matches the 4B on schedule-and-draft tasks (95 vs 96) and finished all 18 agent loops. Great for a lightweight agent that runs tools and drafts things on small hardware. It's the slowest-responding model when reasoning is on, however. - MiniCPM5 2B is the reader of the 2Bs. Strong at pulling the right details out of long personal context, solid briefings, and the fastest of the three with reasoning (12 sec response for A1 compared to LFM3's 33 sec). Great for summarising, recall and quick answers. With reasoning off, LFM3 and MiniCPM5 are dead level. With it on, LFM3 pulls ahead on agent work and MiniCPM5 keeps the edge on context and speed. Still not a Gemma 4 12B for my use case, but the gap keeps shrinking. Great work @LiquidAI_ & @OpenBMB! (Background of testing in quoted-post comments. Thanks @Franzferdinan57 and @FreelanceMike90 for asking about this)
这条是引用着另一条写的:x.com/paulgug/status/2115238461032779947