Bug Hunt Bench:GPT-6 Astra 重复跑分提升代码审查
同一模型跑 3 次找 bug,Astra 得分从 45 升到 55,作者建议代码审查至少跑 3 遍。
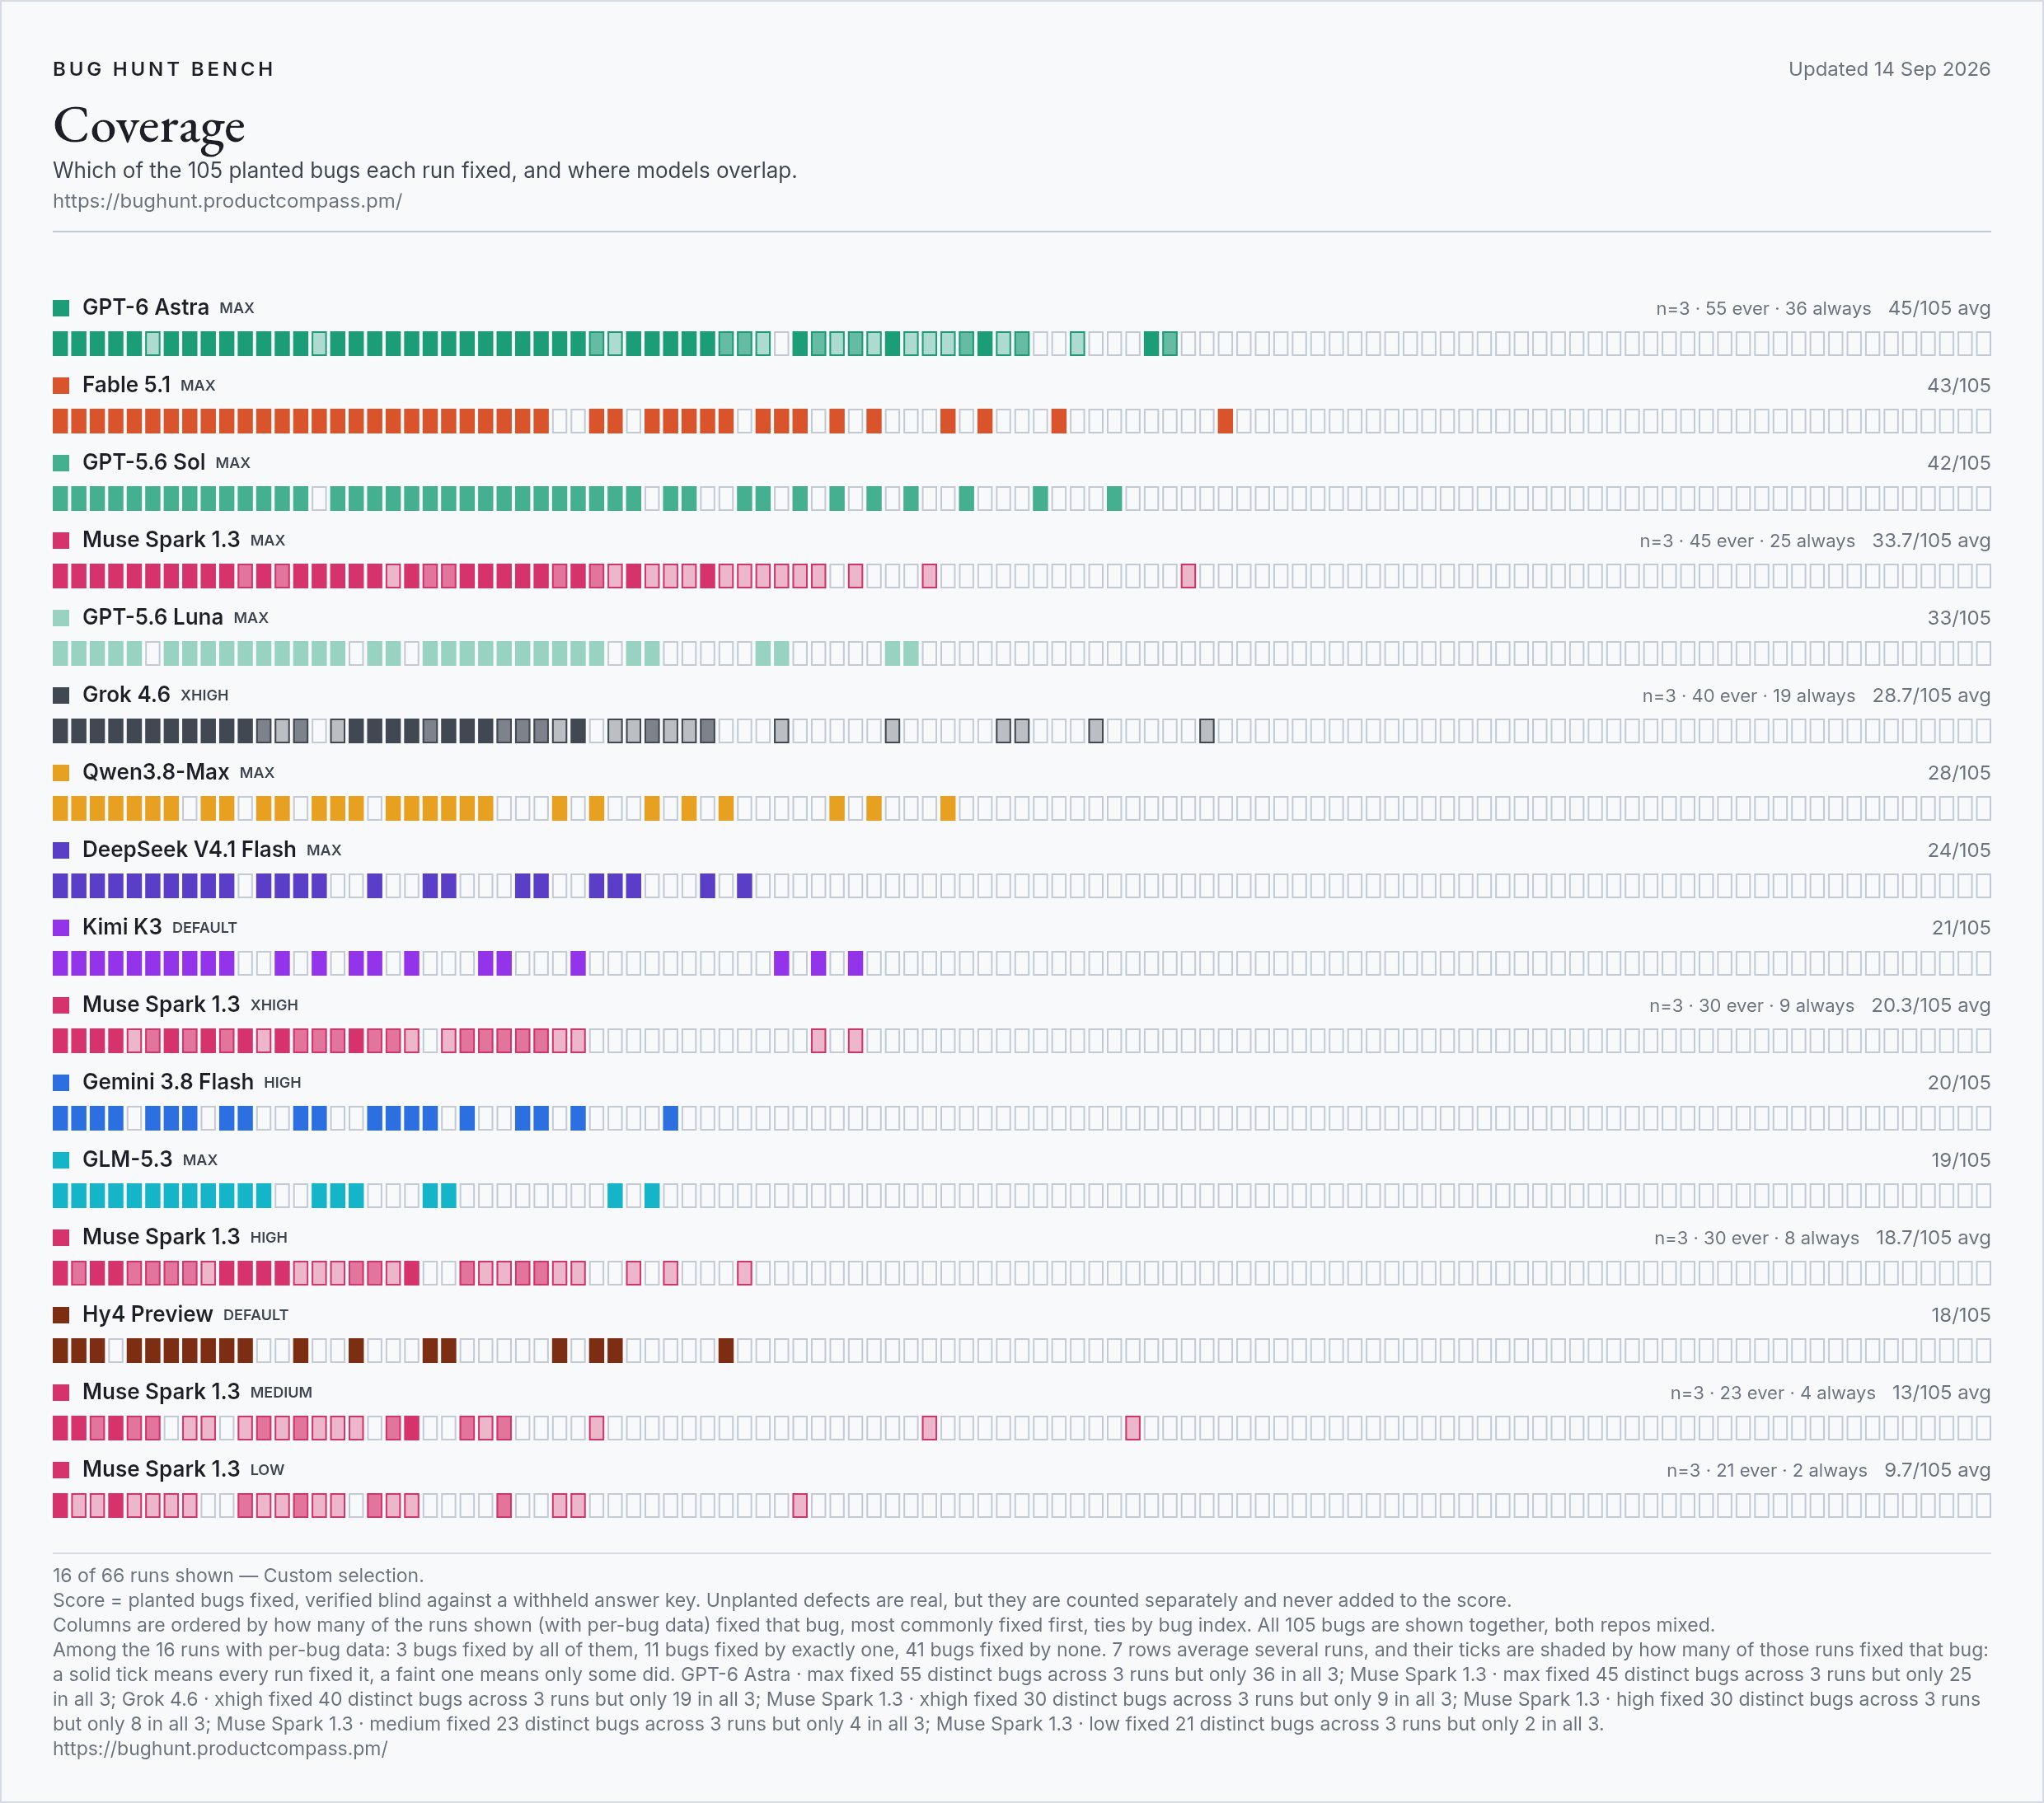
Today, in the Bug Hunt Bench, I started measuring how often the models find and fix the same bugs. Turns out, the lower the effort, the more you gain by running the same model multiple times. For example for n=3: - GPT-6 Astra (max) score jumps from 45 to 55 - Muse Spark 1.3 (max) jumps from 33.7 to 45 - Muse Spark 1.3 (high) jumps from 18.7 to 30 - Muse Spark 1.3 (low) jumps from 9.7 to 21 A practical implication: You get 20-50% better code review results by reviewing your code 3+ times. BTW this and how how incredibly motivated GPT-5.6 Luna (max) is could explain why it scored 33 - same as Fable 5.1 (high). When it comes to hunting bugs, persistence and motivation can beat a raw intelligence. More models dropping in the next few hours (website).
这条是引用着另一条写的:x.com/pawelhuryn/status/2099043849104429326