Maya v1.1.29 本地运行 M3.1 Flash:428B 总参、23B 激活
Maya 新增 M3.1 Flash 引擎,可在 V100 起的 NVIDIA 显卡上本地跑,自动规划显存、长上下文缓存减半,视觉塔按需加载;后续将出适配 128GB 机器的 GGUF 量化。
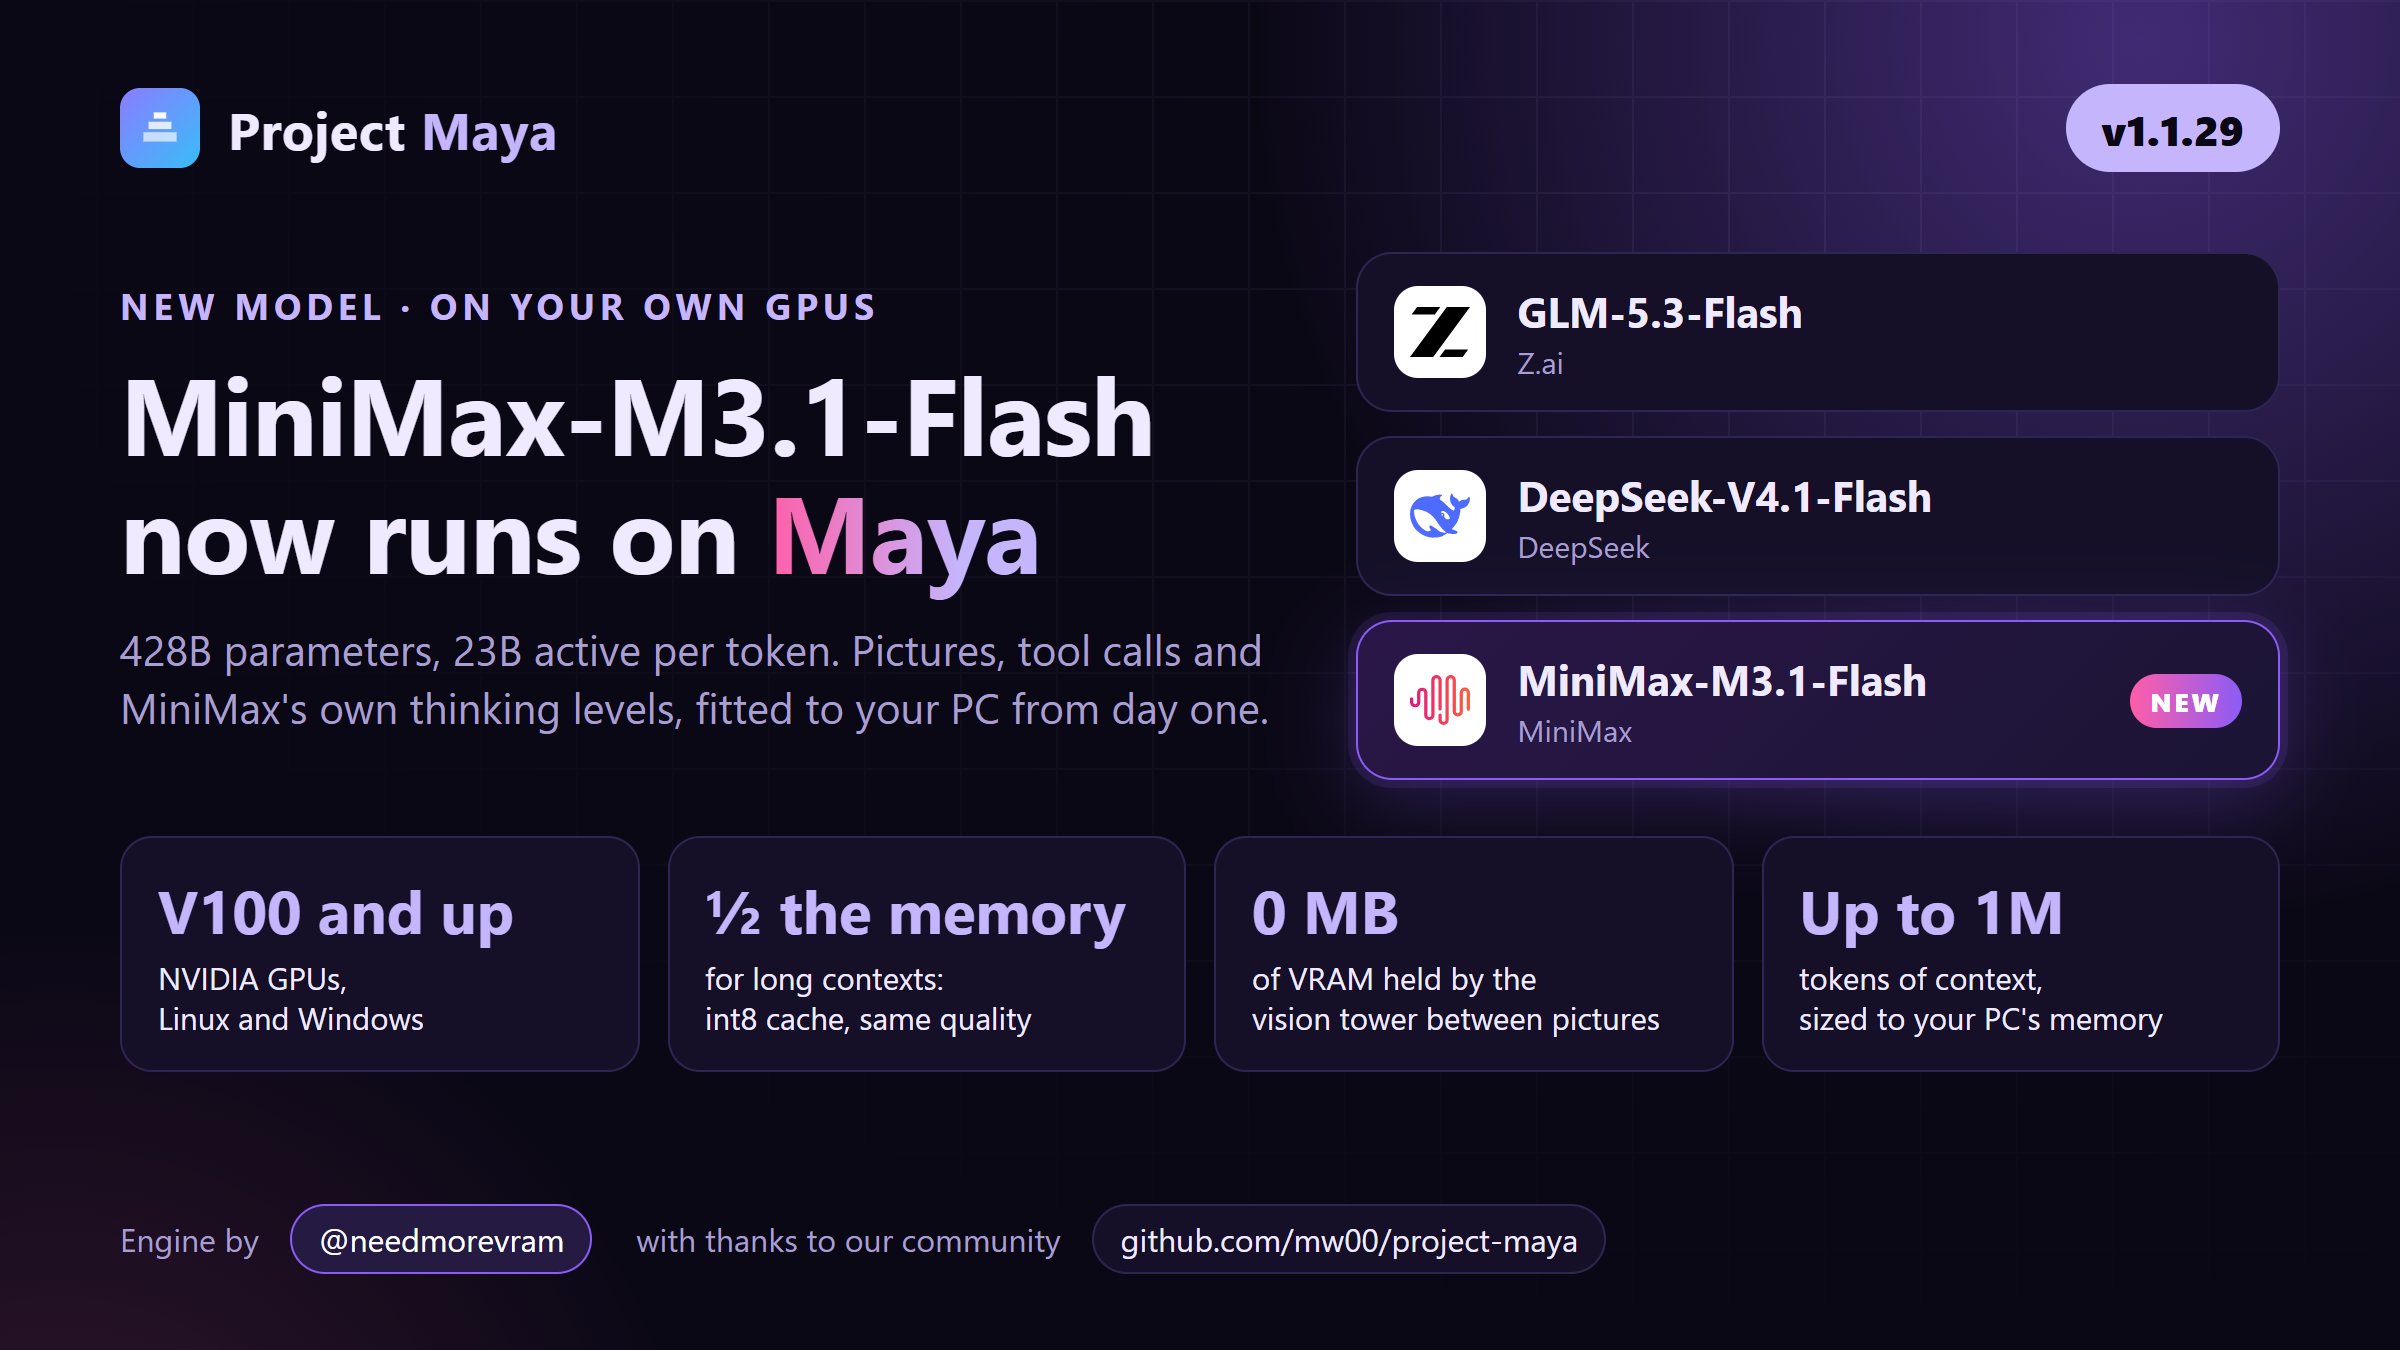
Project Maya v1.1.29 is here, and it's a big one: MiniMax-M3.1-Flash now runs on Maya. That makes three frontier open models you can run at home on your own GPUs: GLM-5.3-Flash, DeepSeek-V4.1-Flash and now MiniMax-M3.1-Flash, a 428B model with 23B active per token and up to a 1M context. MiniMax gets its own engine, built by @needmorevram. We brought it up to the same standard as GLM and DeepSeek before shipping it: - Runs on NVIDIA from V100 up, on Linux and Windows - Fits itself to your PC: the setup picks the context your memory can hold, and the engine plans VRAM and RAM instead of failing - A compact cache by default, so long contexts take half the memory with no loss in quality - Pictures, tool calls and every one of MiniMax's thinking levels, with its own recommended settings out of the box - The vision tower stays off your GPU until you send a picture, so the VRAM goes to the model Huge thanks to @needmorevram, and to everyone who tests, reports and contributes to Maya. This is what community open source looks like. Next up (WiP): our own Maya GGUF quants of MiniMax-M3.1-Flash, small enough for a 128 GB PC. Link in the reply 👇