实测 Jev 校准度:8 个数据集错 7 个
用贷款违约、破产、医疗诊断等 8 个真实数据集共 16500 次预测检验 Jev 的置信度,7 个数据集校准失败,且系统性高估坏结果概率约两倍。
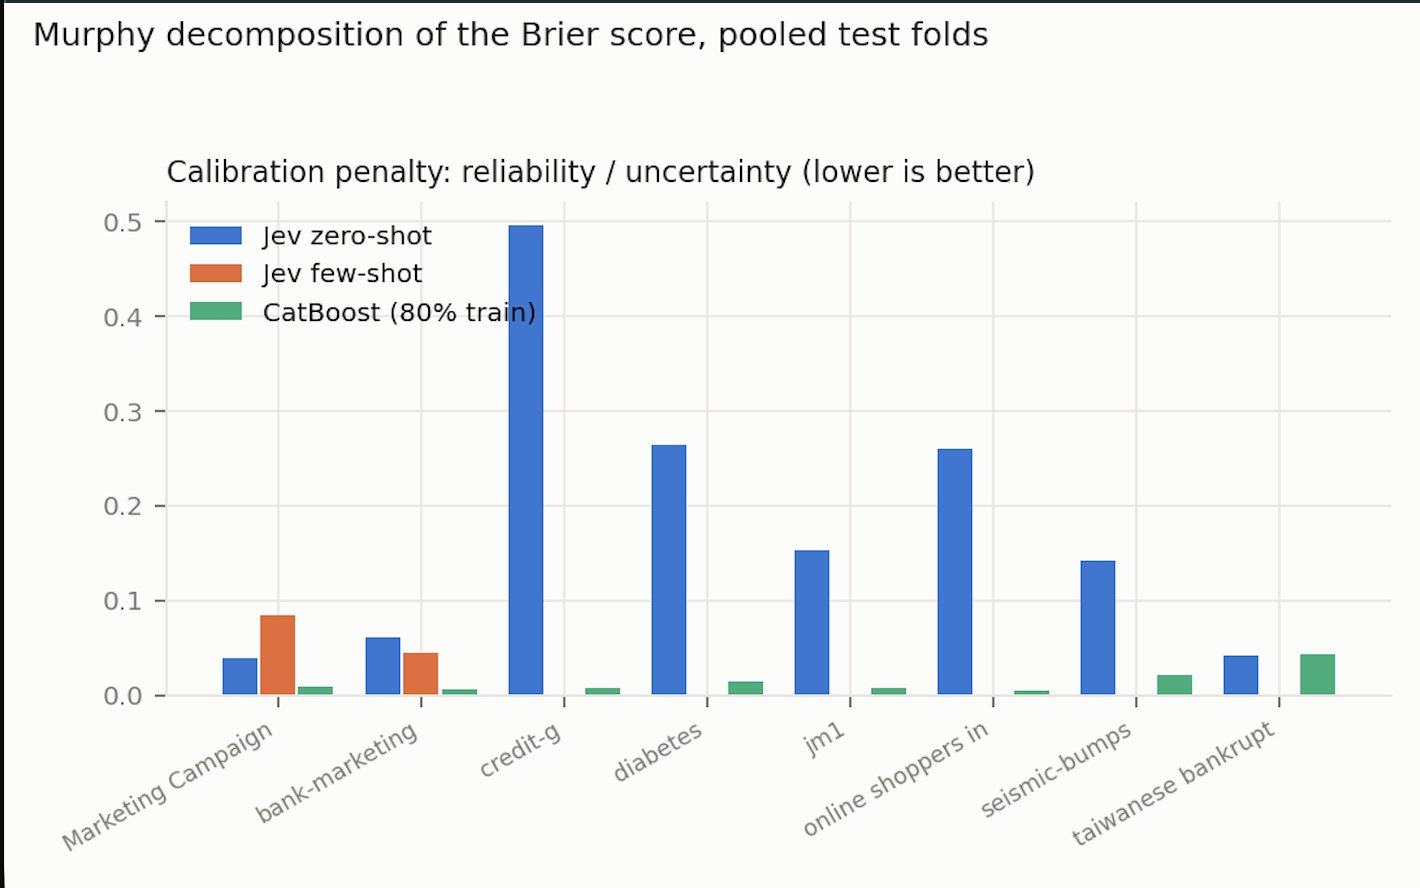
@fakegingerbitch asked and I checked. Here is what I quickly found: TypeSafe sells its AI model Jev on one promise: when it says "70% likely", it's right about 70% of the time. I tested that on 8 real datasets — loan defaults, bankruptcies, medical diagnoses, marketing responses. 16,500 predictions. It fails on 7 of 8. Jev is 10× more miscalibrated than CatBoost, a standard model anyone can download for free. On average it's no more useful than guessing the overall rate for every single case. And it fails in one direction: it thinks bad things are about twice as likely as they really are. Loan defaults, bankruptcies, disease — all overstated, on every dataset. German loan data: applicants flagged "critical account" repay 83% of the time. Jev says 26%. The fix takes 120 rows of data and a textbook method from 2017. It removes three quarters of the error. A model that was actually calibrated would gain nothing from that. Calibration is something you measure. Not something you announce.
这条是引用着另一条写的:x.com/fakegingerbitch/status/2101118764561453436