Jev vs TabPFN:招聘欺诈审核实测
用 17,880 条招聘帖对比:Jev 44 例样本 AUC 0.8883,TabPFN 全量 0.9995,作者建议 Jev 决策、表格模型预测。
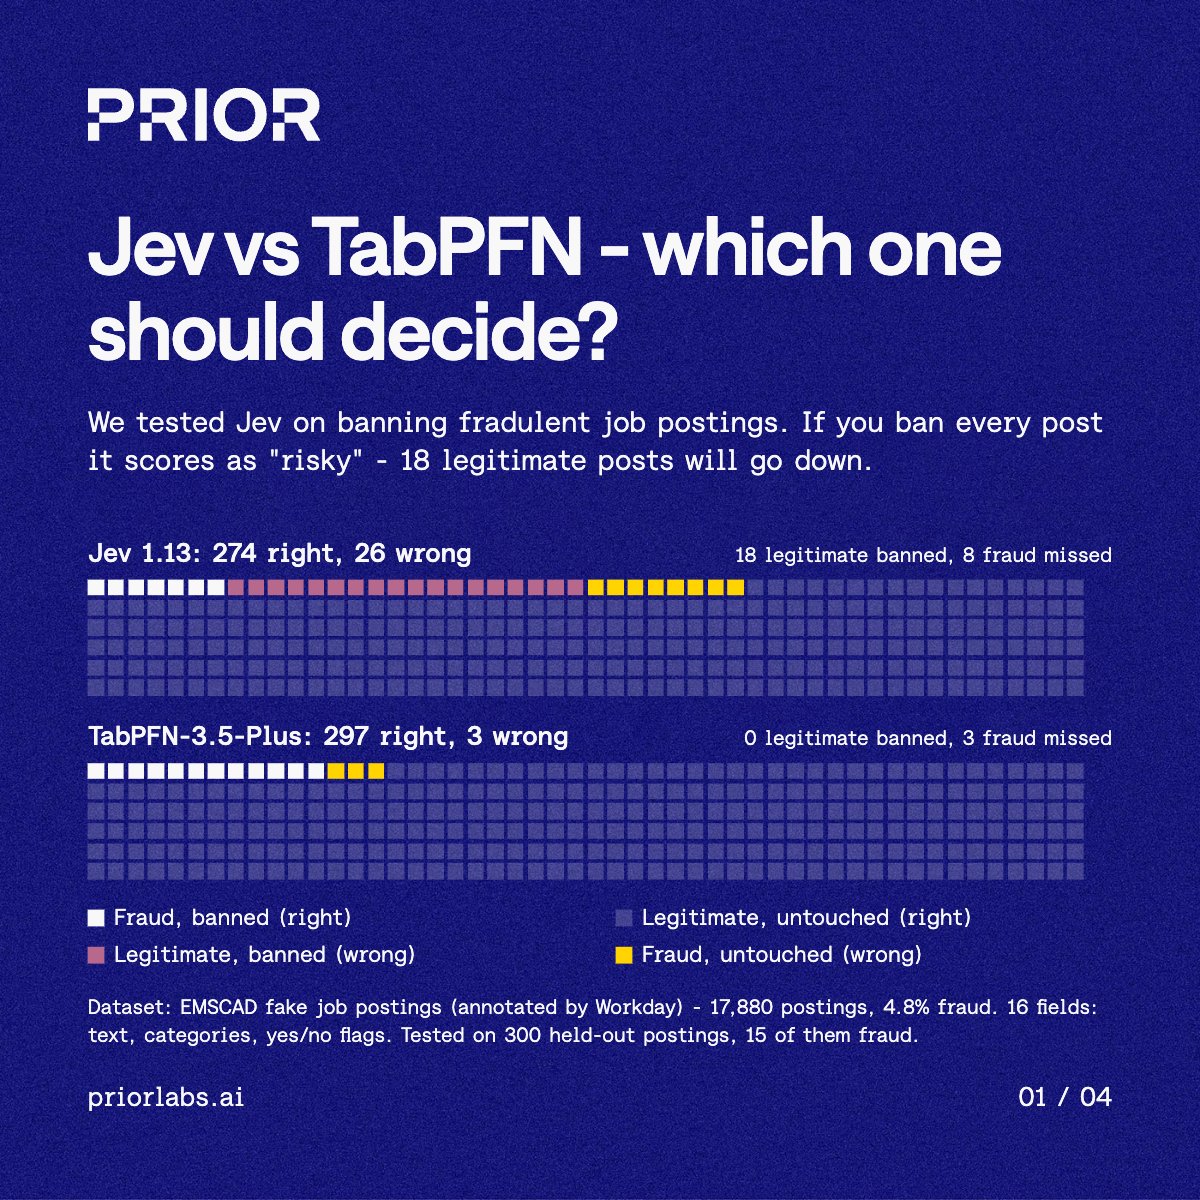
We tested what happens if an agent moderates a job board and bans any post scored above 60% on fraud risk. This is a classic prediction (and decision!) task - few fraud examples, a lot of legitimate ones, and outcomes that cost you both time and money. We used an open dataset of 17,880 job postings and evaluated ROC AUC of two models - Jev and TabPFN - on the same 300 test posts: Jev, 44 examples (enforced by its context limit): 0.8883 TabPFN, 400 examples: 0.9485 TabPFN, all 17,567 eligible training examples: 0.9995 Jev’s average predicted fraud risk was 27.5%, while the actual rate was 5%. TabPFN landed at 4.8% with 400 examples. This suggests a new approach to agentic systems - the agent handles end-to-end moderation, Jev helps it decide on the right tools, while a tabular foundation model makes the predictions. And in case you'd like to try and compare yourself, the setup and results are in the cookbook - link in comments.