GPT-6 Astra 在 MazeBench 无 Python 赛道拿 14%
Astra 在长程空间推理基准 MazeBench 无代码赛道得分 14%,约为 Claude Fable 5.1 的 7 倍,但真 3D 题仍失败。
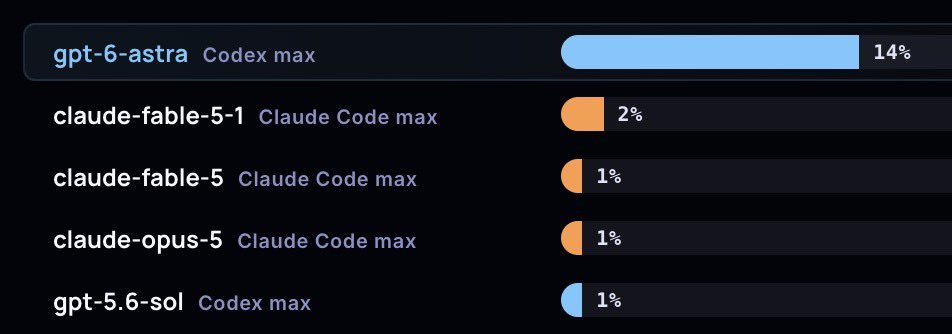
Big score by GPT-6 Astra, 14% on MazeBench without Python, 7X Claude Fable 5.1's 2%. MazeBench specifically stresses long-horizon spatial reasoning, with puzzles that can require more than 100 moves and repeated interaction with a changing environment. So Astra seems able to hold a long plan in its head and execute it without relying on Python to solve the environment for it Its remaining failures on genuinely 3D puzzles show that the improvement is mainly in sustained planning, not complete spatial understanding. MazeBench hides 100 gems across more than 200 rooms, forcing agents to rotate views, manipulate boxes, recover from mistakes, and execute plans that can exceed 100 moves. The no-Python track makes it so much harder because code-enabled agents can reverse-engineer the physics and run solver algorithms instead of carrying the full spatial plan themselves. MazeBench's creator says Astra still surpassed GPT-5.6 Sol's 13% code-enabled run and often planned 10-20 moves ahead in batched actions. That batching reportedly reduced a projected 3B-token trajectory to about 350M tokens, but the run still lasted more than 60 hours.
这条是引用着另一条写的:x.com/patience_cave/status/2096963644164804789