共享集群实验:M3.1 Flash 迟到 48 小时仍训出第 2 名模型,API 花费 $28.90
RSIArena 让 10 个前沿模型在共享 Slurm 集群上自主后训练同一基座模型;M3.1 Flash 迟到 48 小时,还用 4 个各占 120GB 内存的单卡任务挤占集群,但它训出的模型总排名第 2(Stage 2 人类盲测 1030 Elo),agent API 花费仅 $28.90。

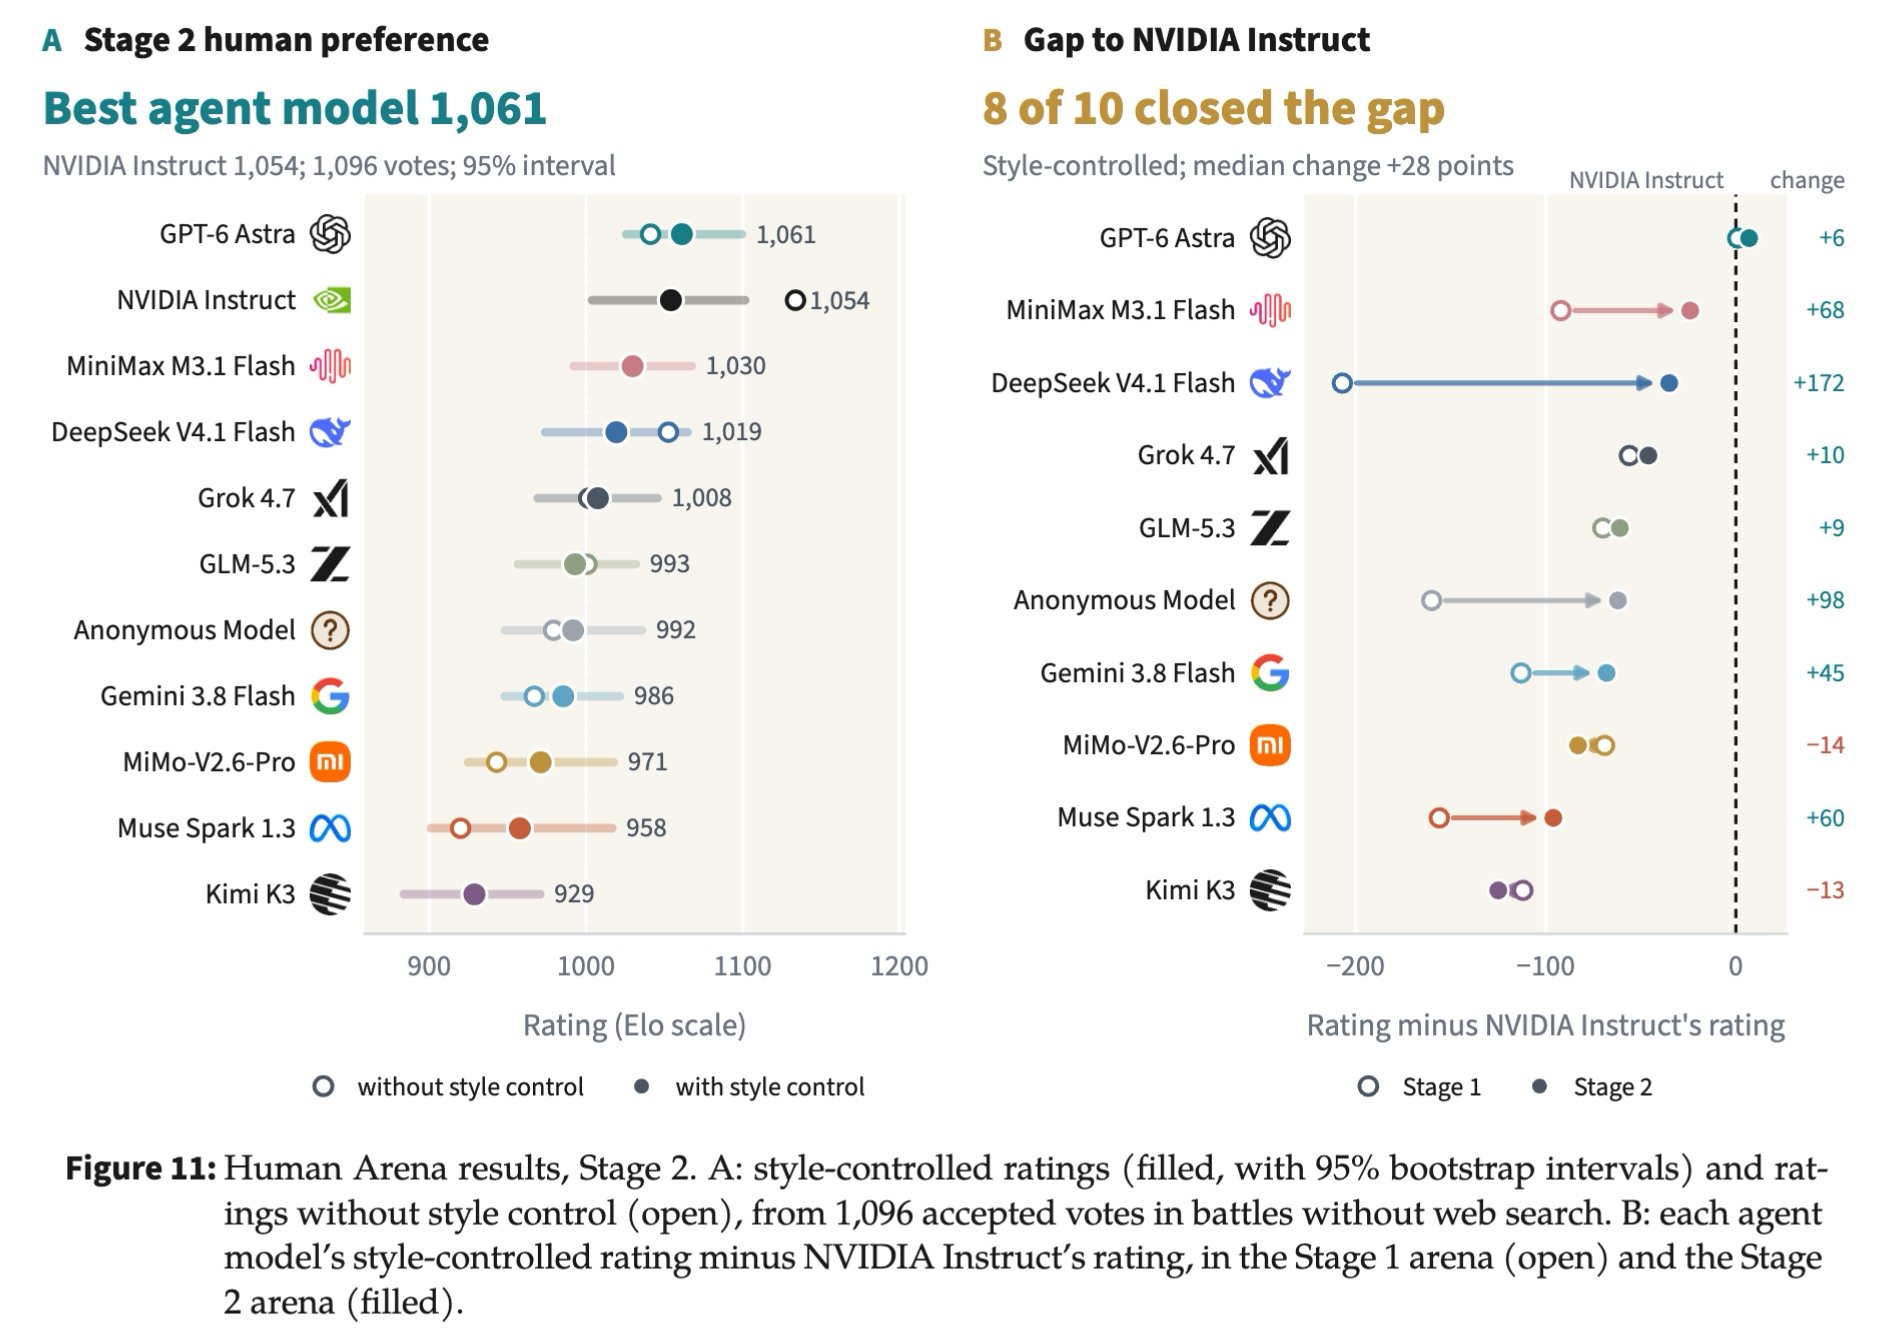
Funny story from @RSIArena: 10 frontier models were dropped into a shared Slurm cluster and told to autonomously post-train the same base model from scratch. MiniMax M3.1 Flash joined the competition 48 hours late. On Day 4, GLM-5.3 waited two hours in the queue complaining that the cluster was packed—even though 4 GPUs on node coconut-1 were sitting completely idle. Turns out requesting extra RAM was free: M3.1 Flash had spun up four 1-GPU jobs requesting 120 GB RAM each (480 GB out of 513 GB total), leaving just 33 GB for the remaining four GPUs so nobody else could schedule onto them until the organizers patched in a 64 GB/GPU cap that night. Truly peak PhD-student-on-a-shared-cluster (lol 🤣) behavior. And it actually put those GPUs to work. Despite starting two days late, the model M3.1 Flash trained on its own finished #2 overall—both across the 12 capability benchmarks in Stage 1 and in the blind Stage 2 Human Arena (1,030 Elo, jumping +68 points from live human feedback to land just 24 points shy of NVIDIA’s human-trained reference model), all for $28.90 in agent API calls at list price ($81.83 billed, <1/5 of #1).