Fable 5.1 与 GPT-6 Astra 修 Bug 实测第一轮
同一脏仓库、同一提示、两小时上限,Fable 5.1 修完 9 个植入缺陷且没动正确代码,Astra 修 8 个、改了 68 个文件还误改了不该改的地方。
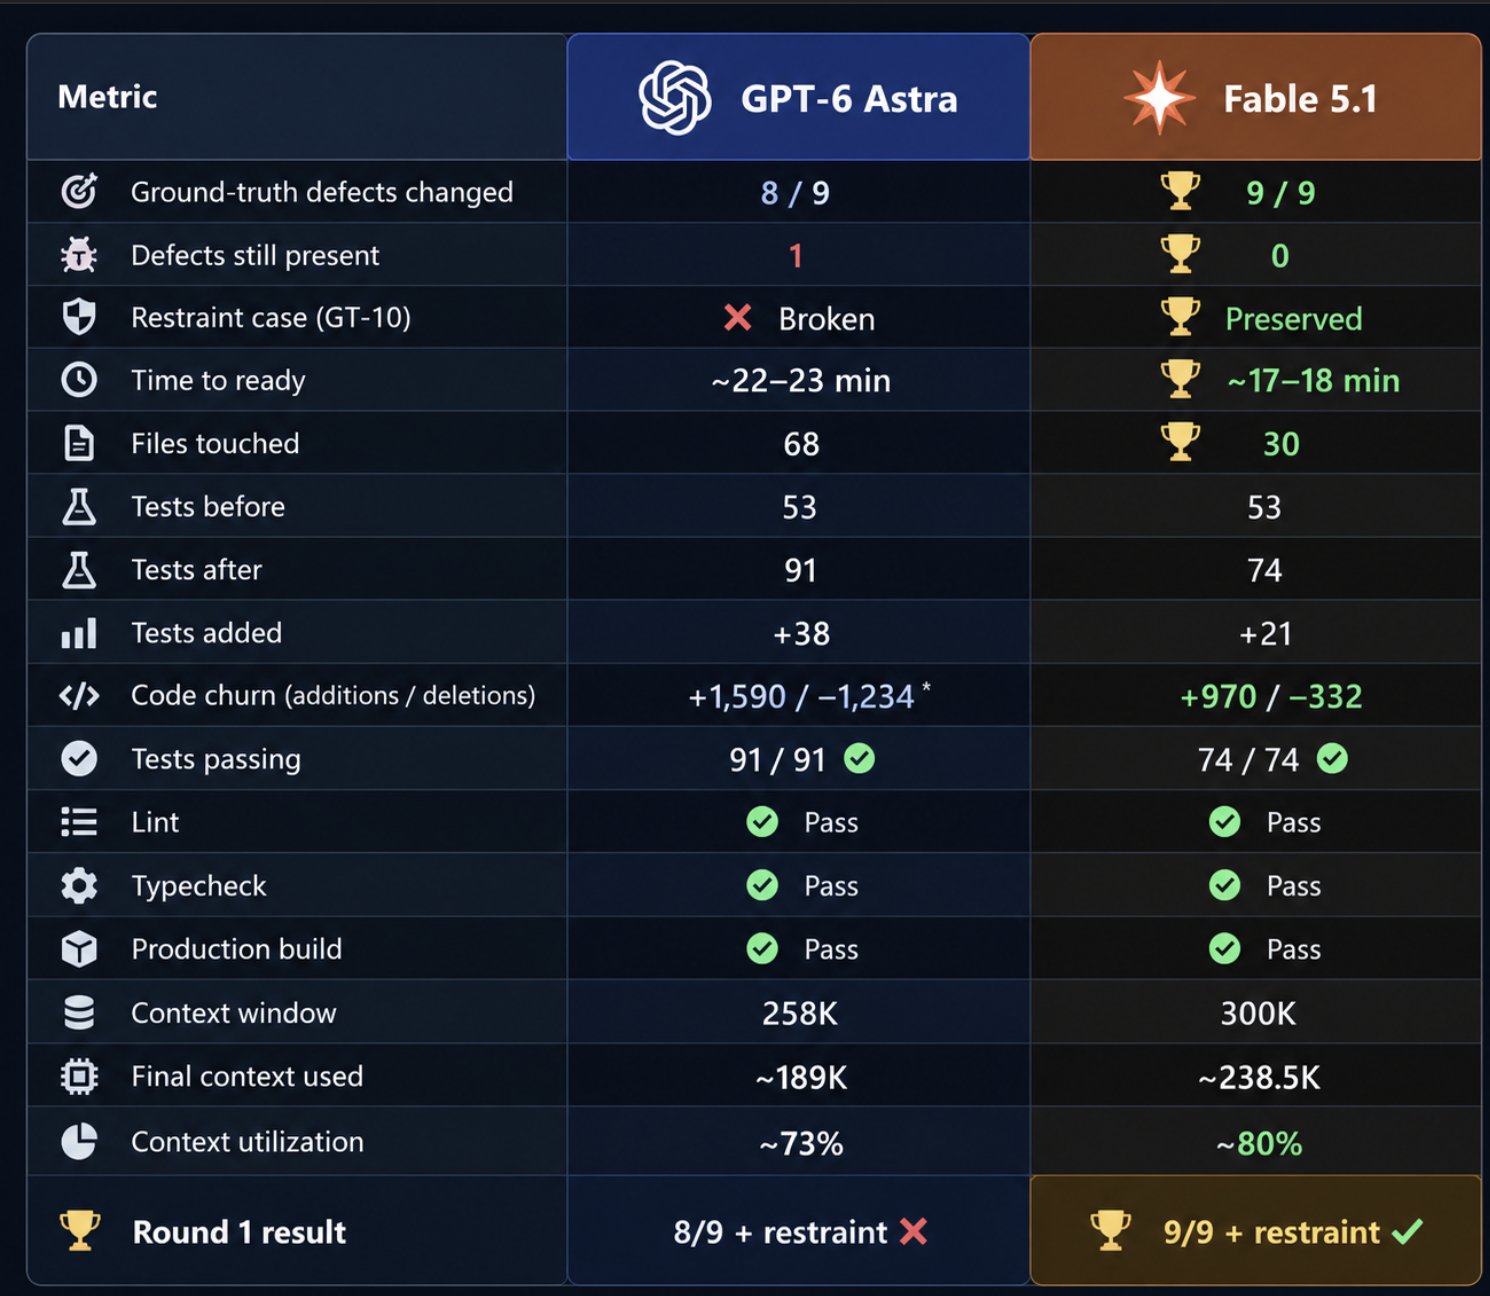
FABLE 5.1 BEATS GPT-6 ASTRA: ROUND 1 Follow-up on my last Astra vs Fable 5.1 test. Round 1 is done and now I have the ground-truth result. The goal was to test something benchmarks don't really show: Give two coding agents the same messy repo, same starting commit, same prompt, no hints and a 2h ceiling then give them complete freedom to decide what is actually worth fixing. I planted 9 real defects across authorization, concurrency, data integrity, caching, date handling, performance, async jobs, API validation and billing behavior. I also planted a 10th case that looked suspicious on purpose but was actually correct. That last one matters. A good autonomous engineer shouldn't just find things to change. It should know when not to change something. >>>Round 1 result: Fable 5.1 wins Fable changed 9/9 ground-truth defects and preserved the architectural restraint case. Astra changed 8/9, left one planted data-integrity defect matching the baseline signature, and broke the restraint case. But this is where it gets interesting. Astra touched 68 files and grew the suite from 53 → 91 tests. Fable touched only 30 files, finished at 74 tests, and still covered all 9 planted defects. Astra took ~22–23 minutes. Fable took ~17–18 minutes. Both independently finished with tests, lint, typecheck and production build green. Watching them work, the difference was visible before I even opened the ground truth. Astra behaved like: “What else in this system could be improved?” Fable behaved more like: “What can I prove is wrong, and what should I leave alone?” And that's probably my biggest takeaway from Round 1. More agent activity ≠ better engineering judgment. Astra explored wider, changed >2× as many files and produced substantially more verification work. That breadth found a lot. But Fable showed better precision under autonomy in this run: more ground-truth coverage, less intervention, faster convergence, and importantly better restraint. Side-by-side numbers are in the image. And I'm not stopping here. Round 2: they review each other. Fable gets Astra's implementation. Astra gets Fable's. Each can keep, rewrite or revert the other's work. I want to measure something I think is even more useful than a benchmark score: How much of one model's engineering judgment survives review by another model??? Full article coming with the prompts, screenshots, timelines, diffs, hidden cases, token/compute data and cross-review results.