Opus 5.5 基准拆解:建议与 Jev 组成 System 1/2 双模型栈
逐项对比 Opus 5.5 在编码、知识工作、推理和电脑操作上的成绩,并建议把 Jev 作为 70–500ms 内出结构化决策的 System One 层嵌进 agent 循环。
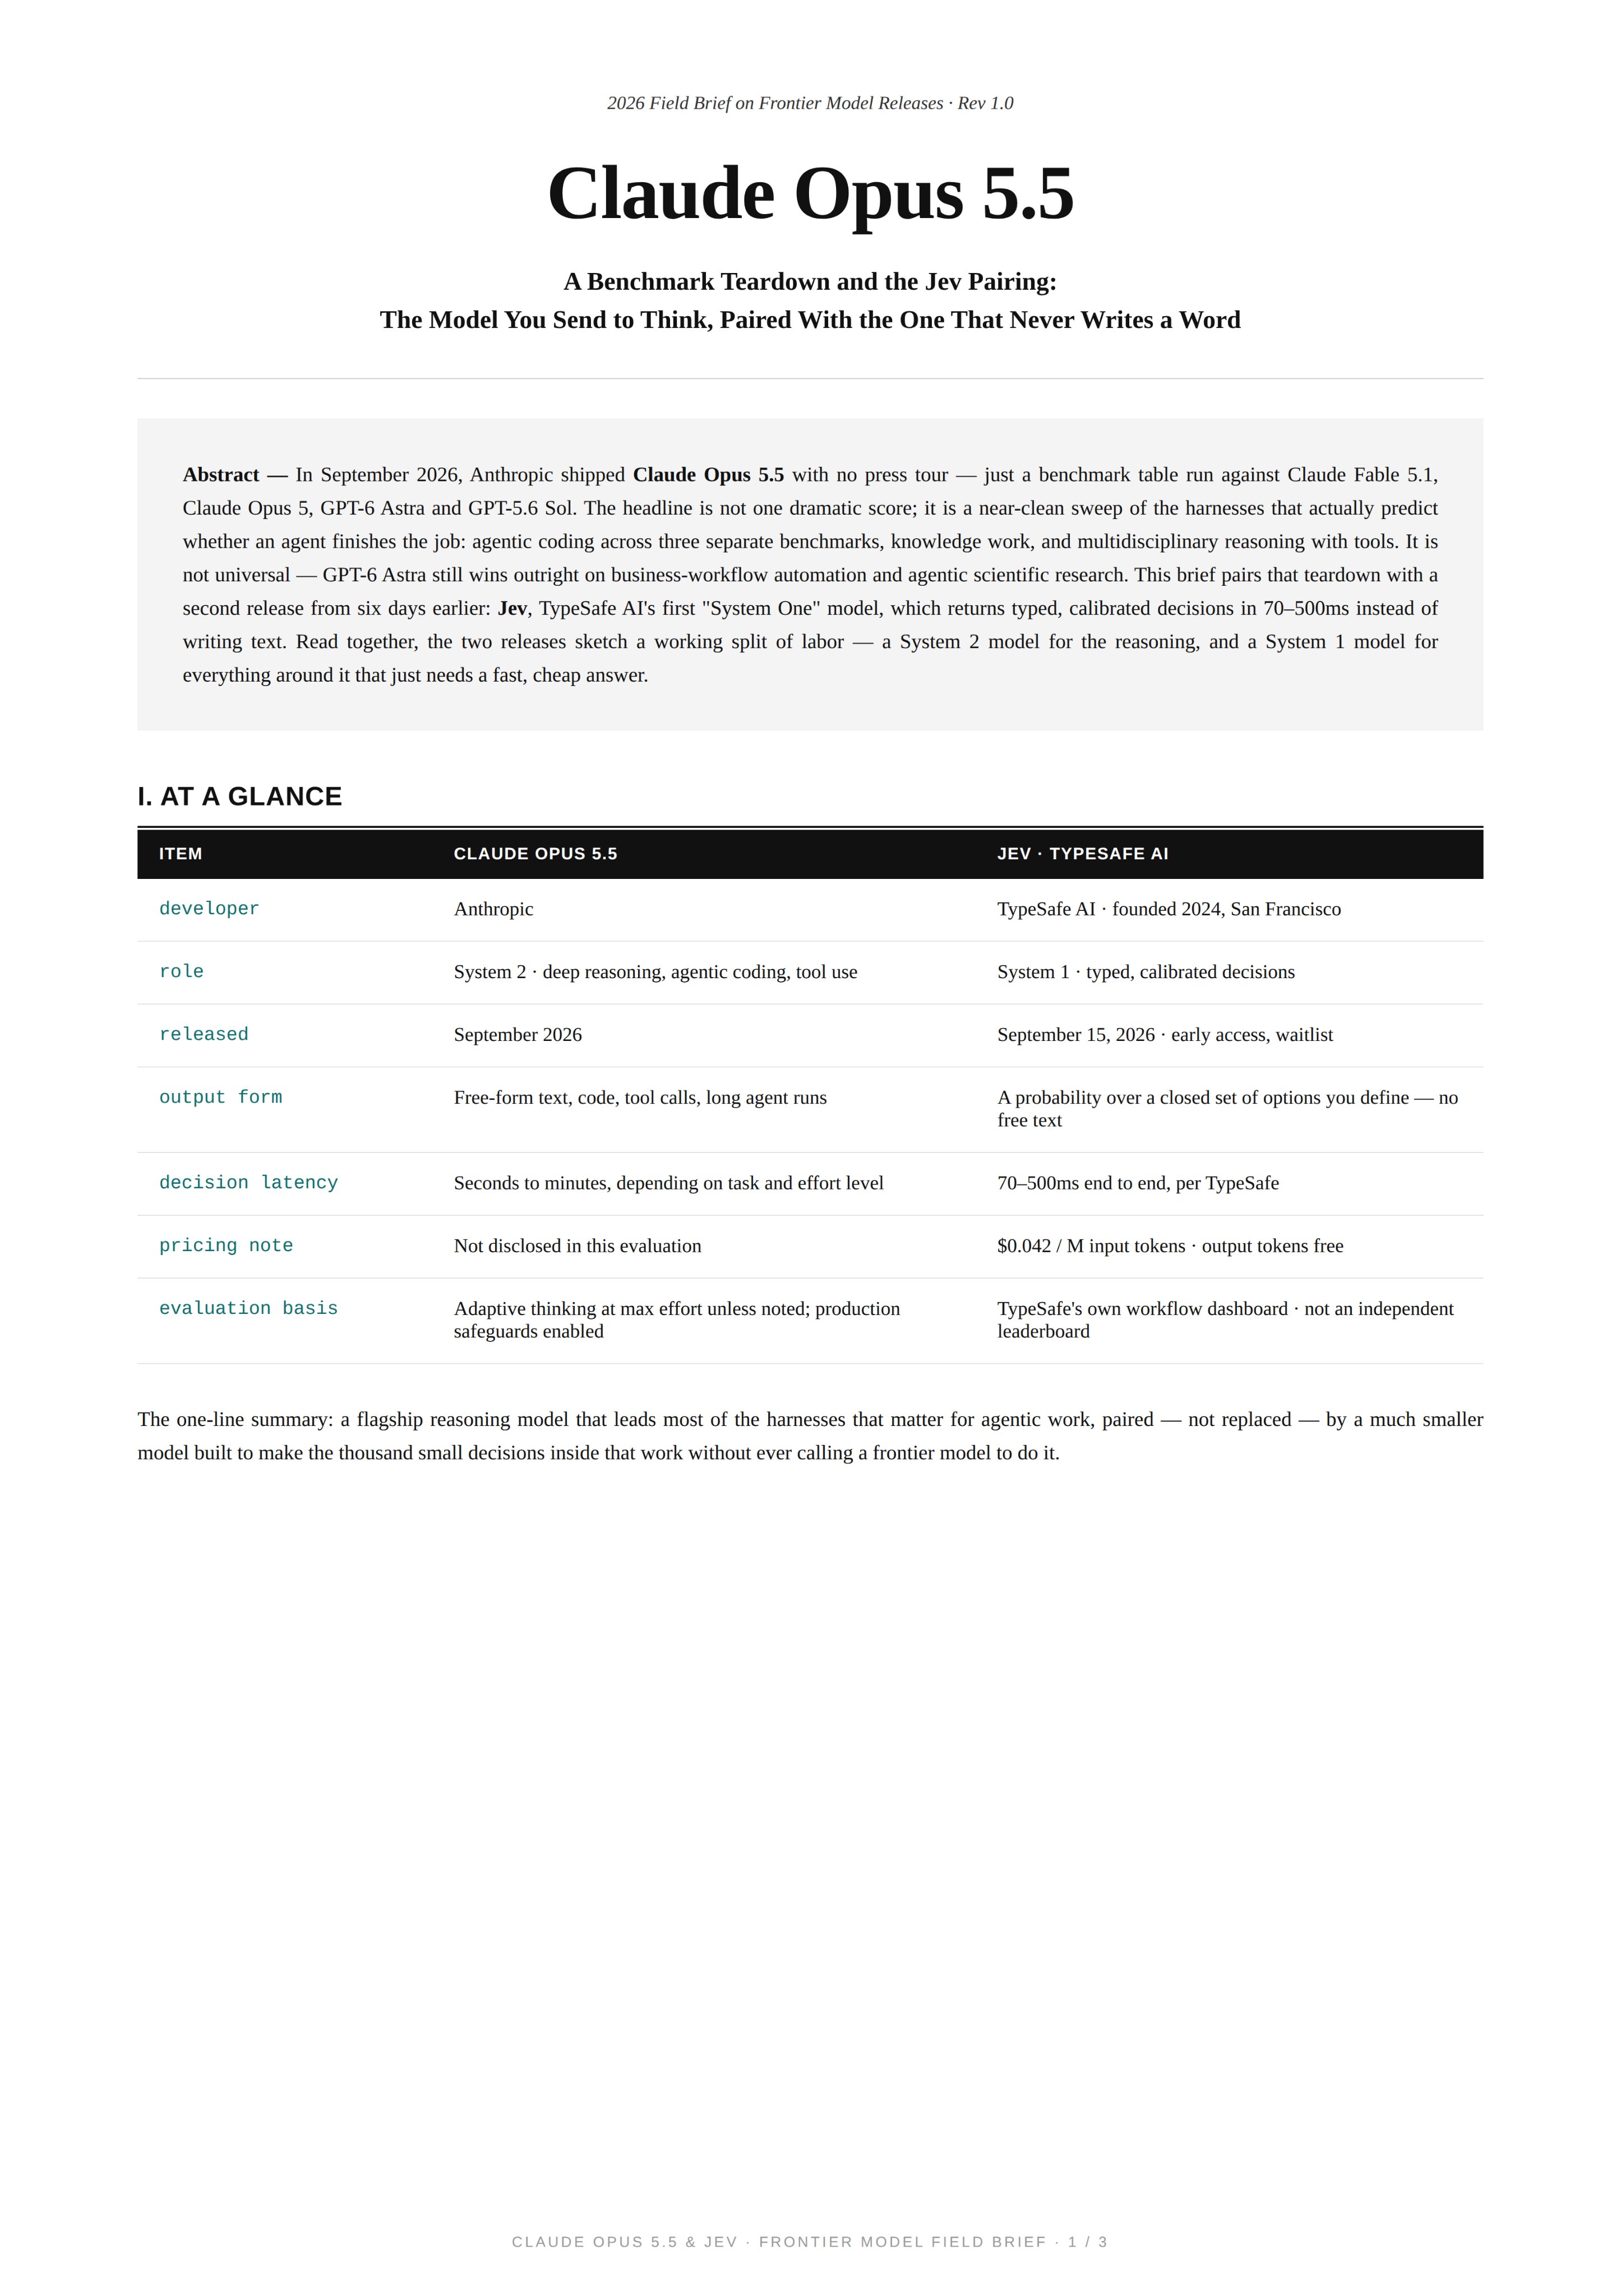
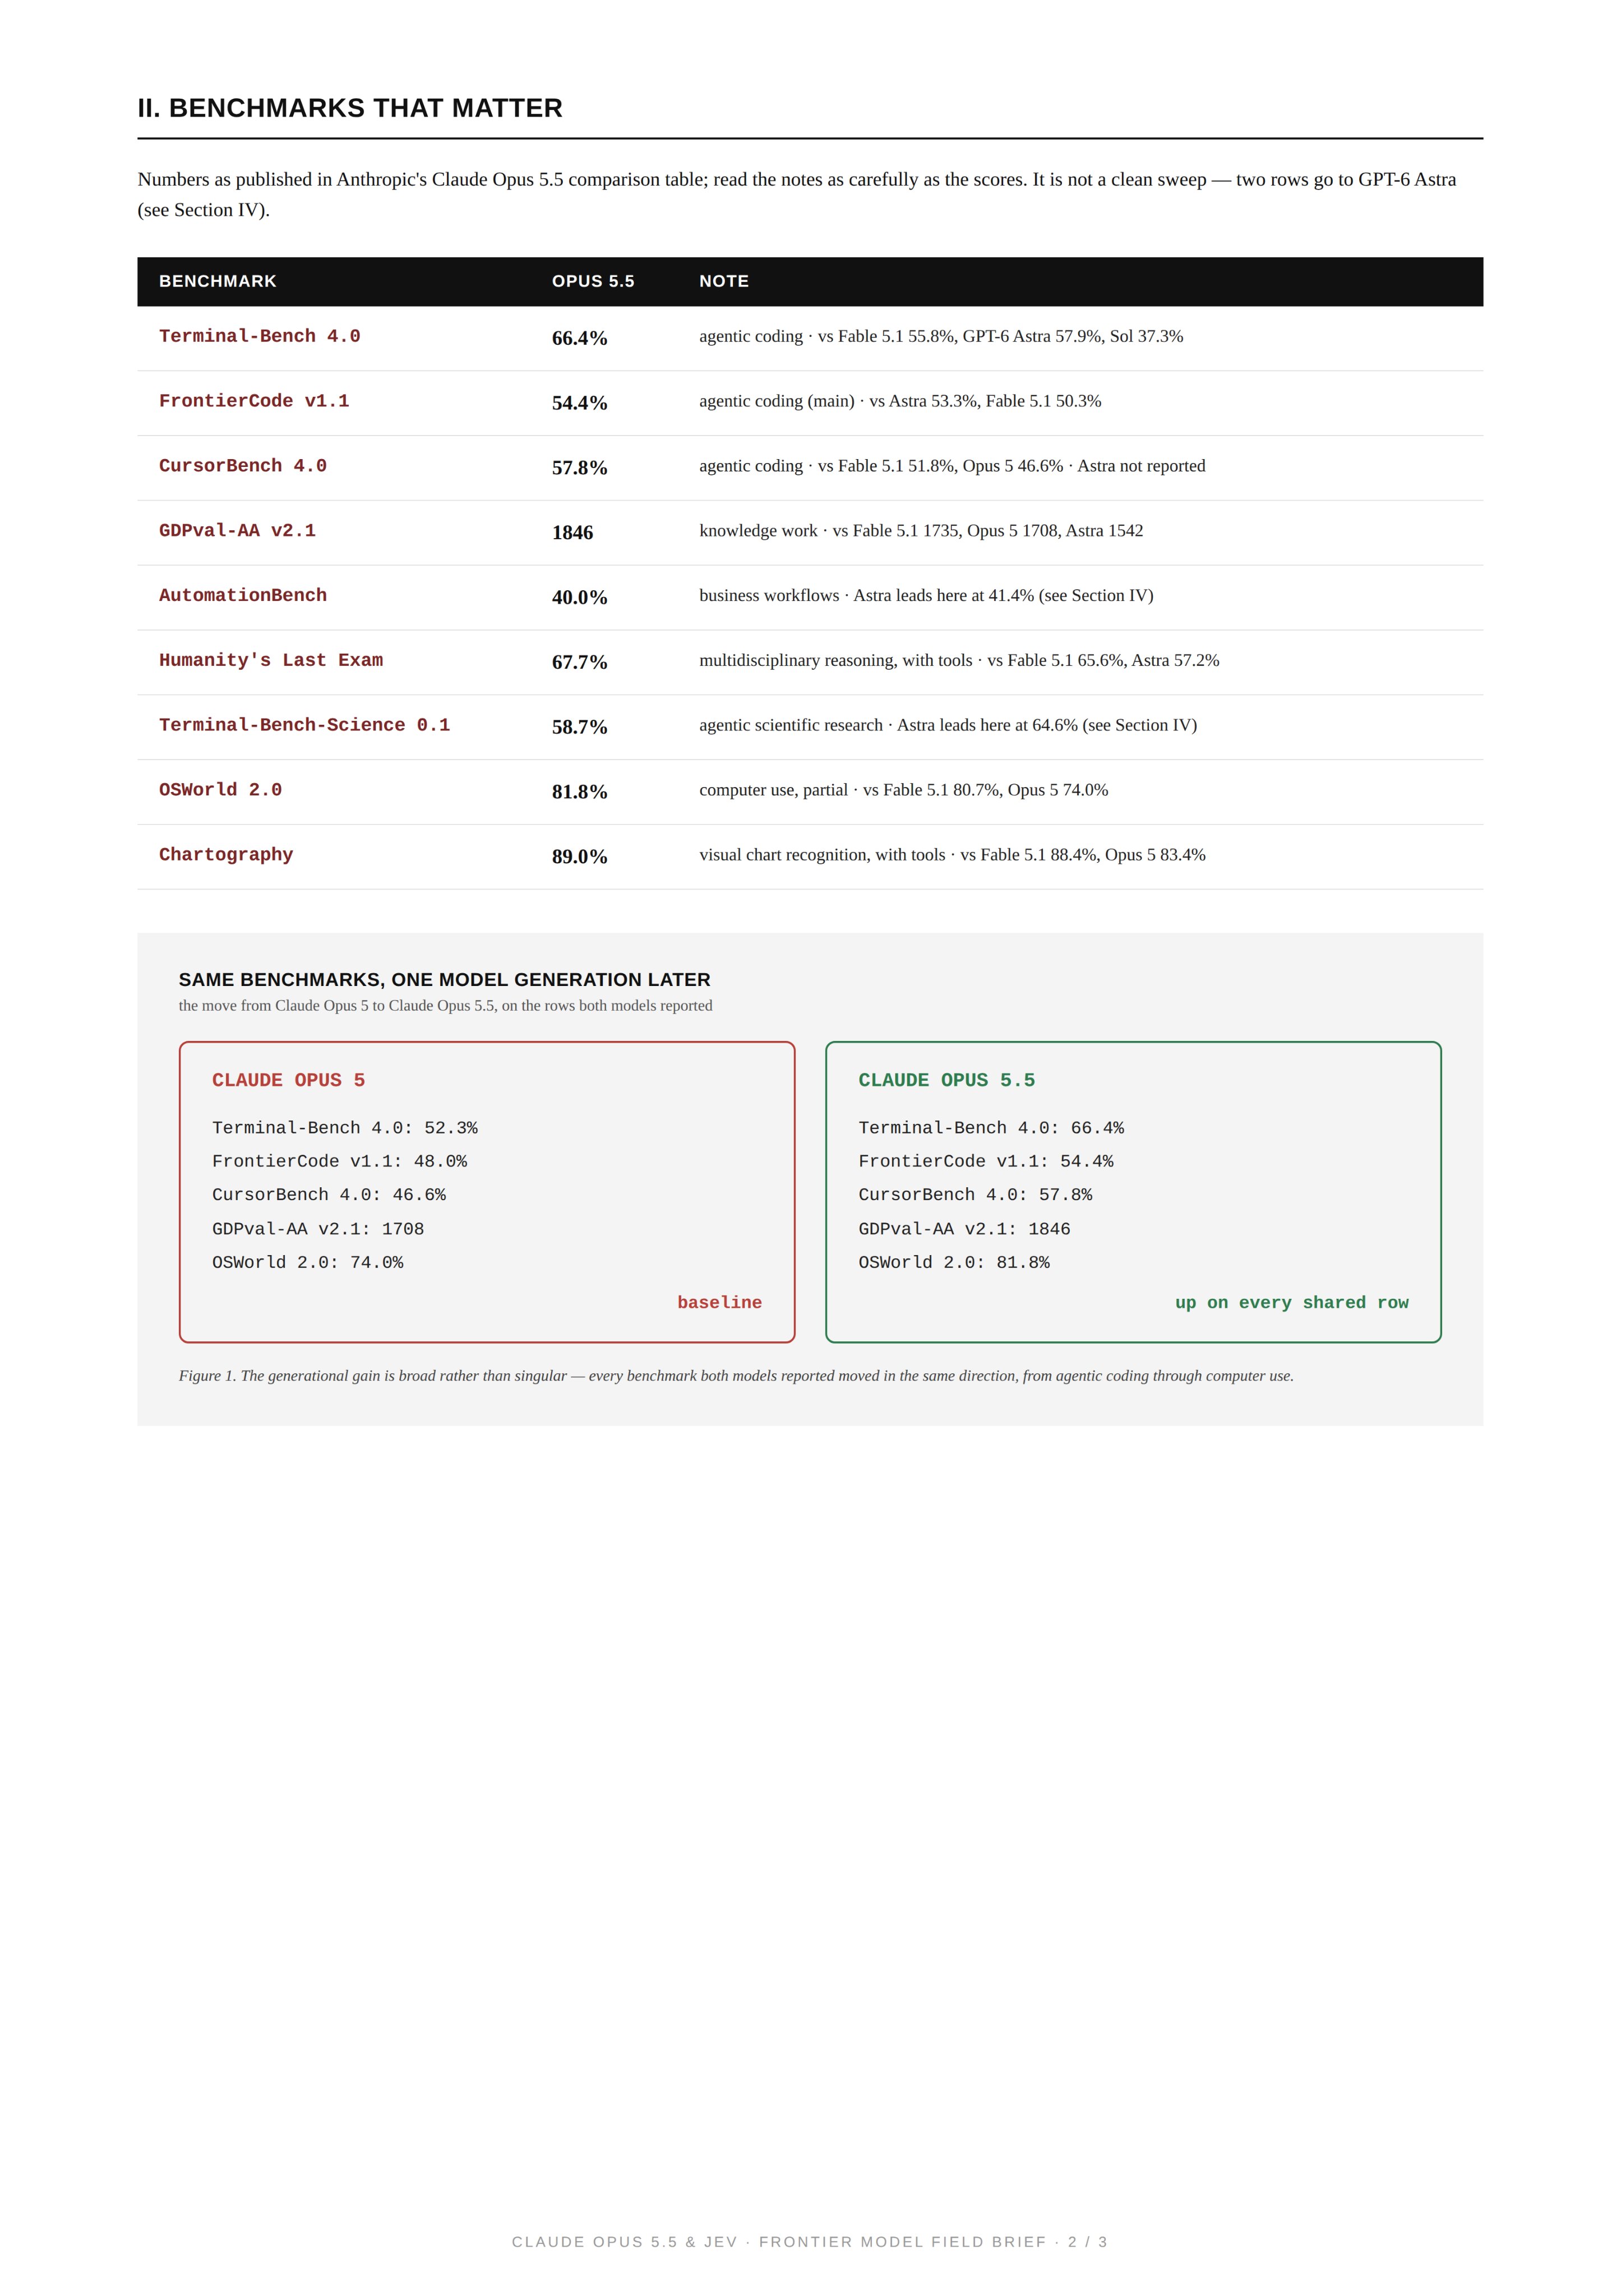
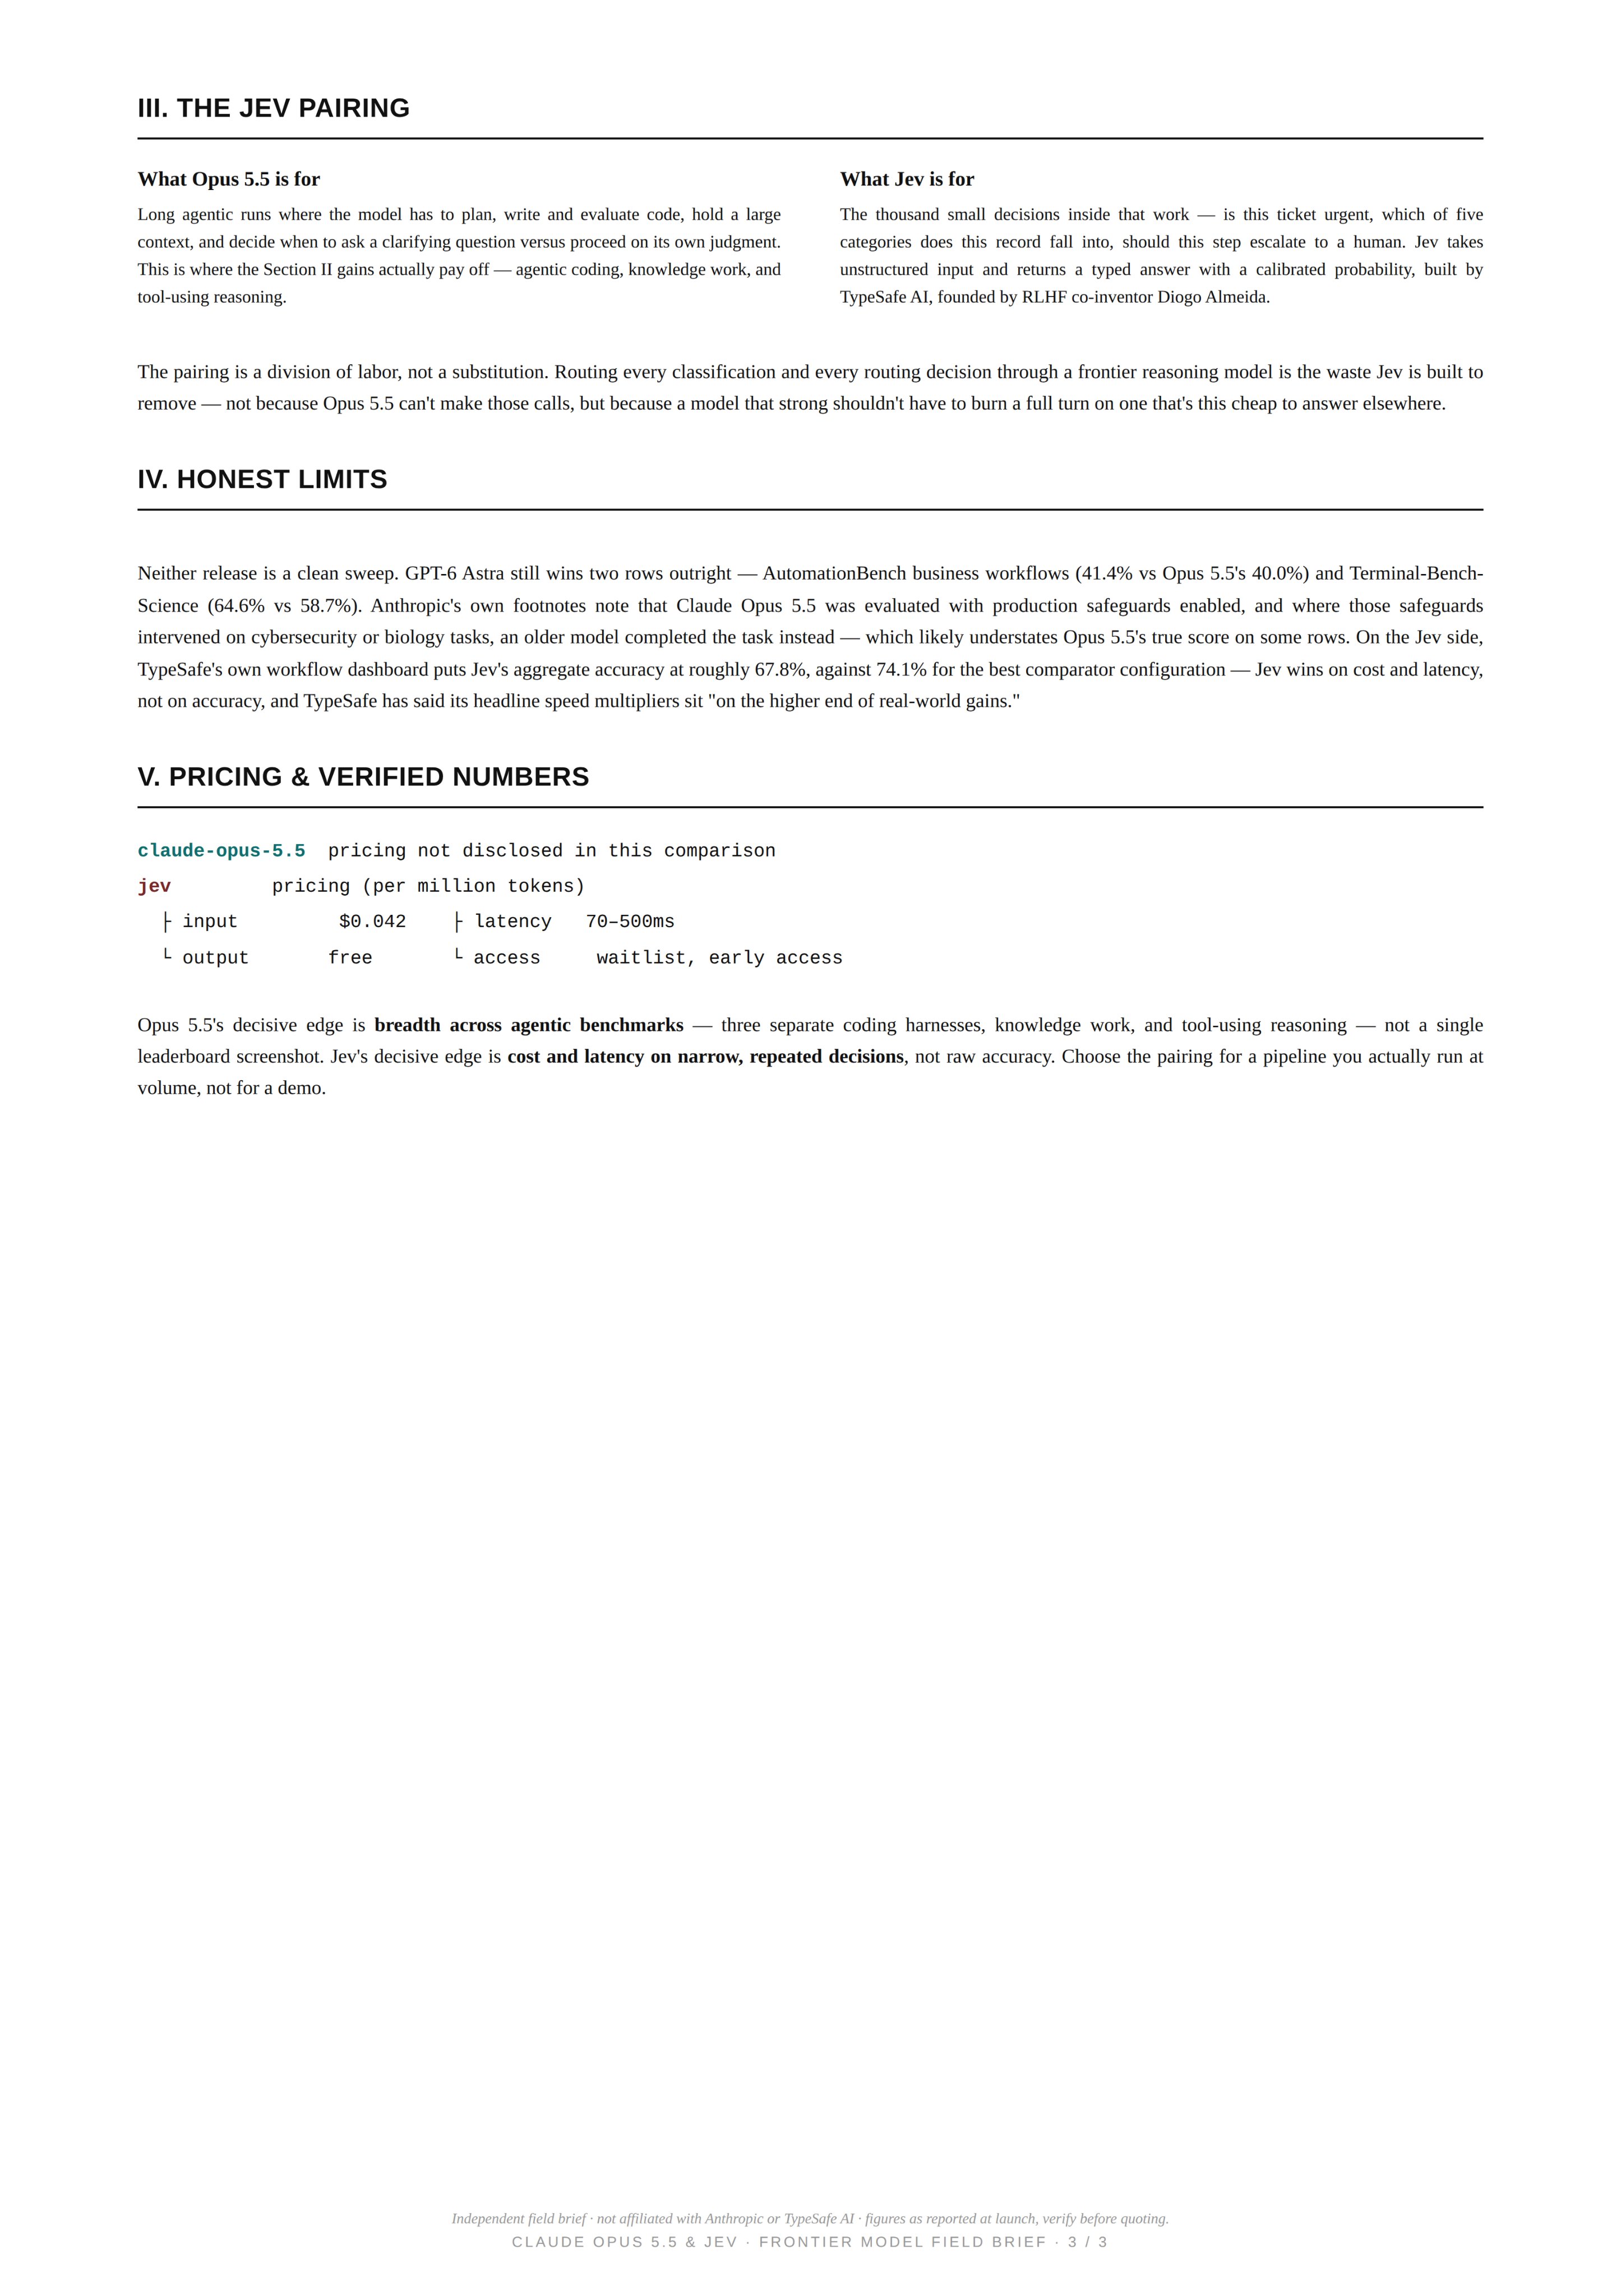
Anthropic just shipped Claude Opus 5.5 and didn't bother with a press tour - just dropped a benchmark table against everything else on the market The shift here isn't a new modality or a new trick. It's the same model, still faster, still cheaper, now just further ahead on the numbers that actually predict whether an agent finishes the job here's the breakdown: 1 - agentic coding, three ways → 66.4% on Terminal-Bench 4.0 (Astra 57.9%, Fable 5.1 55.8%, Sol 37.3%), 54.4% on FrontierCode v1.1, 57.8% on CursorBench 4.0. Not a one-benchmark fluke - it leads on every coding harness that got tested 2 - knowledge work → 1846 on GDPval-AA v2.1, ahead of Fable 5.1 (1735), Opus 5 (1708), and well clear of GPT-6 Astra (1542) and Sol (1588) 3 - reasoning → 67.7% on Humanity's Last Exam with tools, the top score on the table, edging out Fable 5.1 (65.6%) and beating Astra by 10.5 points (57.2%) 4 - computer use → 81.8% on OSWorld 2.0 (partial), ahead of Fable 5.1 at 80.7% - Astra didn't even report a number here 5 - the honest catch → it's not a clean sweep either. Astra actually wins two categories outright: AutomationBench business workflows (41.4% vs Opus 5.5's 40.0%) and Terminal-Bench-Science (64.6% vs 58.7%). Worth knowing before you pick a model by vibes 6 - the stack worth building → pair Opus 5.5 with Jev (TypeSafe AI's new "System One" model, out Sept 15). Jev doesn't write text - it takes unstructured input and returns a typed decision with a calibrated probability in 70-500ms, at a fraction of a cent per call. So Opus 5.5 does the actual thinking - the agentic coding, the long research runs, the judgment calls - and Jev sits inside the loop doing the thousand small classifications and routing decisions the agent doesn't need a full model turn for. System 2 for the hard parts, System 1 for everything that repeats 7 - why this matters → most teams are running one model for both jobs right now - reasoning through a plan AND deciding "is this ticket urgent, yes or no" with the same expensive call. That's the gap Jev is built for, and it's the gap Opus 5.5's own numbers make obvious: the model is good enough that burning it on trivial decisions is waste Full benchmark table and the Jev docs are worth five minutes before you touch your stack
这条是引用着另一条写的:x.com/loofyb0i/status/2102452178384273431