Amplitude 评测:GPT-6 Sol/Luna 与 Opus 5.5 质量成本对比
185 道真实分析任务评测中,Sol 81% 正确率、每题 0.58 美元,是最便宜的 80%+ 模型;Luna 76% 且低于 0.04 美元,但 p95 延迟约 400 秒。
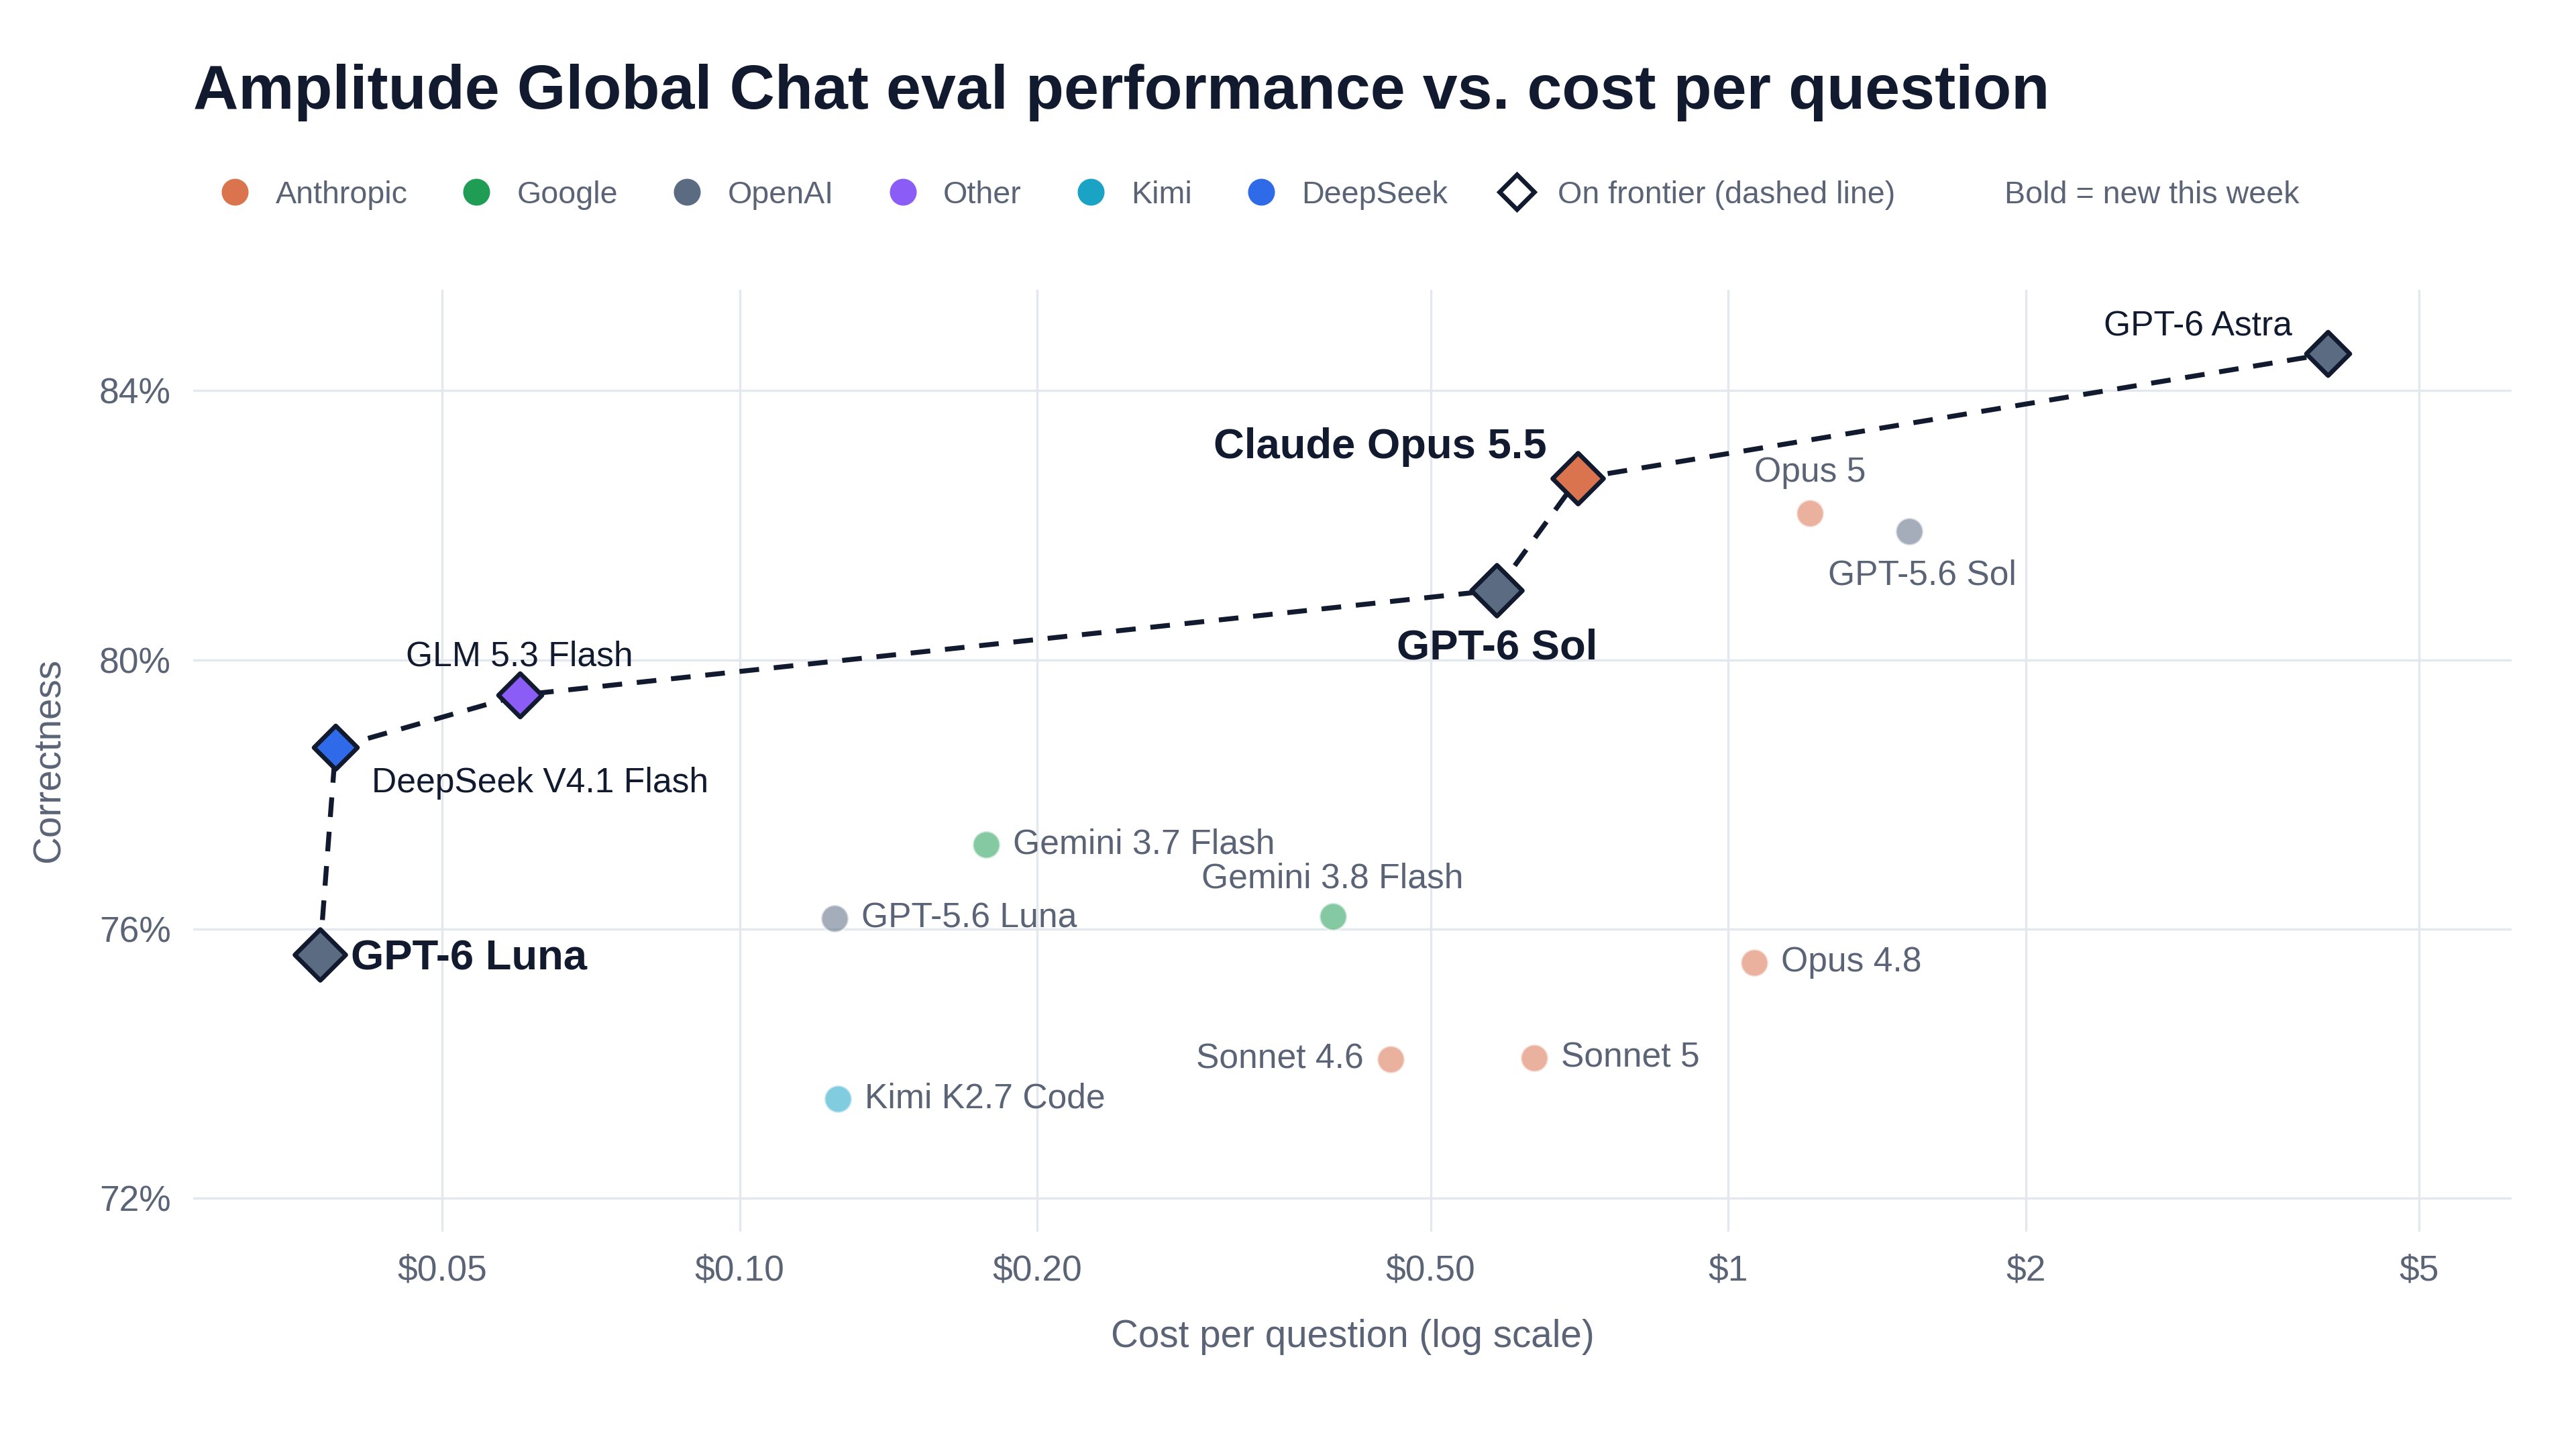
We put GPT-6 Sol, GPT-6 Luna, and Claude Opus 5.5 through our Amplitude Global Chat eval and mapped the outcomes on our quality/cost frontier. Our eval is 185 analytics tasks from simple to complex: building a chart, editing one, choosing the right event in a taxonomy, getting the correct date range, finding the property that most explains the variance in a chart. These evals are all based on real customer queries. We grade answers on correctness only. We measure cost and latency separately. Here’s where each new model landed (one run each so±2%): -Claude Opus 5.5: 83% correct at $0.70 per question. That's about 2 points behind our top score (GPT-6 Astra) at roughly a sixth of the cost. -GPT-6 Sol: 81% at $0.58. It scored a little lower than GPT-5.6 Sol, but was considerably cheaper (less than half the price). This is the cheapest model we've tested that clears 80%. -GPT-6 Luna: 76% at under $0.04, making it the cheapest model on the frontier. It's about 3x cheaper than GPT-5.6 Luna and achieves about the same score. The tradeoff is speed: its p95 latency was ~400 seconds, about 3x slower than Opus 5.5. Even with the inclusion of these new releases, GPT-6 Astra still gets the top score (84%) on our eval. The tradeoff is it costs $4 per question and was one of the slowest models we tested (900 seconds at p95).