Cekura 发布语音到语音模型基准测试
Cekura 用同一电话代理、82 个场景、2214 通真实通话对比 8 个实时语音模型,GPT Realtime 2.1 最稳,Phonic v1 响应最快。
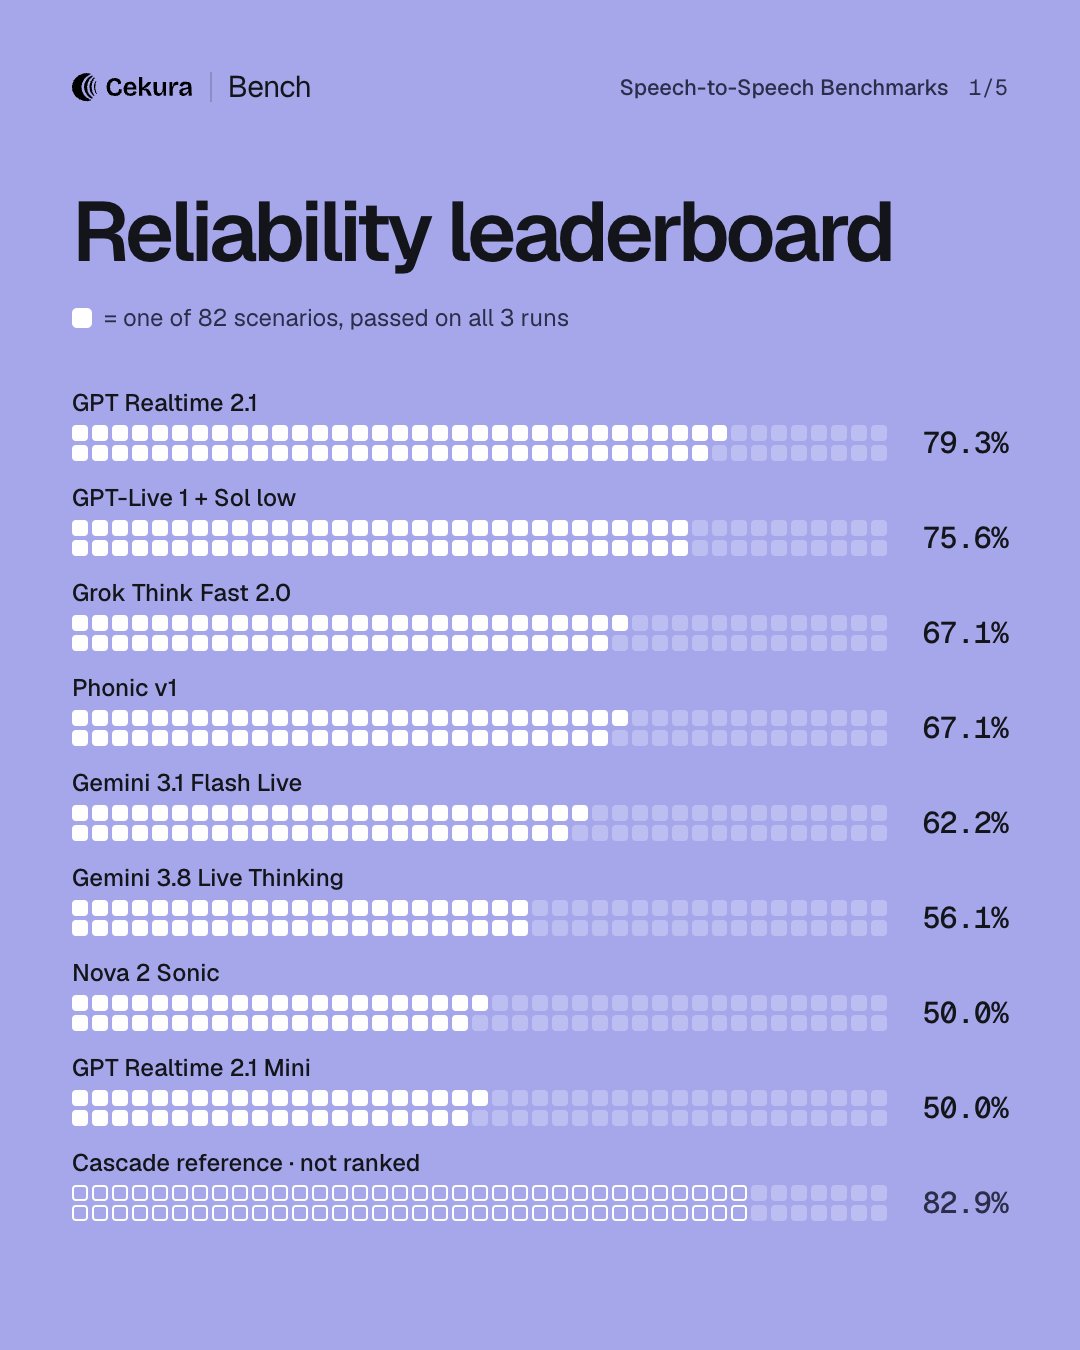
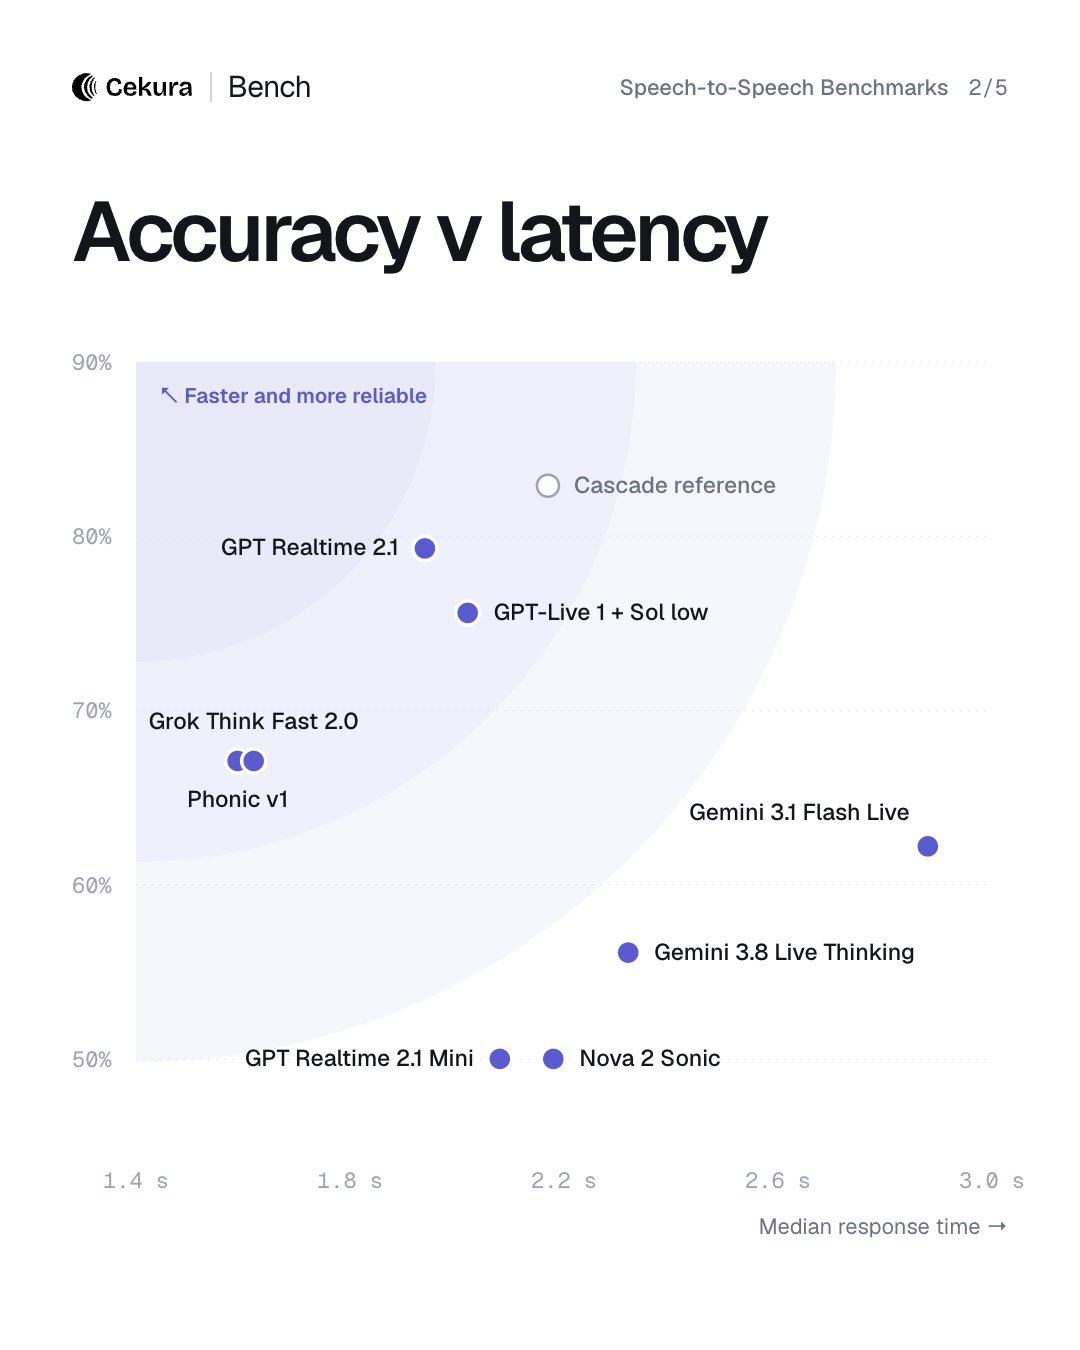
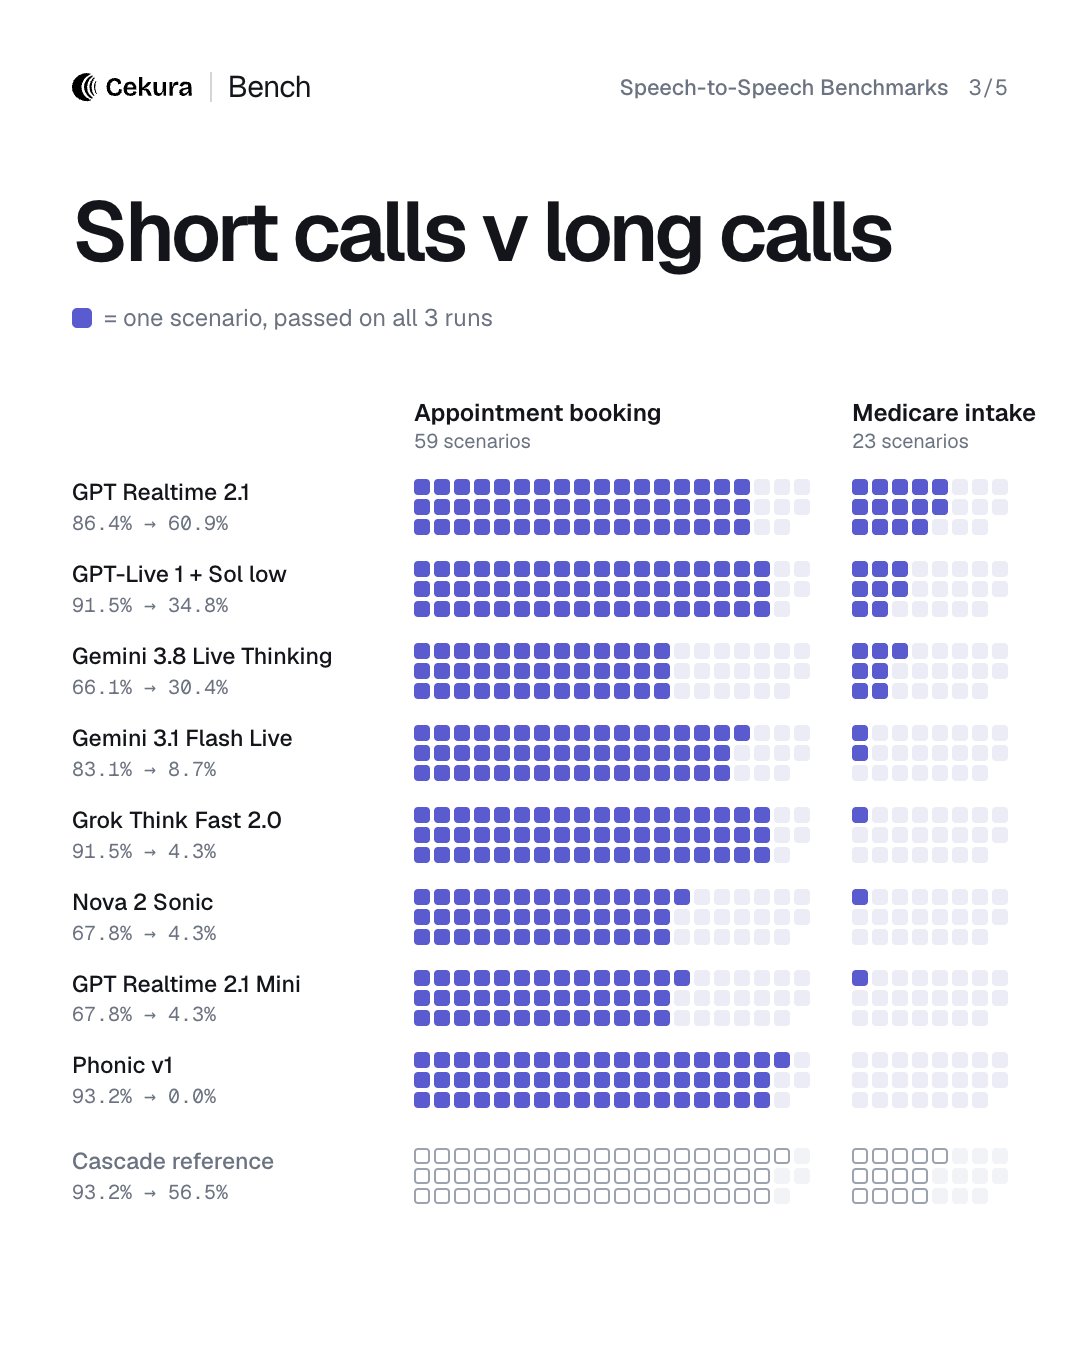
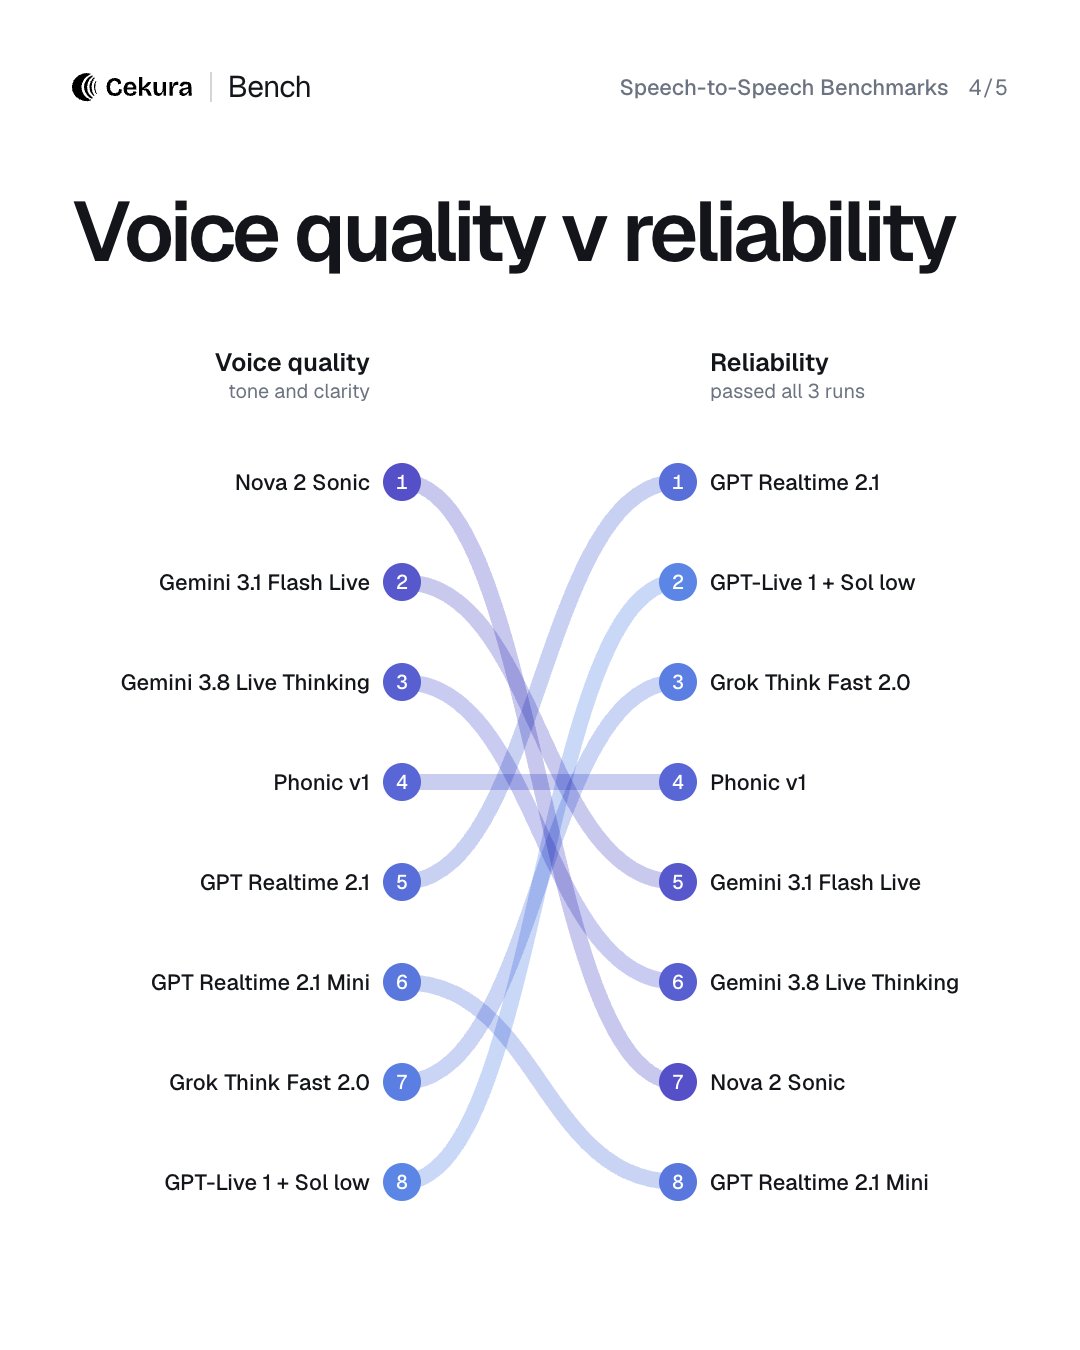
We’ve launched @cekuraAi's speech-to-speech benchmark, comparing eight realtime voice models across 82 scenarios and 2,214 live calls. We tested models from @OpenAI, @Google, @xai, @amazon and @phonic_co. Every model ran on the same phone agent, with the same prompt, tools and phone line. We also tested a cascade agent as a separate reference. The calls covered two workflows: booking a clinic appointment and completing a longer Medicare intake. We ran each scenario three times and counted it as reliable only if the agent passed every time. It had to reach the right outcome and save the right information. A few results stood out: 1. GPT Realtime 2.1 was the most reliable realtime model, passing 65 of 82 scenarios on all three runs. The separate cascade reference passed 68. 2. Phonic v1 was the fastest to respond, with a median response time of 1.59 seconds. 3. The type of call made a big difference. Five of the eight realtime models passed at least 85% of the shorter appointment scenarios. Only GPT Realtime 2.1 passed more than half of the longer Medicare scenarios on all three runs. 4. Amazon Nova 2 Sonic had the highest voice-quality score, but passed only 41 of 82 scenarios on all three runs. An agent can sound good while still missing a name or saving the wrong phone number. We’ve published the results, methodology and call records so you can explore the comparisons yourself. Take a look at the full benchmark here: https://benchmarks.cekura.ai/speech-to-speech