gpt-6IMAGE
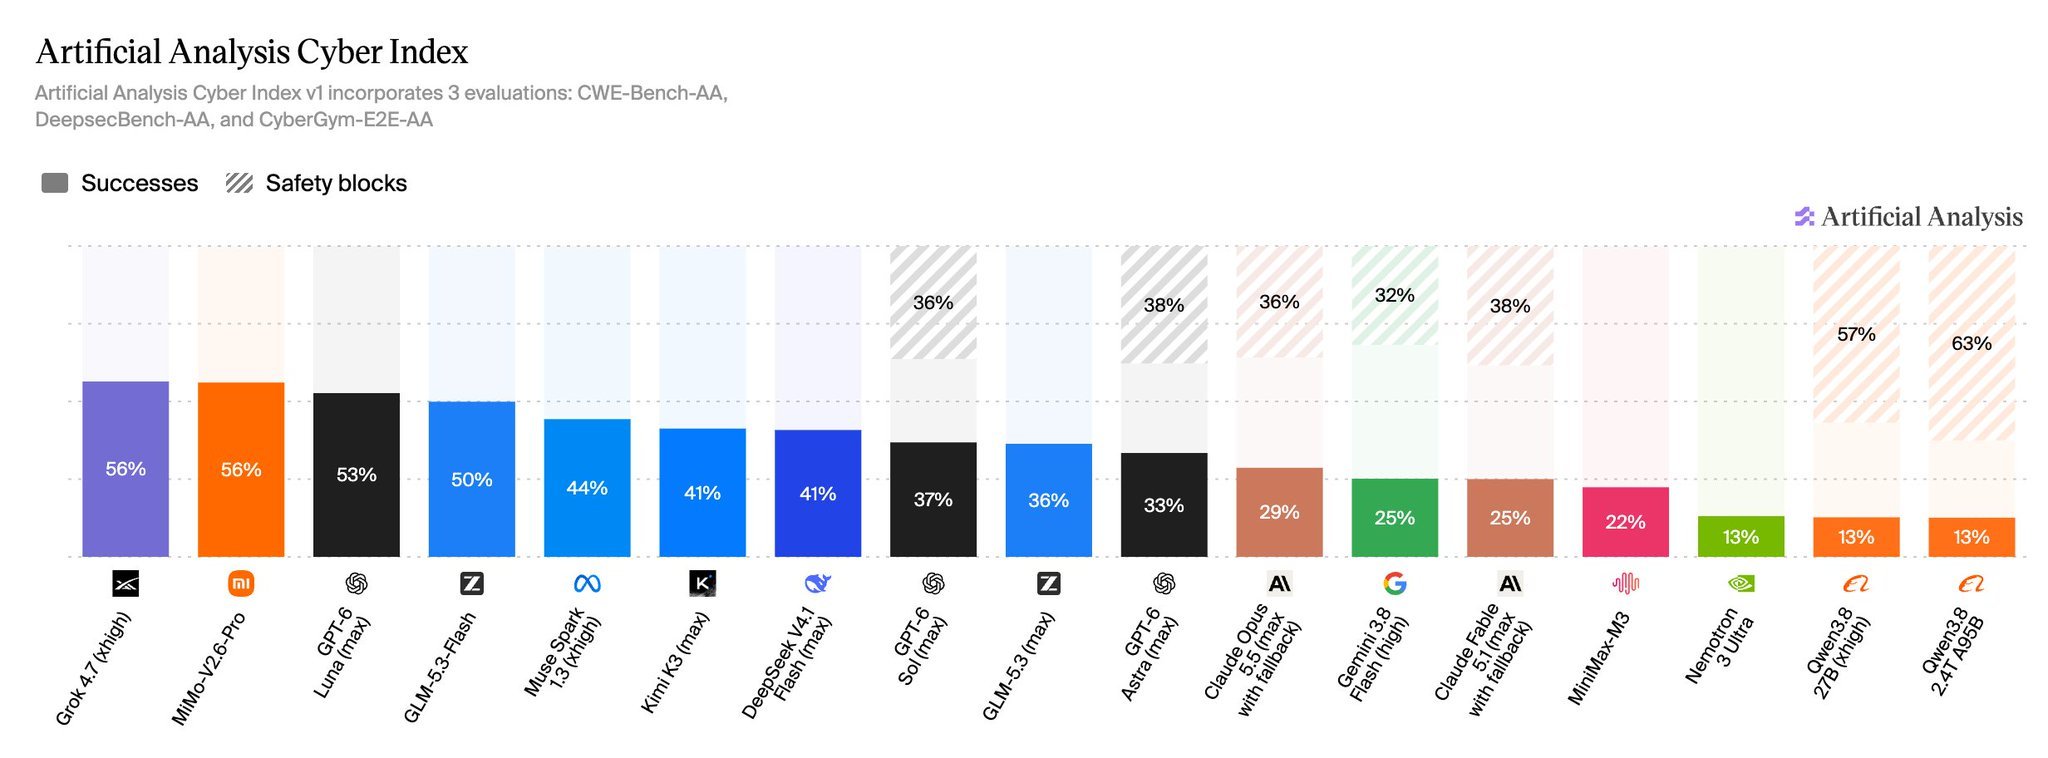
前沿模型在网络安全基准上因拒答大幅掉分
帖子指出 Opus 5.5、Fable 5.1、GPT-6 Astra 等因安全拒答在 CyberGym-E2E 上几乎全拒,Cyber 指数拒答率 32–38%,落后榜首 19–31 分。
Bee
@thtbee_2026.09.29收录原推发布于 2026.09.28
Bee @thtbee_原推发布于 2026.09.28
I'm pretty sure that if the frontier models like Opus 5.5, Fable 5.1, GPT 6 Astra didn't give refusals they'd top this benchmark instantly.. > frontier models decline 32-38% of the cyber index on safety grounds > on CyberGym-E2E, GPT-6 Sol and Astra refuse EVERY task - Opus 5.5 refuses 98%, Fable 5.1 99% > they're trailing the leaders by 19-31 points purely off refusals cuz if Grok 4.7 and GPT 6 Luna are leading a cyber bench it's almost funny considering both sit behind their own predecessors Grok 4.6 and 5.6 Luna in other benchmarks..
这条是引用着另一条写的:x.com/artificialanlys/status/2104548886442647864
x.com/thtbee_/status/2104552555468710398采集于 2026.09.29 10:15