AI 产品更新 · @ViC305
🚀 𝗧𝗪𝗢 𝗠𝗢𝗗𝗘𝗟𝗦 𝗢𝗡𝗘 𝗦𝗣𝗔𝗥𝗞! One main frontier level agent running Qwen3.8-Flash Next. Up to eight concurrent sub agents running MiniCPM-V 4.7 35B-A3B. A shared 1M-
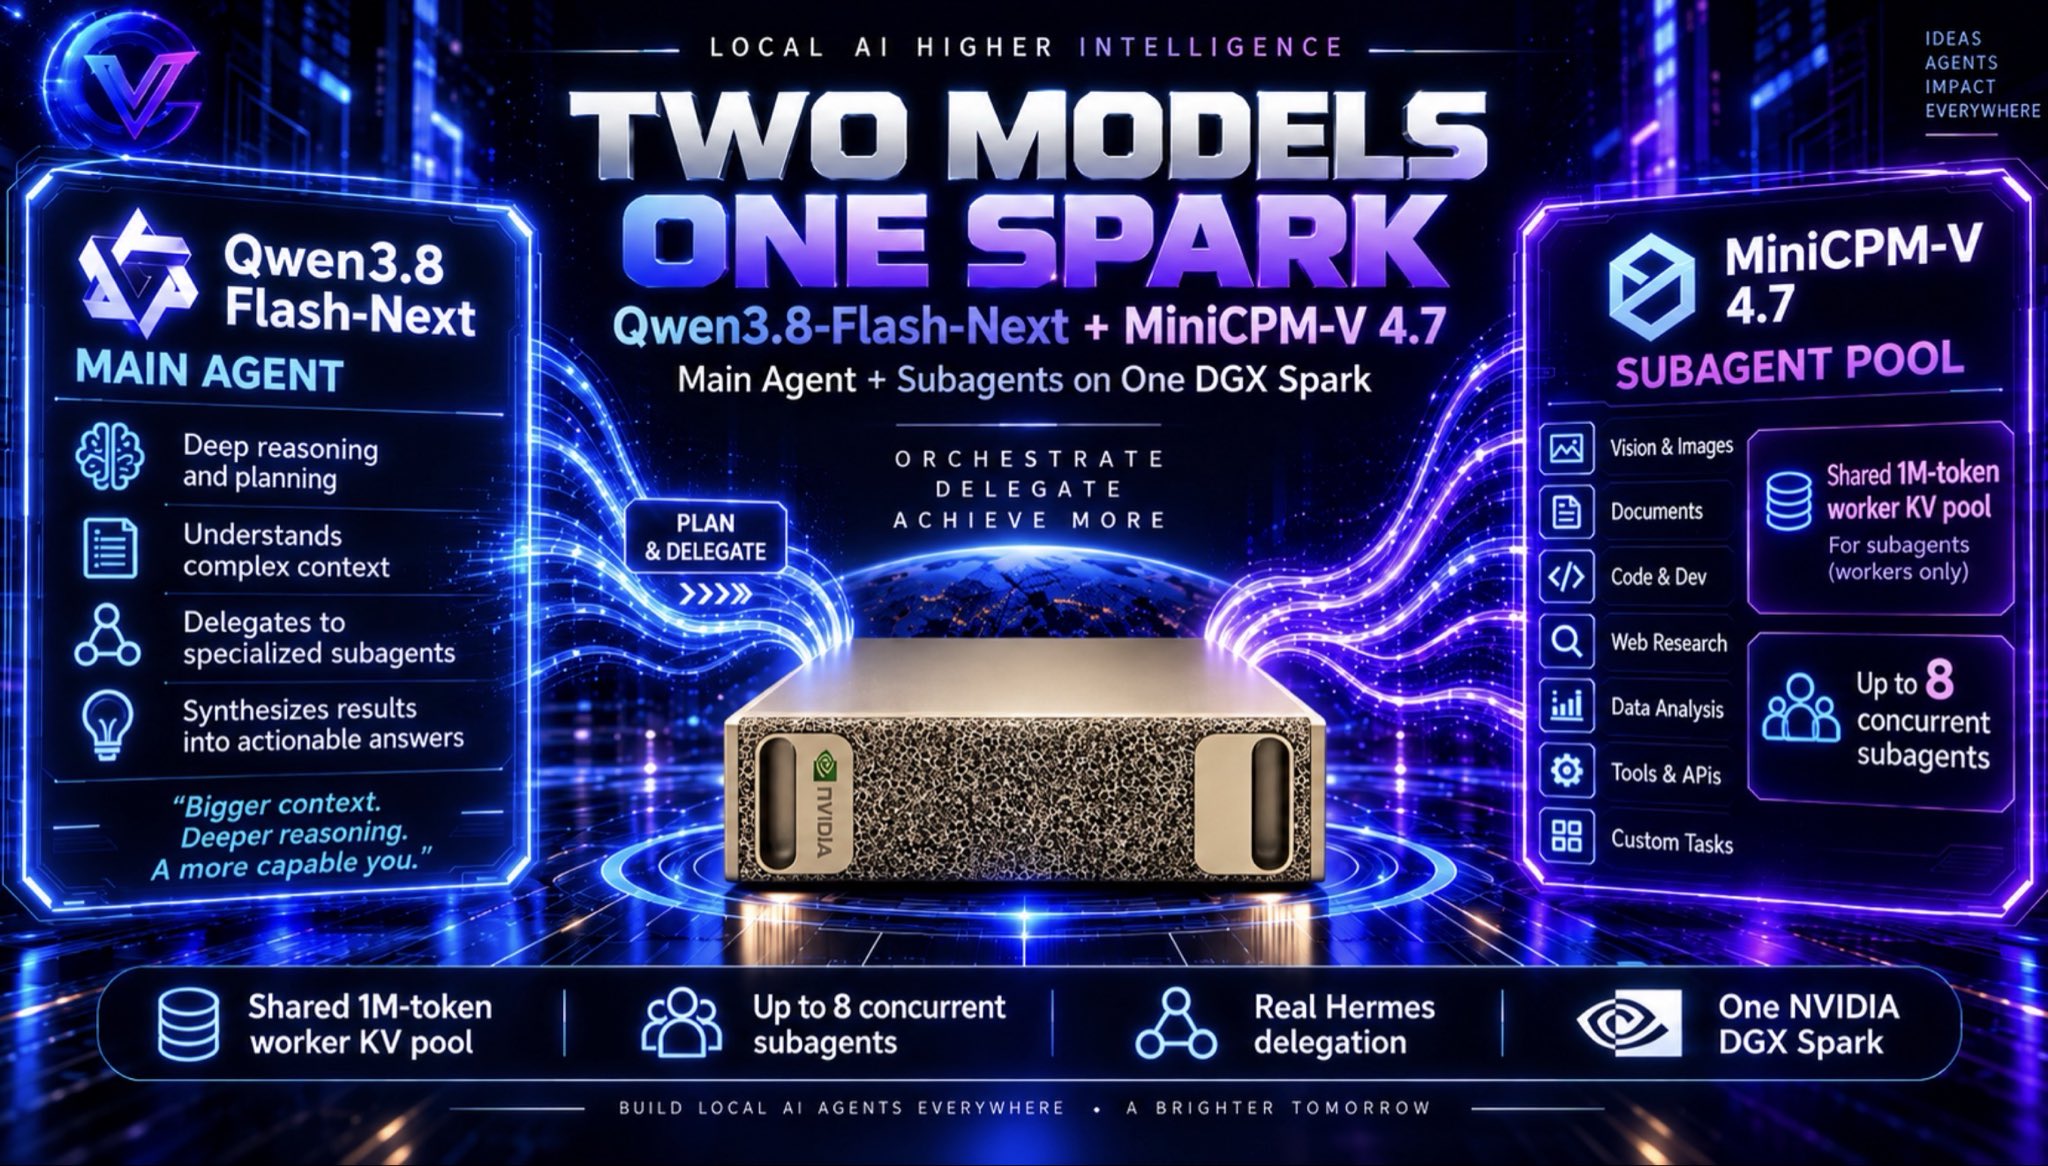
🚀 𝗧𝗪𝗢 𝗠𝗢𝗗𝗘𝗟𝗦 𝗢𝗡𝗘 𝗦𝗣𝗔𝗥𝗞! One main frontier level agent running Qwen3.8-Flash Next. Up to eight concurrent sub agents running MiniCPM-V 4.7 35B-A3B. A shared 1M-token worker KV pool. All on ONE NVIDIA DGX Spark. 🔥 I’m launching a new recipe series built around a different question: Not just “What’s the biggest model I can fit?” But “How much useful work can this machine actually do?” Not two unrelated chat windows. Two models working together, with real delegation, tool use and measured results. 🧠 𝗠𝗘𝗘𝗧 𝗧𝗛𝗘 𝗧𝗘𝗔𝗠 Qwen3.8-Flash-Next EXL3 • 3.05 bpw The main agent: owns the conversation, delegates tasks and brings the results together. MiniCPM-V 4.7 35B-A3B SAGE EXL3 • 3.74 bpw The worker model: serves the delegated subagents. ExLlamaV3 + Hermes Agent. One GB10. 128 GB unified memory. Both models stay loaded. No second Spark. No cloud model endpoint. No swapping models for each task. 🧮 𝗢𝗡𝗘 𝗠𝗜𝗟𝗟𝗜𝗢𝗡 𝗧𝗢𝗞𝗘𝗡𝗦 𝗙𝗢𝗥 𝗧𝗛𝗘 𝗪𝗢𝗥𝗞𝗘𝗥𝗦 MiniCPM has a shared Q4 KV pool of 1,048,576 tokens, with the Hermes profile allowing: 8 concurrent workers × 131,072-token context limits. One loaded worker model, NOT eight copies. Separate conversation contexts sharing a cache budget, NOT a shared conversation or 1M tokens per worker. Qwen keeps its own separate 262,144-token Q8 KV cache. Additional tasks queue in Hermes. Full worker-pool saturation testing is still ahead. ✅ 𝗥𝗘𝗔𝗟 𝗗𝗘𝗟𝗘𝗚𝗔𝗧𝗜𝗢𝗡. 𝗖𝗛𝗘𝗖𝗞𝗘𝗗 𝗥𝗘𝗦𝗨𝗟𝗧𝗦. Qwen delegated file-reading and calculation tasks. Workers used tools, returned their answers and Qwen assembled the result. 4 tasks: 4/4 correct in ~92s. 8 tasks: 8/8 correct in ~123s. 12 tasks: 12/12 correct in ~218s. 16 tasks: 16/16 correct in ~321s. Routing audit: 44 subagent sessions on MiniCPM, five parent sessions on Qwen. ZERO cross-routed sessions. Both models passed streaming and non-streaming tool-calling checks. ⚡ 𝗕𝗢𝗧𝗛 𝗟𝗢𝗔𝗗𝗘𝗗. 𝗕𝗢𝗧𝗛 𝗪𝗢𝗥𝗞𝗜𝗡𝗚. Other model loaded but idle: Qwen: 88.6 tok/s code / 55.9 prose. MiniCPM: ~69.8 tok/s. Both actively generating code: Qwen: 35.3 tok/s. MiniCPM: 40.0 tok/s. Those are concurrent measurements, not standalone numbers added together. In the heavier eight-worker synthetic test with ~7.2K-token prompts and tool schemas, Qwen maintained 26.2 tok/s while MiniCPM delivered 25.8 tok/s aggregate, measured end-to-end. 🛠️ 𝗛𝗢𝗪 𝗜𝗧 𝗙𝗜𝗧𝗦 Qwen’s ~31 GB n-gram embedding table streams from NVMe, freeing RAM for MiniCPM and its worker cache. This is NOT cold-expert offloading. More than 20 GB of available memory remained in the heaviest measured run. 128K retrieval checks passed on each model with the other loaded, plus simultaneous 64K checks on both. Cold 128K first-token latency was ~206s for Qwen and ~90s for MiniCPM. 📦 𝗧𝗛𝗘 𝗥𝗘𝗖𝗜𝗣𝗘 𝗜𝗦 𝗟𝗜𝗩𝗘 Setup, downloads, coordinated startup/shutdown, memory guards, a separate Hermes profile, tests and measured results. 🙏 Credit: @Alibaba_Qwen @QwenDevs @OpenBMB @turboderp_ @NousResearch My contributions: SAGE MiniCPM quantization, recipes, integration and measurements. @NVIDIAAI 💚 We’ve spent a lot of time asking whether one model fits on a Spark. 𝗟𝗲𝘁’𝘀 𝗯𝘂𝗶𝗹𝗱 𝘁𝗵𝗲 𝘁𝗲𝗮𝗺 𝘁𝗵𝗮𝘁 𝗿𝘂𝗻𝘀 𝗼𝗻 𝗶𝘁. ⚡ https://github.com/vcruz305/TWOMODELS-ONESPARK-Qwen3.8-Flash-Next-and-MiniCPM-V-4.7-EXL3