用 Jev 当裁判给 RL 环境打分
把 RL 验证当分类问题,用 Jev 替代 LLM-as-Judge 打分轨迹,验证成本和时间大幅下降。
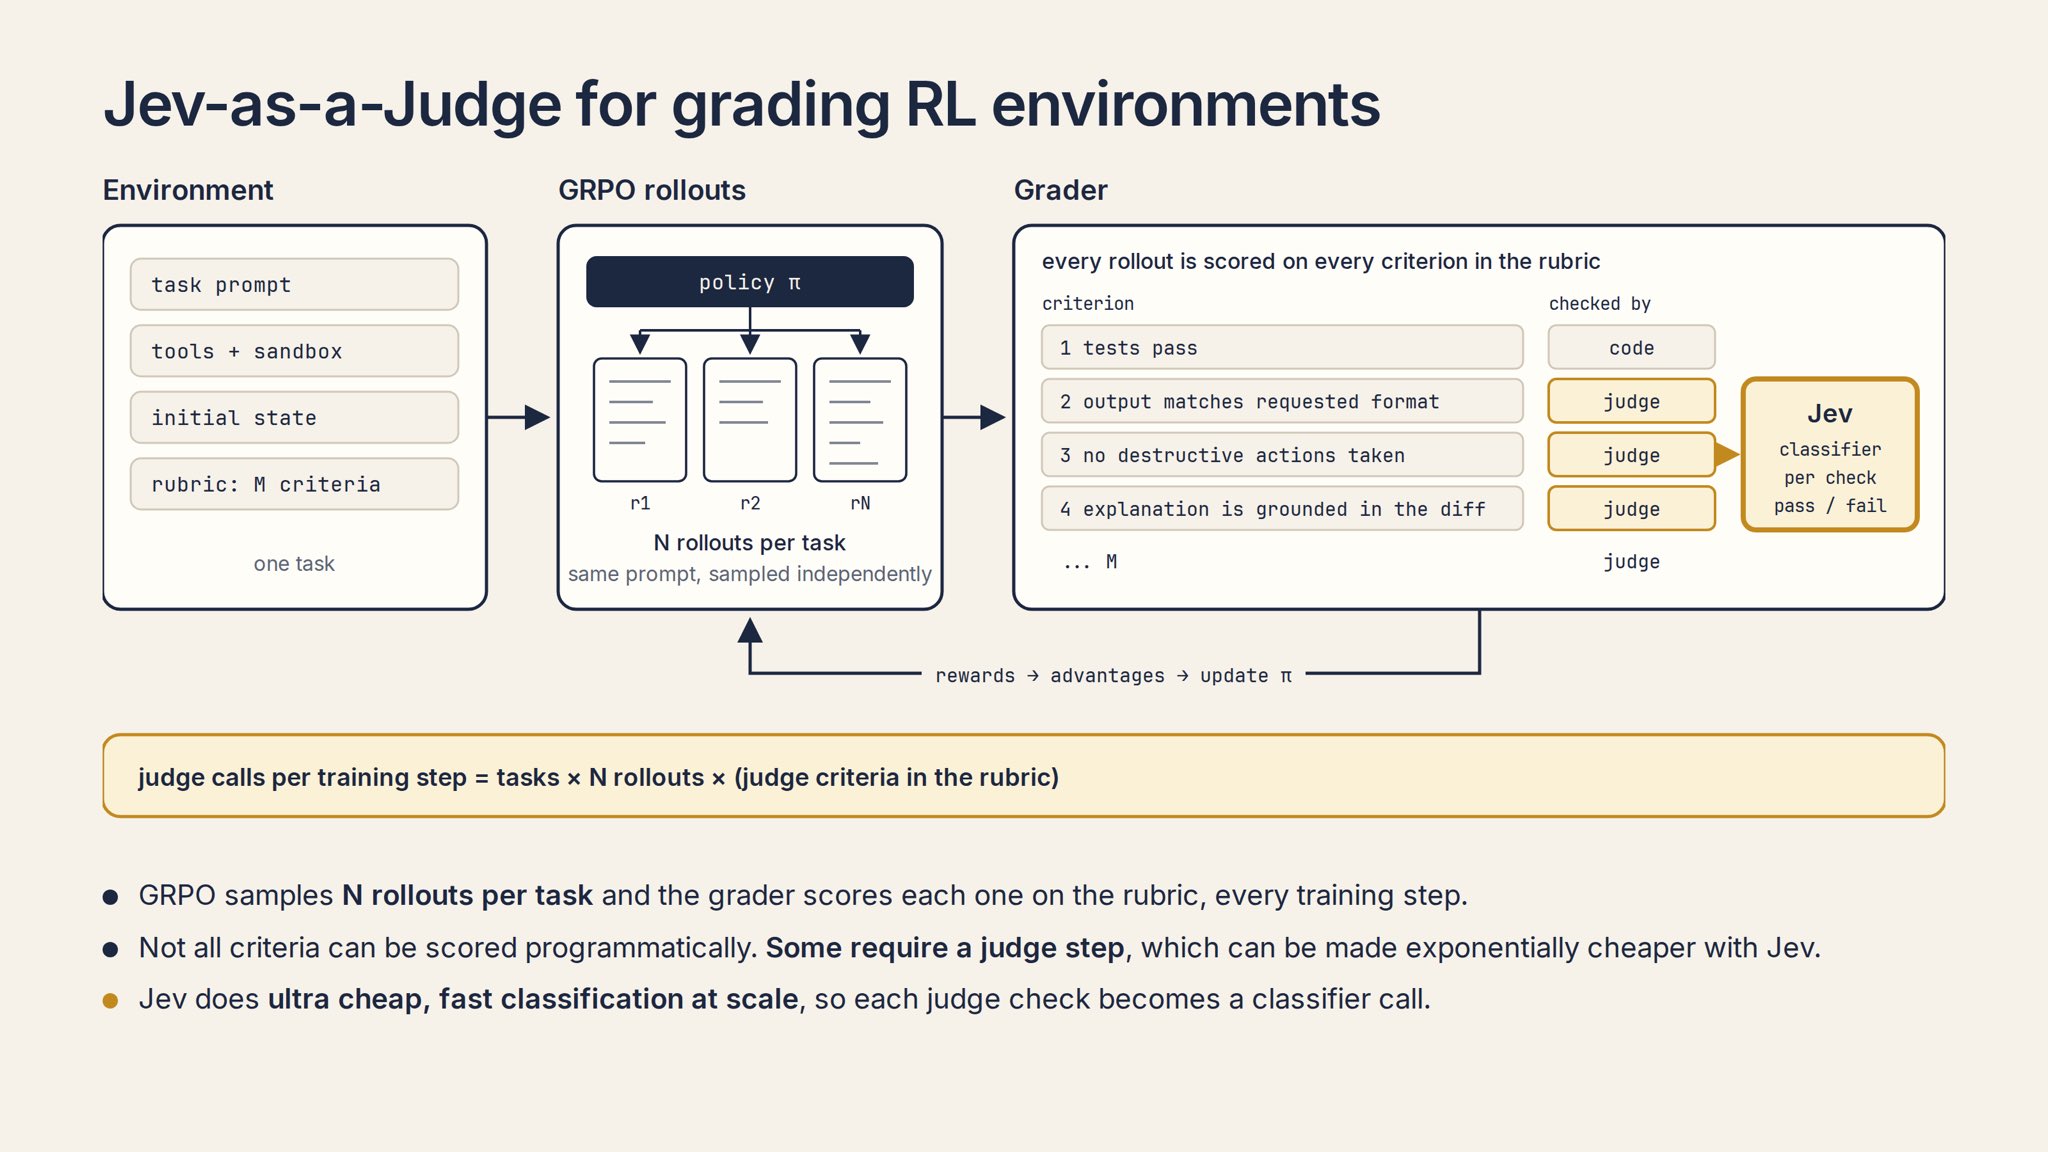
Jev-as-a-judge🤝 RL Environment Verifiers 🤝 way cheaper + faster RL a lot of things in Agent World look like classification problems…including grading RL - many RL Tasks need a judge to verify pieces of outputs or trajectories - at scale this can be very expensive and slow with tons of rollouts to score - Jev is incredibly fast and cheap meaning, can potentially remove the verification bottleneck for many tasks we previously worked with @harvey on their LAB benchmark which used LLM-as-Judge for tens of criteria per task we found that Harness/Prompt Engineering + Open Models meant we could judge tasks orders of magnitude cheaper like any verifier, it needs to be calibrated to make you’re giving back a good signal but Jev has the opportunity to massively bring down verification costs (and tuning friction) for many tasks which means more teams will do RL, which is great!
这条是引用着另一条写的:「LangChain 实测 Jev 对比 LLM 评审」