呼吁 benchmark 标准化:按每任务成本而非 token 价比较
作者列出 Gemini 4 Argon、Opus 5.5、GPT-6 Astra 的输入输出价,认为 Argon 效率突出、多模态值得期待。
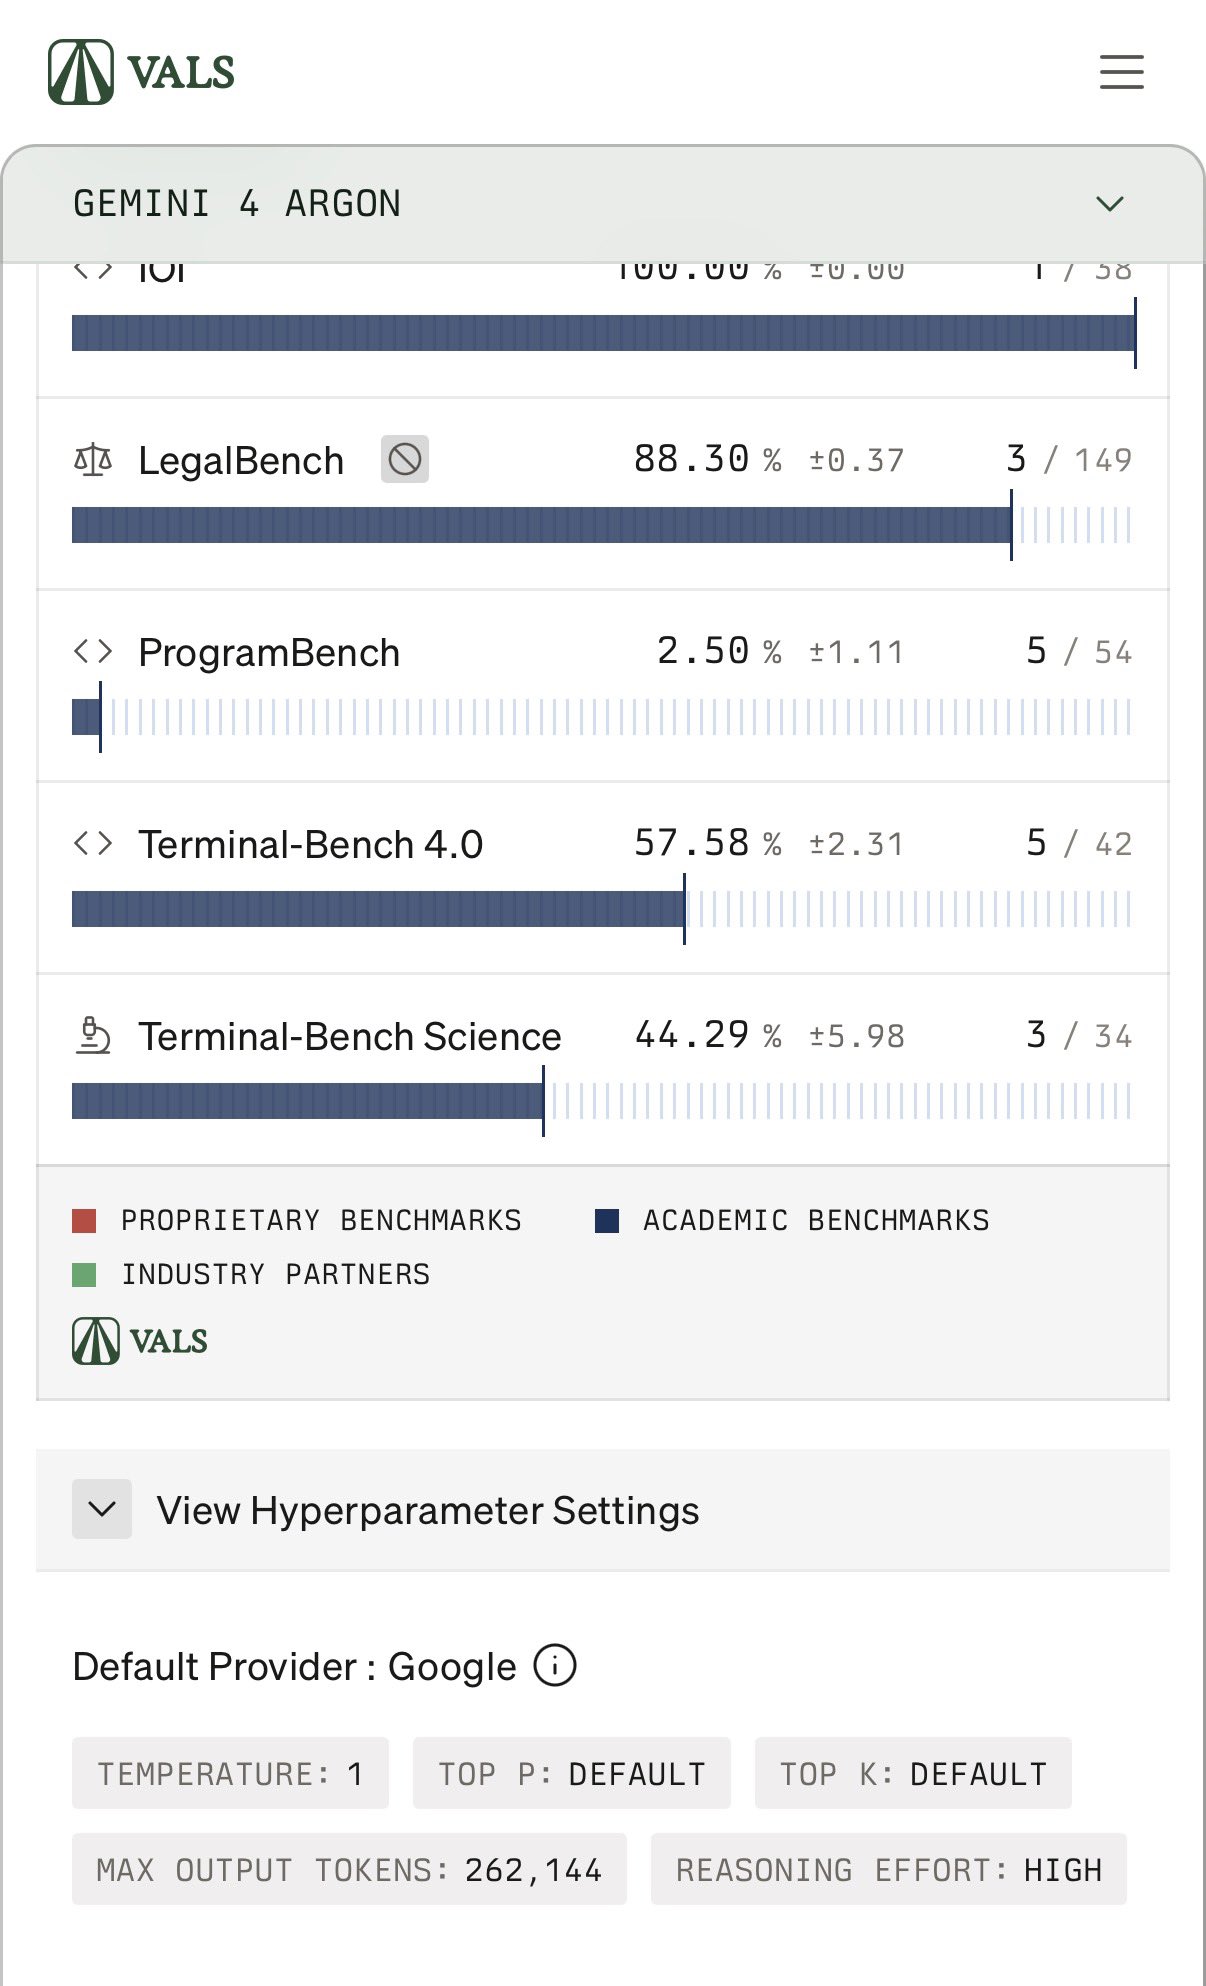
for benchmark scores we should standardize around making it really easy to find details like: - $/Task - Harness - Reasoning level - Infra used (for latency) @ValsAI makes nice reports covering some of these details per individual bench they use, some details vary per bench (like infra limits) the thing ppl actually care about is “how much money do I pay to have this unit of work done” you can’t tell that from Token pricing because the harness and model efficiency wildly affect total cost/speed see: gemini 4 argon: $2 / $10 opus 5.5: $4 / $20 gpt-6 astra: $10 / $50 different models also have varying efficient levels on different domains depending how they were trained Argon looks pretty sick for efficiency 👀 Google also always has great multimodal capabilities, excited to try there once it’s publicly released!
这条是引用着另一条写的:x.com/valsai/status/2105388446844072033