ApprenticeBench:Astra 与 Fable 5.1 拉开差距
新基准强调真实办公场景,Fable 5.1 与 Astra 明显领先,但成本、效率、沟通自然度仍不如人类。
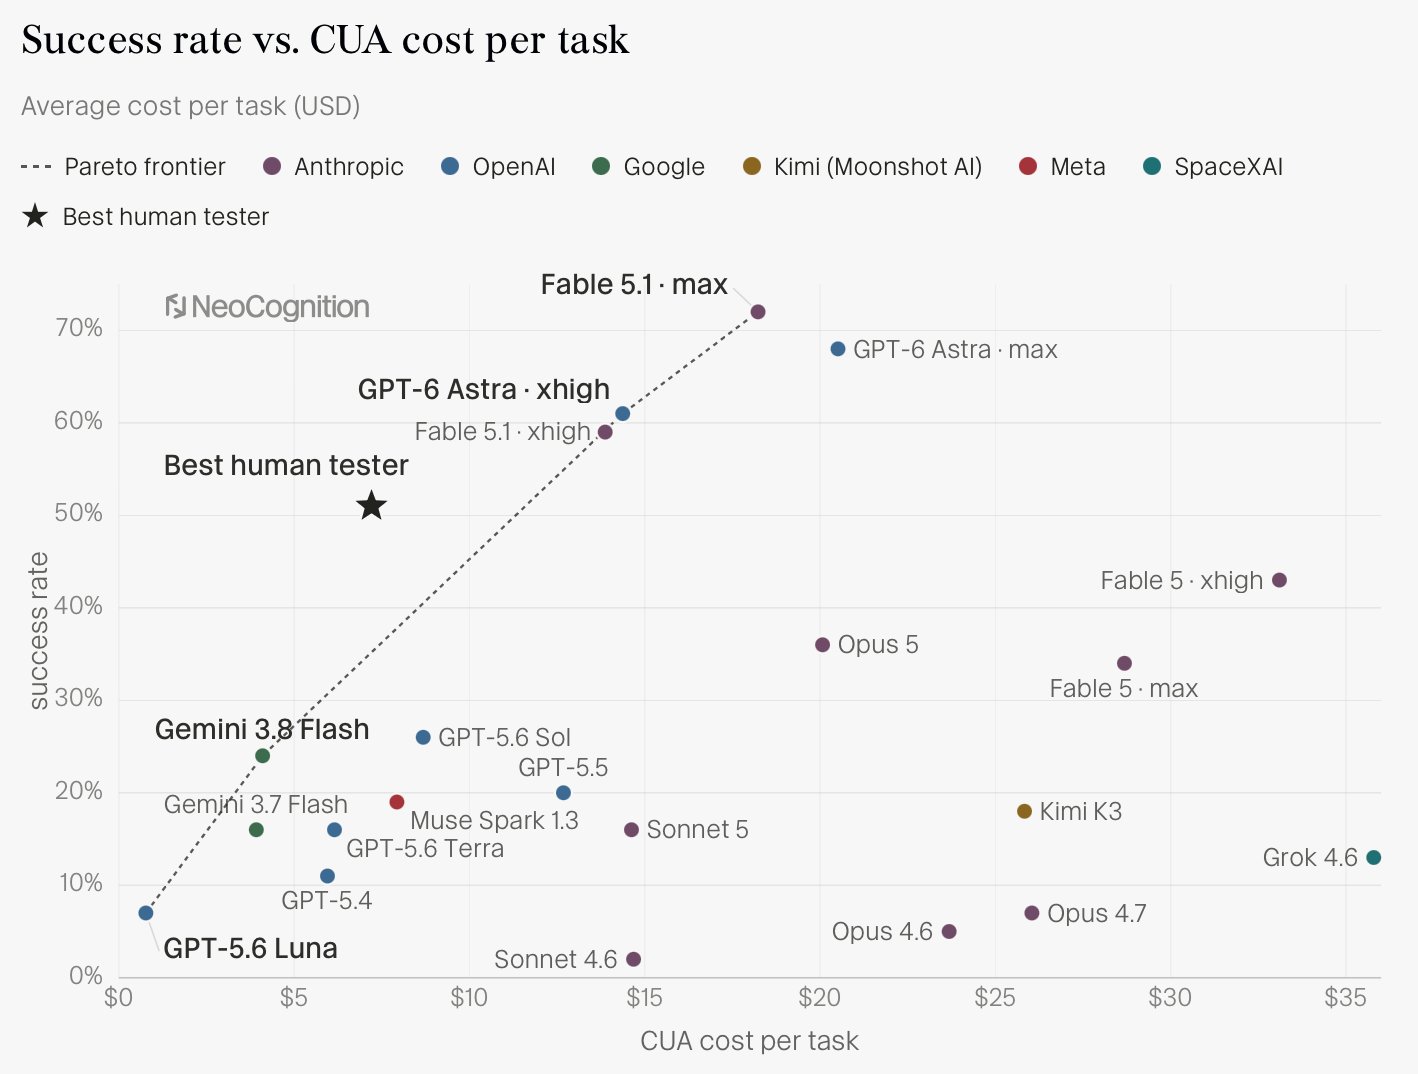
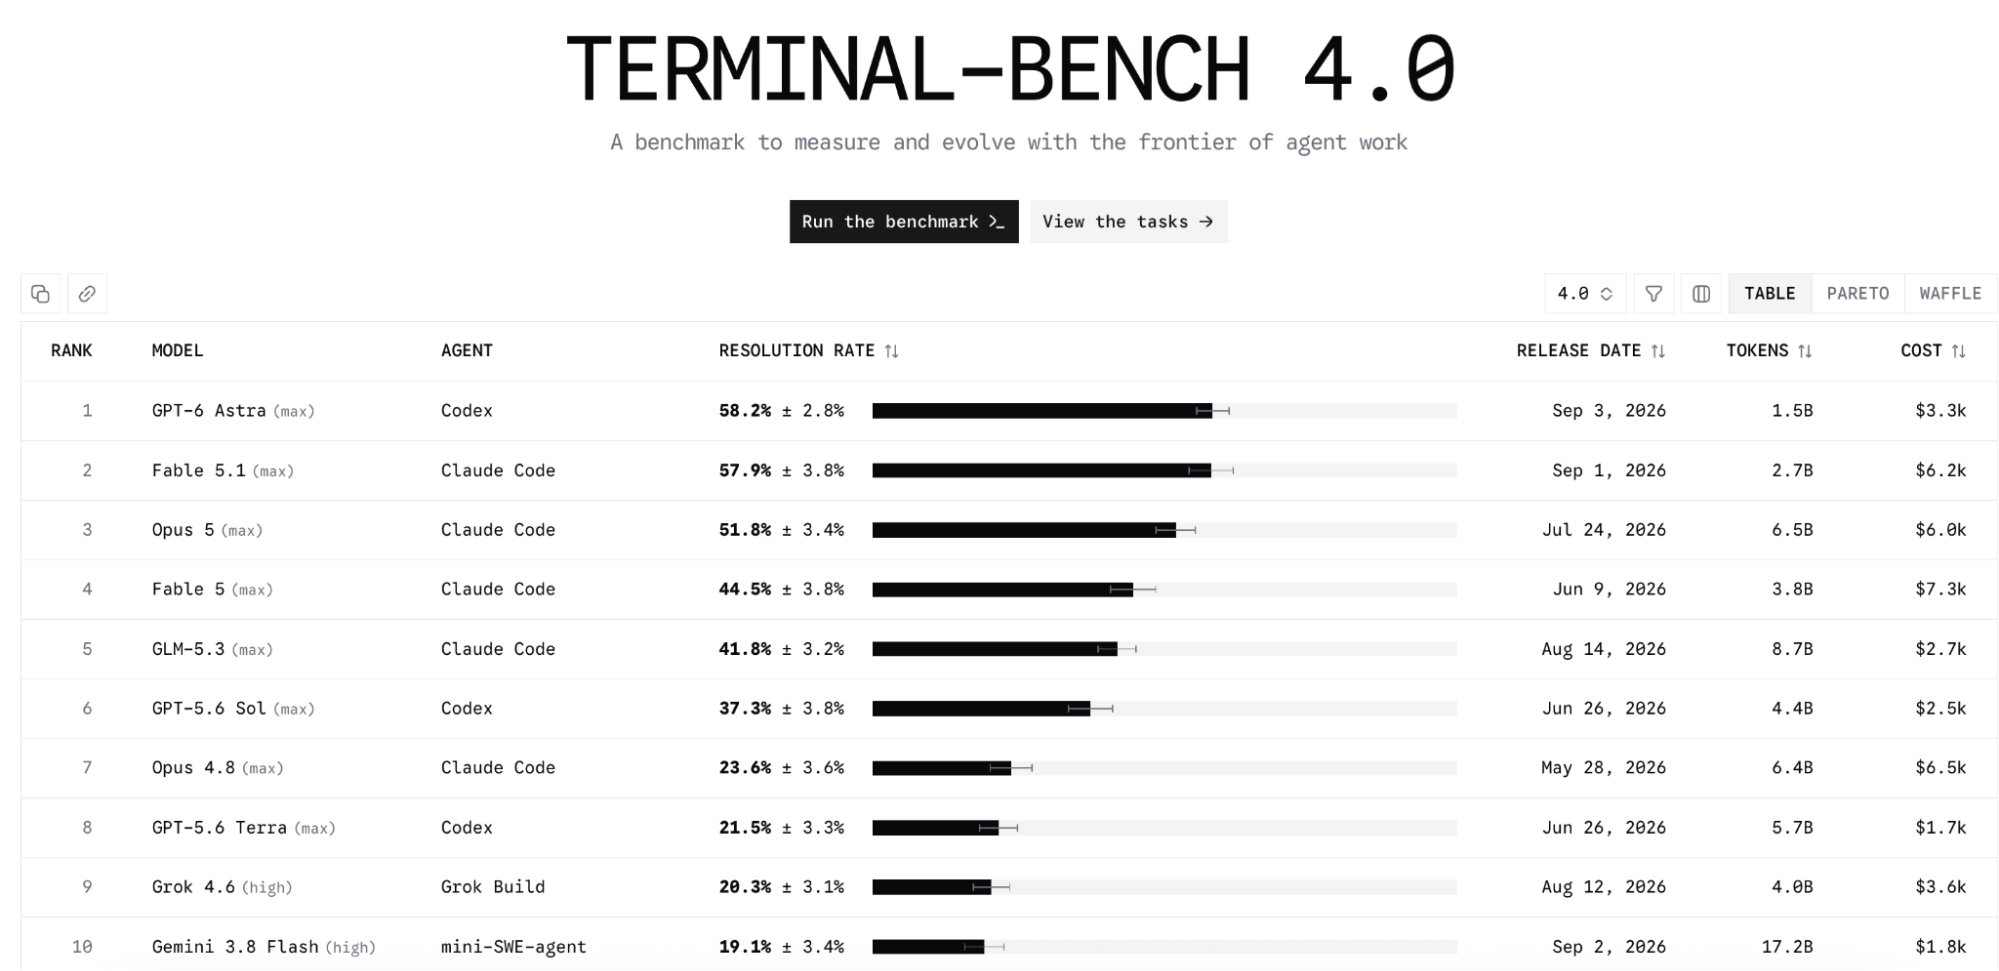
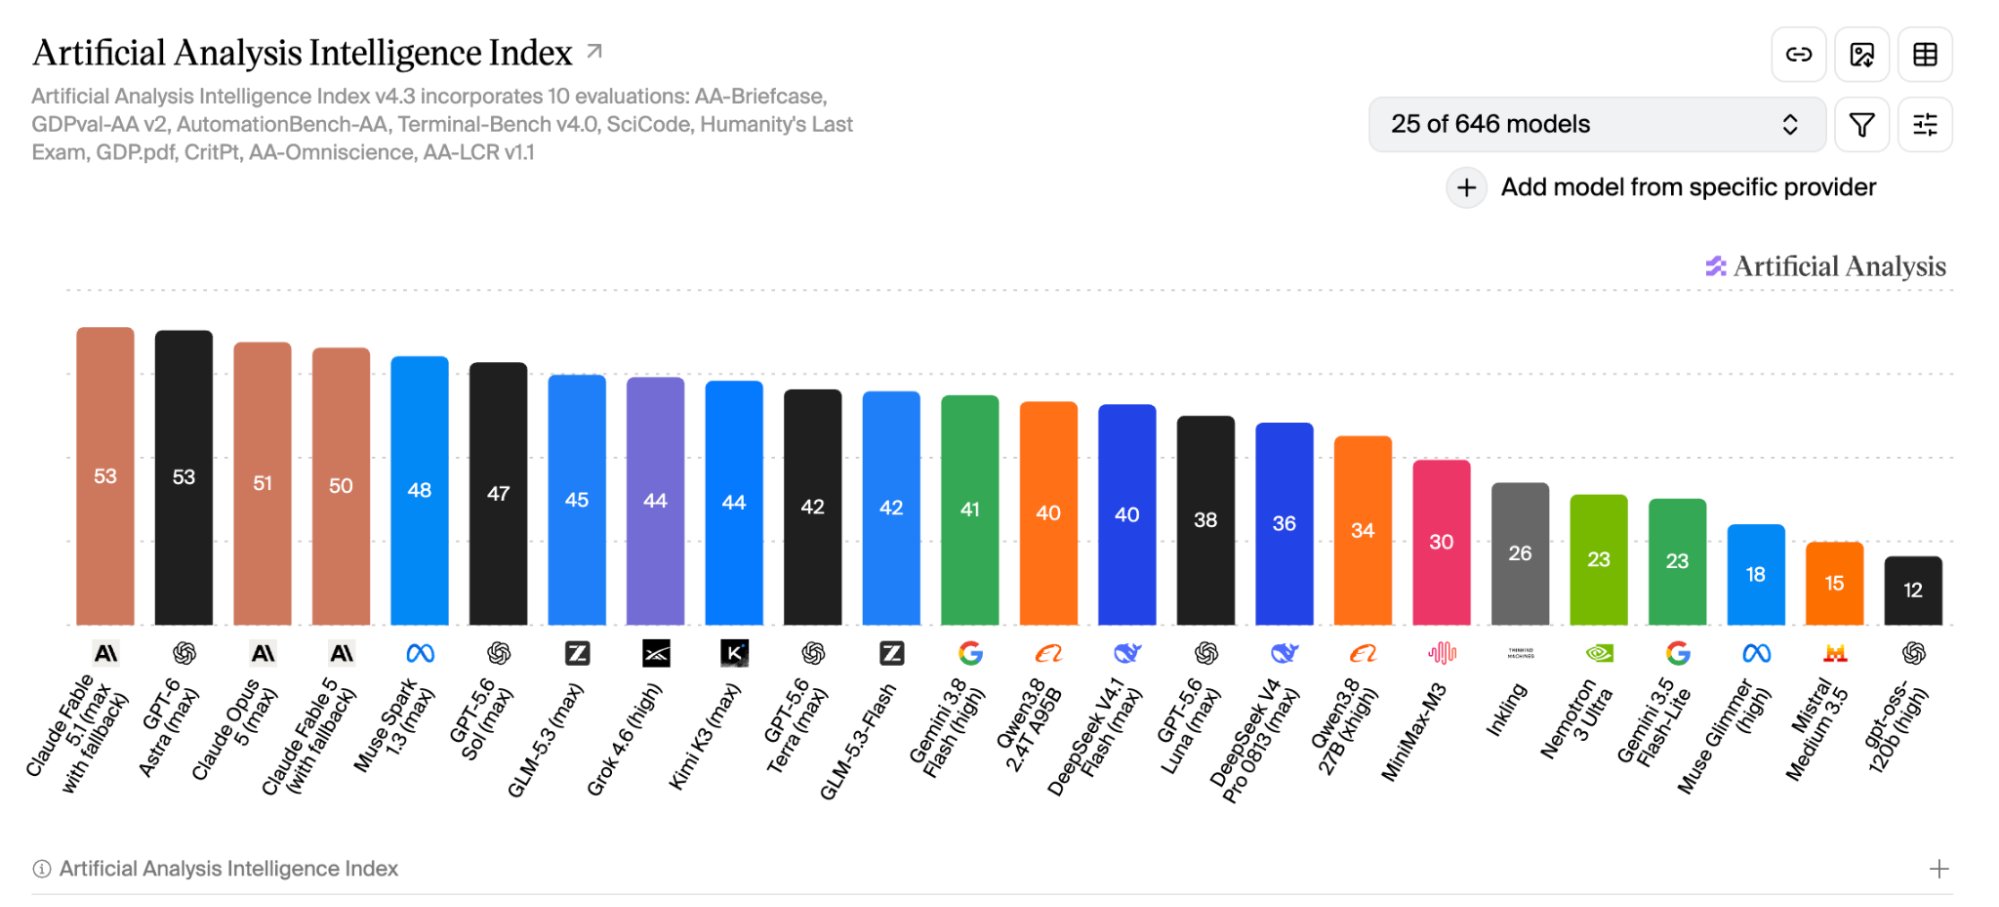
(1/2) ApprenticeBench probably has the strongest differentiation power of any benchmark out there. We’re seeing a step change with Fable 5.1 and GPT-6 Astra. Just look at Fable 5.1 and Opus 5: only a few points apart on AA, Terminal-Bench 4.0, and CursorBench 4.0, but 72% vs. 36% on ours! A major reason behind this is we built ApprenticeBench for ecological validity, i.e., we want it to encode all the challenges that make a job hard for a human employee to do. The agent has to learn company conventions from past bills, adapt to policy changes, and use the software to do the work. Two models can look close on any one of these challenges. However, when putting everything together, small gaps can compound into a big difference in getting the job done. No offense to open-weight models, but this gap is rough. Fable 5.1 and Kimi K3 score 53 and 44 on AA. Here, they get 72% and 18%. For the same 100 bills, it’s 28 to fix versus 82. If you’re the one doing the job, you won’t like the gap :) We also want to highlight that despite the big advantage of Fable 5.1 and GPT-6 Astra, compared with human testers, we also found non-trivial issues of those strong models in terms of cost (agents have 2.5x cost), efficiency (humans generally become faster and faster), and communication naturalness.
这条是引用着另一条写的:「ApprenticeBench:GPT-6 Astra 在真实岗位上持续学习并超越人类」