38 个模型 107 档推理强度写作实测
内部写作基准测试:提高推理强度普遍小幅提分但成本约 2.5 倍;GPT-6 Sol 在 max 档胜过 Astra 且更便宜更快。
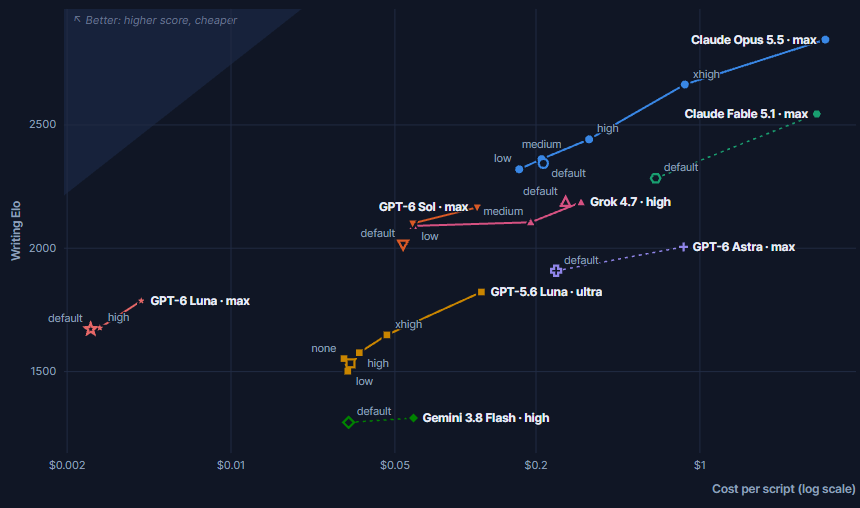
I ran 38 models at 107 reasoning-effort settings, including Opus 5.5, Fable 5.1 and GPT-6 Sol/Astra/Luna, on whether higher effort led to better writing. For coding and math, more effort usually pays off. For writing, I wasn't sure. A YouTube script has no right answer to reason *more* toward. So I tested it on our internal benchmark, where every model writes the same 10 real scripts from my channel, scored blind by three judges and our rubric. Results: ✅ Effort does help. All 11 RECENT models we ran at two or more explicit settings score higher at their top setting than at their lowest. The typical gain is modest though, for about 2.5x the price. (this wasn't the case for models before june this year) ✅ Opus 5.5 benefits the most: #10 at low effort, #1 at max. But max costs 20x more ($3.43 vs $0.17 per script) and takes about 17 minutes. it seems xhigh is the sweet spot: #2 for a quarter of the price of max. ✅ GPT-6 Luna is much more interesting than GPT-5.6 Luna, similar perfs for about 1/30th of the cost, under half a cent per script. ✅ GPT-6 Sol at max (#31) beats GPT-6 Astra at max (#50) for about an eighth of the price and a third of the wait. ✅ Some models don't care: Grok 4.7's default already scores like its high setting, same for Gemini 3.8 Flash. If you (or your agent*) write at volume, don't default to max. Find where the curve flattens for your budget! But if you just want the best script and don't mind the bill or the wait, Opus 5.5 at max is the best writer we've tested yet. It and Opus 5.5 xhigh are the only two configurations that reach my own scripts' score on this rubric.