Momentic 实测 Jev 定位元素:51.8% 准确率、0.35 秒
Momentic CTO 在 Locator Bench 上测 Jev:单用 51.8% 准确率、0.35 秒;加 v5 兜底到 78%,仍低于自家 v5-auto 的 84.6%。
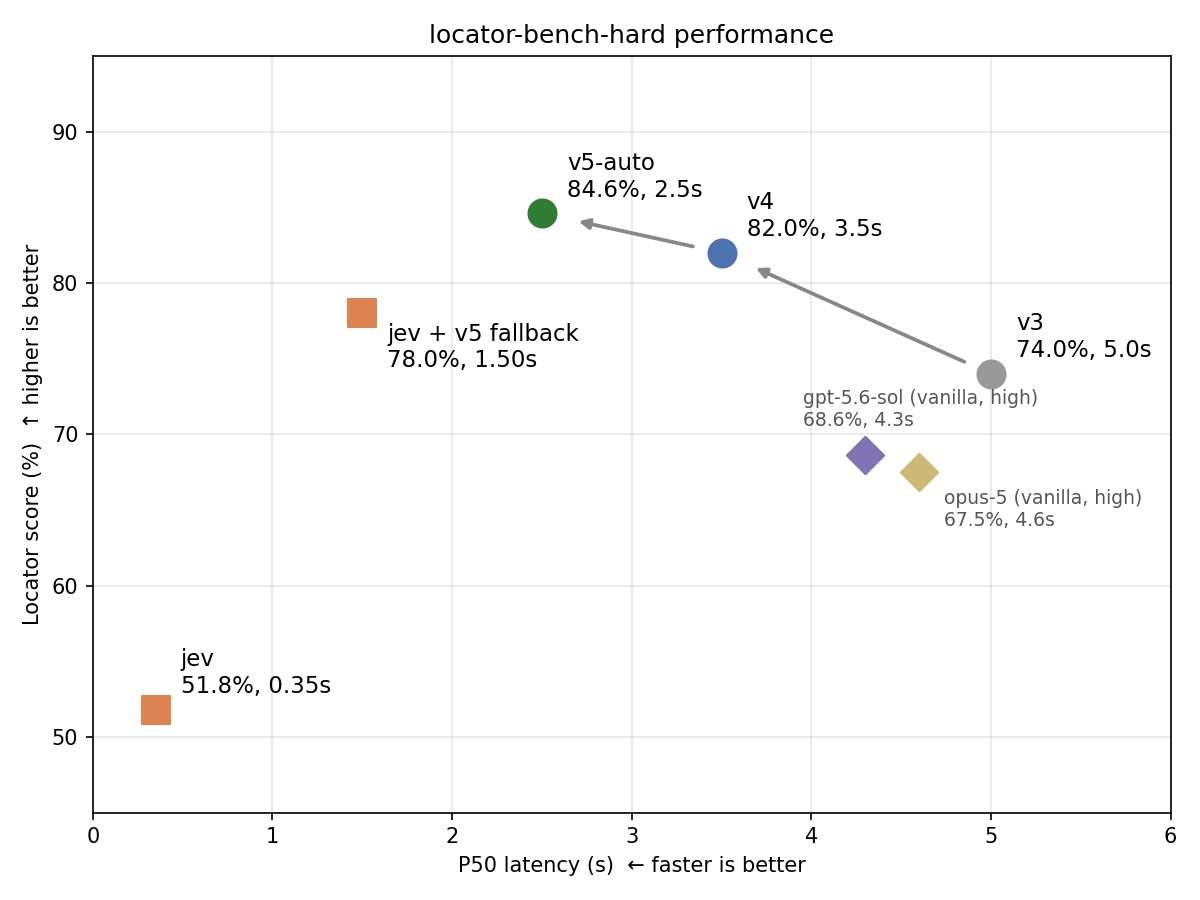
our CTO @itsjeffan tested @TypeSafeAI's Jev on Momentic's hardest locator eval Locator Bench the set requires visual, spatial and logical reasoning to find the element a user describes Jev got it right 51.8% of the time at 0.35s median latency. fast, but below the accuracy our customers need on the same benchmark: - Jev + v5 fallback: 78.0% accuracy at 1.5s median latency - Momentic v5-auto: 84.6% at 2.5s on our separate locator + assertion evals, Jev was 8x faster than Luna, our fast config, at 1/4 the cost accuracy was lower there too the Jev-only prototype was more limited on our broader AI-action eval. it could click and type, but couldn't run JavaScript, do AI checks or extract data. it ran 4x faster per step than Luna, but only completed ~8% of the tasks with Luna handling general tasks and Jev locating elements, completion reached ~24%. that hybrid ran 2.8x faster per step than baseline we've already broken general tasks into smaller classification problems for our sub-agents, so i can see Jev being useful there but it can't take images, and even checking whether a page is ready can need visual context it's impressive for a first gen. we'd still need it to meet our accuracy requirements for each task before using it in customer tests if a test keeps failing for the wrong reasons, engineers learn to ignore it that's when it's worse than having no test