jevIMAGE
Jevals:用 Jev 做裁判的 LLM 评测框架
把评测打分从 LLM judge 换成 Jev,每个通过/不通过都带可设阈值的校准置信度,更便宜更快。
Sai Yashwanth
@yashwanthsai292026.09.19收录原推发布于 2026.09.18
Sai Yashwanth @yashwanthsai29原推发布于 2026.09.18
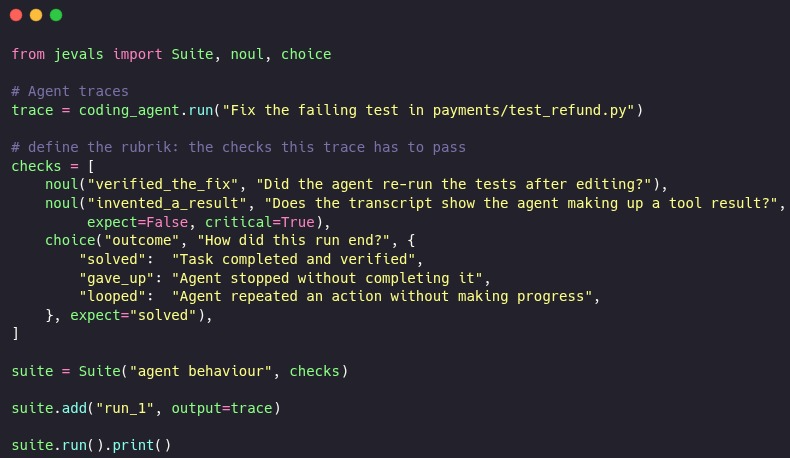
I built Jevals, an evals framework for LLMs and AI agents. Instead of an LLM judge, grading runs on Jev. So every pass/fail comes with a calibrated confidence you can set a bar on. Cheaper and Faster.
这条是引用着另一条写的:「ChatGPT 联合发明人发布新模型 Jev」
x.com/yashwanthsai29/status/2100824939540660357采集于 2026.09.19 10:17