Grok 4.7 实测:自测能力变强但成本高
知乎测评显示 Grok 4.7 逻辑分中位数升至 60.97、幻觉控制进入第一梯队,但单任务常耗 9 万–15 万 token,且偏暴力求解。
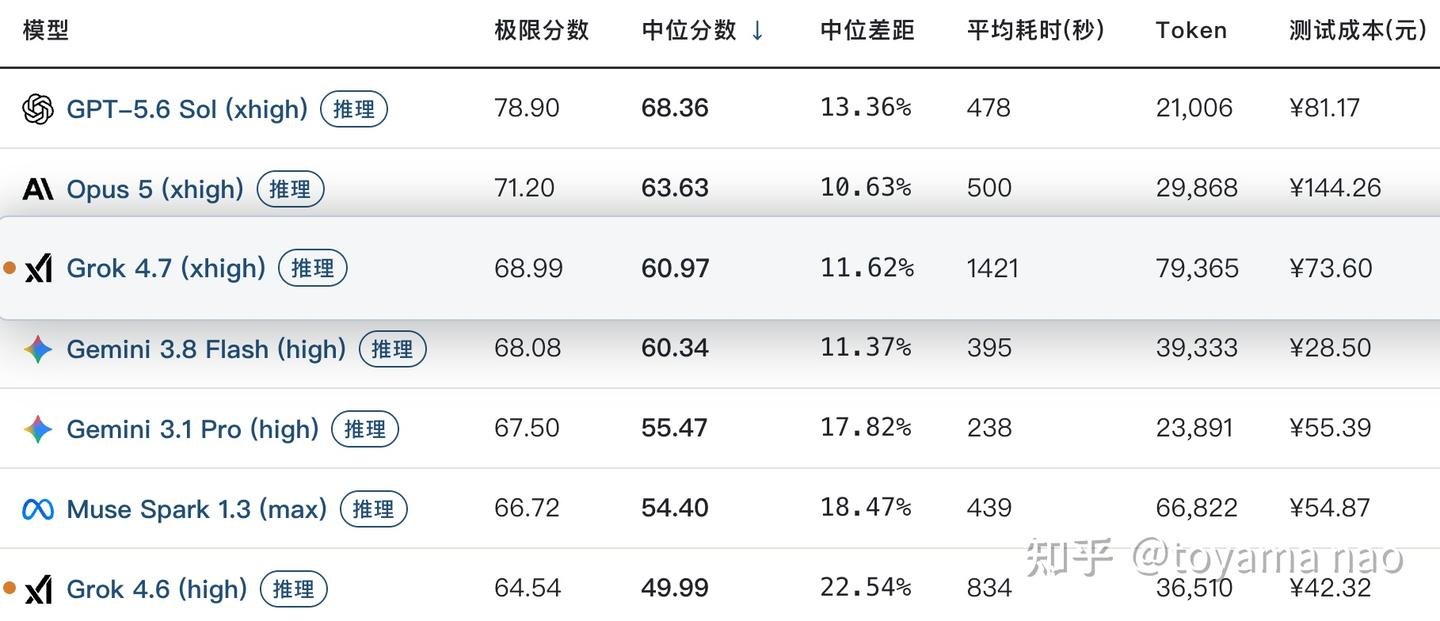
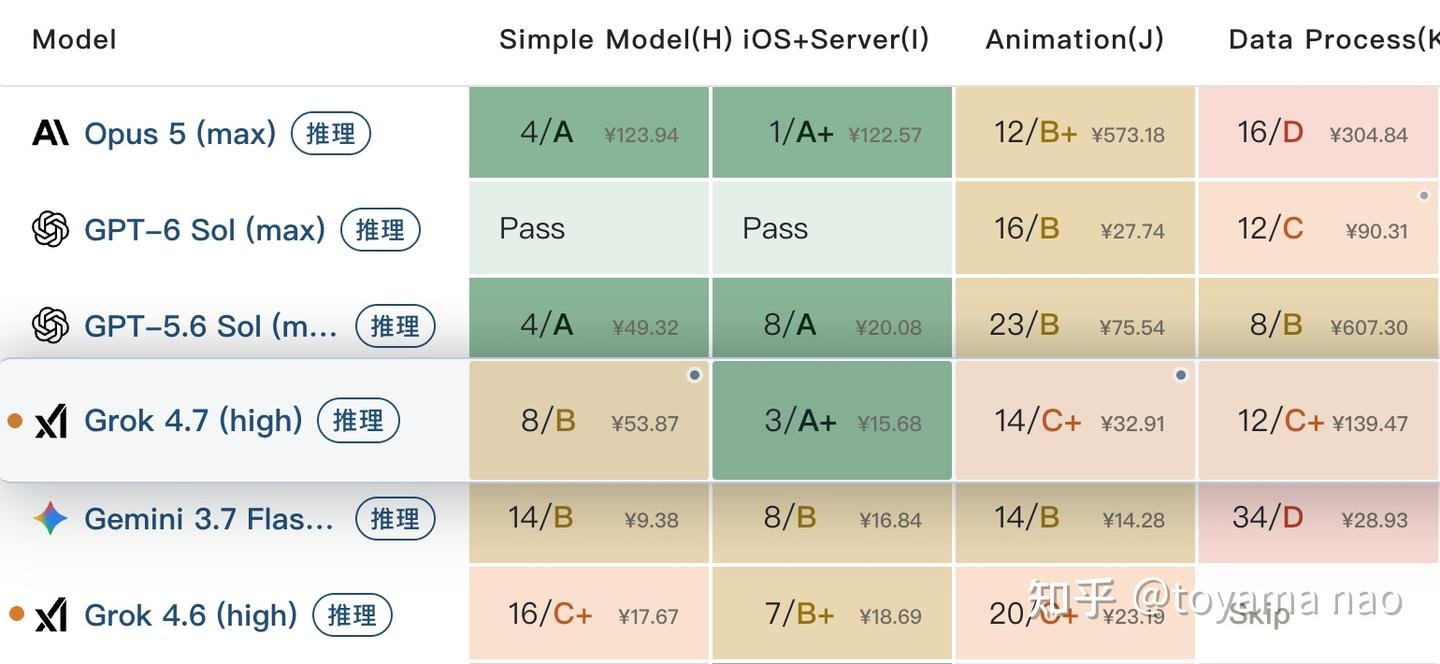
Grok 4.7: Better Self-Testing, but Progress Comes at a Cost Grok 4.7 is closing the gap, but not cheaply. In Zhihu contributor toyama nao's tests, stronger hallucination control came with average token usage of 90K-150K on those tasks. Coding agents that actually test their work Grok has progressed from skipping self-tests in 4.5 to basic compilation checks in 4.6, then simulator use and test-case writing in 4.7. But this improvement does not generalize consistently beyond standard web frontends. Visual design also remains rough compared with peers. Better scores, with a comparison caveat The median logic score rose from 49.99 to 60.97. However, 4.6 was tested at high, while 4.7 used xhigh: this is not a like-for-like reasoning-effort comparison. The author places hallucination control in the top tier, though some complex texts still expose gaps in comprehension and extraction accuracy. More reasoning does not always mean better reasoning Complex multistep tasks showed mixed gains, with no clear efficiency improvement. The author found greater reliance on brute force and weaker performance on problems requiring a clever approach. Their assessment: Grok is becoming a serious challenger, but task cost remains a weakness.