Cat Boss test: M3.1 Flash near-perfect on old questions, near-zero on new ones
On the Zhizhi leaderboard's private question set, M3.1 Flash scored a median 51.76 versus 23.86 for M3 and 56.03 for DeepSeek V4.1 Flash 1017, but nearly aced old questions and nearly failed new ones, raising benchmaxxing suspicions.
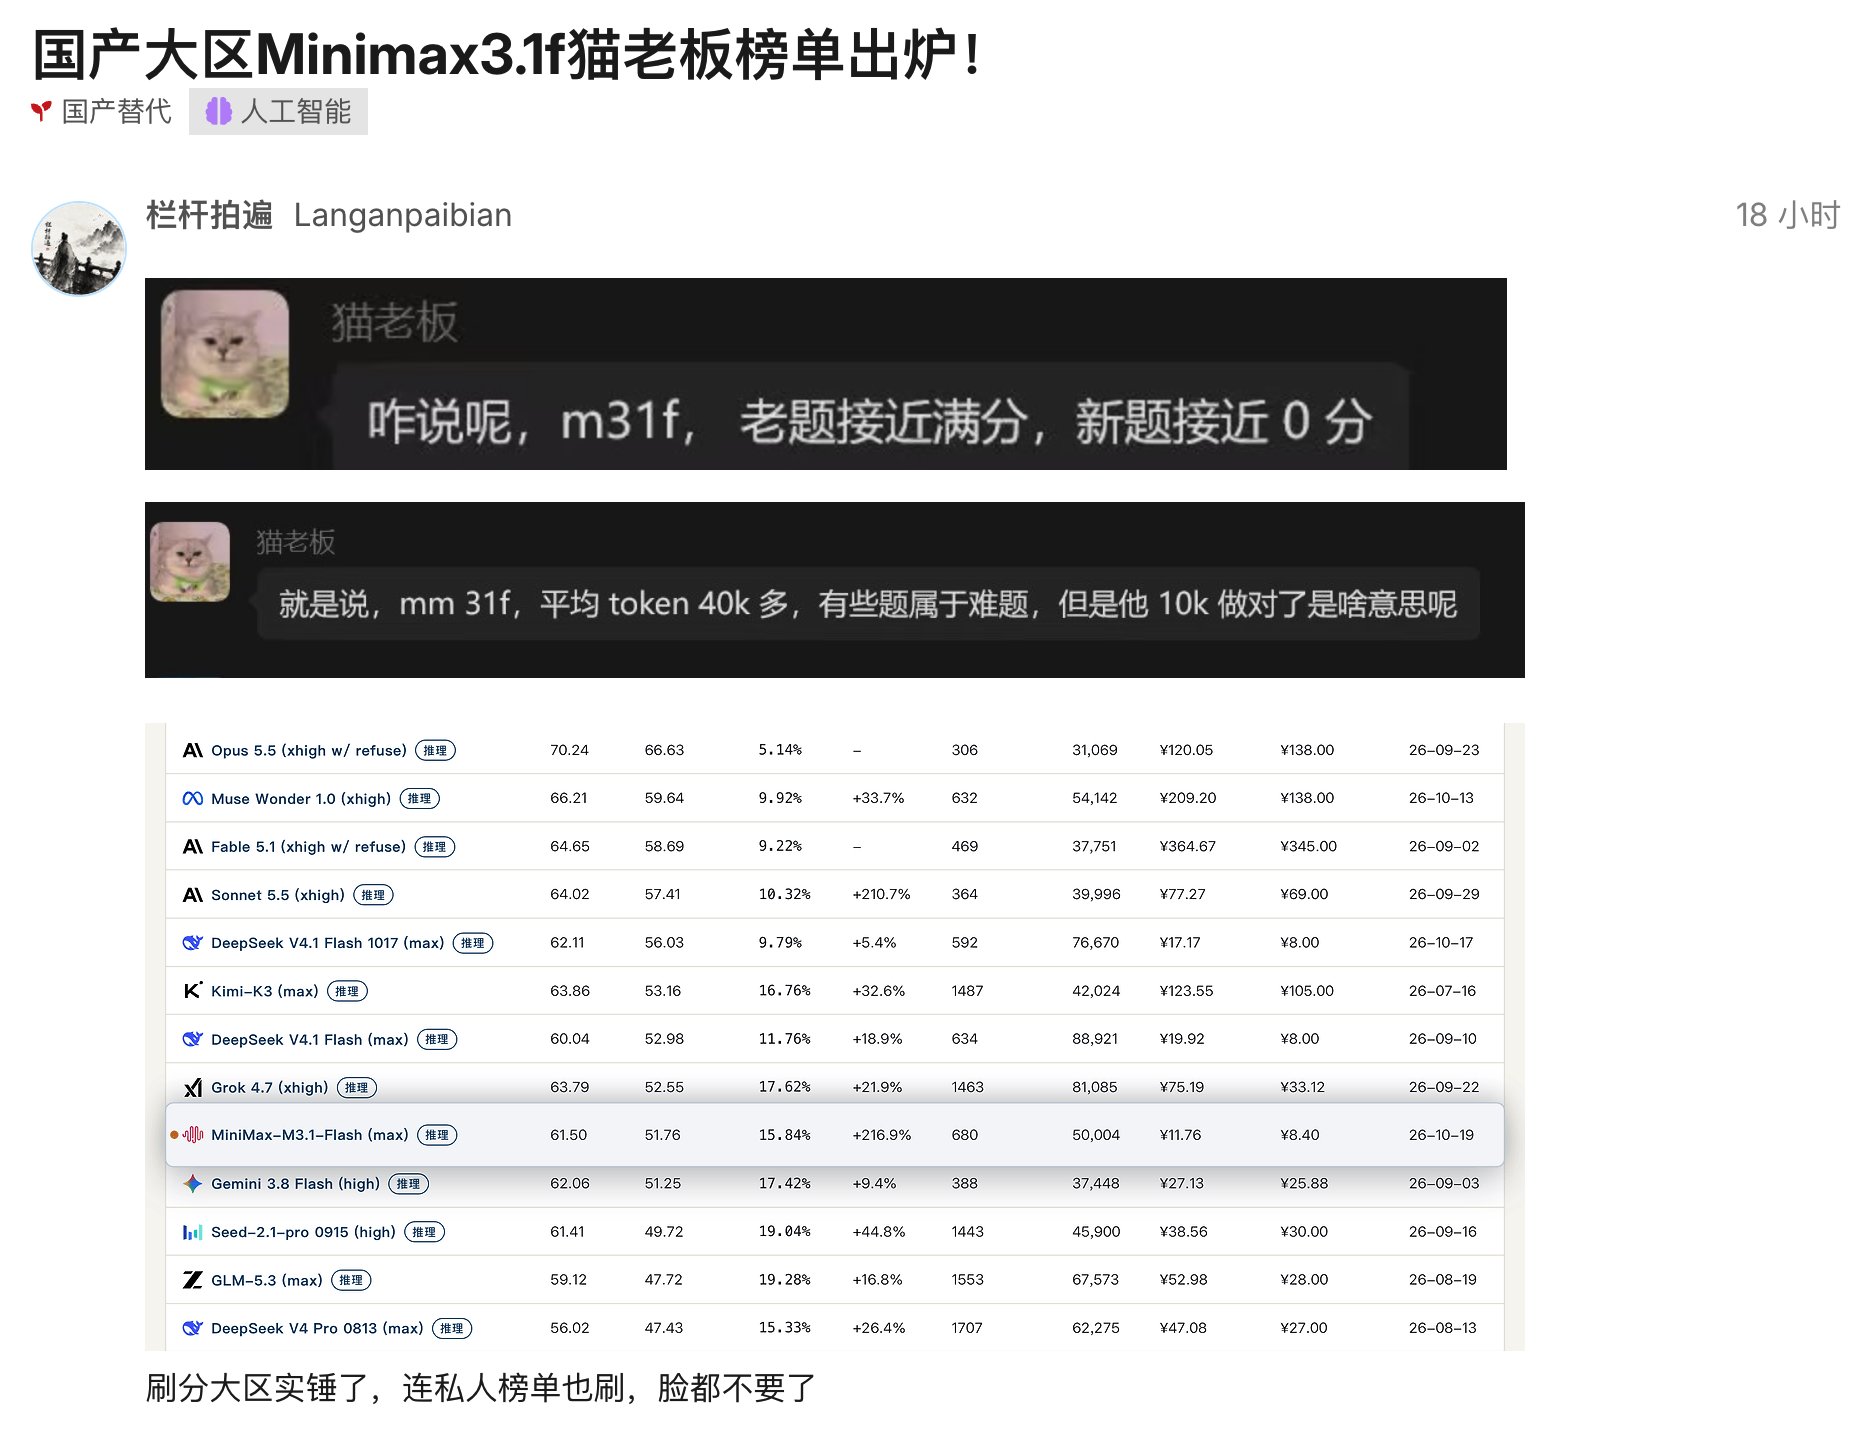
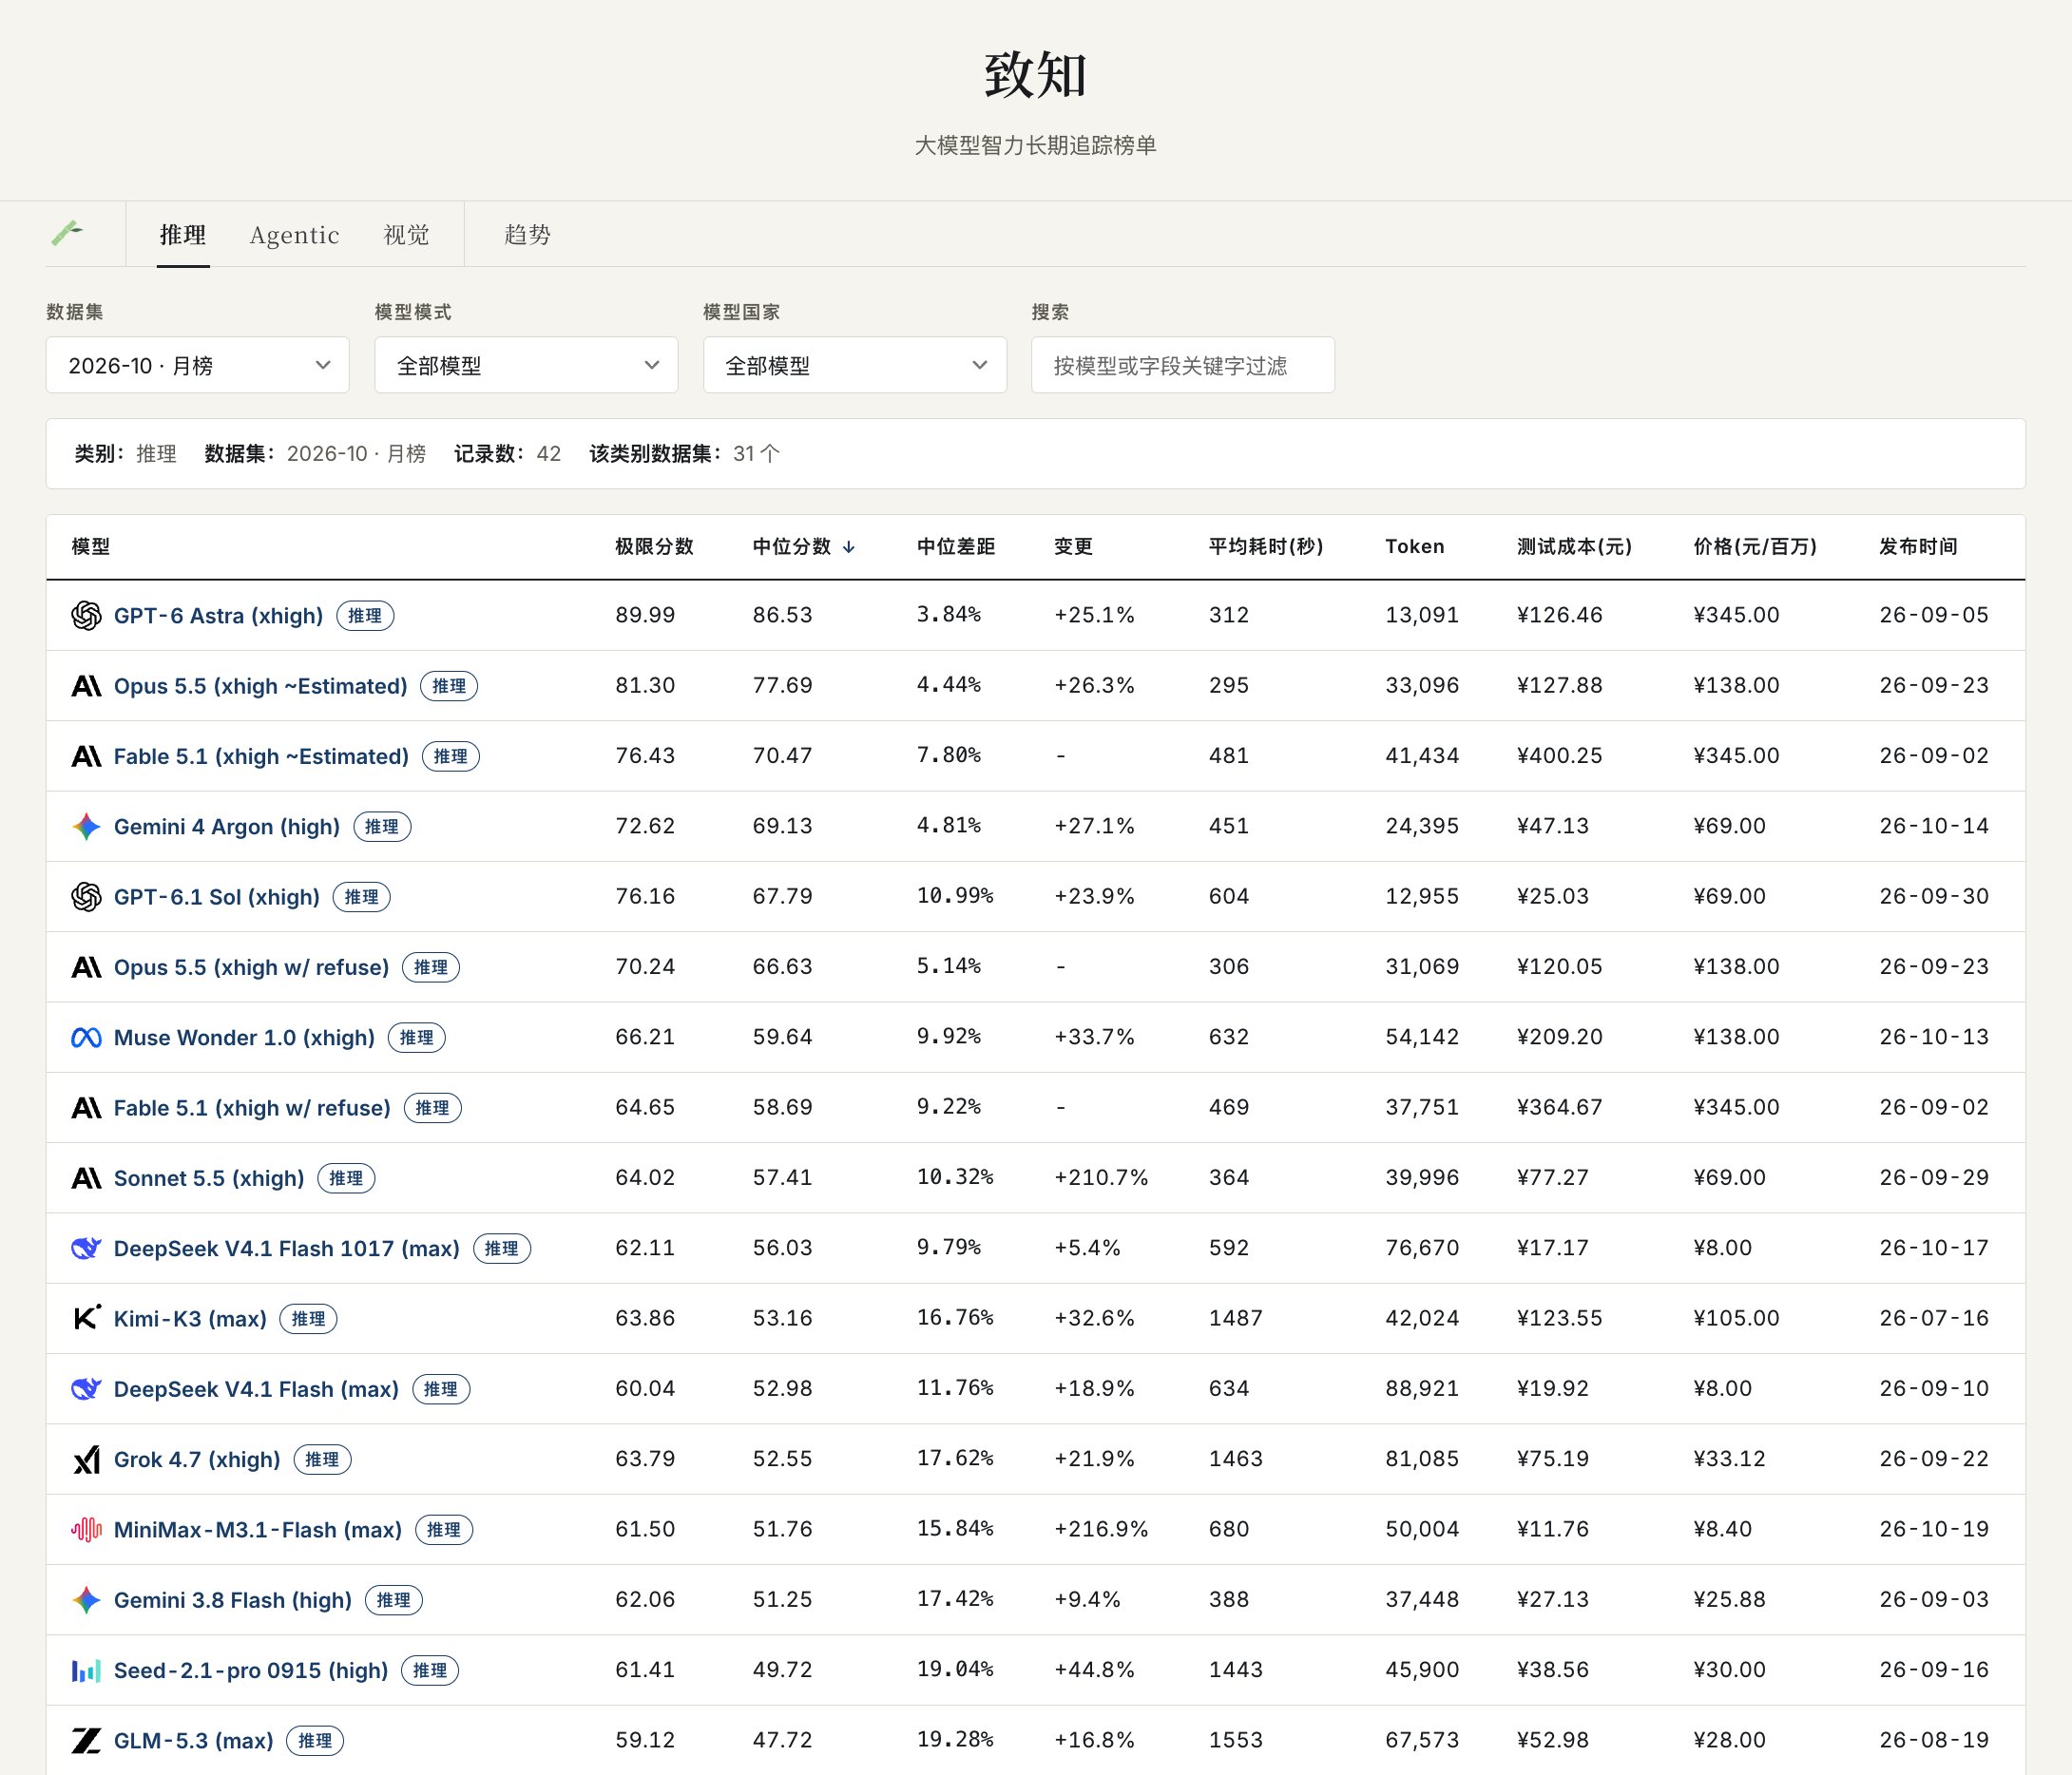
大模型评测博主「猫老板」测试 MiniMax M3.1 Flash 时也发现,模型在老题上接近满分,换成新题却接近零分。 模型平均每题要消耗数万 Token,但一些难题只用了约 1 万 Token 就能答对。这种反常的表现,让人怀疑模型是不是提前记住了部分题目的答案。 猫老板长期维护「致知」大模型排行榜,使用不公开的私人题库,主要测试逻辑、数学和编程能力。题库通常维持在 28 道题、270 个测试用例以内,每月更新部分题目,每道题测试 3 次,同时统计最高成绩和中位成绩。 这次 M3.1 Flash 的中位分数达到 51.76,比上一代 M3 的 23.86 提高一倍以上,接近最新 DeepSeek V4.1 Flash 1017 的 56.03。 大家怀疑,模型可能针对旧题进行了专门训练,而没有真正掌握解题方法。这种为提高评测成绩而专门优化模型的做法,被称为 Benchmaxxing。
This post quotes another post: “Suspicion that Minimax M3.1 Flash benchmaxxed AA Omniscience, passing Gemini 4 Argon”