MiniMax M3.1 Flash open weights: Space Bunny revealed plus specs and benchmarks
Roundup of the official release: Space Bunny was an earlier M3.1 Flash, 428B total/23B active with text, image and video input and 1M context, weights on HF/ModelScope, plus scores like DeepSWE 73.7% and OSWorld V2 61.7 and day-0 support from Together and SGLang.
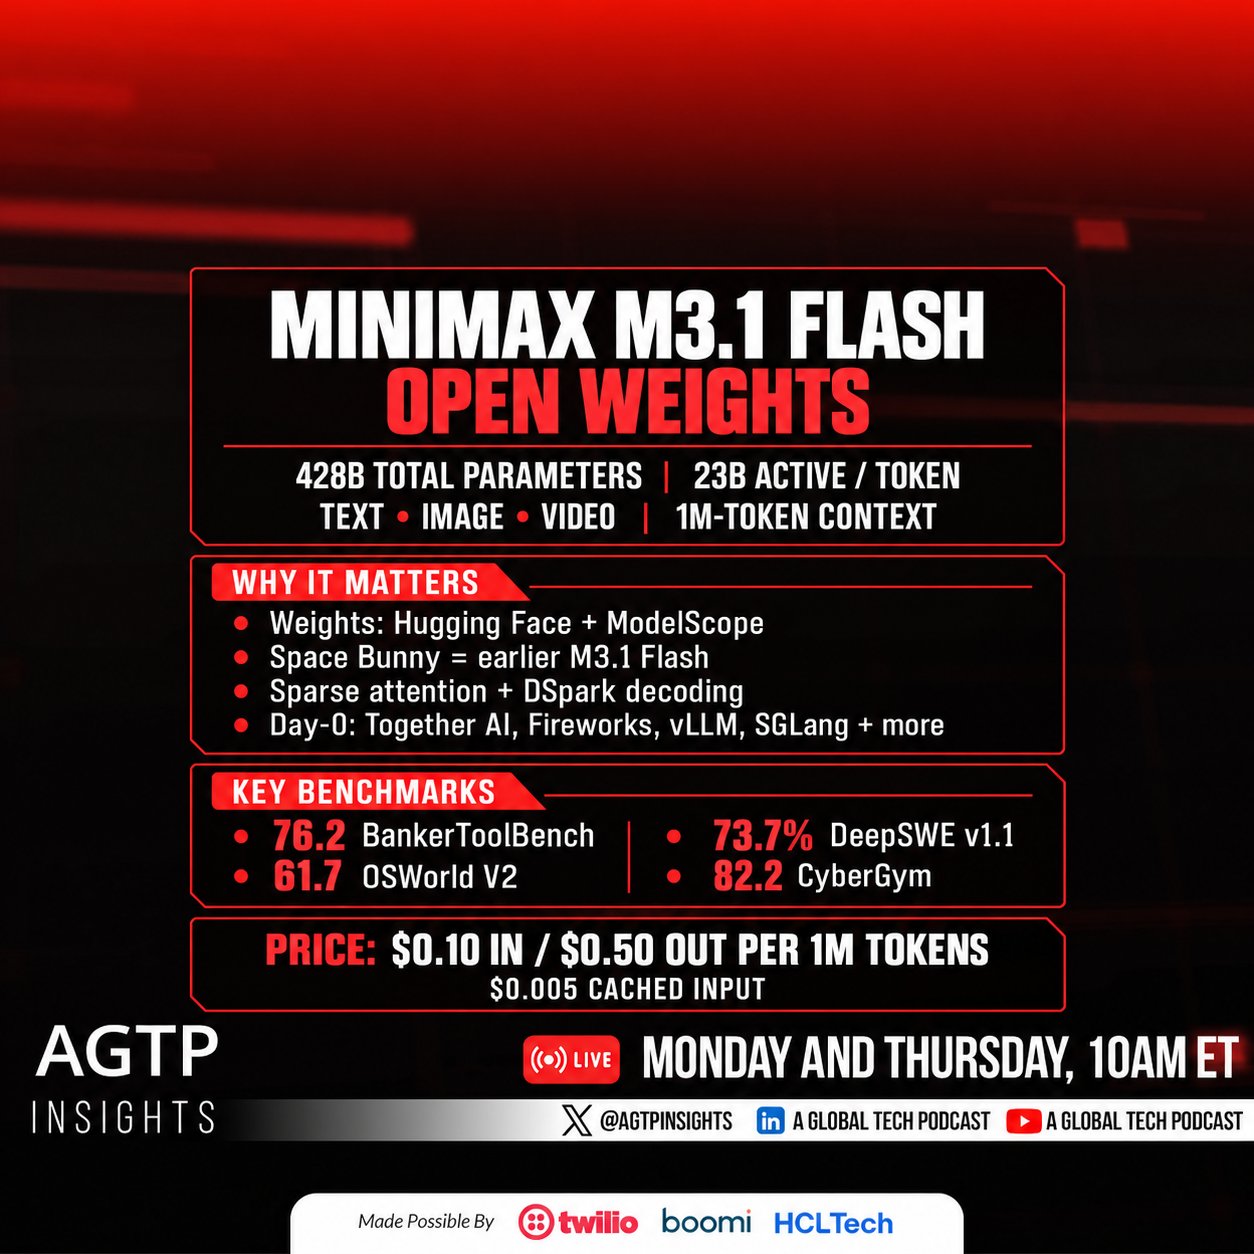
MiniMax just released the open weights for M3.1 Flash today. Here's what you need to know. The model teased earlier as Space Bunny is now downloadable. MiniMax says it has 428B parameters in total, with 23B activated per token. Weights are on Hugging Face and ModelScope. It supports text, image and video input, with a 1M-token context window. Space Bunny topped global leaderboards with 200T+ tokens, and MiniMax says it was an earlier version of M3.1 Flash. MiniMax says it is a generational leap in agentic tasks, coding and cybersecurity. It also says efficiency comes from MiniMax Sparse Attention and DSpark speculative decoding. Earlier it claimed nearly 3x faster online inference and 70% lower agentic cost than M3. The earlier free launch period on OpenRouter ended Oct 22. Day-0 support landed across the stack. Together AI, Fireworks, vLLM, SGLang, Tenstorrent and Inferact all went live at release. SGLang reports over 1K tokens per second at batch size 1 decode. NVIDIA says Vera Rubin ran it at up to 200K TPS per GPU. Inco AI open-sourced a DFlash 2 drafter under Apache 2.0, which it says makes generation up to 3.5x faster, and lossless. MiniMax also announced a partnership with Inferact to improve production inference, with engineering work going back to vLLM. Community reaction centers on two points. One observer says M3.1 Flash is essentially M3 with attention sparsified in 3 more layers, quantized, and DSpark added on top. Others say MiniMax got permission to open source it under new Chinese rules after the Oct 16 AI export restrictions, with DeepSeek getting approval for V4.1F-1017 too. Key numbers: - 428B total parameters, 23B active per token - 76.2 on BankerToolBench - 73.7% on DeepSWE v1.1 - 61.7 on OSWorld V2 - 29.6 on Agents' Last Exam - 82.2 on CyberGym - 62.8 on AutomationBench-AA, per Fireworks - OpenRouter price of $0.10 input and $0.50 output per 1M tokens, with $0.005 cached input The official post had about 97K views a few hours after it went up.
This post quotes another post: “MiniMax M3.1 Flash open weights: 428B total, 23B activated”