gpt-6IMAGE
Opus 5.5 is verbose and hard to skim, a user says, comparing it with GPT-6 Sol
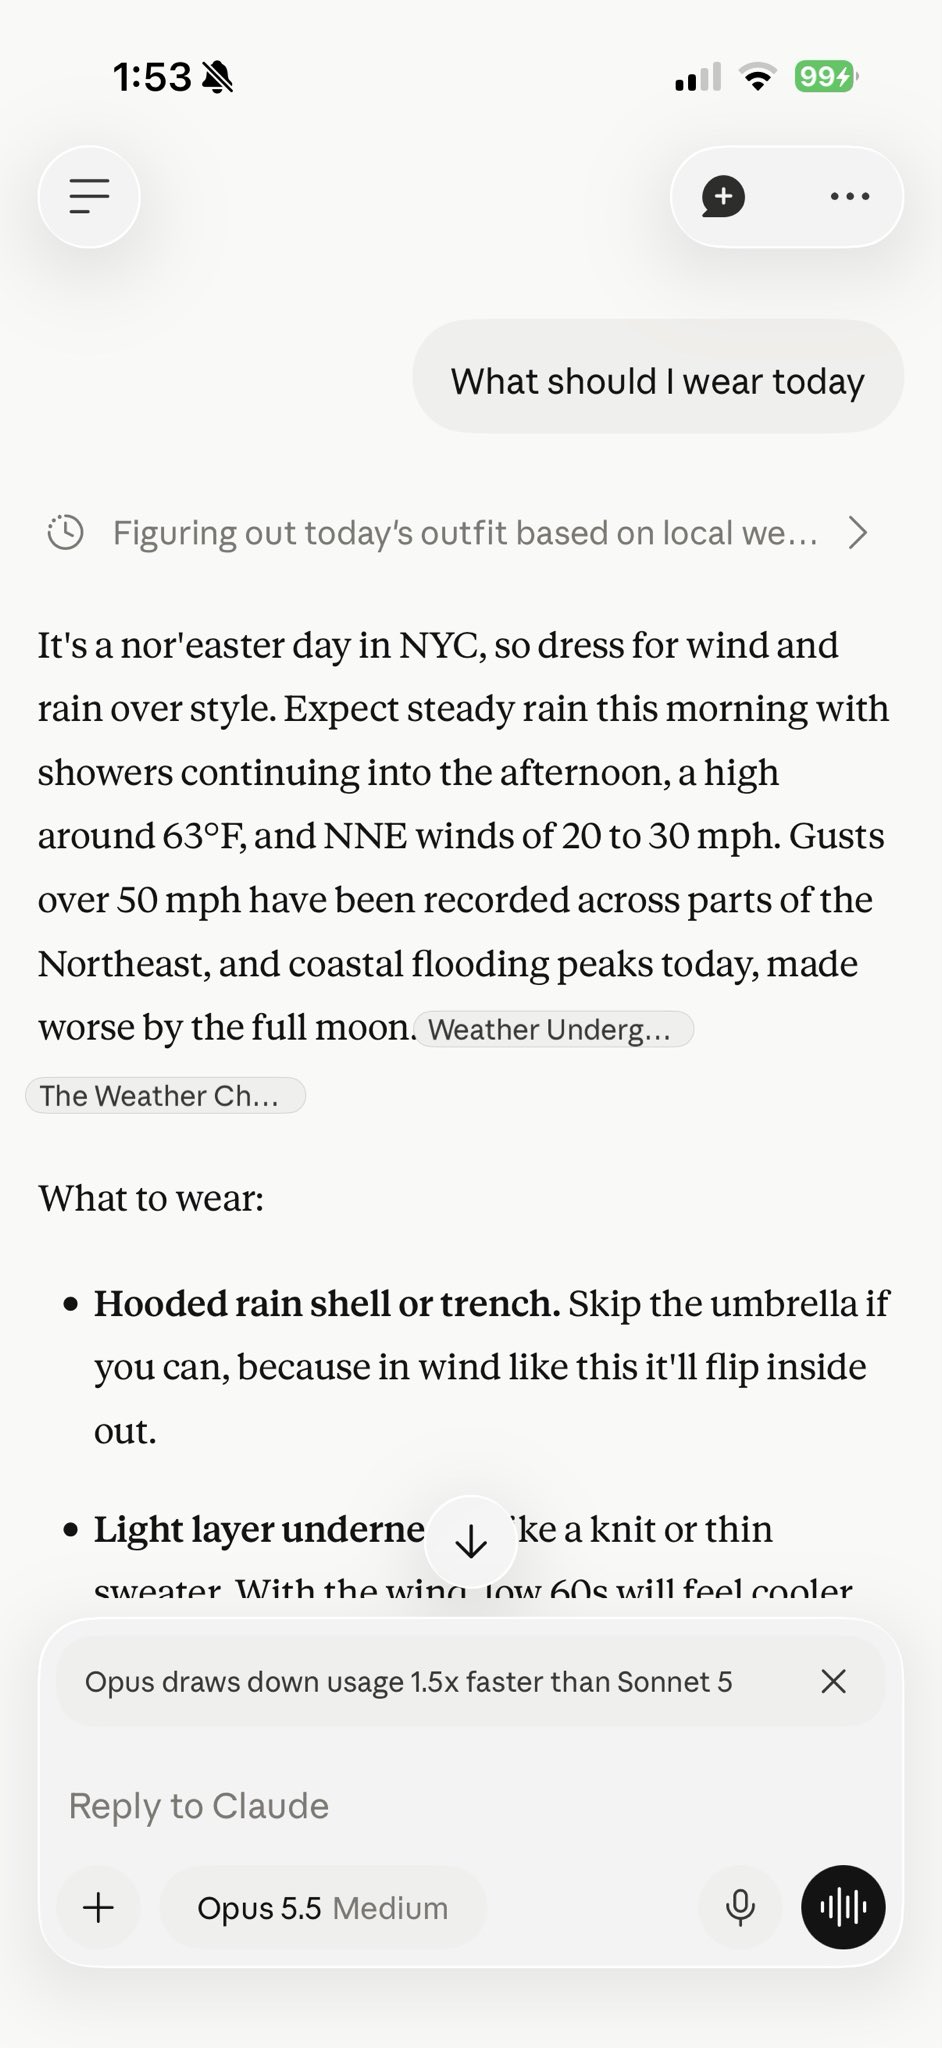
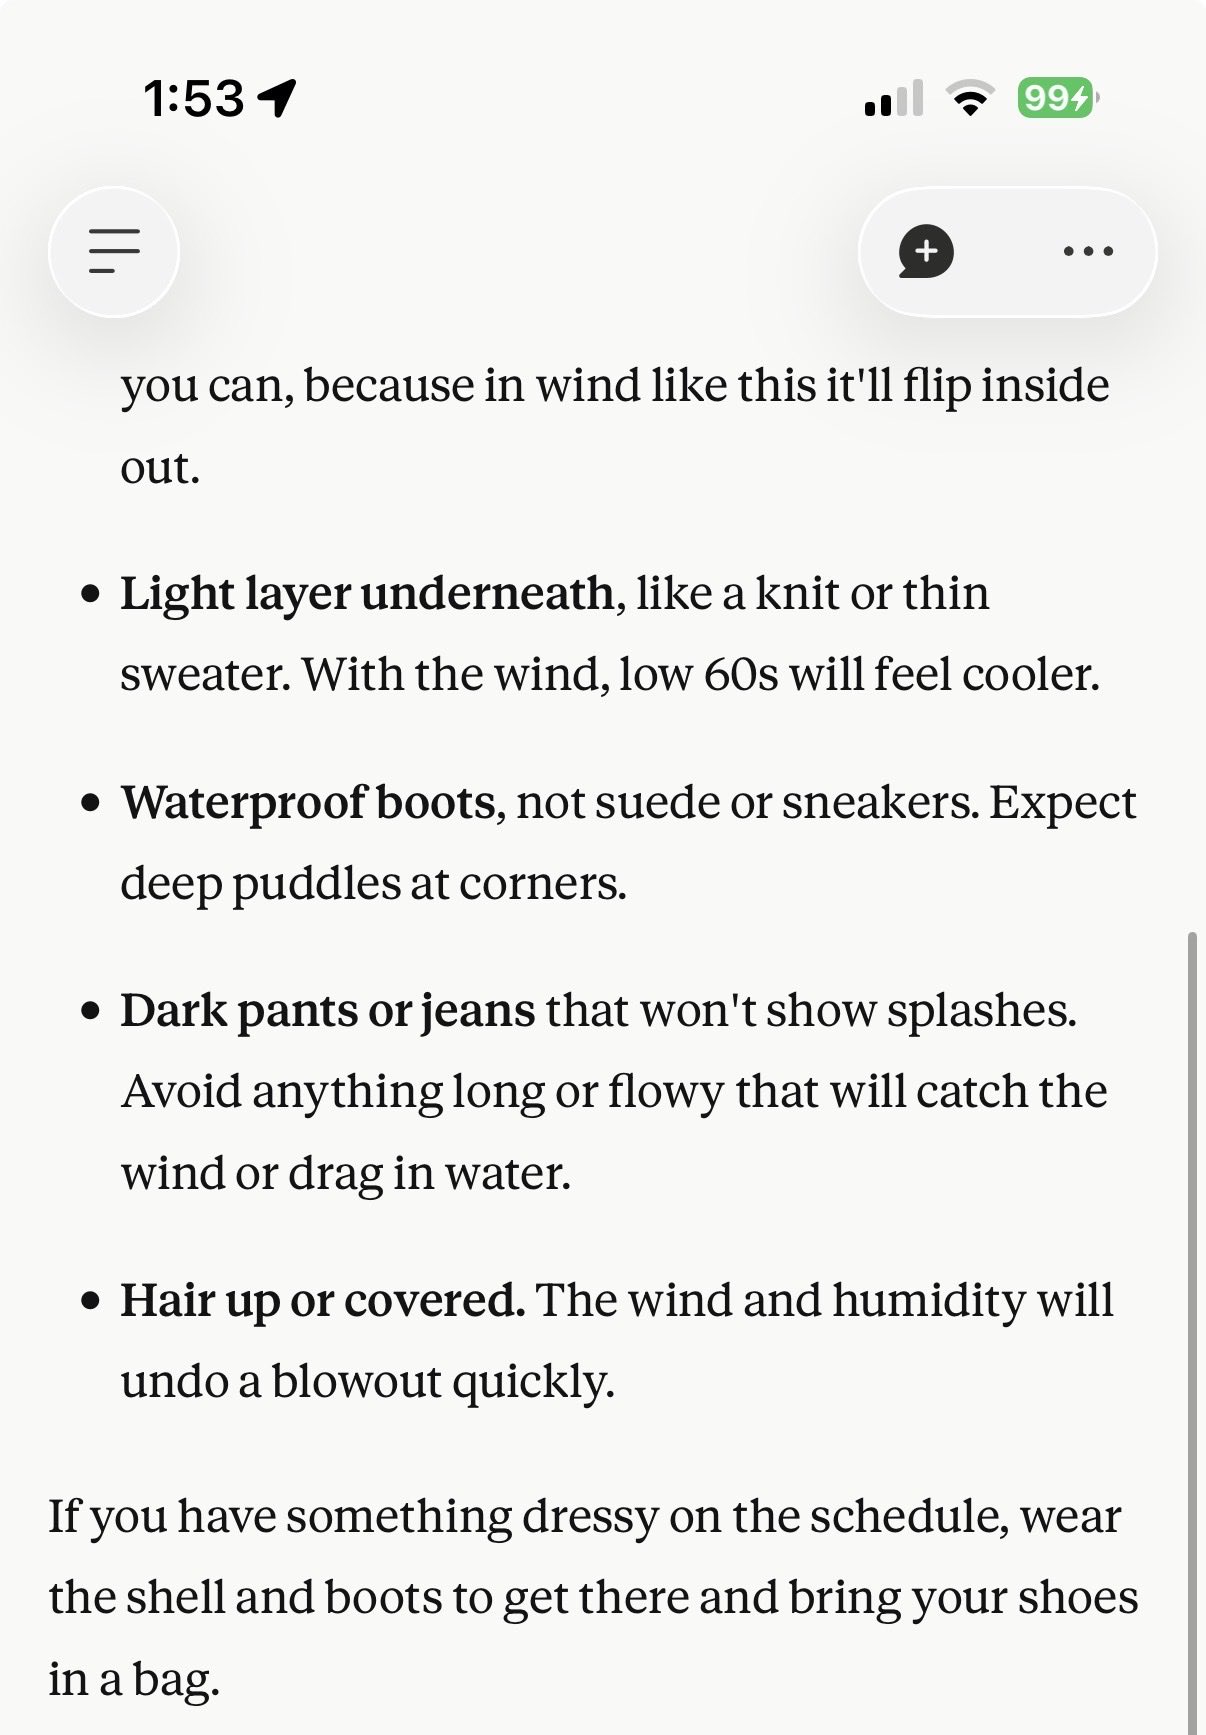
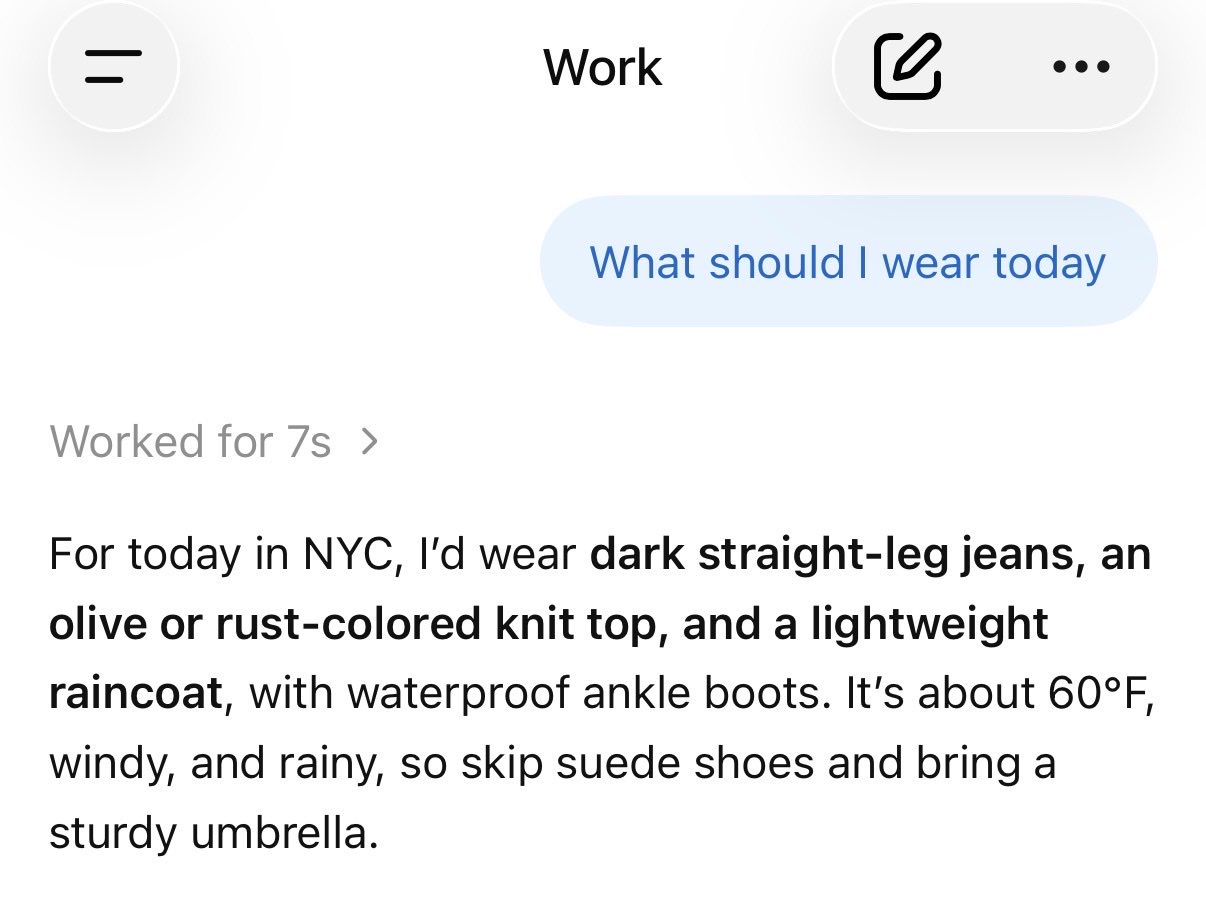
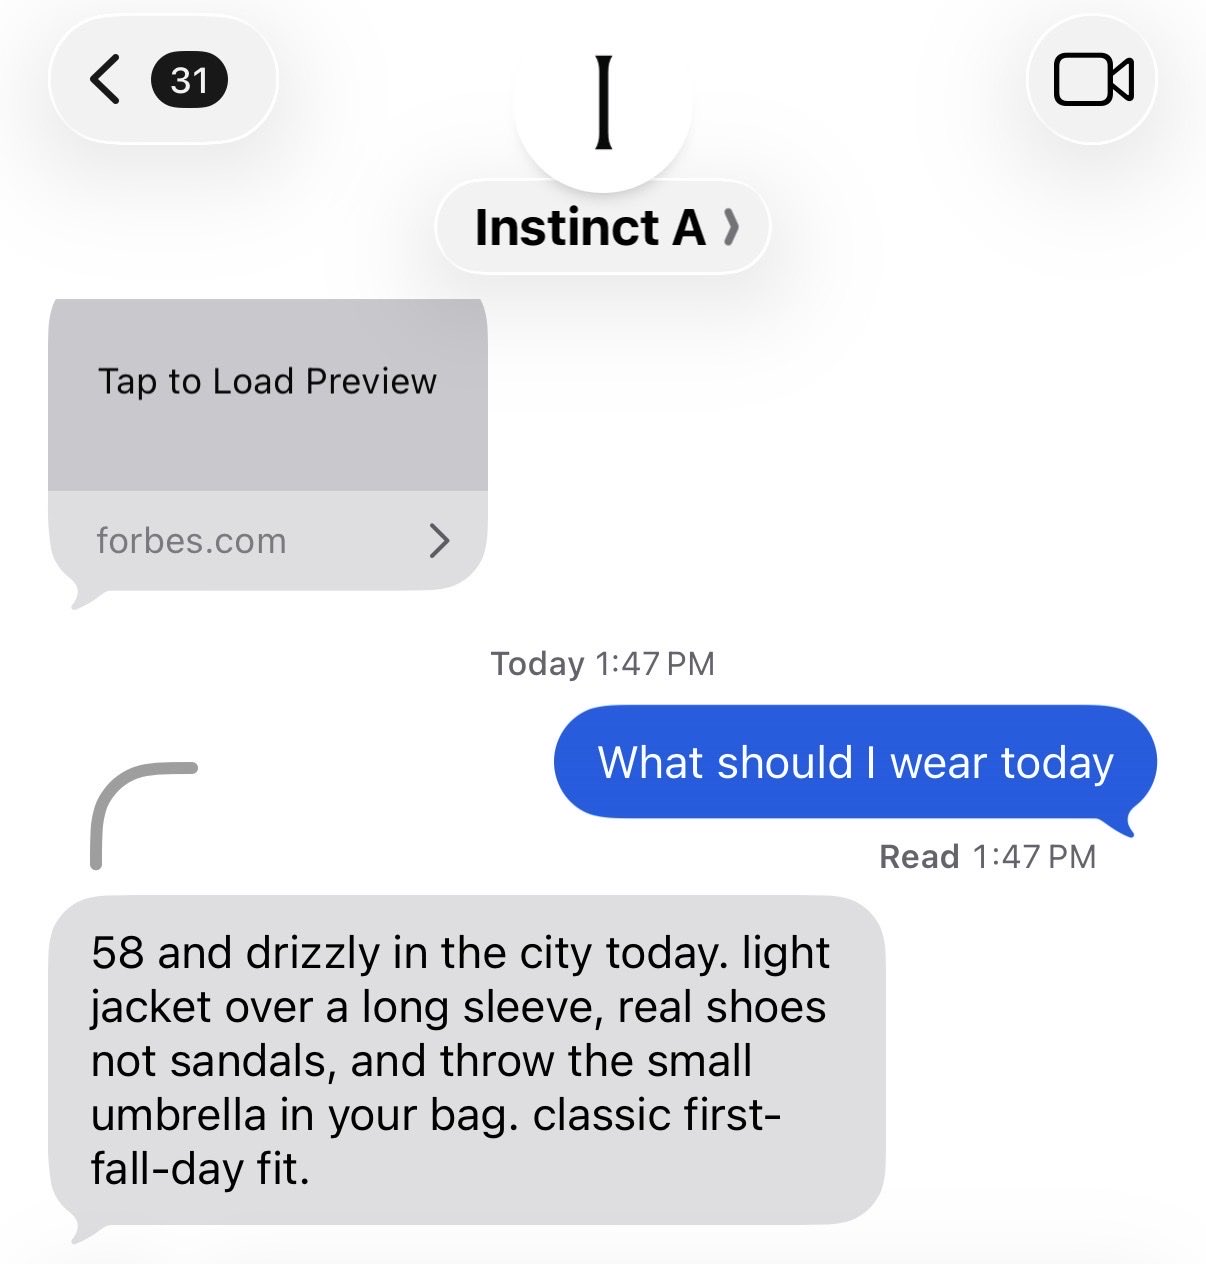
The author complains that Opus 5.5 is verbose, over-justifies everything and is hard to skim, and shares mobile screenshots comparing it with GPT-6 Sol and Instinct.
Allie K. Miller
@alliekmillerArchived 2026.09.27Originally posted 2026.09.27
Allie K. Miller @alliekmillerOriginally posted 2026.09.27
People on X: “CLAUDE IS BACK, baby!” Listen, Opus 5.5 is incredible and probably my favorite overall model right now, but it is still ridiculously verbose and over-justifies and over-qualifies everything. I curse at it less than previous models, but it still responds in a way that - dare I say - makes no sense to the average reader? It always feels so difficult to skim. And that makes it worse in a business or personal setting. See comparison examples from Claude chat on mobile with Opus 5.5 medium, ChatGPT Work on mobile with GPT-6 Sol medium, and Instinct.
x.com/alliekmiller/status/2103906784666652948Archived 2026.09.27 09:53