Artificial Analysis publishes MiniMax M3.1 Flash benchmark page
Independent evaluator Artificial Analysis has a model page with its own benchmarks and intelligence index for MiniMax M3.1 Flash.
See Artificial Analysis for further details and benchmarks of MiniMax-M3.1-Flash: https://artificialanalysis.ai/models/minimax-m3-1-flash
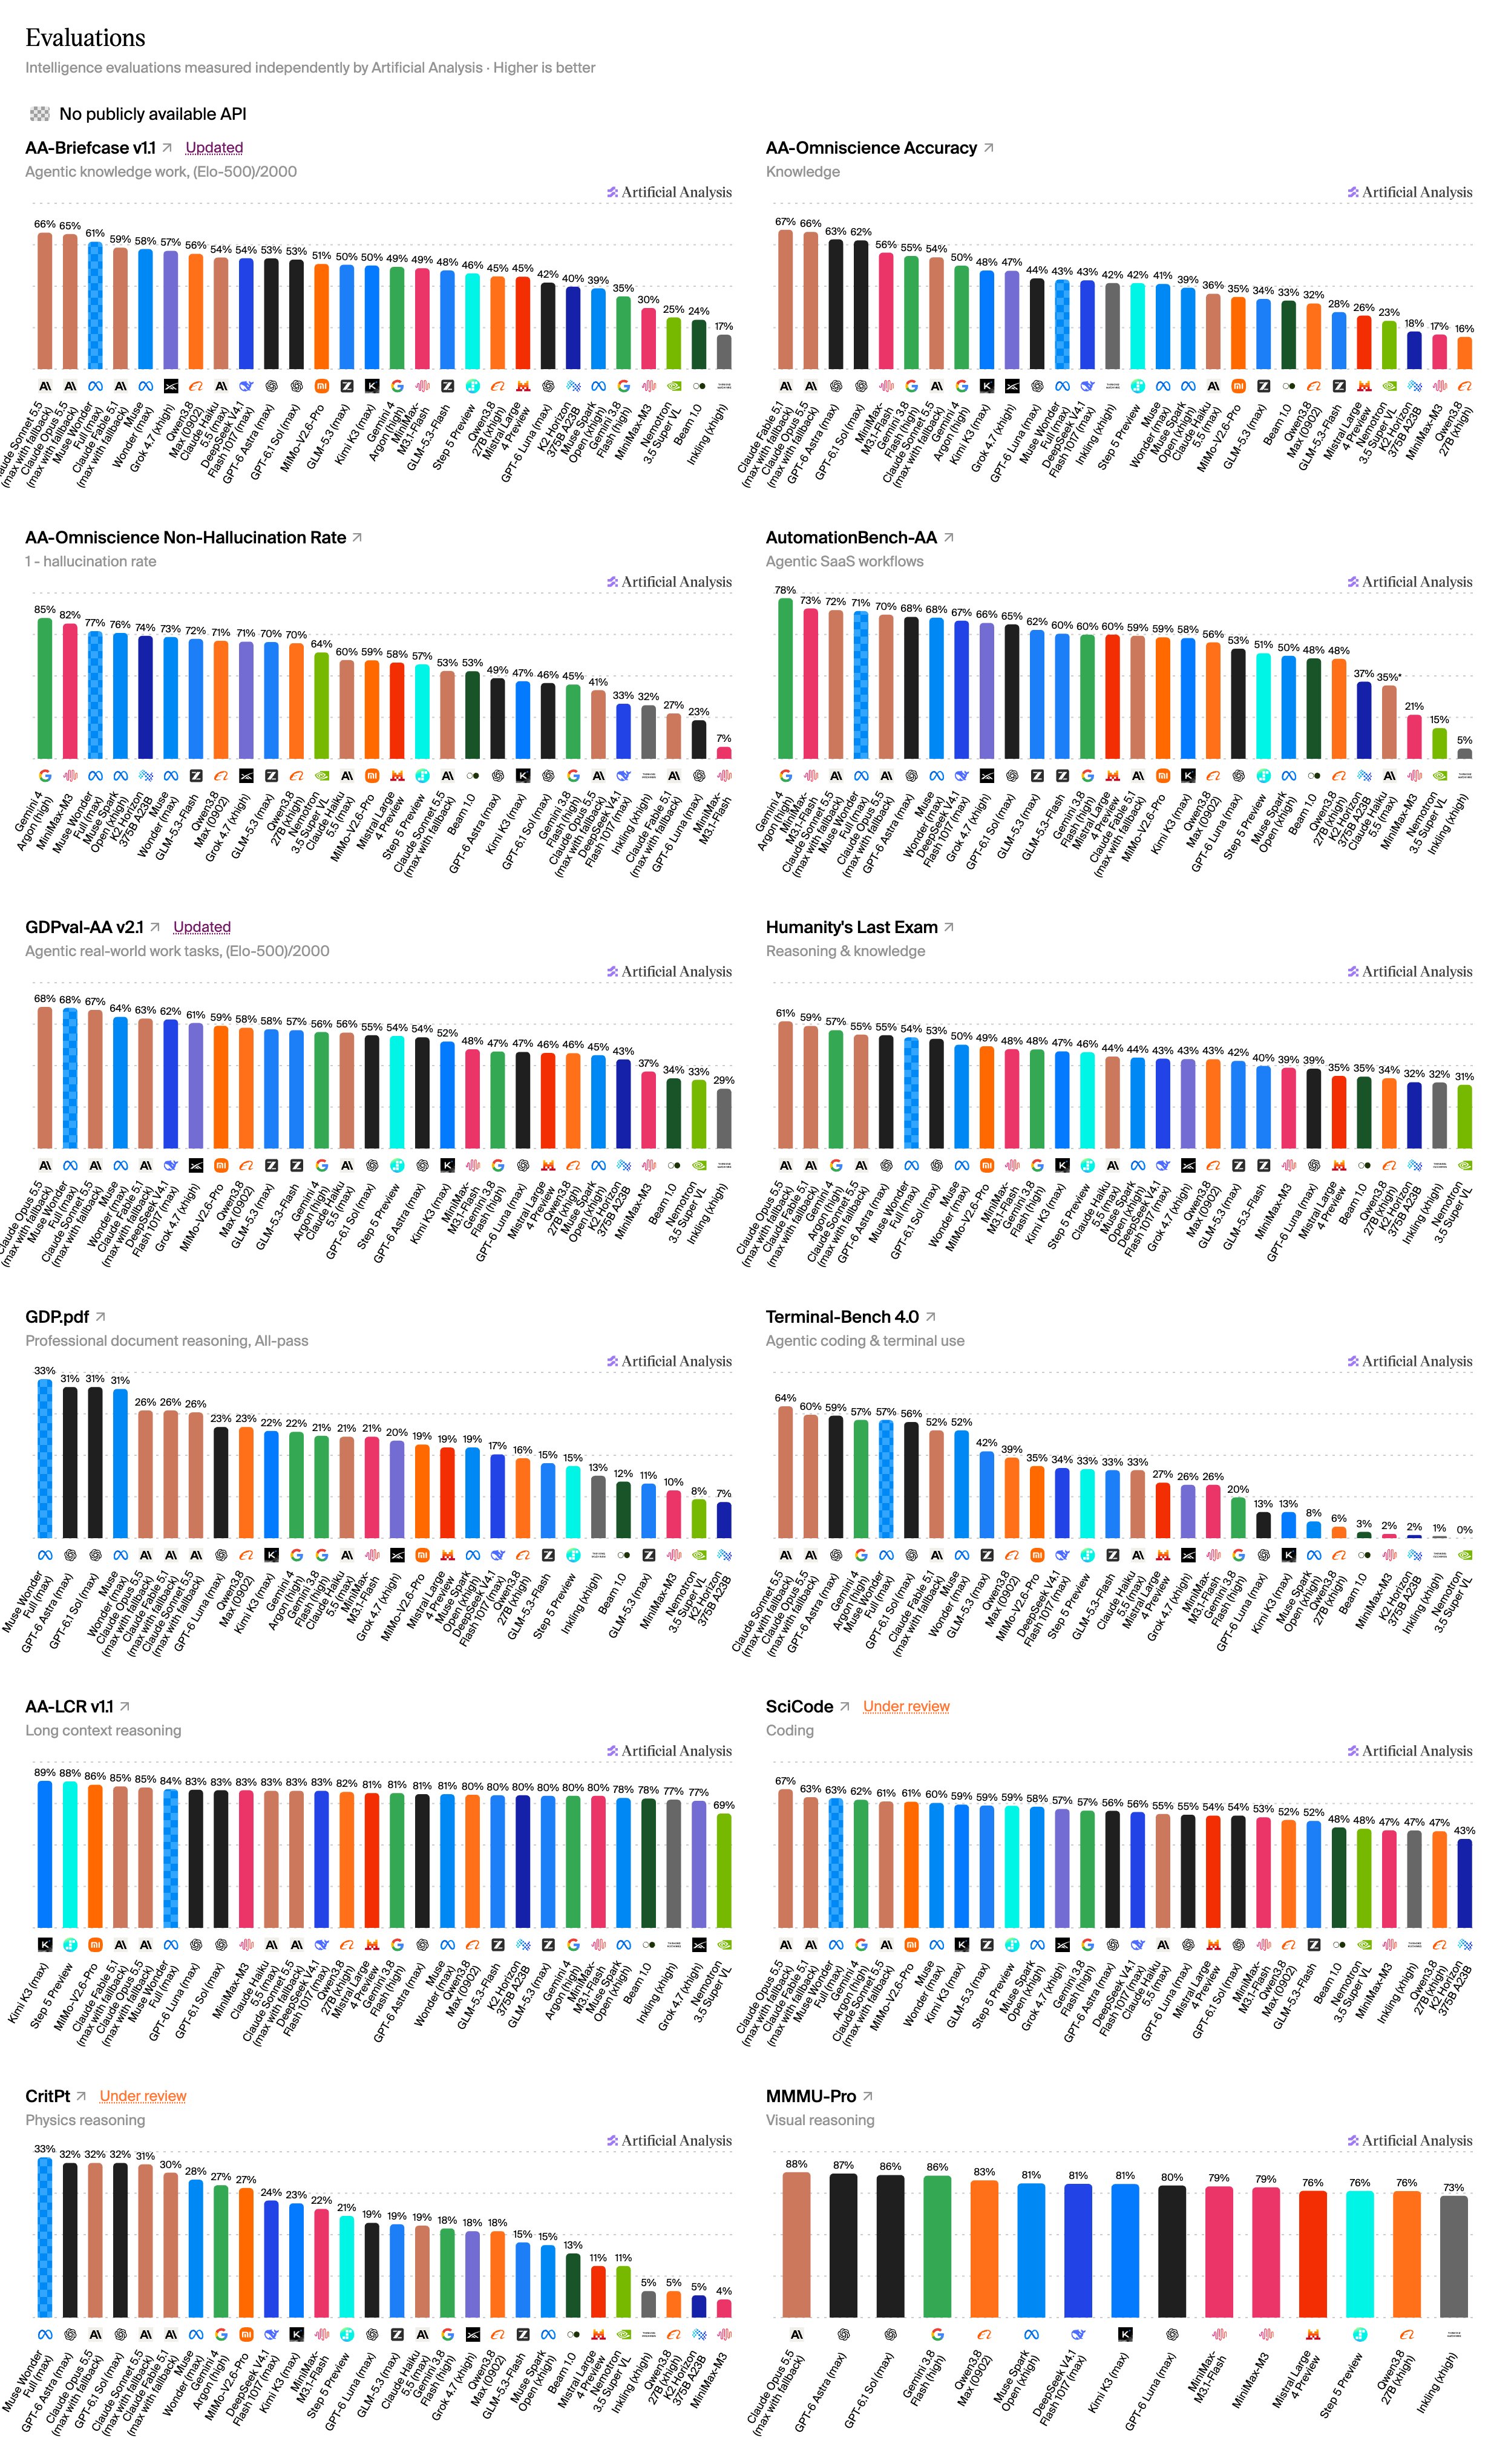
Full breakdown of results for MiniMax-M3.1-Flash across the evaluations in the Artificial Analysis Intelligence Index
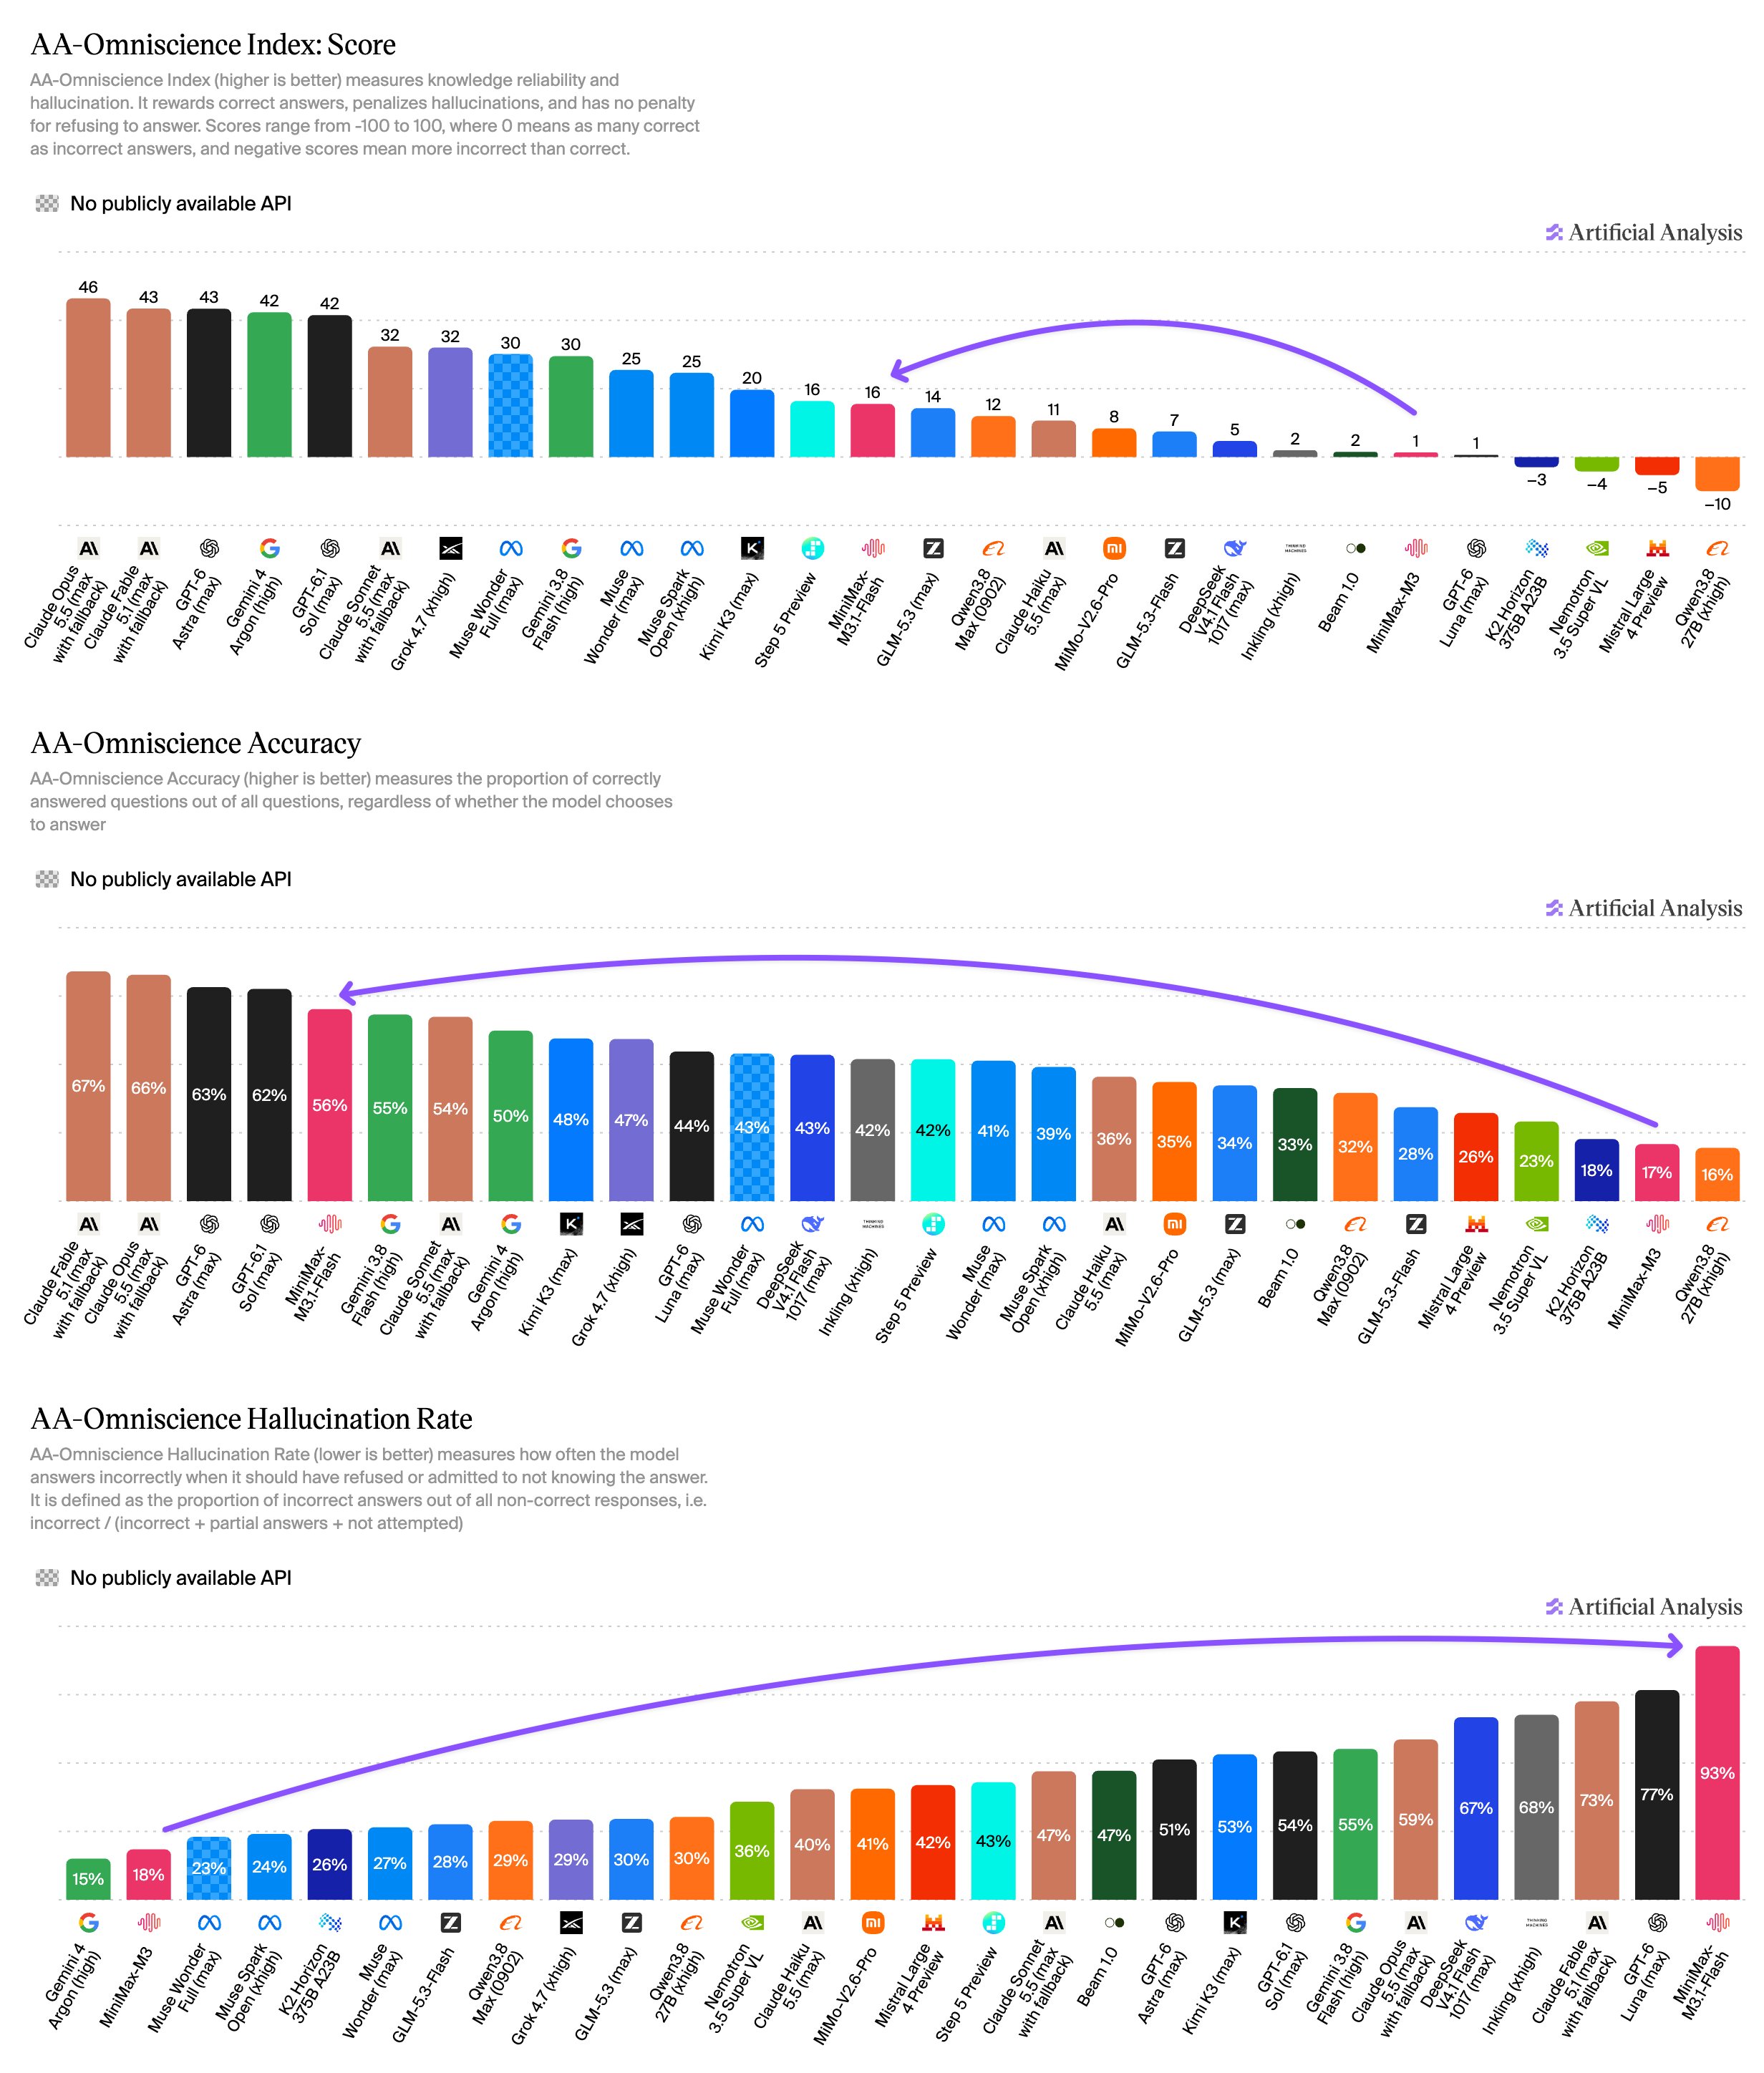
On AA-Omniscience, MiniMax-M3.1-Flash answers 56% of questions correctly, ahead of GLM-5.3-Flash (max, 28%) and DeepSeek V4.1 Flash 1017 (max, 43%) and in line with Gemini 3.8 Flash (high, 55%). It attempts 98% of questions, however, and hallucinates on 93% of those it does not know, against 28%, 67% and 55% respectively. Its higher accuracy still puts it at 16 on the AA-Omniscience Index, ahead of GLM-5.3-Flash (8) and DeepSeek V4.1 Flash 1017 (5) but behind Gemini 3.8 Flash (30). This is a reversal from MiniMax-M3, which attempted only 35% of questions and had a hallucination rate of 18%, but answered just 17% correctly for an AA-Omniscience Index of 1
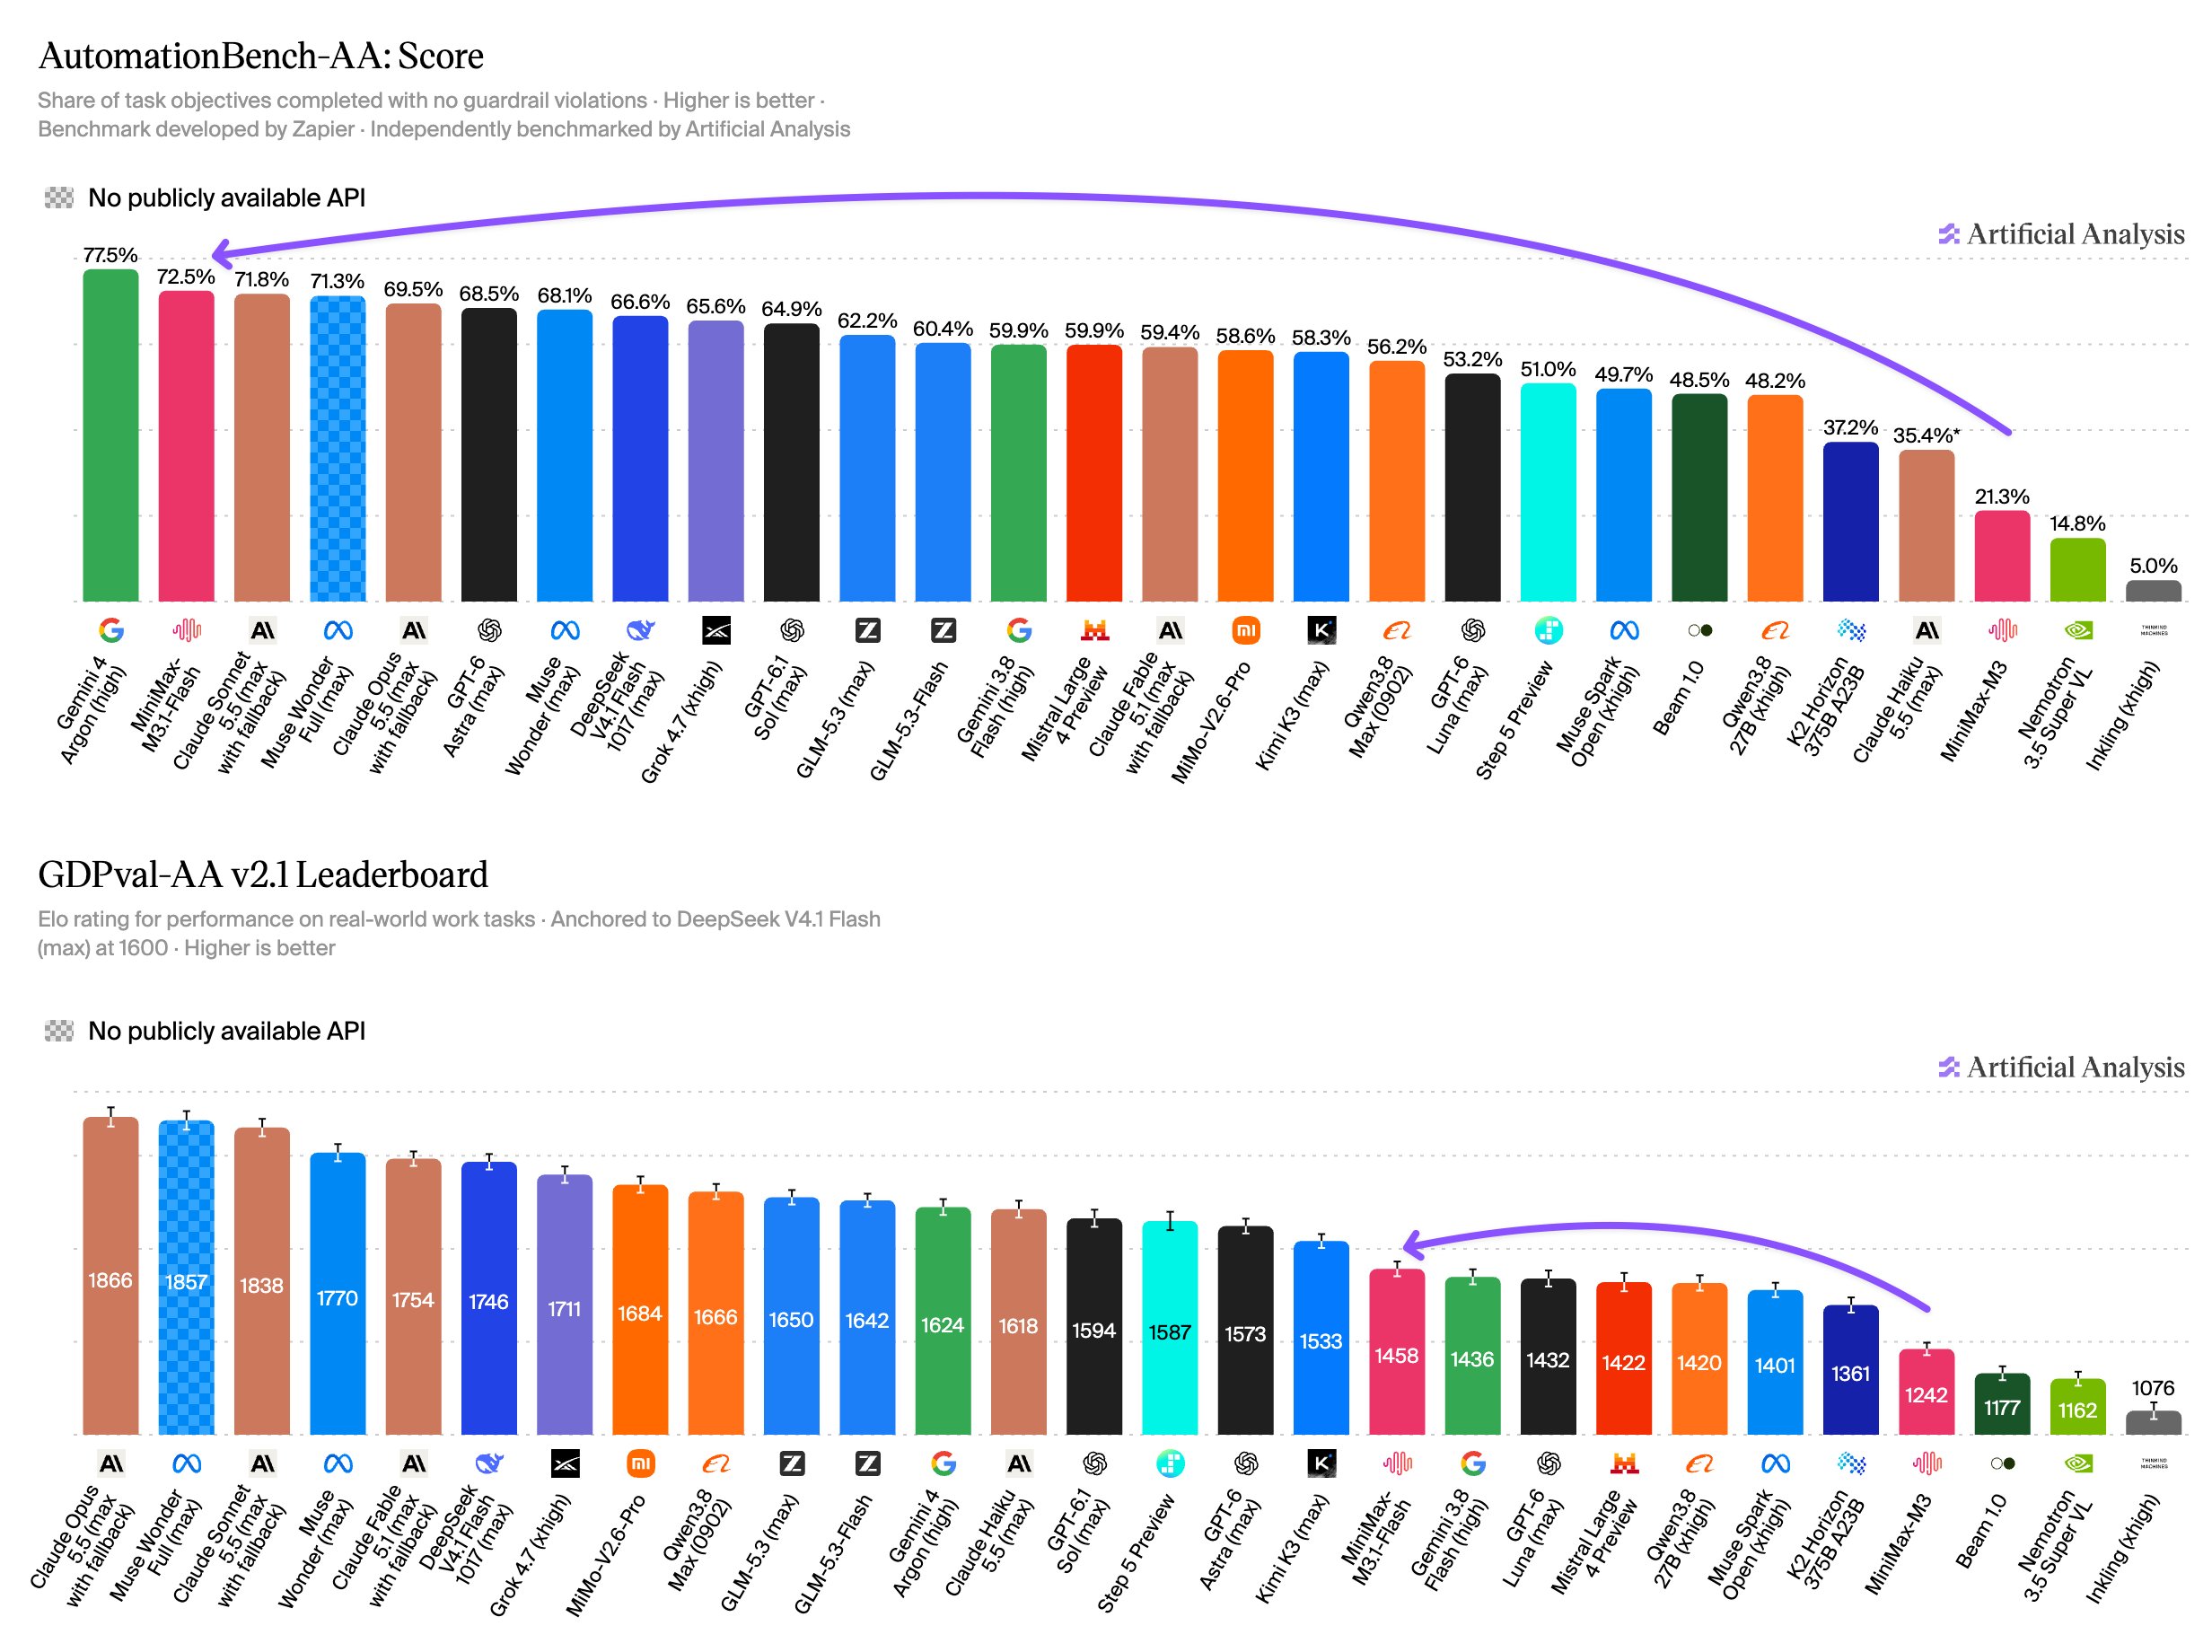
MiniMax-M3.1-Flash scores 73% on AutomationBench-AA, ahead of GLM-5.3-Flash (max, 60%) and DeepSeek V4.1 Flash 1017 (max, 67%). Its other agentic results are mixed: it sits between them on AA-Briefcase (1474 Elo vs 1453 and 1570), but trails both on GDPval-AA (1458 vs 1642 and 1746) and Terminal-Bench v4.0 (26% vs 33% and 34%)
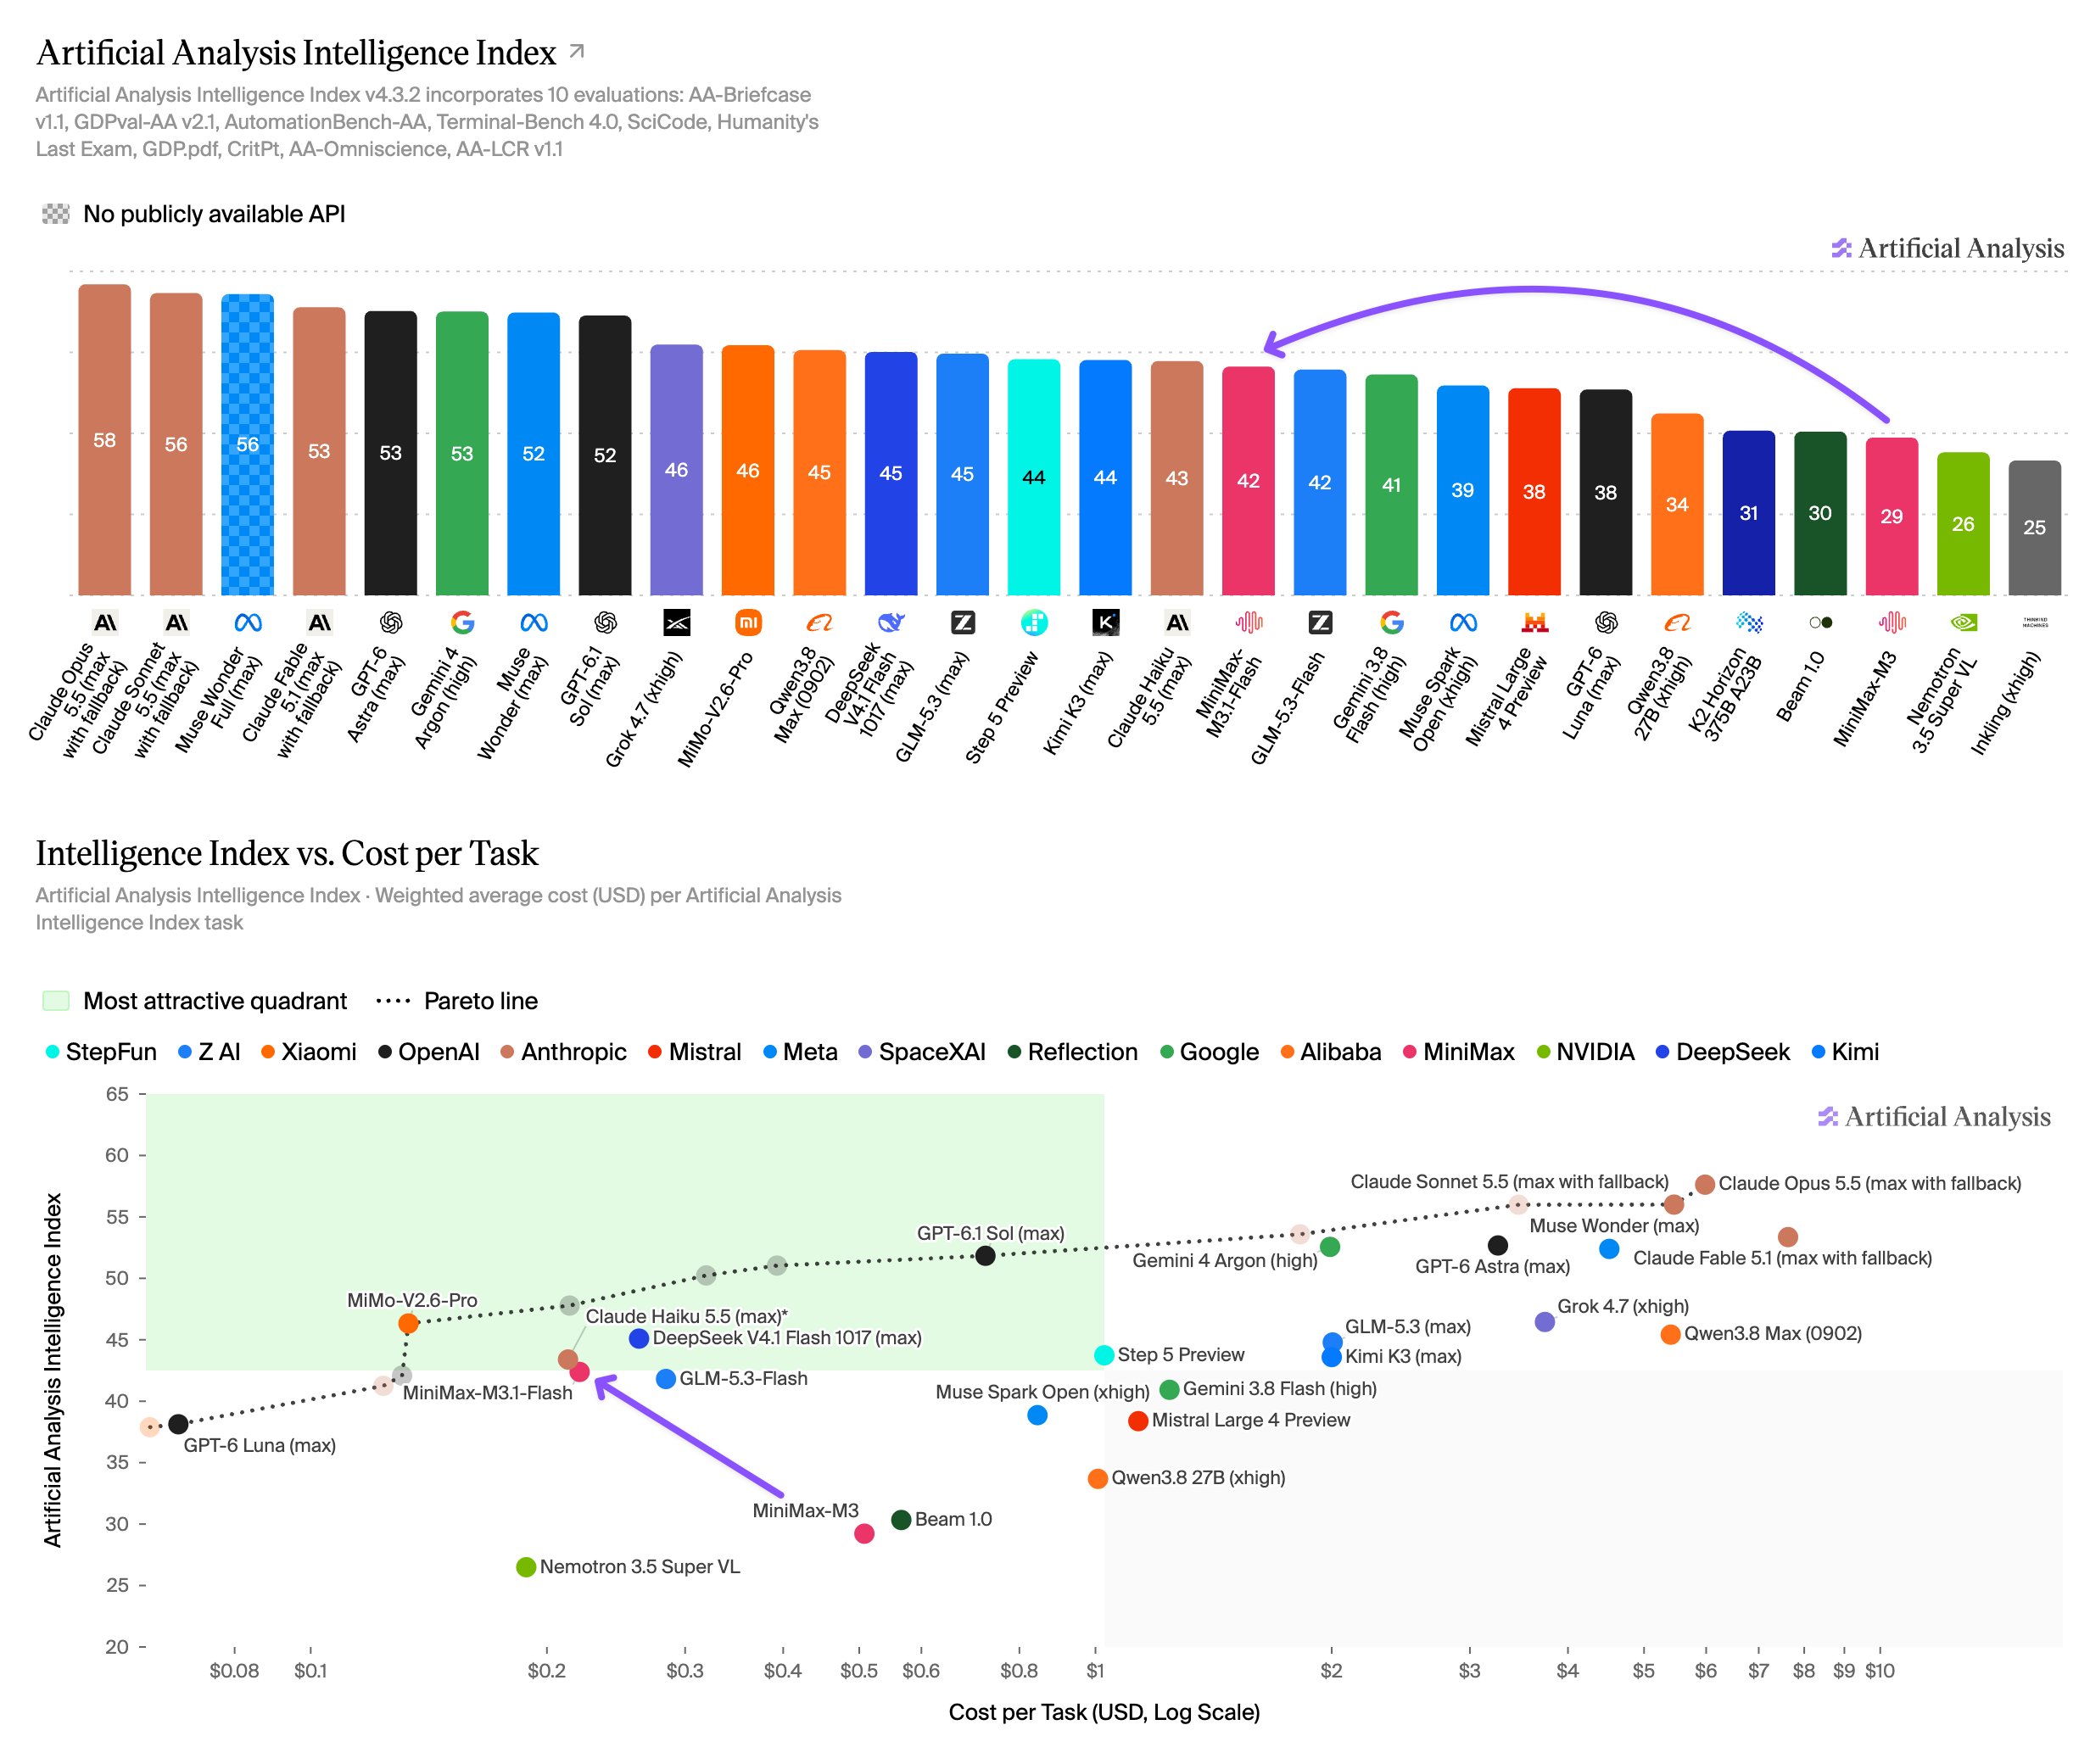
MiniMax-M3.1-Flash costs ~$0.22 per task to run the Intelligence Index and score 42, cheaper than GLM-5.3-Flash (max, ~$0.28) which scores the same 42 and DeepSeek V4.1 Flash 1017 (max, ~$0.26) which scores 3 points higher. Its per-token pricing is close to GLM-5.3-Flash ($0.15/$0.60 vs $0.15/$0.50 per 1M input/output tokens), so the gap comes mostly from token usage: ~189M output tokens to run the Index against ~324M for GLM-5.3-Flash
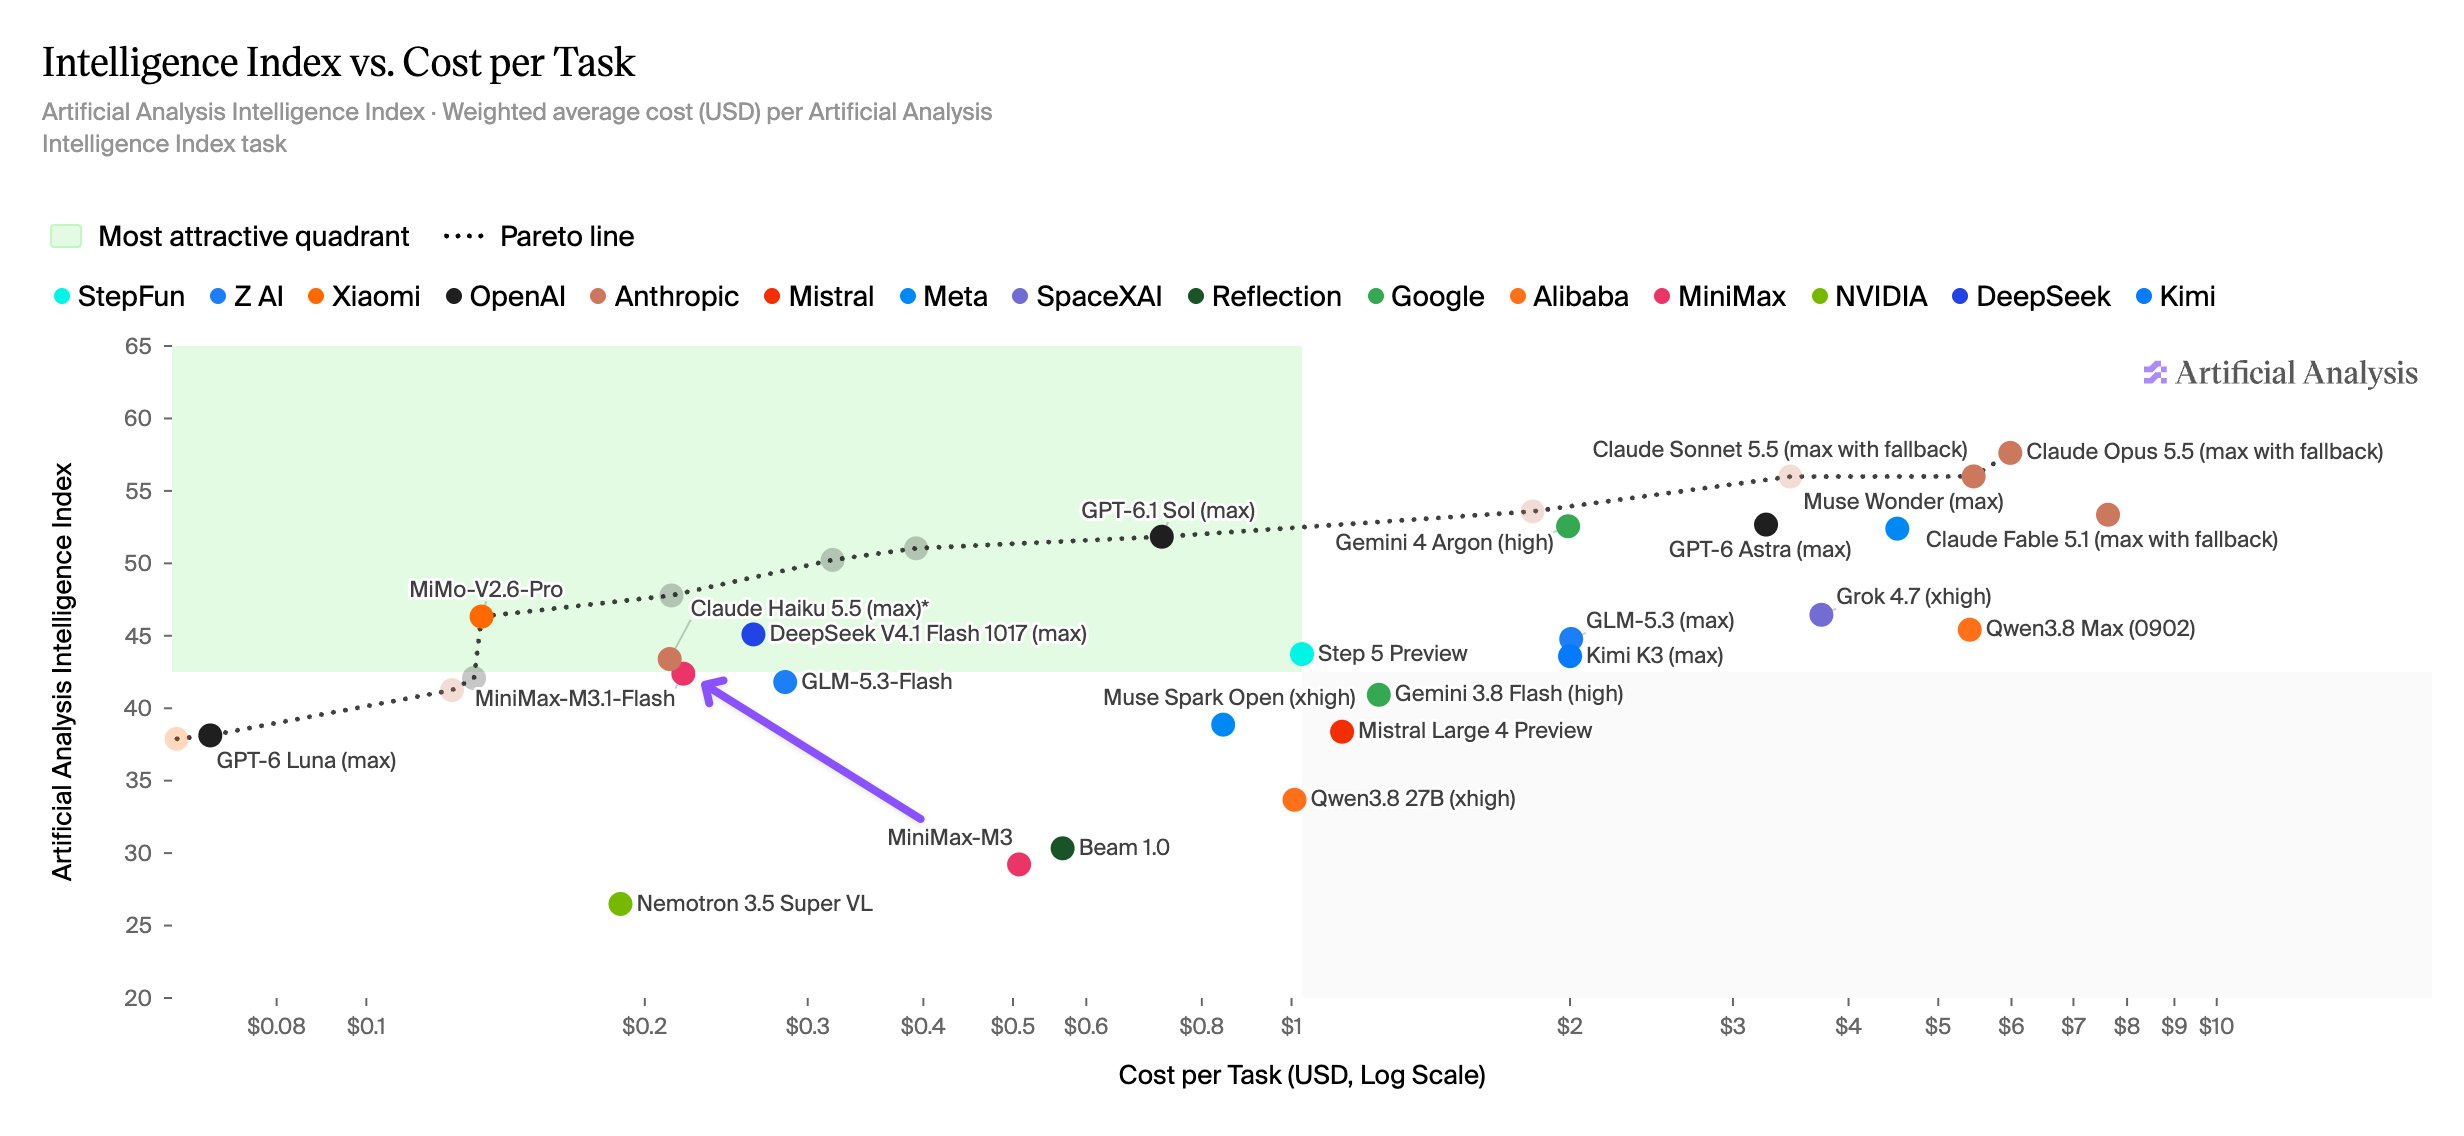
MiniMax-M3.1-Flash scores 42 on the Artificial Analysis Intelligence Index, 13 points higher than MiniMax-M3 and less than half the cost per task. It scores level with GLM-5.3-Flash but behind DeepSeek V4.1 Flash 1017 MiniMax-M3.1-Flash is @MiniMax_AI's new Flash reasoning model, which we benchmarked at its max effort setting. It scores 42 on the Artificial Analysis Intelligence Index, level with GLM-5.3-Flash (max, 42), just ahead of Gemini 3.8 Flash (high, 41), and behind DeepSeek V4.1 Flash 1017 (max, 45) Key takeaways: ➤ Complex reasoning improved substantially compared to M3: MiniMax-M3.1-Flash scores 48% on Humanity's Last Exam, ahead of GLM-5.3-Flash (max, 40%) and DeepSeek V4.1 Flash 1017 (max, 43%), and level with Gemini 3.8 Flash (high, 48%). On CritPt it scores 22%, ahead of GLM-5.3-Flash (15%) and Gemini 3.8 Flash (18%) and just behind DeepSeek V4.1 Flash 1017 (24%). These are up from MiniMax-M3 which scored 39% and 4% respectively ➤ Fewer output tokens, lower cost per task: MiniMax-M3.1-Flash used ~189M output tokens to run the Intelligence Index, considerably fewer than GLM-5.3-Flash (max, ~324M), DeepSeek V4.1 Flash 1017 (max, ~224M) and Gemini 3.8 Flash (high, ~334M). Combined with pricing of $0.15/$0.60 per 1M input/output tokens, this brings its cost to ~$0.22 per Intelligence Index task, vs ~$0.28 for GLM-5.3-Flash, ~$0.26 for DeepSeek V4.1 Flash 1017 and ~$1.24 for Gemini 3.8 Flash, and less than half MiniMax-M3's ~$0.51 ➤ High AA-Omniscience accuracy, offset by a high hallucination rate: MiniMax-M3.1-Flash answers 56% of questions correctly on AA-Omniscience, our benchmark measuring factual recall and hallucination, vs 28% for GLM-5.3-Flash (max) and 43% for DeepSeek V4.1 Flash 1017 (max). It attempts almost every question, resulting in a hallucination rate of 93% and an overall score of 16 on AA-Omniscience Key model details: ➤ Context window: 1M tokens ➤ Multimodality: Text and image input, text output ➤ Pricing: $0.15/$0.60 per 1M input/output tokens, with cached input at $0.015/M ➤ Availability: MiniMax first-party API, with MiniMax announcing an open weights release on October 23rd ➤ Licensing: Closed weights currently, with MiniMax announcing a weights release on October 23rd