gpt-6IMAGE
Braintrust eval pits Opus 5.5 against GPT-6 Sol and Luna
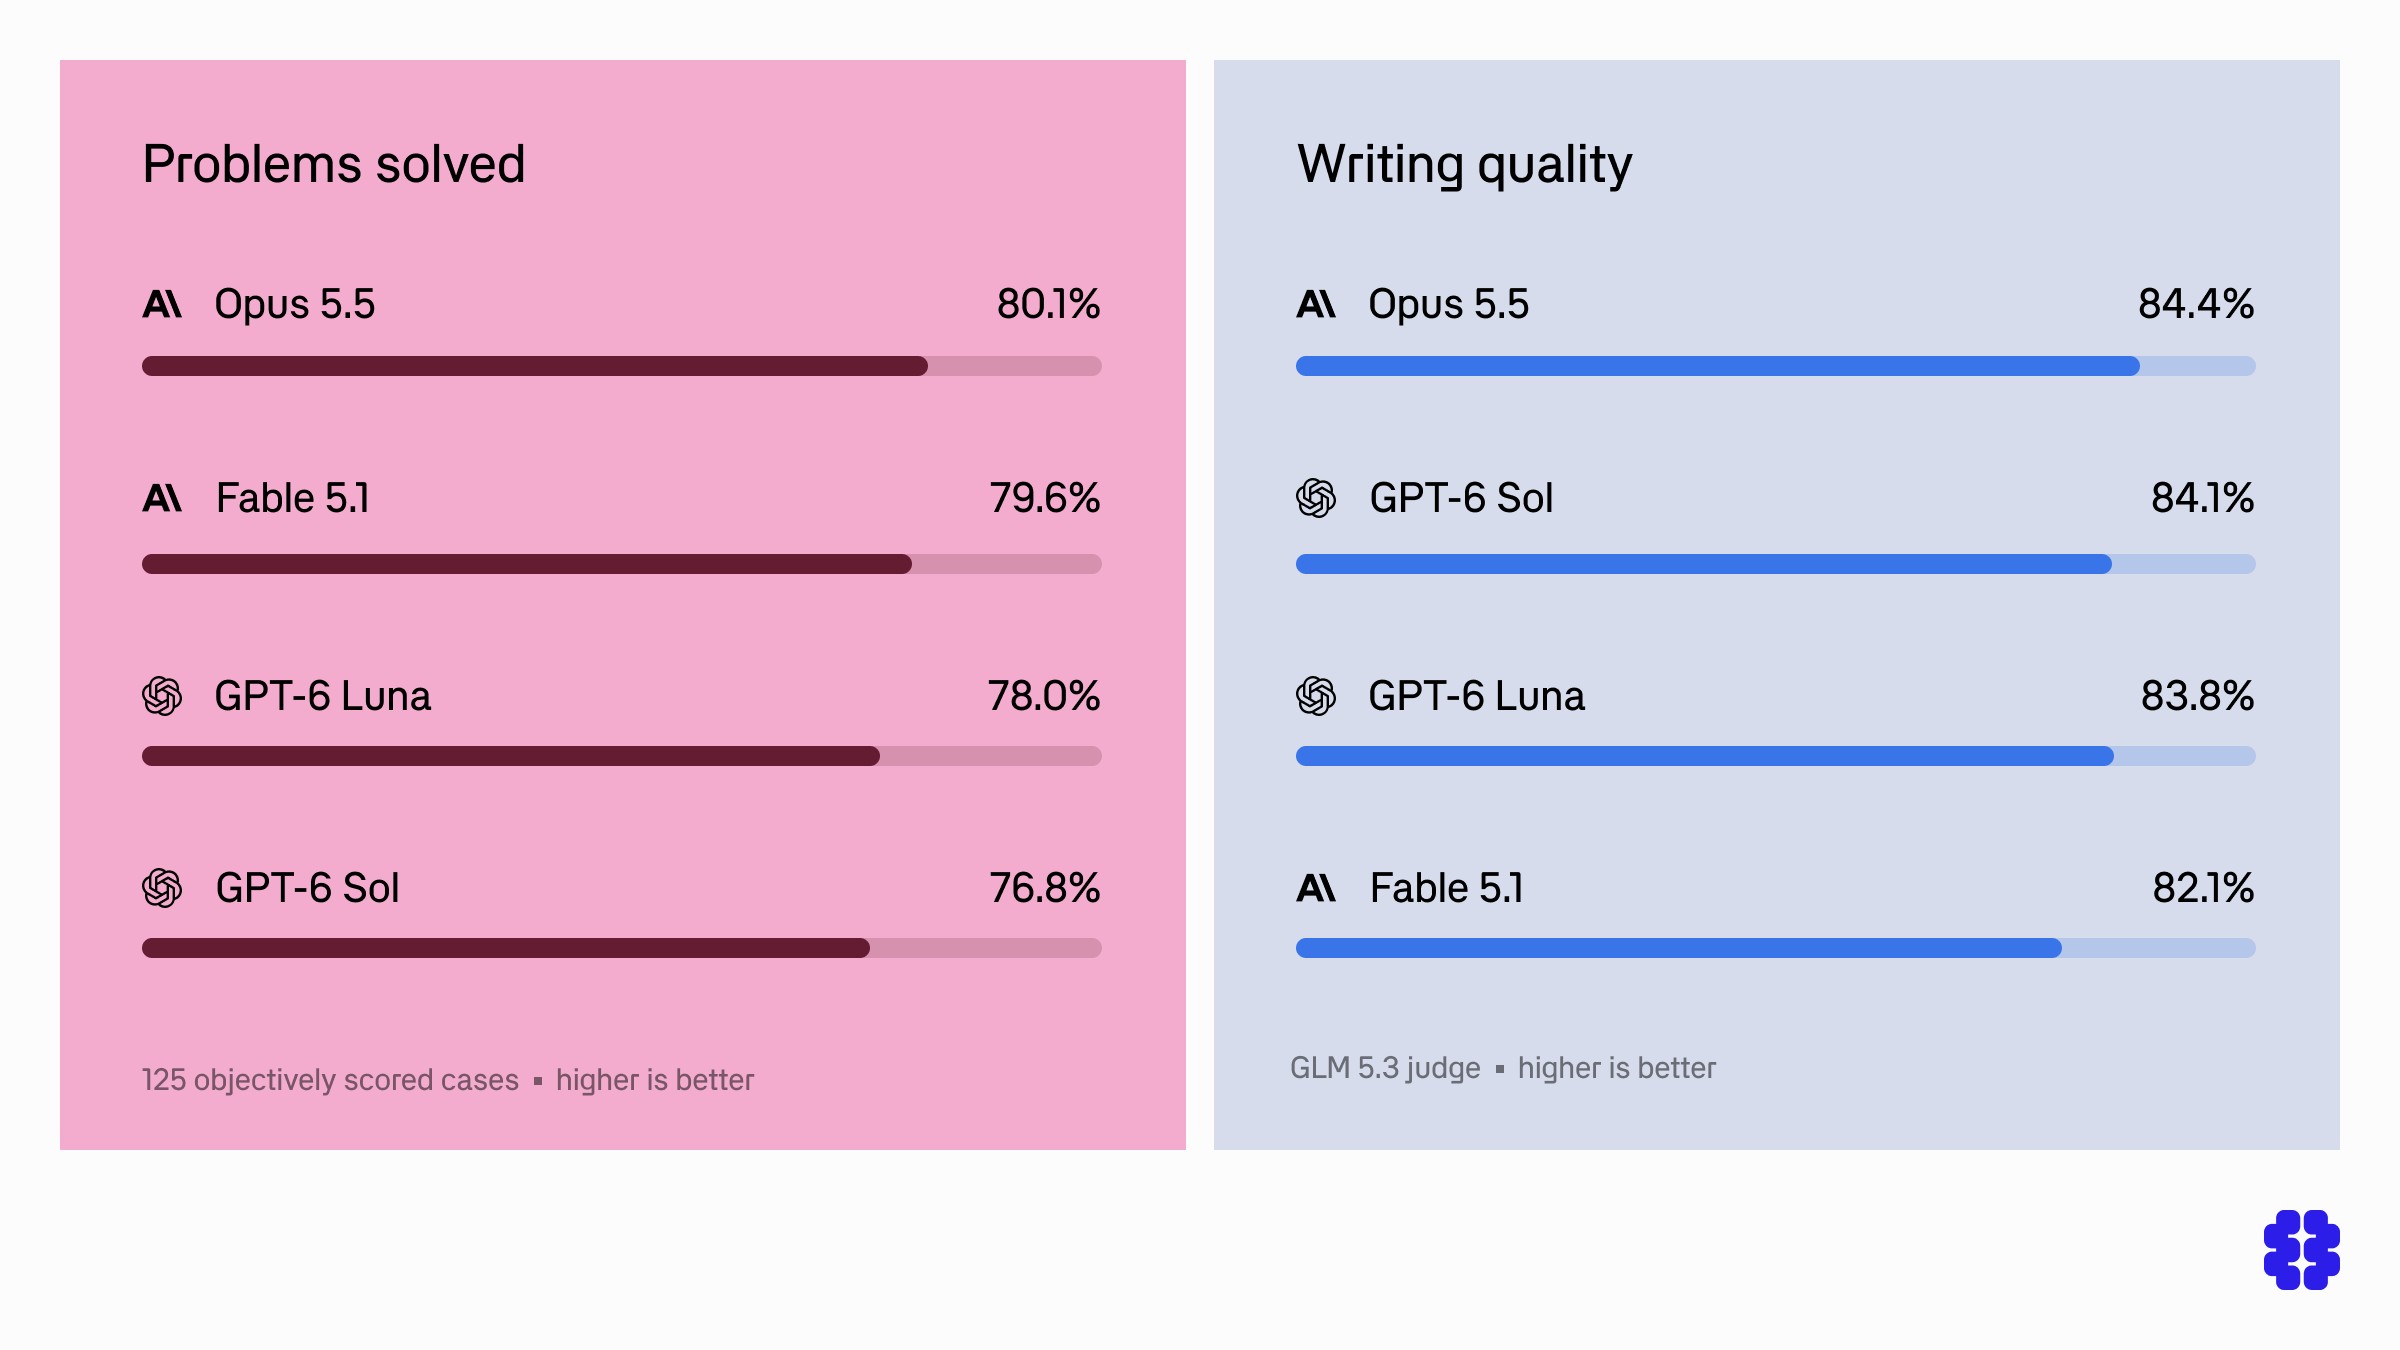
Braintrust ran writing and problem-solving evals: Opus 5.5 led with 80.1% on tasks and 84.4% on writing, while Luna reached 78.0% and 83.8% at roughly 2% of the cost.
Braintrust
@braintrustArchived 2026.09.24Originally posted 2026.09.23
Braintrust @braintrustOriginally posted 2026.09.23
Everyone is tired of reading AI slop. Anthropic says Opus 5.5 writes more naturally and actually follows instructions, so we ran an eval. We tested it against the new versions of OpenAI's GPT-6 Luna and Sol to see whether models can solve a problem AND write a decent explanation. Opus 5.5 came out on top in our tests, solving 80.1% of tasks and scoring 84.4% on writing quality. But Luna got to 78.0% and 83.8% for roughly 2% of the cost. Test them on your own tasks to see whether the difference matters. Read more → https://braintrustdata.link/opus-55-vs-gpt-6
x.com/braintrust/status/2102551299082330496Archived 2026.09.24 10:07