Grok Bot's costliest failure: flawless execution of wrong instructions
The author argues autonomous Grok Bot workflows should be run like production pipelines, with stop conditions, cross-checking bots and blast-radius approvals, costing out a 2% error rate.
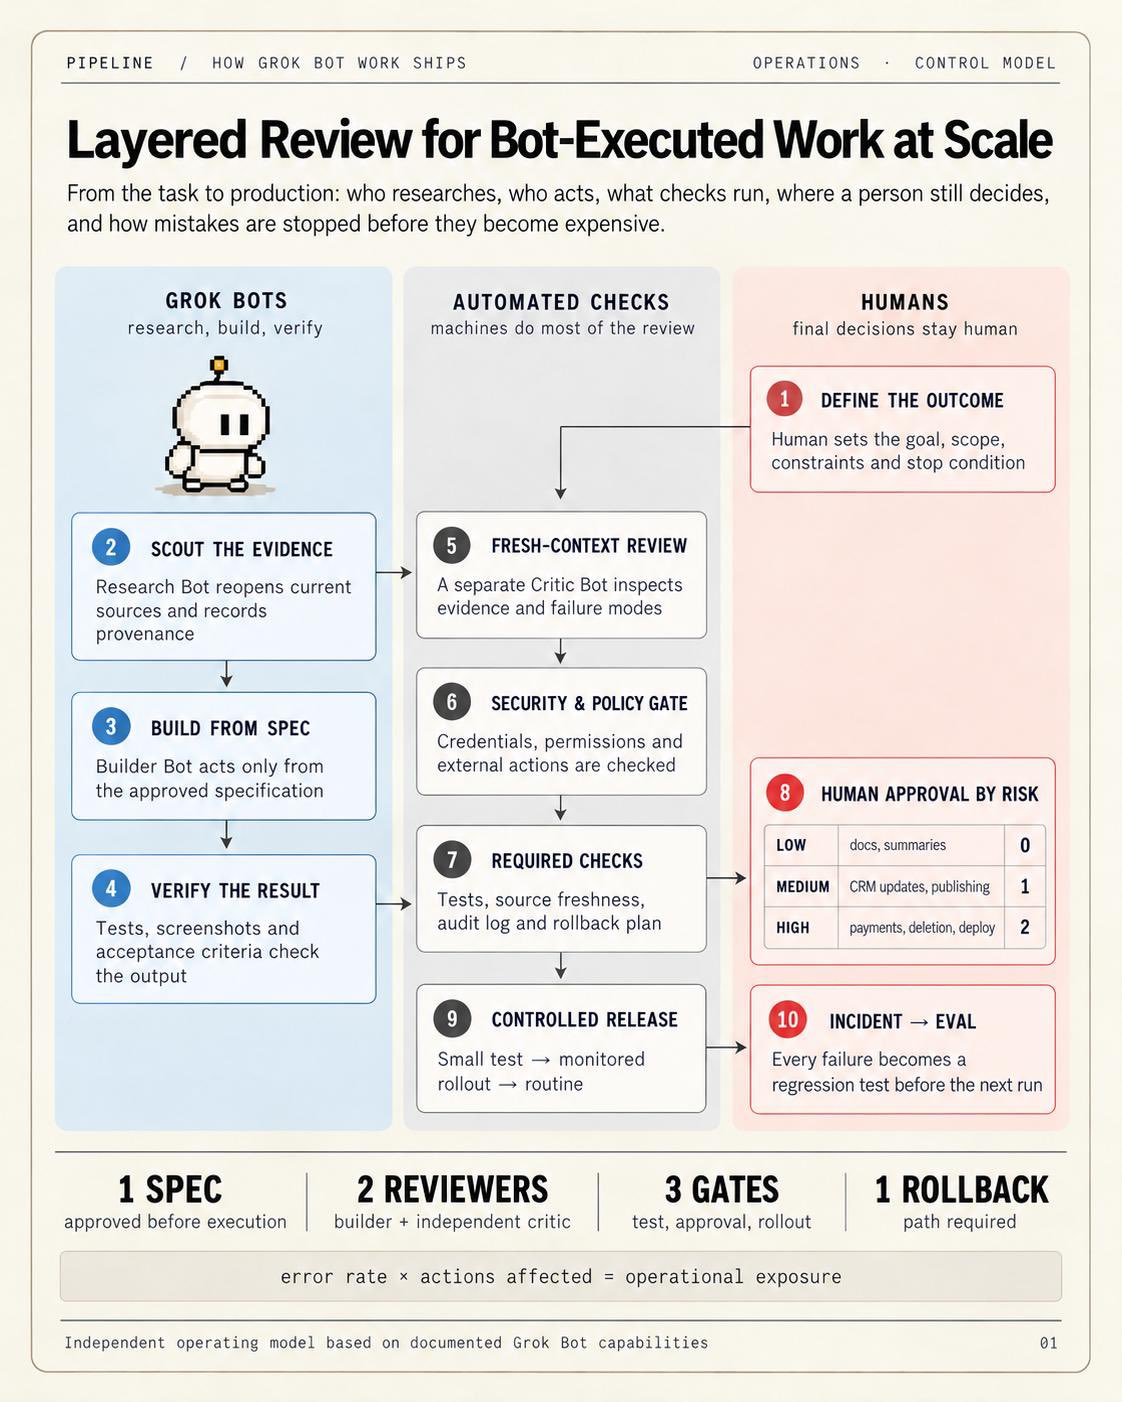
The most expensive Grok Bot failure is not a broken task It is a flawless execution of the wrong instruction at scale. Treat every autonomous workflow like a production pipeline: > define the outcome, data sources and stop condition > let one Bot research while another challenges its evidence > give the Builder only the approved specification > require source links, screenshots and a change log > test on a small sample before touching the full dataset > pause before any send, purchase, deletion or deployment > turn every failure into a permanent regression test Assign approvals by blast radius: routine research can run automatically, external communication needs one reviewer, and payments or production changes need two. The math explains why → A 2% error across 10,000 customer actions creates 200 failures → At just $20 to investigate and correct each one, that is a $4,000 mistake before refunds, churn or reputational damage. Do not measure Grok Bot by tasks completed. Measure failures caught before they become expensive.
This post quotes another post: “Using a canary marker to catch Grok Bot instruction drift”