NVIDIA Flare: local inference engine for DGX Spark
NVIDIA shipped Flare, a local inference engine for DGX Spark; a head-to-head test shows 47.6 tok/s decode versus TensorFold's 75.7, 1.5x faster first token at 32k, and temperature locked at 1.0.
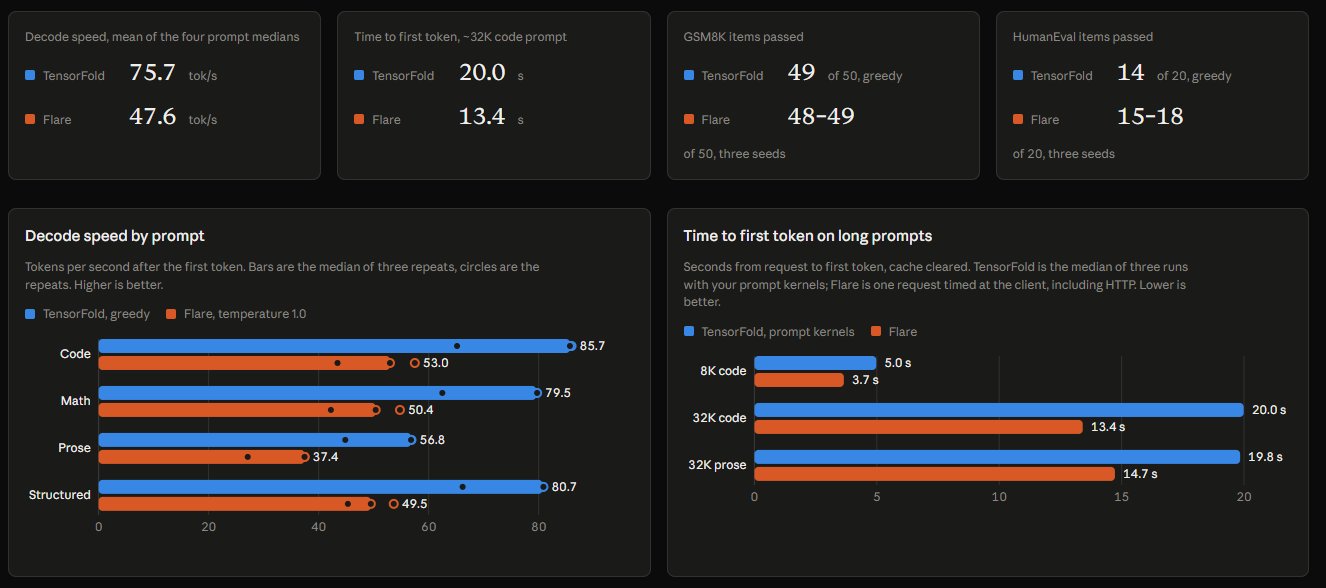
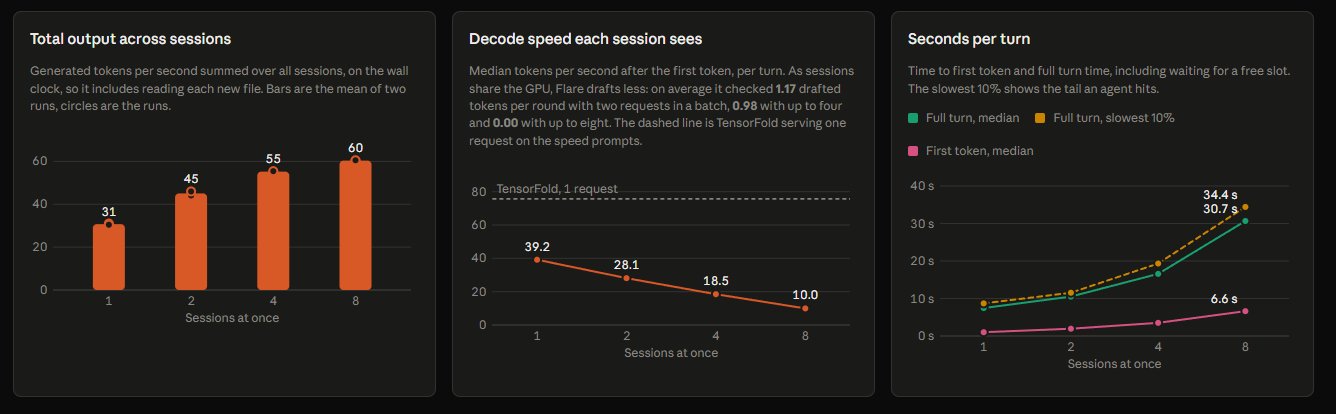
nvidia shipped flare, a local inference engine built for the dgx spark. so i ran it head to head against my tensorfold setup. same box, same model (qwen3.8-flash-next, 125b moe), same frozen prompts, hash-checked. → decode: tensorfold 75.7 tok/s. flare 47.6 (51.9 after tuning) → long prompts: flare wins, first token 1.5x faster at 32k → quality: dead tie on gsm8k + humaneval → 8 agents at once: flare only doubles total output. each agent gets 4x slower the catch: the shipped package locks temperature at 1.0. no greedy. its draft tokens miss more, so it stops guessing ahead.