MiniMax M3.1 Flash released: 428B MoE, $0.15/$0.60, always-on reasoning with 5 effort levels
Release breakdown: 428B MoE with ~23B active, 1M context, text/image/video input at $0.15/$0.60 per 1M tokens; reasoning can't be disabled and has five effort levels; 62.2 on Automation-Bench beats Opus 5 but Terminal Bench 4.0 trails by 13.7.
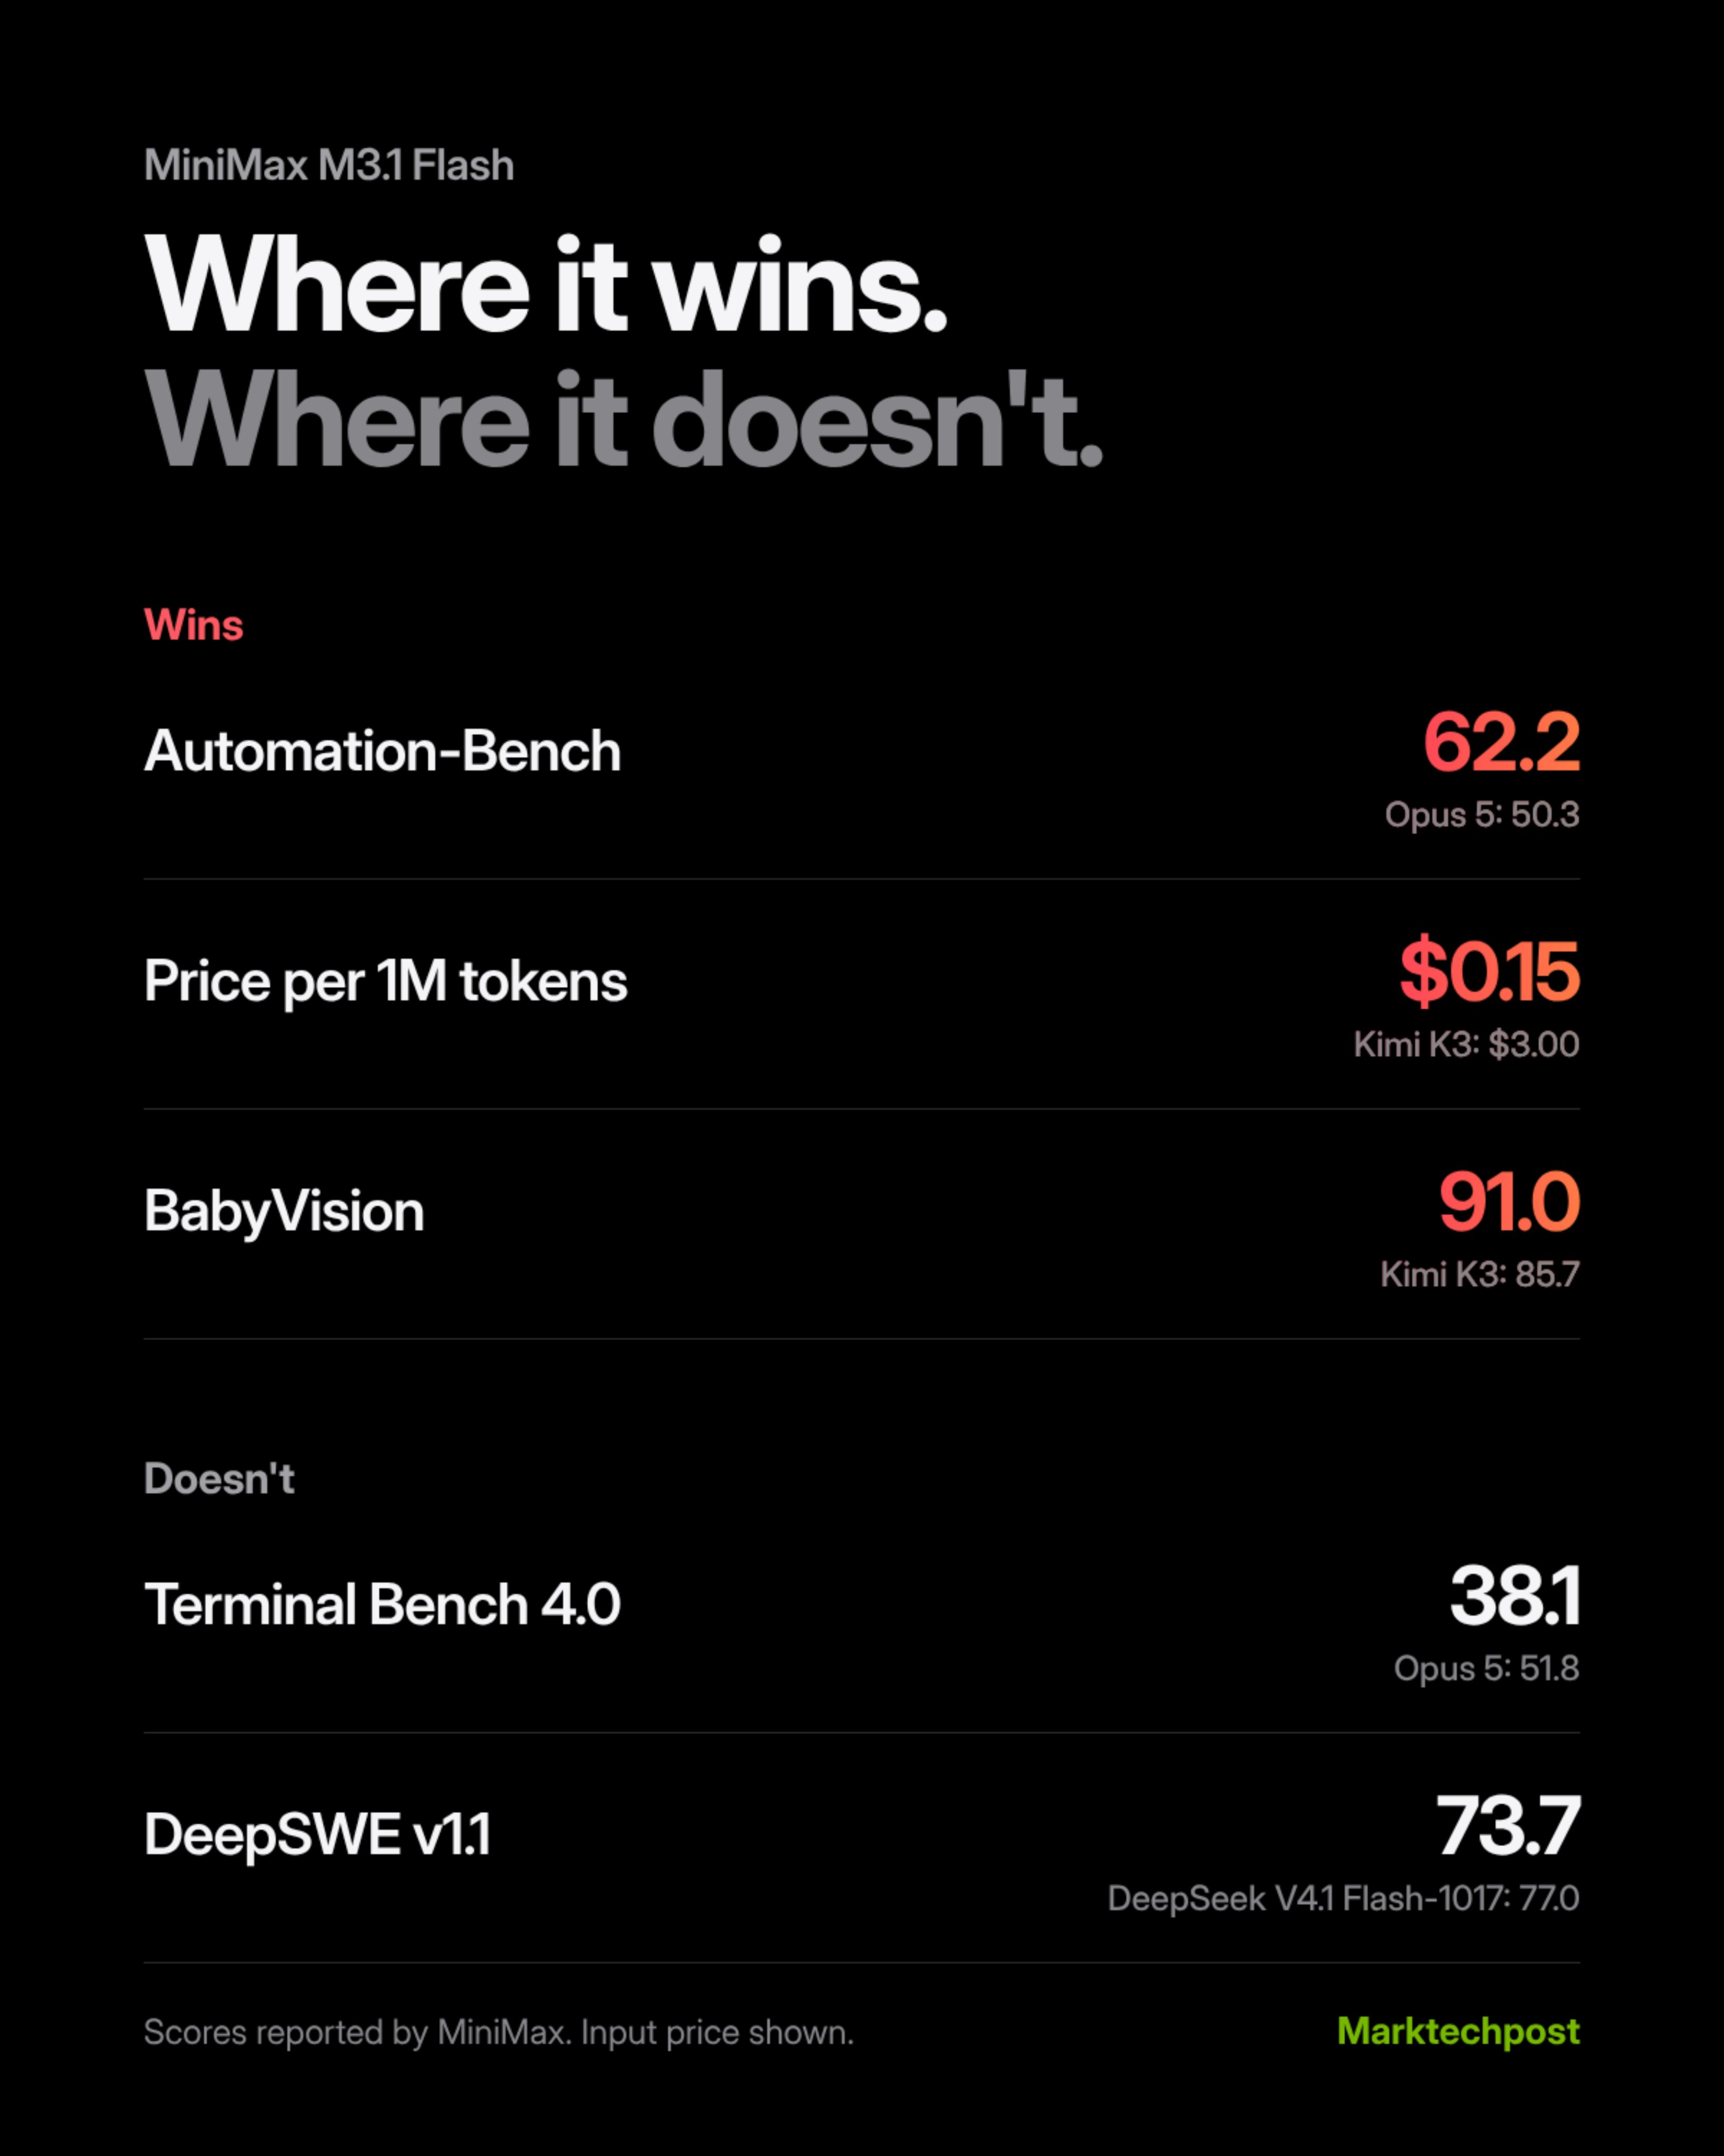
▲ MiniMax just released M3.1 Flash, pushing frontier-level agent performance down to Flash pricing: $0.15 / $0.60 per 1M tokens on a 428B MoE with about 23B activated parameters. Space Bunny, the stealth model that processed 200T+ tokens, was an earlier version of it. 🐰 Yes, Space Bunny was on M3.1 Flash from its development... The core design choice is always-on reasoning with 5 effort levels, from Low to Max. Thinking cannot be disabled, so M3 integrations that send thinking.type=disabled now return an error. On MiniMax's own table, it scores 62.2 on Automation-Bench v1.0.6, ahead of Opus 5 (50.3) and GPT-5.6 Sol (45.8), and ties Opus 5 on BankerToolBench at 76.2. Every effort level stays below $0.05 per task. It is a trade-off though: it trails Opus 5 by 13.7 points on Terminal Bench 4.0, and DeepSeek V4.1 Flash-1017 still beats it on DeepSWE (77.0 vs 73.7). With a 1M context window, text, image and video input, and a flat price at half of M3's per-token rate, it targets high-volume coding and office agents. Open weights arrive Oct 23...... Full analysis: https://www.marktechpost.com/2026/10/19/minimax-m3-1-flash-release/ API: http://platform.minimax.io Try it: http://agent.minimax.io/tools/m3-1-flash-preview @MiniMax_AI